> This page is for version 0.2.1.
> For other versions, use one of these documentation indexes:
> - 0.2.2 (latest) (default): https://docs.nvidia.com/bionemo/inference-runtime/latest/llms.txt
> - 0.2.1: https://docs.nvidia.com/bionemo/inference-runtime/0.2.1/llms.txt
> - 0.2.0: https://docs.nvidia.com/bionemo/inference-runtime/0.2.0/llms.txt
> - 0.1.1: https://docs.nvidia.com/bionemo/inference-runtime/0.1.1/llms.txt
> - 0.1.0: https://docs.nvidia.com/bionemo/inference-runtime/0.1.0/llms.txt
> For clean Markdown of any page, append .md to the page URL.
> For a complete documentation index, see https://docs.nvidia.com/bionemo/inference-runtime/llms.txt.
# NVIDIA BioNeMo Inference Runtime
> GPU-accelerated PyTorch inference for biomolecular structure prediction models.
## About BioNeMo Inference Runtime
NVIDIA BioNeMo Inference Runtime (BioIR) is NVIDIA's Python library for
accelerating biomolecular structure model inference on NVIDIA GPUs. It provides
biology-aware PyTorch modules, GPU kernels, and graph optimizations for
architecture-specific operations. These operations include Evoformer stacks and
triangle operations [^alphafold2], and Pairformer stacks, attention with pair
bias (pairwise attention), diffusion transformers, and atom-level modules
[^alphafold3].
General-purpose inference stacks do not fully optimize these specialized
operations. BioIR is designed for foundation-model developers and machine
learning researchers who create or modify biomolecular architectures. It
improves model-execution throughput and reduces GPU memory pressure while
preserving a Python development workflow.
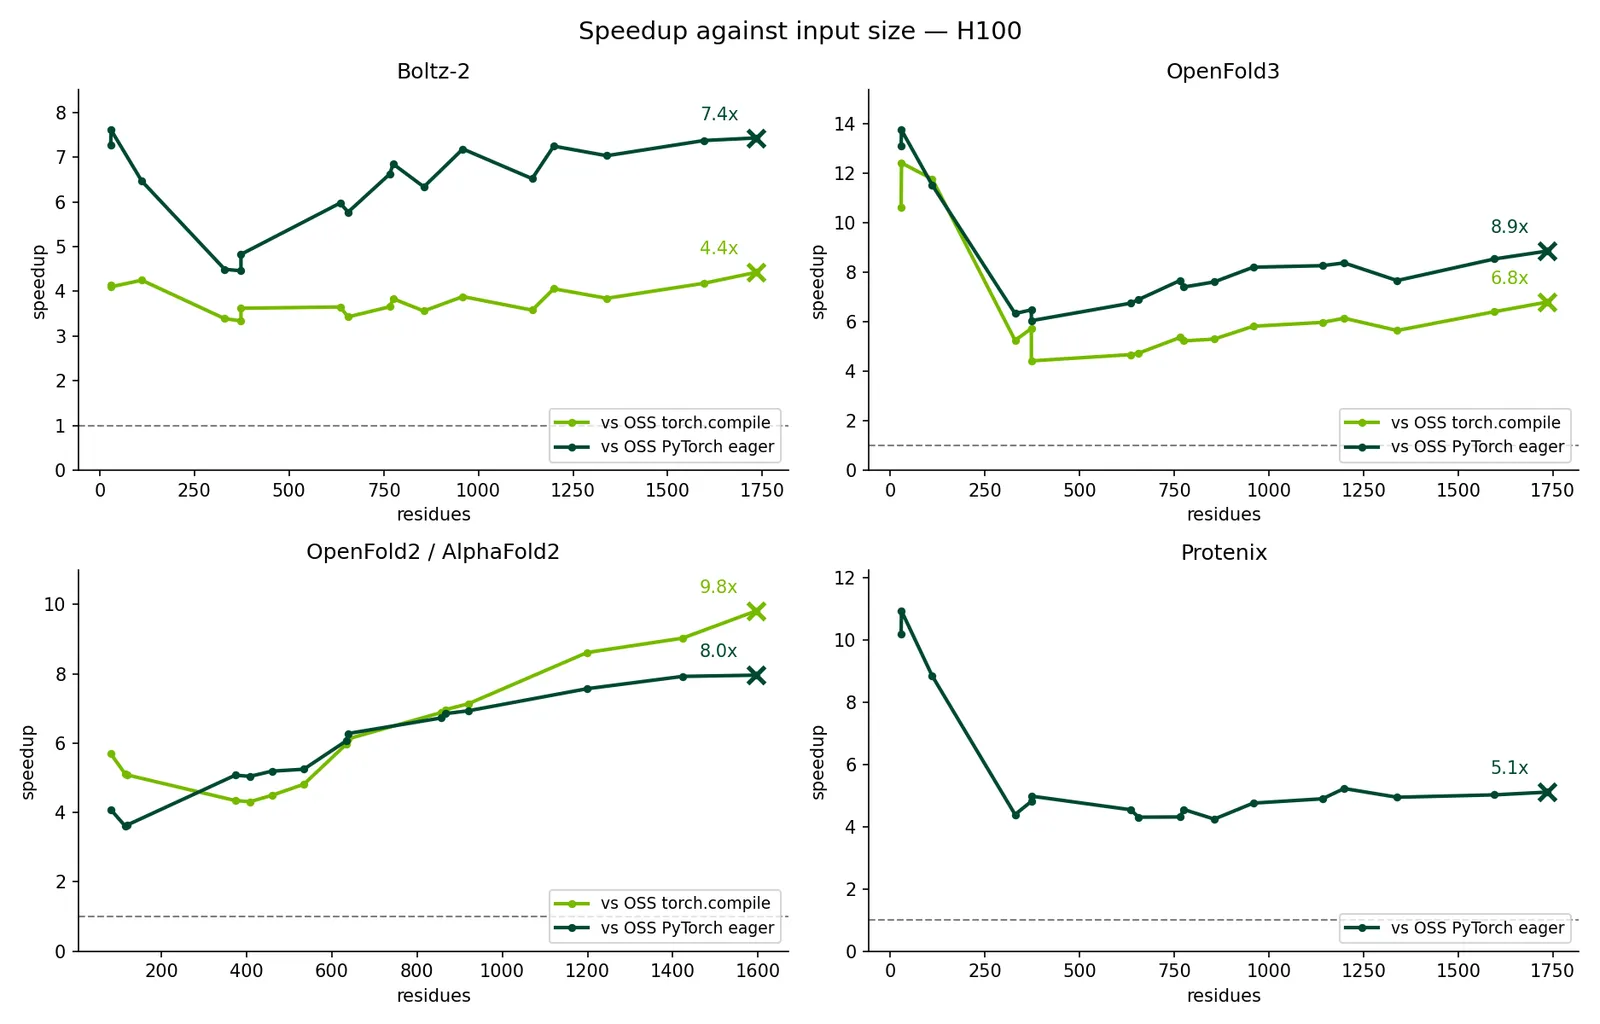
The following chart shows how BioIR speedup changes with input size on an NVIDIA
H100 GPU.
## Disclaimer
BioIR is in a Beta state, may not be fully functional, may contain errors or
design flaws, and may be changed at any time without notice. We appreciate your
feedback to improve and iterate on our products.
## Key Capabilities
BioIR provides the following key capabilities:
* **Architected on PyTorch:** A BioIR model remains an ordinary
`torch.nn.Module`. No engine build, export step, or separate build artifact
sits between a checkpoint and a forward pass. You can inspect tensors and use
standard Python stack traces. Plain configuration fields select optimized
layers, with documented PyTorch fallbacks for supported paths.
* **Built for biomolecular architectures:** BioIR applies optimizations at three
levels: kernels, modules and layers, and the end-to-end pipeline. Custom
CuTeDSL kernels and CUDA graphs use NVIDIA GPU capabilities to accelerate
structure-prediction patterns and supported modules. Pipeline orchestration
overlaps data loading, featurization, and output writing with the GPU forward
pass. Refer to
[how BioIR accelerates](/bionemo/inference-runtime/0.2.1/references/architecture#how-bioir-accelerates).
* **Lower GPU memory pressure:** Fused kernels reduce intermediate
materialization. Output-row chunking bounds peak activations for `O(N^2)` pair
tensors. Precomputed masks avoid rebuilding the same attention data in every
layer. Refer to
[where the memory savings come from](/bionemo/inference-runtime/0.2.1/references/architecture#where-the-memory-savings-come-from).
* **Supported hardware and models:** BioIR supports mixed FP32 and BF16
execution across data center and workstation GPUs. Six are qualified for this
release; the rest of the matrix runs but is not part of that set. The
[support matrix](/bionemo/inference-runtime/0.2.1/references/support-matrix) lists model keys, input coverage, GPU
architectures, and fused-kernel availability.
## Choose How to Use BioIR
BioIR supports two inference workflows:
1. **Run a supported model end to end.** Run OpenFold2, AlphaFold2, OpenFold3,
Boltz-1, or Boltz-2 through the complete prediction pipeline.
2. **Accelerate a custom model.** Keep your architecture and replace matching
components with optimized BioIR modules, such as a Pairformer stack or
diffusion transformer [^alphafold3].
Your custom model does not need to belong to a supported end-to-end family. It
only needs to contain a module that BioIR optimizes. Refer to
[the two inference workflows](/bionemo/inference-runtime/0.2.1/references/architecture#two-inference-workflows)
for implementation details, and to
[Accelerate a Custom Model](/bionemo/inference-runtime/0.2.1/references/accelerate-custom-model) for the
step-by-step swap.
### Choose an Executor
For large batches of independent inputs, use the Ray executor to improve
end-to-end throughput. Ray streams inputs through independently scalable
preprocessing, GPU inference, and output-writing stages, so CPU work on one
batch can run while GPUs process another. The inference stage assigns one
complete model replica to each GPU, which lets available GPUs process different
inputs concurrently.
> **Warning**
>
> Ray does not split one prediction across multiple GPUs or reduce its
> individual latency. Use the serial executor for debugging and per-request
> timing.
Refer to [Ray multi-GPU replicas](/bionemo/inference-runtime/0.2.1/references/api#ray-multi-gpu-replicas) for
configuration details.
The following diagram shows how the Ray executor processes independent inputs
across CPU stages and complete GPU model replicas.
```mermaid
flowchart TB
IN["Independent inputs"] --> P["Parser
CPU actor pool"]
P --> T["Tokenizer
CPU actor pool"]
T --> F["Feature generator
CPU actor pool"]
F --> R{"Ray schedules
the next batch"}
R --> G0["GPU 0
complete model replica"]
R --> G1["GPU 1
complete model replica"]
R --> GN["GPU N
complete model replica"]
G0 --> W["Writer
CPU actor pool"]
G1 --> W
GN --> W
W --> OUT["Structures and scores"]
```
## Target Workloads
BioIR targets large-scale structure inference workloads.
* **High-throughput protein design** — generate and evaluate large candidate
sets with hybrid generative and folding models.
* **Synthetic data generation** — produce structures in bulk for
self-distillation, retraining, and fine-tuning.
* **Folding-based scoring filters** — screen and rank generative output by
structural plausibility before committing to wet-lab work.
* **Structure prediction alongside docking** — supplement early-stage
protein-ligand and protein-protein screening with structure predictions.
BioIR accelerates the GPU model-execution layer. It does not accelerate database
search, MSA generation, experimental data preparation, or the remaining
design-to-lab workflow. End-to-end gains still depend on how much time remains
in the model forward pass after preprocess.
Related proteome-scale structure prediction work is described in:
* [How to Accelerate Protein Structure Prediction at Proteome
Scale][accel-structure-prediction]
* [AlphaFold Database expands to proteome-scale quaternary structures][afdb].
[accel-structure-prediction]: https://developer.nvidia.com/blog/how-to-accelerate-protein-structure-prediction-at-proteome-scale/
[afdb]: https://research.nvidia.com/labs/dbr/assets/data/manuscripts/afdb.pdf
[alphafold2-paper]: https://doi.org/10.1038/s41586-021-03819-2
[alphafold3-paper]: https://doi.org/10.1038/s41586-024-07487-w
[^alphafold2]: Jumper et al., ["Highly accurate protein structure prediction with
AlphaFold"][alphafold2-paper], *Nature* 596, 583–589 (2021).
[^alphafold3]: Abramson et al., ["Accurate structure prediction of biomolecular
interactions with AlphaFold 3"][alphafold3-paper], *Nature* 630, 493–500
(2024).
## Start Here
The [notice and disclaimer](#notice-and-disclaimer) applies to separately
downloaded dependencies, model checkpoints, and metadata.
#### [Install BioIR](/bionemo/inference-runtime/0.2.1/install)
Install the latest release wheel for your CPU architecture.
#### [Run a Boltz-2 prediction](/bionemo/inference-runtime/0.2.1/quickstart)
Fold a protein sequence with Boltz-2 and inspect the output.
#### [Scale predictions with Ray](/bionemo/inference-runtime/0.2.1/references/ray)
Run one Boltz-2 replica per visible GPU for concurrent batch inference.
#### [Use the Python API](/bionemo/inference-runtime/0.2.1/references/api)
Prepare inputs and run supported structure-prediction models.
#### [Understand the architecture](/bionemo/inference-runtime/0.2.1/references/architecture)
The two workflows, the three levels of acceleration, and how the pieces fit.
#### [Review performance benchmarks](/bionemo/inference-runtime/0.2.1/references/benchmark)
Compare BioIR speed, peak memory, and accuracy with OSS PyTorch baselines.
## Notice and Disclaimer
The following notice applies to separately downloaded components, including
runtime dependencies, model checkpoints, and chemical metadata.
**NOTICE AND DISCLAIMER:** This software automatically retrieves, accesses or
interacts with external materials. Those retrieved materials are not distributed
with this software and are governed solely by separate terms, conditions and
licenses. You are solely responsible for finding, reviewing and complying with
all applicable terms, conditions, and licenses, and for verifying the security,
integrity and suitability of any retrieved materials for your specific use case.
This software is provided "AS IS", without warranty of any kind. The author
makes no representations or warranties regarding any retrieved materials, and
assumes no liability for any losses, damages, liabilities or legal consequences
from your use or inability to use this software or any retrieved materials. Use
this software and the retrieved materials at your own risk.