


Execution Methods#
These methods are used to run the FFT operation.
A code example:
#include <cufftdx.hpp>

using FFT = decltype( cufftdx::Size<128>() + cufftdx::Type<fft_type::c2c>()
                    + cufftdx::Direction<fft_direction::forward>()
                    + cufftdx::Precision<float>() + cufftdx::Block() );

using complex_type = typename FFT::value_type;

__global__ kernel(... /* arguments */) {

  // Shared memory pointer
  extern __shared__ __align__(alignof(float4)) complex_type shared_mem[];

  // Register data
  complex_type thread_data[FFT::storage_size];

  // Load data into registers (thread_data)
  // ...

  FFT().execute(thread_data, shared_mem);

  // Store results (thread_data) into global memory
}
Thread Execute Method#
// #1
void FFT().execute<typename T>(T* input)

// #2: provided for symmetry with the block execute methods; ignores workspace
void FFT().execute<typename T>(T* input, FFT::workspace_type& workspace)
Runs the FFT operation defined by the FFT descriptor. T can be any type (such as float2 or double2),
as long as its alignment and element size are the same as those of FFT::value_type.
This method is available if the descriptor has been constructed using the Thread Operator and
cufftdx::is_complete_fft_execution is true.
input array must be in registers. Passing a pointer to global or shared memory is not supported: it is not diagnosed at compile time and its behavior and performance are not guaranteed. input must fit
FFT::storage_size elements of type FFT::value_type.
The operation is in-place: the results are stored back into input, overwriting the input values.
Overload #2 accepts a workspace argument for signature similarity with the block execute methods: thread
FFTs never require a workspace, so the argument is ignored. See FFT::workspace_type.
Do not use it to write code that is generic over Thread() and Block() descriptors: with a Block() descriptor the same call
execute(regs, workspace) selects the shared-memory overload, so the register array would be treated as a shared-memory pointer.
The block equivalent for register data is execute(regs, shared_memory, workspace).
Warning
It is not guaranteed that executions of exactly the same FFTs on GPUs of different CUDA architectures will produce bit-identical results.
Block Execute Method#
// #1 Execute with input in registers
void FFT().execute<typename T>(T* input, void* shared_memory,
                               FFT::workspace_type& workspace)

// #2: Version of #1 for FFTs which don't require workspace
void FFT().execute<typename T>(T* input, void* shared_memory)

// #3: Execute with input data in shared memory
void FFT().execute<typename T>(T* shared_memory_input,
                               FFT::workspace_type& workspace)

// #4: Version of #3 for FFTs which don't require workspace
void FFT().execute<typename T>(T* shared_memory_input)
Runs the FFT operation defined by the FFT descriptor. T can be any type (such as float2 or double2),
as long as its alignment and element size are the same as those of FFT::value_type.
This method is available if the descriptor has been constructed using the Block Operator
and cufftdx::is_complete_fft_execution is true.
When FFT::requires_workspace is false, overloads #2 and #4 can be used. Otherwise, user has to use
methods #1 or #3 and pass a reference to a workspace. When FFT::requires_workspace is true, execute() performs read-only global-memory
reads through the workspace’s buffers as part of computing the result.
For methods #1 and #2 a valid pointer to shared_memory must always be provided, even when no workspace is required and the input is provided
in registers. The shared_memory space is used internally for the FFT calculation.
shared_memory and shared_memory_input must point into CUDA shared memory. Pointers to global or host memory are not supported: this is not diagnosed at compile time, and it fails at run time with invalid shared memory accesses.
FFT data must be in registers (input, methods #1 and #2) or in shared memory (shared_memory_input, methods #3 and #4).
Global-memory operands are not supported (see Supported Functionality). Thread execute methods support register input/output only.
Warning
The library code assumes that both shared_memory and shared_memory_input are aligned to 128 bits for optimal memory operations.
This can be accomplished by using either __align__ or alignas compiler directives. Proper alignment is demonstrated in example
simple_fft_block_shared. Please consult CUDA C++ Programming Guide for furher details on memory alignment. Although not required
the user may also consider aligning thread local arrays in the same way, to reduce kernel resource usage.
Example
// Examples of how to make sure shared memory pointer is aligned
// to 128 bits (16 bytes):
using value_type = typename FFT::value_type;
extern __shared__ alignas(float4)
  unsigned char shared_mem[];                              // 1
extern __shared__ __align__(16)
  value_type shared_mem[];                                 // 2
extern __shared__ __align__(alignof(float4))
  value_type shared_mem[];                                 // 3
extern __shared__ float4 shared_mem[];                     // 4

// Warning: std::aligned_storage became deprecated in C++23
extern __shared__ std::aligned_storage_t<sizeof(float4),
                                         alignof(float4)>
  shared_mem[];                                            // 5
Note
Overloads #3 and #4 always issue block-wide barriers, and overloads #1 and #2 do when FFT::stride > 1. Do not rely on
execute being (or not being) a barrier: it must be called by every thread of the CUDA block, including
threads for which FFT::working_group’s is_thread_active() returns
false. Use is_thread_active() to guard the data accesses around the call, never the call itself.
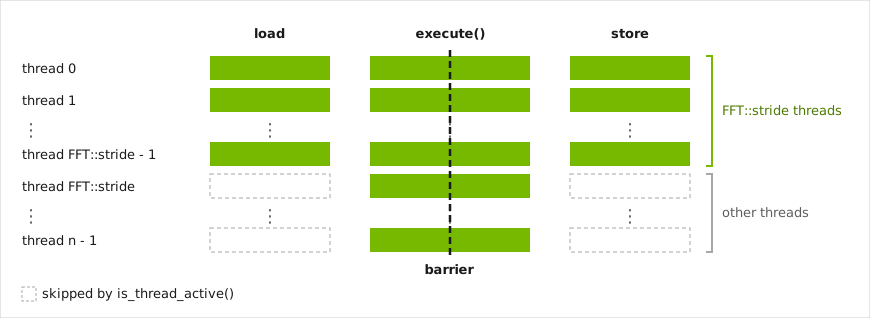
Fig. 3 Example for one batch per block (FFT::working_group::implicit_bpb() == 1), where FFT::stride threads take part in the FFT.
All threads call execute(); only the data accesses are guarded with is_thread_active().#
In methods #1 and #2 input is in thread local arrays, and shared_memory is a pointer to a shared memory of size
FFT::shared_memory_size bytes. The operation is in-place meaning the results are stored in input. input must
fit FFT::storage_size elements of type FFT::value_type.
Note
Methods #1 and #2 don’t assume that shared memory (shared_memory) is safe to modify or access without block synchronization,
and perform required synchronization (__syncthreads()) before the first use of it. Also, methods #1 and #2 don’t
synchronize any threads within a block after the last operation on shared memory is done. If that shared memory is going to be
reused later a synchronization has to be performed first.
In methods #3 and #4 the input data is passed in shared memory (shared_memory_input). The operation is in-place, meaning
the results are stored back to shared_memory_input. These methods don’t require an additional shared_memory pointer
to be passed, as shared_memory_input will be used for the required communication between threads. Thus, shared_memory_input
must fit all input and output values, and can’t be smaller than FFT::shared_memory_size bytes
(i.e. shared memory size in bytes is a maximum of FFT::shared_memory_size, FFT::ffts_per_block * <FFT_input_size_in_bytes>, and
FFT::ffts_per_block * <FFT_output_size_in_bytes>) bytes). With the DynamicBatching operator
FFT::ffts_per_block is 1 and FFT::shared_memory_size covers a single batch, so use the runtime number of FFTs per block instead.
Note
Methods #3 and #4, which get input via shared memory, assume that a block-wide synchronization (__syncthreads())
was already performed by every thread of the block and the data can be safely accessed. Methods don’t synchronize
any threads within a block after the last operation on shared memory is done. Before reading from or writing to
shared memory a block-wide synchronization (__syncthreads()) has to be performed first.
Warning
It is not guaranteed that executions of the same FFTs (size, direction, type, precision) but with different
number of elements per thread (ElementsPerThread),
number of FFTs calculated per CUDA block (FFTsPerBlock), or
block dimension (BlockDim),
will produce bit-identical results.
Warning
It is not guaranteed that executions of exactly the same FFTs on GPUs of different CUDA architectures will produce bit-identical results.
Make Workspace Function#
template<class FFT>
auto cufftdx::make_workspace(cudaError_t& error, cudaStream_t stream = 0)

template<class FFT>
auto cufftdx::make_workspace(cudaStream_t stream = 0)
cufftdx::make_workspace<FFT>(cudaError_t&, cudaStream_t) is a helper function for creating workspace required for block execute(...) method
when FFT::requires_workspace is true. FFT is type of FFT descriptor. If no stream
argument is passed, the default 0 stream is used for execution. If after calling the function error is not cudaSuccess the
workspace was not created correctly and is invalid.
cufftdx::make_workspace<FFT>(cudaStream_t) is a helper function for creating workspace which will throw an exception, std::runtime_error
initialized with a string describing returned cudaError_t code, if allocation of workspace failed. This is the only difference when compared with
cufftdx::make_workspace<FFT>(cudaError_t&, cudaStream_t) helper function.
Both overloads of cufftdx::make_workspace are host functions and are not available in NVRTC-compiled code.
If FFT::requires_workspace trait is
false, user doesn’t have to create workspace.Workspace can be created for FFT with
FFT::requires_workspaceequal to false: such workspace is an empty workspace with no global memory allocation.Workspace object is valid only for FFT it was created for.
Workspace object can allocate global memory, however never more than FFT::workspace_size, and it’s responsible for freeing it.
Kernels running concurrently can share a workspace, since
execute()only reads it. All copies share the same underlying global memory allocation, so it must have been created (its creation kernel completed) before the kernels use it, and it must stay alive until they finish.Allocated global memory is freed upon destruction of the last copy of created workspace object.
Workspace object can be implicitly cast to FFT::workspace_type.
When
FFT::requires_workspaceistrue, creating a workspace launches an internal kernel on the supplied stream to precompute the Bluestein chirp. That kernel consumes dynamic shared memory and is opted in viacudaFuncSetAttribute(cudaFuncAttributeMaxDynamicSharedMemorySize, ...); a failure of that opt-in is reported through the samecudaError_t/ exception path as an allocation failure.Creating a workspace that requires global memory performs a full
cudaDeviceSynchronize(), not acudaStreamSynchronize()on the suppliedstream: the call blocks the host, synchronizes the whole device rather than just the given stream, and cannot be used inside a CUDA graph stream capture.
Note
Workspace is not required for FFTs of following sizes:
Powers of 2 up to 32768.
Powers of 3 up to 19683.
Powers of 5 up to 15625.
Powers of 6 up to 7776.
Powers of 7 up to 16807.
Powers of 10 up to 10000.
Powers of 11 up to 1331.
Powers of 12 up to 1728.
Powers of 13 up to 2187.
Powers of 14 up to 2744.
Powers of 15 up to 3375.
Powers of 17 up to 4913.
Powers of 18 up to 5832.
Powers of 19 up to 6859.
Powers of 20 up to 8000.
Powers of 21 up to 9261.
Powers of 22 up to 10648.
Powers of 23 up to 12167.
Powers of 24 up to 13824.
Powers of 26 up to 17576.
Powers of 29 up to 21952.
Powers of 30 up to 27000.
Powers of 31 up to 29791.
Factors of 4 lower than 512.
- In the future versions of cuFFTDx:
Workspace requirement may be removed for other configurations.
FFT configurations that do not require workspace will continue to do so.
Warning
FFT::workspace_type object doesn’t track lifetime of underlying memory, and is only valid within a lifetime of workspace object it was casted from.
Warning
Type returned by cufftdx::make_workspace<FFT>(cudaError_t&, cudaStream_t) can be different for different FFT descriptions,
and is not the same as FFT::workspace_type. User should use auto when
creating a workspace object. Example:
// Kernel
template<class FFT>
__launch_bounds__(FFT::max_threads_per_block)
__global__ void block_fft_kernel(
    typename FFT::value_type* data,
    typename FFT::workspace_type workspace) {
    // ...

    // Execute FFT
    FFT().execute(thread_data, shared_mem, workspace);
}

// Create workspace
cudaError_t error = 0;
auto workspace = cufftdx::make_workspace<FFT>(error, stream);

// ...

// Run kernel with FFT
block_fft_kernel<FFT><<<1, FFT::block_dim,
    FFT::shared_memory_size, stream>>>(data, workspace);
Value Formats and Data Layouts#
To perform the FFT correctly data needs to be passed to the library in a specific format described in section Value Formats and partitioned among threads as detailed in section Data Layouts. The user is responsible for getting these two factors right, but the library provides idioms, traits and examples which should make API use accessible and intuitive.
Value Formats#
For complex numbers of single and double precision, the first value in a complex number is the real part and the second is the imaginary part.
The input value format for complex-to-complex and complex-to-real FFTs is the aforementioned complex type, but for real-to-complex FFT this property is dependent on the use
of RealFFTOptions Operator and specifically its real_mode enum value. By default the real-to-complex execution takes real values as arguments,
but if the execution mode is set to real_mode::folded the library performs an optimized execution which treats real input as complex input of half the size.
In this case the value format is complex (identical to that of complex-to-complex or complex-to-real) containing two real values.
Similarly, the output value format for complex-to-complex and real-to-complex FFTs is the complex type, but for complex-to-real FFT this property is dependent on the use
of RealFFTOptions Operator and specifically its real_mode enum value. By default the complex-to-real execution outputs real values as results,
but if the execution mode is set to real_mode::folded the library performs an optimized execution which treats real output as complex output of half the size.
In this case the value format is complex (identical to that of complex-to-complex or complex-to-real) and otherwise it’s made of real values.
Half Precision Implicit Batching#
Processing of half (fp16) precision FFTs in cuFFTDx is implicitly batched, that is, a single computation processes two FFT batches. cuFFTDx expects that a complex number of half precision has 2 real parts and 2 imaginary parts in that order (i.e real0, real1, imaginary0, imaginary1). Real values of half precision (for R2C and C2R FFTs) follow the same logic and each should contain two real values. See also FFT::implicit_type_batching trait.
Data Layouts#
Input and output data layouts of an FFT depend strictly on its configuration and the selected transform type. A data layout
describes the size and the pattern of input or output data for the execute methods, no matter if input/output are partitioned
between threads into thread local arrays or stored contiguously in shared memory.
As the section Value Formats put forth, the input / output formats are either real or complex. Another important execution attribute is the sequence length. In complex-to-complex transforms this property is equal to transform size, but for real-to-complex and complex-to-real the library offers a few options to choose from. This choice can be made by means of the RealFFTOptions Operator operator.
The sections below provide detailed descriptions of the input and output data layouts for both thread and block execution modes .
Complex-to-complex#
In the case of complex-to-complex transforms both the input and output data must be a complex array in a corresponding precision. Both input and output arrays are always of the same length, equal to the size of the FFT.
Input/Output in Registers for Thread Execution#
The input values of the FFT should be stored in input in the natural order.
Results are stored in input following the same rule.
Input/Output in Registers for Block Execution#
n-th thread (indexing from 0) participating in the FFT should include the following elements of FFT in its input
values: n + FFT::stride * i where i is an index in input.
Results are later stored in input following the same rule.
Please note that in certain cases, especially if FFT::requires_workspace is true, the
values are not partitioned equally between threads.
See also FFT::stride.
Example
0th thread of 8-point FFT with FFT::stride equal to 2 should have values 0, 2, 4, and 6 in its input.
Elements are not always perfectly divisible among threads:
0th thread of a 7-point FFT with FFT::stride equal to 2 should have values 0, 2, 4, and 6 in its input, while the 1st thread should have values 1, 3 and 5.
Real-to-complex and complex-to-real#
For real-to-complex (R2C) and complex-to-real (C2R) FFT input and output data layouts depend on the RealFFTOptions Operator.
By default RealFFTOptions is set to complex_layout::natural and real_mode::normal.
Complex layouts:
complex_layout::natural(default),complex_layout::packed,complex_layout::full.Real modes:
real_mode::normal(default),real_mode::folded.
Complex Element Layouts#
Complex element layout is defined for the complex-to-real input and real-to-complex output.
It depends on the passed complex_layout value of the RealFFTOptions operator.
complex_layout::naturalfor even length ((r0, i0 = 0), (r1, i1), … , (rN/2, iN/2 = 0)), only non-redundant N/2 + 1 elements, with first and last elements containing only real parts.imag0 and imagN/2 are both assumed to 0 due to mathematical properties of complex-to-real FFT input signal.
complex_layout::naturalfor odd length ((r0, i0 = 0), (r1, i1), … , (r⌊N/2⌋, i⌊N/2⌋)), only non-redundant ⌊N/2⌋ + 1 elements, with first element containing only the real part.imag0 is assumed to be 0 due to mathematical properties of complex-to-real FFT input signal.
complex_layout::packed((r0, i0), (r1, i1), … , (rN/2 - 1, iN/2 - 1)), packs the last real element into the imaginary component of the first element.Packing means that the first element x0 contains (real0, real⌊N/2⌋).
Allowed only for even sizes, e.g. for 16-point FFT the length is 8, for 15-point it is unavailable.
complex_layout::fullfor even lengths ((r0, i0 = 0), (r1, i1), … , (rN/2, iN/2 = 0), … , (rN - 1, iN - 1)), all elements, including redundant ones, since the output is hermitian.For example, for 16-point FFT the length is 16
imag0 and imagN/2 are both assumed to be 0 due to mathematical properties of complex-to-real FFT input signal.
complex_layout::fullfor odd lengths ((r0, i0 = 0), (r1, i1 ), … , (rN - 1, iN - 1)), all elements, including redundant ones, since the output is hermitian.For example, for 15-point FFT the length is 15
imag0 is assumed to be 0 due to mathematical properties of complex-to-real FFT input signal.
Complex Input/Output in Registers for Thread Execution#
Follows the same rules as described in Complex Input/Output In Shared Memory for Block Execution, but the input/output data is stored in a thread local array.
Complex Input/Output in Registers for Block Execution#
n-th thread (indexing from 0) participating in the FFT should include the following elements of FFT in its input
values: n + FFT::stride * i where i is an index in input. Results are later stored in input following the same rule.
Please note that in certain cases, especially if FFT::requires_workspace is true, the
values are not partitioned equally between threads.
Example
For 16-point FP32/FP64 C2R FFT with ElementsPerThread set to 4 (implying 4 threads, and FFT::stride equal to 4):
complex_layout::natural: the input layout (first row) and required partitioning of the data (entire table) into thread local arrays is presented below:
thread / element |
(r0, i0 = 0) |
(r1, i1) |
(r2, i2) |
(r3, i3) |
(r4, i4) |
(r5, i5) |
(r6, i6) |
(r7, i7), |
(r8, i8 = 0) |
|---|---|---|---|---|---|---|---|---|---|
0 |
X |
X |
X |
||||||
1 |
X |
X |
|||||||
2 |
X |
X |
|||||||
3 |
X |
X |
complex_layout::packed: the input layout (first row) and required partitioning of the data (entire table) into a thread array is presented below:
thread / element |
(r0, r8) |
(r1, i1) |
(r2, i2) |
(r3, i3) |
(r4, i4) |
(r5, i5) |
(r6, i6) |
(r7, i7), |
|---|---|---|---|---|---|---|---|---|
0 |
X |
X |
||||||
1 |
X |
X |
||||||
2 |
X |
X |
||||||
3 |
X |
X |
complex_layout::full: the input layout (first row) and required partitioning of the data (entire table) into thread local arrays is presented below:
thread / element |
(r0, i0 = 0) |
(r1, i1) |
(r2, i2) |
(r3, i3) |
(r4, i4) |
(r5, i5) |
(r6, i6) |
(r7, i7), |
(r8, i8 = 0) |
(r9, i9) |
(r10, i10) |
(r11, i11) |
(r12, i12) |
(r13, i13) |
(r14, i14) |
(r15, i15), |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
0 |
X |
X |
X |
X |
||||||||||||
1 |
X |
X |
X |
X |
||||||||||||
2 |
X |
X |
X |
X |
||||||||||||
3 |
X |
X |
X |
X |
The layouts and the required partitioning look similarly for R2C output.
Half-precision FFTs follow the same rules but the implicit batching has be taken into account.
Real Element Layouts#
Real element layout is defined for the complex-to-real output and real-to-complex input.
It depends on real_mode parameter of the RealFFTOptions operator:
real_mode::normal(x0, x1, … , xN - 1), real element array of length equal to the transformation size.real_mode::folded(x0, x1, … , x N/2 - 1), complex element array of length half that of the transformation size.
Note
The physical layout of the elements in shared memory is the same as in the real_mode::normal case, but the logical one changes: instead of being an array of real values, it is an array of complex values.
Note
real_mode::folded execution is dependent on certain FFT characteristics, and currently it is available in block execution only
for sizes equal to 2N where N is any exponent which still makes the transform fit into available size range. For thread
execution this optimization supports all sizes equal to 2 * N, where N is any multiplier which makes the transform fit into available
size range. Using folded execution doubles the size limit available otherwise. Consult Supported Functionality for further details.
Real Input/Output in Registers for Thread Execution#
Follows the same rules as described in Real Input/Output In Shared Memory for Block Execution, but the input/output data is stored in a thread local array.
Real Input/Output in Registers for Block Execution#
n-th thread (indexing from 0) participating in the FFT should include the following values of type Input Type Trait
: n + FFT::stride * i where i is an index in input.
Results are later stored in input following the same rule.
Please note that in certain cases, especially if FFT::requires_workspace is true, the
values are not partitioned equally between threads.
It is also important to remember that the count of values of this type per thread will be Input EPT Trait and not Elements Per Thread Trait
Example
For 8-point FP32/FP64 R2C FFT with ElementsPerThread set to 2 for real_mode::normal (4 threads) and
to 4 for real_mode::folded (2 threads):
real_mode::normal input layout looks like this: [real0, r1, r2, r3, r4, r5, r6, r7].
The required partitioning of the data into thread local arrays is presented below:
thread / element |
r0 |
r1 |
r2 |
r3 |
r4 |
r5 |
r6 |
r7 |
|---|---|---|---|---|---|---|---|---|
0 |
X |
X |
||||||
1 |
X |
X |
||||||
2 |
X |
X |
||||||
3 |
X |
X |
real_mode::folded input layout looks like this: [(real0, r1), (r2, r3), (r4, r5), (r6, r7)].
The required partitioning of the data into thread local arrays (each thread holds two pairs) is presented below:
thread / element |
(r0, r1) |
(r2, r3) |
(r4, r5) |
(r6, r7) |
|---|---|---|---|---|
0 |
X |
X |
||
1 |
X |
X |
The layouts and the required partitioning look similarly for C2R output.
Half-precision FFTs follow the same rules but the implicit batching has be taken into account.
Loading and Storing Data#
To deal with the complexity of changing input and output lengths depending on configuration, the library provides various traits allowing for easy memory operations. Input Length Trait and Output Length Trait describe lengths of respectively input and output arrays. This covers real-to-complex (R2C) and complex-to-real (C2R) cases described above. Input EPT Trait describes the count of elements to be loaded by each thread, assuming that each element is of type Input Type Trait. Respectively Output EPT Trait and Output Type Trait describe the same properties for storing output.
The detailed idiomatic IO is shown in examples, but the general approach for loading data from global memory is as follows:
Example
Block FFT with Data in Registers
The following example shows block trait-based universal loading scheme for cuFFTDx register API execution mode. Here a thread group performs an FFT cooperatively, so the data needs to be spread among all participants. The following code snippets already account for this partitioning, but also different value formats (as described in Value Formats) and data layouts (as described in Real Element Layouts and Complex Element Layouts).
// Which batch in this block is this thread performing. Using FFT::working_group
// instead of threadIdx directly keeps this correct regardless of the
// ThreadLayout/ThreadLinearization operators used.
// A batch holds FFT::implicit_type_batching FFTs (2 for __half, 1 otherwise).
const auto local_fft_id = FFT::working_group::batchid();
// Which batch in this grid is this thread performing. Uses implicit_bpb(), the number
// of batches per block, not FFT::ffts_per_block, which counts FFTs and would be
// twice too large for __half.
const auto global_fft_id = FFT::working_group::implicit_bpb() * blockIdx.x + local_fft_id;
// Memory offset for accessing the first element of the global_fft
const auto global_offset = global_fft_id * FFT::input_length;

// Cast registers to type required as input to FFT execution
using input_t = typename FFT::input_type;
auto thread_fft_data = reinterpret_cast<input_t*>(thread_data);
auto fft_data = reinterpret_cast<const input_t*>(input);

// Only required if a BlockDim operator makes the launch use more threads than the FFT
// needs (FFT::working_group::is_predicated() is true); otherwise all threads are active.
if (FFT::working_group::is_thread_active()) {
  auto index = FFT::working_group::fftid();
  for (unsigned int i = 0; i < FFT::input_ept; ++i) {
    if (index < FFT::input_length) {
      thread_fft_data[i] = fft_data[global_offset + index];
      index += FFT::stride;
    }
  }
}
Block FFT with Data in Shared Memory
The following example shows block trait-based universal loading scheme for cuFFTDx shared memory API execution mode. Here
entire CUDA block performs FFTs Per Block Trait FFTs cooperatively, so the data in shared memory needs to contain
all necessary batches. execute() itself reads shared_memory_input indexed by
FFT::working_group’s batchid()/fftid(), so each thread loads exactly the
elements it will itself consume, using the same trait; this keeps the mapping correct under any
ThreadLayout/ThreadLinearization
configuration. For the default mapping, the threads of one FFT access consecutive elements, so the accesses of those threads are coalesced into full 32-byte sectors when FFT::stride * sizeof(FFT::input_type) is at least 32 bytes. The following code snippet accounts for different
value formats (as described in Value Formats) and data layouts (as described in
Real Element Layouts and Complex Element Layouts).
// The index of first batch being performed by threads of this block. A batch holds
// FFT::implicit_type_batching FFTs (2 for __half, 1 otherwise), so use implicit_bpb()
// and not FFT::ffts_per_block.
const auto block_fft_id = blockIdx.x * FFT::working_group::implicit_bpb();
// Offset in memory to the first element accessed by threads in this block
const auto block_offset = block_fft_id * FFT::input_length;

// Cast registers to type required as input to FFT execution
using input_t = typename FFT::input_type;
auto shared_fft_data = reinterpret_cast<input_t*>(shared_memory);
auto fft_data = reinterpret_cast<const input_t*>(input);

// Offset, within shared memory, of the batch this thread participates in.
const auto batch_offset = FFT::working_group::batchid() * FFT::input_length;
auto index = FFT::working_group::fftid();
if (FFT::working_group::is_thread_active()) {
    for (int i = 0; i < FFT::input_ept; ++i) {
        if (index < FFT::input_length) {
            shared_fft_data[batch_offset + index] = fft_data[block_offset + batch_offset + index];
        }
        index += FFT::stride;
    }
}
// Results written into shared memory must be visible to the whole block
// before methods #3/#4 of execute() are called.
__syncthreads();
Storing results from shared memory follows the same scheme in reverse. A block-wide synchronization must be
performed first, since execute() leaves its results in shared memory without synchronizing on the caller’s
behalf (see the note on methods #3 and #4 above):
// Block-wide synchronization before shared memory is read back.
__syncthreads();

// Offset in memory to the first output element accessed by threads in this block.
// Uses output_length, not input_length: they differ for R2C/C2R.
const auto block_output_offset = block_fft_id * FFT::output_length;

using output_t = typename FFT::output_type;
auto shared_fft_output = reinterpret_cast<output_t*>(shared_memory);
auto fft_output        = reinterpret_cast<output_t*>(output);

const auto batch_output_offset = FFT::working_group::batchid() * FFT::output_length;
auto output_index = FFT::working_group::fftid();
if (FFT::working_group::is_thread_active()) {
    for (int i = 0; i < FFT::output_ept; ++i) {
        if (output_index < FFT::output_length) {
            fft_output[block_output_offset + batch_output_offset + output_index] =
                shared_fft_output[batch_output_offset + output_index];
        }
        output_index += FFT::stride;
    }
}
The following example shows thread trait-based universal loading scheme for cuFFTDx execution. Here a single thread performs entire FFT, so there is no need to partition data, it will perform a load of entire sequence. This already accounts for different value_formats (as described in Value Formats) and data layouts (as described in Real Element Layouts and Complex Element Layouts).
// This example assumes a 2-dimensional block and 1-dimensional grid

// Which FFT in block is this thread performing
const auto local_fft_id = threadIdx.y * blockDim.x + threadIdx.x;
// Which FFT in grid is this thread performing
const auto global_fft_id = (blockDim.x * blockDim.y) * blockIdx.x + local_fft_id;
// Memory offset for accessing first element of this FFT
const auto global_offset = global_fft_id * FFT::input_length;

// Cast registers to type required as input to FFT execution
using input_t = typename FFT::input_type;
auto thread_fft_data = reinterpret_cast<input_t*>(thread_data);
auto fft_data = reinterpret_cast<const input_t*>(input);

for (unsigned int i = 0; i < FFT::input_length; ++i) {
  thread_fft_data[i] = fft_data[global_offset + i];
}