Cascaded Compression#
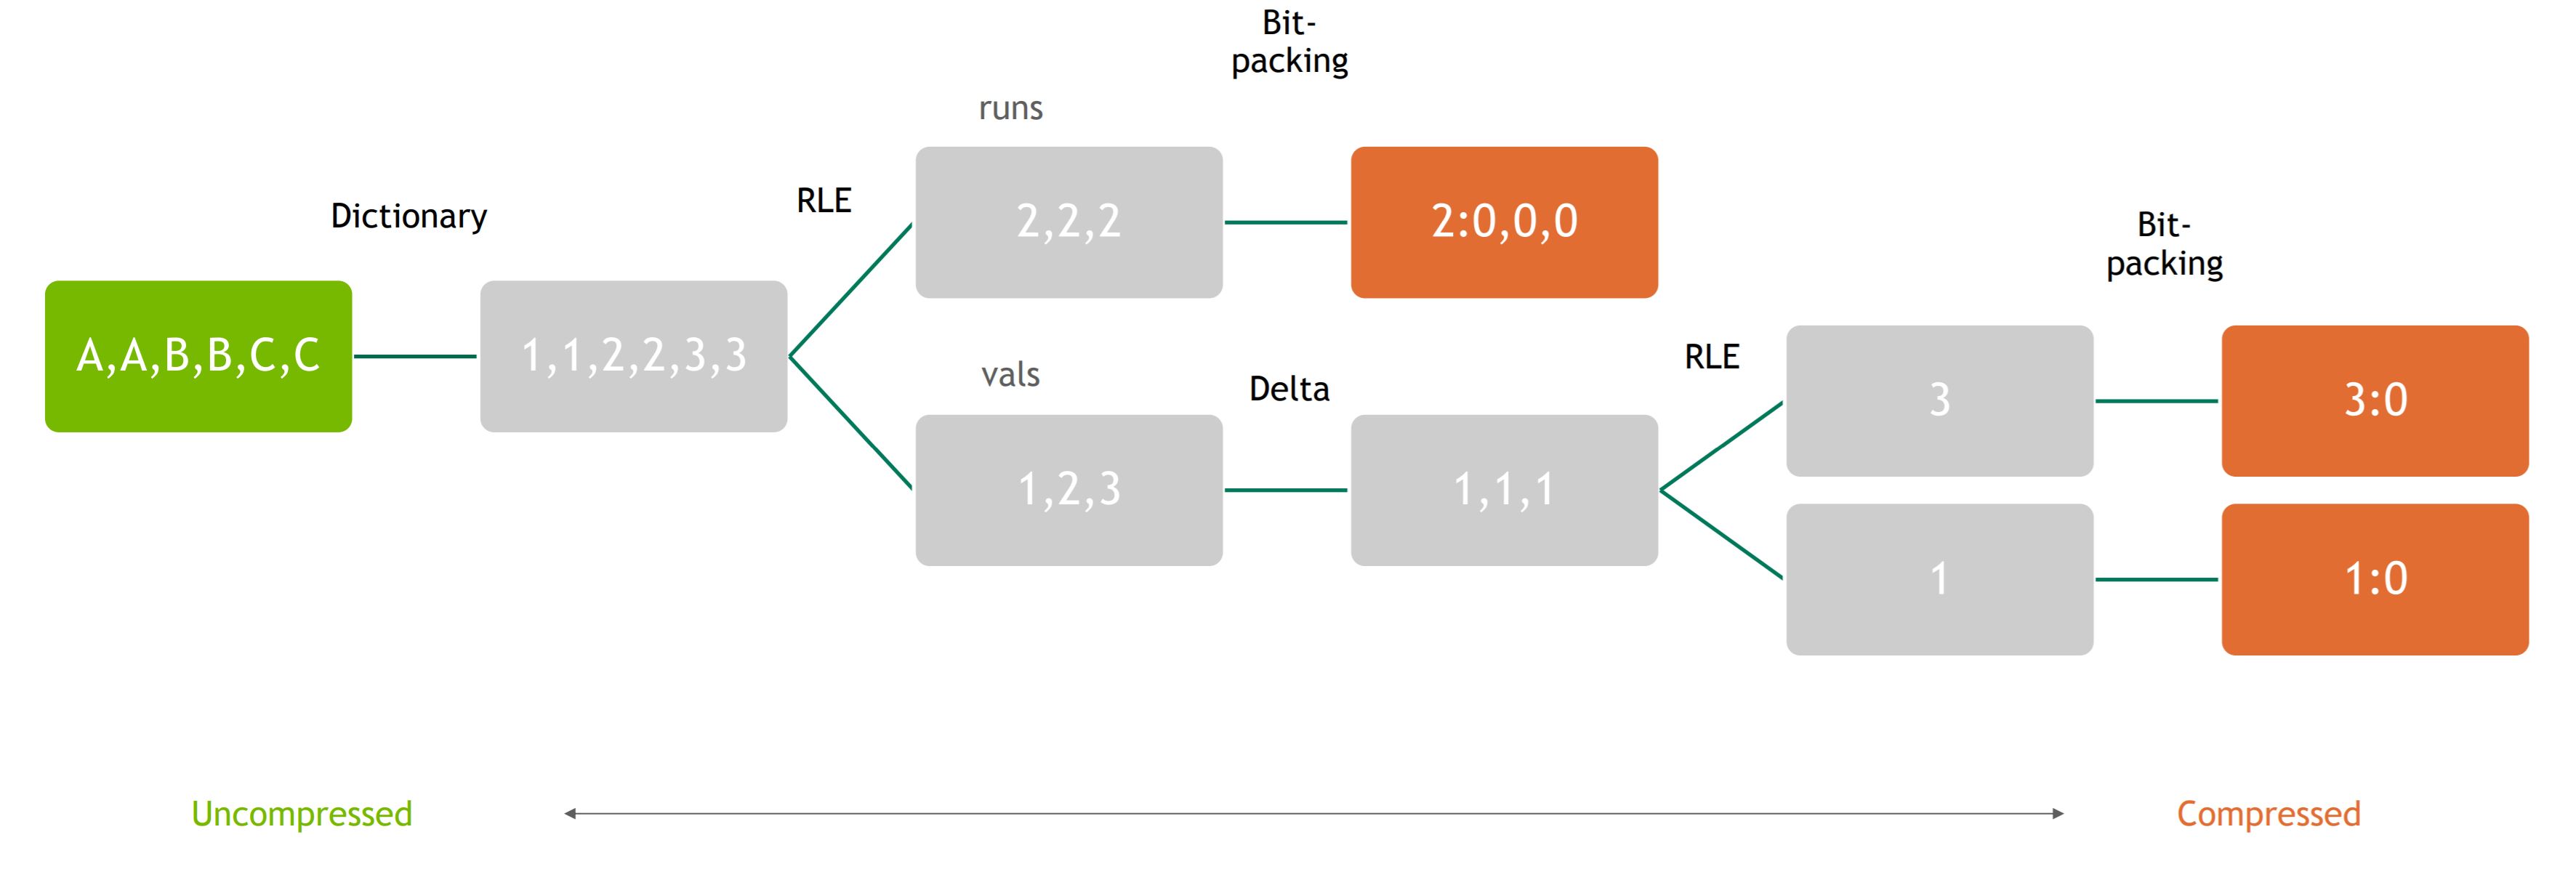
Cascaded compression is a general compression scheme that is ideally suited for analytical workloads. It uses a series of low-level compression building blocks that can be used in combination. Since there are many possible combinations of these building blocks, Cascaded compression can be configured in several different ways. Below is a brief overview of each low-level building block compression scheme.
A more detailed description of each algorithm is available in the GTC 2020 presentation “Software-Based Compression for Analytical Workloads”.
Run-Length Encoding (RLE)#
Run-length encoding is a very simple encoding scheme that compresses repeated values into a single pair: the value and run length (number of repetitions). Since RLE only compresses repeated duplicates, its performance is highly dependent on the input dataset. Note that performing RLE on a sequence of inputs results in two sequences: values and runs. Thus, if every run is of length 1 (no duplicate consecutive values), RLE can result in an expansion of the input by a factor of 2.
Example:
3 9 9 4 4 4 0 0 0 0 0 0 0 0 0 0 1 1 1 1 1 1 -> (3,1) (9,2) (4,3) (0,10) (1,6)
For encoding (compression), nvCOMP uses the low-level RLE kernel available in the CUB library. Overall, the approach is simply to identify the start of each run and compute their lengths. In parallel, we identify the start of each run by having each thread check if a pair of consecutive values differ. We then use a prefix sum operation to compute the length of each run.
Decoding (decompression) is accomplished by first performing a prefix sum on the run lengths to compute the output index of the start of each run. We then simply write the duplicates out for each run, being careful to have sufficient parallelism when writing out large runs.
Delta Encoding#
Delta encoding involves representing each value by its differential (or delta) relative to the previous value in the sequence. While it does not directly compress itself, it provides two potential benefits: 1) reducing the range of values, allowing further compression with bitpacking (described below), and 2) creating more consecutive duplicates that can be compressed by a later RLE step.
Example:
15000 15001 15002 15003 15004 15204 15104 15103 15102 15101 15100 -> 15000 1 1 1 1 200 -100 -1 -1 -1 -1
We can efficiently perform Delta encoding (compression) on the GPU by simply computing the difference between every pair of consecutive values in a thread-parallel manner.
Decoding (decompression) is performed by a simple exclusive prefix sum operation, which we perform using the CUB library implementation.
Frame Of Reference Encoding#
Frame Of Reference (FOR) stores values as offsets from a reference value before bitpacking them. Like Delta encoding, it reduces the range that bitpacking must represent. Asymmetric mode currently requires FOR to be enabled. FOR is optional in symmetric mode, which supports signed and unsigned 32- and 64-bit integer inputs.
Bitpacking#
Bitpacking is a bit-level operation that aims to reduce the number of bits required to store each value. It does this by using only as many bits as needed to represent the range of values that are found in the input data. If the input uses B bits per value and we can pack them into b bits per value, then the achieved compression ratio is approximately B/b.
Example:
15000 15001 15002 15003 15004 15204 15104 15103 15102 15101 15100 -> min:15000, 0 1 2 3 4 204 104 103 102 101 100
Resulting values are all < 256, so each compressed value requires only 8 bits.
The bitpacking compression algorithm has two steps: 1) find min and max values, and 2) encode the input data. We can efficiently find the min and max values with a parallel scan and reduction operation. Once the min and max values are found, the range is computed as max-min, giving us the number of bits, b, needed for each value. We then encode every value in the dataset as val-min, represented using only b bits. We store this encoding along with min as the final compressed bitstring. Note that, if b is not a multiple of the machine word size (32), some symbols may straddle multiple words. We take special care to handle these cases, and details are available in the GTC 2020 presentation “Software-Based Compression for Analytical Workloads”.
Unpacking (decompression) involves computing the full value of each encoded symbol (symbol + min) and writing it out using the full B bits. Since we know B, we can easily compute the output location of each value and perform this in a thread-parallel manner.
The only portion of the cascaded compressor that depends on whether the
specified data type is signed or unsigned is the finding of min and max
values for bitpacking when compressing with no delta encoding, since for
a signed data type, values greater than the maximum signed value will be
interpreted as negative, whereas for an unsigned data type, they will be
interpreted as positive. This means that if the data to be compressed
represent integers that can only be positive, and no delta encoding is
used, it may be beneficial in some cases to specify an unsigned data
type, such as uchar or uint, instead of a signed data type, such
as char or int.
Combining encodings adaptively#
Cascaded has two compression modes:
Asymmetric mode considers RLE and Delta stages independently for each internal chunk and retains a stage only when it reduces the encoded size. It prioritizes compression ratio and requires FOR to be enabled.
Symmetric mode uses the terminal implementation to balance compression and decompression throughput. It supports Delta, RLE, and FOR for signed and unsigned 32- and 64-bit integers.
Asymmetric mode is the default compression mode. Its compression level controls how many optional stages may be considered, and values above the implementation’s current stage capacity select its highest supported level. Symmetric mode currently ignores the compression level and considers every encoding enabled by the fine-grained mask. Cascaded bitpacking is currently required as the terminal codec.
No coarse-grained encodings are currently supported.
The compression options contain common options required during compression and optionally provided during decompression to improve performance: the logical input type, compression mode, terminal-codec mask, and coarse-grained encoding mask. They also select the compression level and fine-grained encoding mask.
Each compressed partition records its mode and selected stages, so
decompression does not require the compression level or fine-grained
encoding mask. When common options are provided during decompression,
their mode must match the compressed stream. A mismatch reports
nvcompErrorCannotDecompress for that chunk and sets its output size
to zero. Leaving the common mode unspecified maximizes decompression
support. High-level native bitstreams record the common options in their
format metadata, and create_manager restores them when
reconstructing a manager.
The example below illustrates how the RLE, Delta, and bitpacking building blocks can be combined.