
Working with DLA#
Important
DLA is not supported in TensorRT 11.3.0 or in TensorRT 11.3.1 for DriveOS. TensorRT 10.7 was the last release that supported DLA. DLA was also not supported in TensorRT 11.0, 11.1, or 11.2.
The guidance in this section is reference material for supported earlier releases. Do not use it as a support claim for TensorRT 11.3.0 or for TensorRT 11.3.1 for DriveOS.
Reference for earlier releases#
NVIDIA DLA (Deep Learning Accelerator) is a fixed-function accelerator engine targeted for deep learning operations. It is designed to fully hardware accelerate convolutional neural networks. DLA supports various layers, such as convolution, deconvolution, fully connected, activation, pooling, and batch normalization. Refer to the DLA Supported Layers and Restrictions section for Jetson and DriveOS DLA support.
DLA is useful for offloading CNN processing from the GPU and is significantly more power-efficient for these workloads. In addition, it can provide an independent execution pipeline in cases where redundancy is important, such as mission-critical or safety applications.
For more information, refer to the DLA Developer page and the DLA tutorial Getting Started with the Deep Learning Accelerator on NVIDIA Jetson Orin.
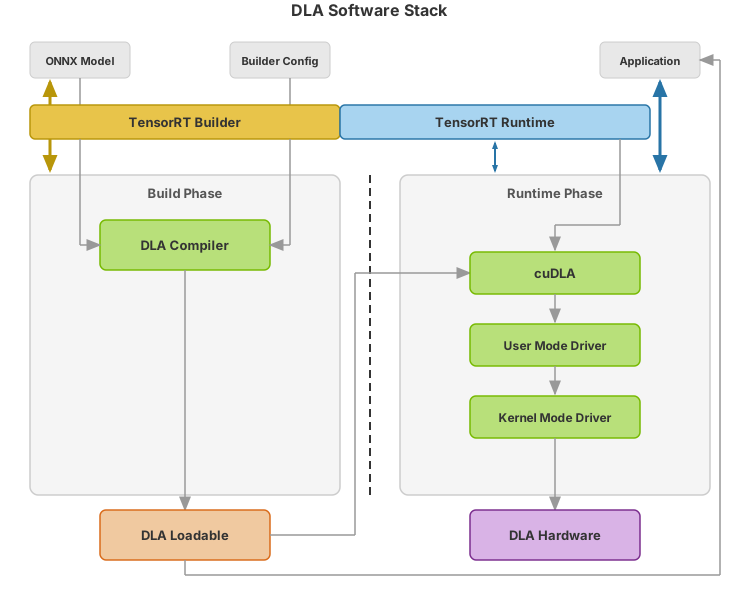
When building a model for DLA, the TensorRT builder parses the network and calls the DLA compiler to compile the network into a DLA loadable. Refer to Using trtexec to learn how to build and run networks on DLA.
In this guide
Building and Launching the Loadable: build and launch DLA loadables with
trtexec, the TensorRT API, and cuDLAStrongly Typed Networks for DLA: specify FP16 and quantized DLA networks with strong typing
ONNX Parser Flags for DLA: configure DLA-specific ONNX parsing, adjustment, and capability reporting
DLA Supported Layers and Restrictions: Jetson and DriveOS DLA supported layers, formats, and hardware limits
DLA Runtime Configuration: configure GPU fallback, I/O formats, workspace allocation, and tensor registration
DLA Standalone Mode: generate standalone DLA loadables outside TensorRT
Customizing DLA Memory Pools: customize DLA SRAM/DRAM pools and structured sparsity