Network Logical Architecture#
This RA uses a converged spine-leaf network providing physical fabrics for the use cases such as inferencing and fine-tuning. Deeper explanations of each of the fabric roles are below:
GPU Compute (East/West) Network
The GPU Compute (East/West) network is an RDMA based fabric in a leaf-spine architecture where the GPUs are connected using a rail-optimized network topology through their respective SuperNICs. This design allows the most efficient communication for multi-GPU applications within and across the compute nodes due to the high number of endpoints needed. The leaf-spine networking architecture also allows for future extensibility.
CPU Converged (North/South) Network
The CPU Converged (North/South) network connects the nodes using two 200 GbE ports to two separate switches to provide redundancy and high storage throughput. This network is used for node communications with compute, storage, in-band management, and end-user connections.
Storage (North/South) connectivity
This network specifically provides converged connectivity for storage infrastructure. Principally storage is attached on this network and then can be provided to the nodes via the CPU Compute network as required.
Customer (North/South) Network Connectivity
Typically, this is upstream connectivity to connect the cluster into the rest of an Enterprise customers networking infrastructure. This is provisioned to provide ample bandwidth for typical user communications.
Support Server Networking
This is dedicated networking for the respective support servers. These servers generally provide management, provisioning, monitoring, and control services to the rest of the cluster. High performance networking is used here due to requirements such as cluster deployment and imaging.
Out-of-band Management Networking for the infrastructure
All infrastructure requires management. This network provides bulk management 1Gb RJ45 connectivity for all the Nodes. This network uses low-cost bulk management switches. These switches have upstream connections to the Core networking infrastructure to allow flexibility and wider consolidation of services such as management and monitoring.
Note
VLAN isolation would be used to provide logical separation of the networks above over the single physical fabric.
Enterprise RA Scalable Unit (SU)#
The RA is built on scalable units (SU) based on 4 compute nodes. Each SU is a discrete entity of computation that is tied to the port availability size of the network devices. SUs can be replicated to adjust the scale of the deployment with more ease.
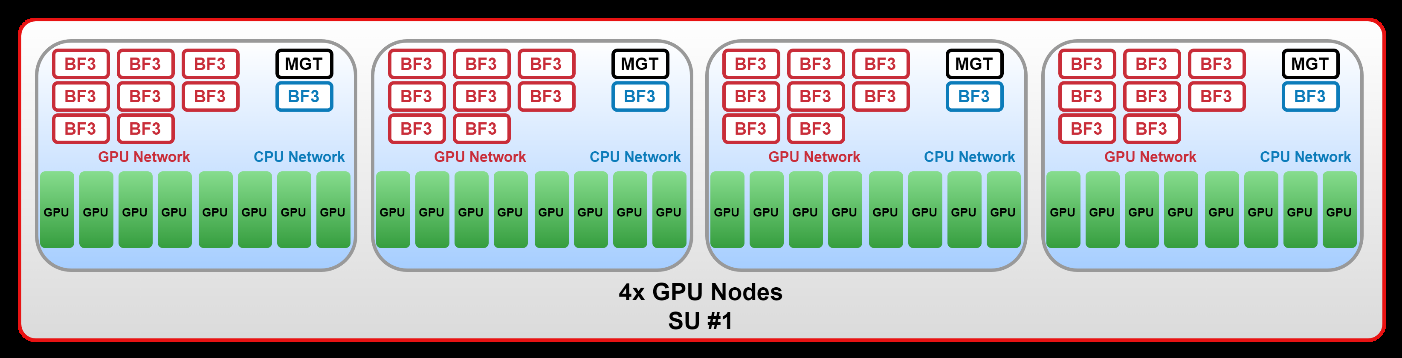
Figure 10 Example diagram of 4-Node SU.#
The 4-Node scalable unit provides the following connectivity building blocks:
For the Compute (E-W) fabric: 4 servers, each with 8x B3140H SuperNICs, providing 32x 400Gb/s connections and a total aggregate bandwidth of 12.8Tb/s
For the Converged (N-S) fabric: 4 servers, each with 1x B3220 DPU providing 8x 200Gb/s connections and a total aggregate bandwidth of 1.6Tb/s
For the Out-of-band Management fabric, 4 servers, each with 12x 1Gb/s connections providing 48x 1Gb/s for management
Spine-Leaf Networking#
The network fabrics are built using switches with NVIDIA Spectrum-X Ethernet technology in a full nonblocking fat tree topology to provide the highest level of performance for the application running over the RA configuration. The networks are RDMA compliant based fabrics in a leaf-spine architecture where the GPUs are connected using a rail-optimized network topology through their respective SuperNICs. This design allows the most efficient communication for multi-GPU applications within and across the nodes.
The leaf and spine architecture allows for a scalable and reliable network that can fit varied sizes of clusters using the same architecture. The compute network is designed to maximize bandwidth and minimize network latency required to connect GPUs within a server and within a rail.
In addition to the supported compute fabrics the converged spine-leaf network also supports the following attributes:
Provides high bandwidth to high performance storage and connects to the data center network.
Each compute and management node is connected with two 200 GbE ports to two separate switches to provide redundancy and high storage throughput.
Out-of-Band (OOB) Management Network#
The OOB management network connects the following components:
Base management controller (BMC) ports of the server nodes
BMC ports of the Bluefield-3 DPU and SuperNICs
OOB management ports of switches
This OOB network can also connect other devices that should have management connectivity physically isolated for security purposes. The SN2201 is used to connect to the BMC/OOB 1 Gbps ports of these components. Scale out this network using a 25 Gbps or 100 Gbps spine layer to connect the SN2201 uplink switches.
Optimized Use Case#
This architecture is optimized for both inference and training use cases. Deployment of this single architecture will enable both types of workloads.
Architecture Details#
The components of the Enterprise HGX H100, H200 or B200 8-GPU Spectrum RA using Spectrum-X 400 Gbps for the compute fabric are described in Table 6.
Table 6: HGX H100, H200 or B200 8-GPU Server Ethernet components with Spectrum-X fabric.
Component |
Technology |
|---|---|
Compute node servers (4-128) |
HGX H100, H200 or B200 8-GPU Servers with 8 NVIDIA H100, H200 or B200 SXM GPUs, configured with |
Compute (E-W) Spine-Leaf Fabric |
NVIDIA SN5600 / SN5610 128-port 400 GbE switches |
Converged (N-S) Spine-Leaf Fabric |
NVIDIA SN5600 / SN5610 128-port 400 GbE switches |
OOB management fabric |
NVIDIA SN2201 48-port 1 Gb plus 4-port 100 GbE |
Compute (Node East-West) Fabric Table#
Table 7 below shows the number of cables and switches required for the Compute (Node East-West) Fabric for different SU sizes.
Table 7: Compute (Node East-West) and switch component count.
Compute Counts |
Switch Counts |
Transceiver Counts |
Cable Counts |
|||||||
|---|---|---|---|---|---|---|---|---|---|---|
Nodes |
GPUs |
SUs |
Leaf |
Spine |
Super-spine |
Node-to-Leaf (Compute) |
Node-to-Leaf (Switch) |
Switch-to-Switch |
Compute-to-Leaf |
Switch-to-Switch |
32 |
256 |
8 |
4 |
2 |
N/A |
256 |
128 |
256 |
256 |
256 |
64 |
512 |
16 |
8 |
4 |
N/A |
512 |
256 |
512 |
512 |
512 |
128 |
1024 |
32 |
16 |
8 |
N/A |
1024 |
512 |
1024 |
1024 |
1024 |
Converged (Node North-South) Fabric Table#
Table 8 below shows the number of cables and switches required for the Converged (Node North-South) Fabric for different SU sizes.
Note
For lower node counts where the Converged Network has been consolidated with the Compute Network the transceiver and cables are additional to the quantities in Table 7.
Table 8: Converged (Node North-South) and switch component count.
Compute Counts |
Switch Counts |
Converged Network Allocated Ports |
Transceiver Counts |
Cable Counts |
|||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
Nodes |
GPUs |
SUs |
Leaf |
Spine |
CPU (Node N-S) |
Storage |
Mgmt. Uplinks |
Customer |
Support |
ISL Ports (both ends) |
Node-to-Leaf (Node) |
Node-to-Leaf (Other) |
Switch |
Switch-to-Switch |
Node-to-Leaf |
Others-to-Leaf |
Switch-to-Switch |
32 |
256 |
8 |
2 |
N/A |
16 |
8 |
4 |
16 |
4 |
18 |
64 |
112 |
32 |
28 |
64 |
32 |
20 |
64 |
512 |
16 |
2 |
N/A |
32 |
16 |
4 |
32 |
4 |
32 |
128 |
208 |
60 |
50 |
128 |
56 |
36 |
128 |
1024 |
32 |
6 |
4 |
64 |
32 |
8 |
64 |
4 |
384 |
256 |
400 |
116 |
420 |
256 |
104 |
392 |
32 Nodes with 256 HGX H100, H200 or B200 SXM GPUs#
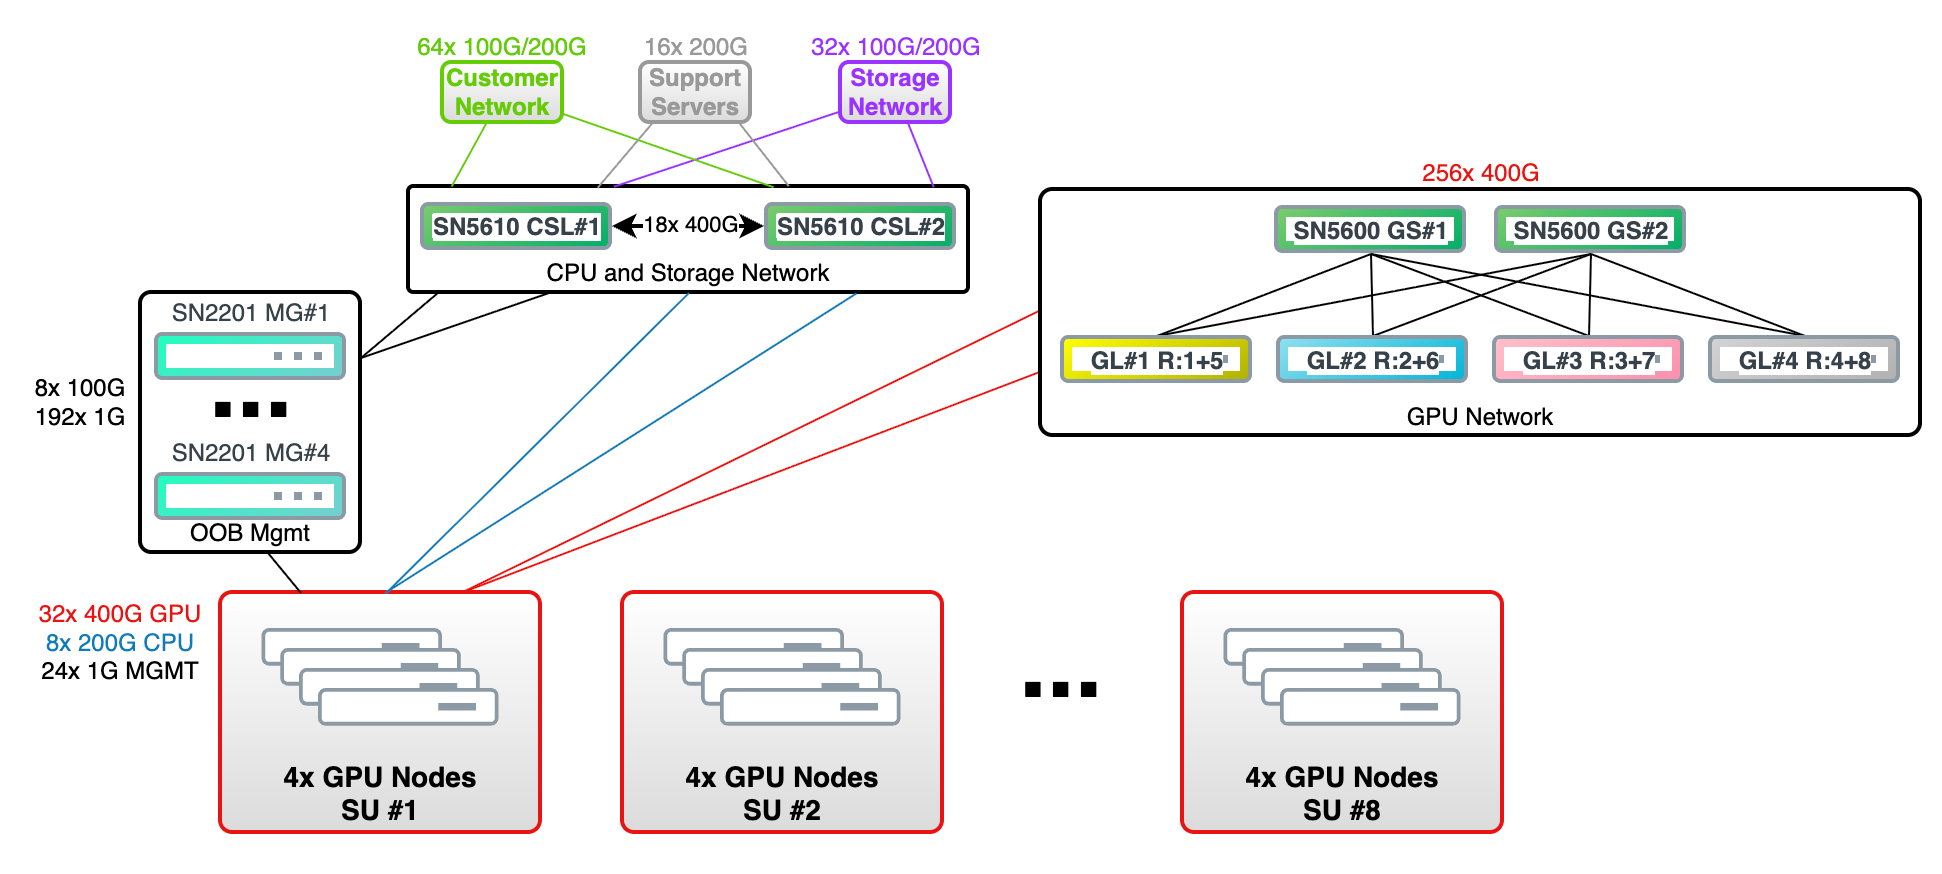
Figure 11 HGX H100, H200 or B200 8-GPU Spectrum RA with 32 servers (256 GPUs).#
Architecture Overview
32 NVIDIA HGX H100, H200 or B200 8‑GPU servers (256 GPUs) in 2‑8‑9‑400 configuration with NVIDIA Spectrum‑X compute fabric.
8 scalable units (SUs) with 4 server nodes per unit; networking infrastructure designed to scale between four and eight SUs.
Network Design
Cost‑efficient collapsed spine‑leaf design for all fabrics except GPU Compute (East/West) Network.
GPU Compute (East/West) Network uses a separate, isolated leaf‑spine architecture for high‑bandwidth, low‑latency node‑to‑node communication.
Spectrum fabric for the Compute (Node East/West) Network is rail‑optimized and non‑blocking using 64‑port switches in a full spine‑leaf design for high availability, resiliency, and load‑balancing.
Each plane has 4 leaf switches, with each leaf supporting 2 rails (1+5, 2+6, 3+7, 4+8).
Port breakout functionality is used wherever possible to consolidate ports while maintaining resiliency.
Connectivity (Under Optimal Conditions)
32× 400G uplinks per SU for GPU Compute traffic (East/West).
8× 200G uplinks per SU for CPU traffic (North/South).
Cluster designed for up to 8 support server nodes, all dual‑connected at 200Gb.
64× 100G/200G connections to the customer network, providing at least 25Gb bandwidth per GPU.
32× 100G/200G connections for storage, providing at least 12.5Gb bandwidth per GPU.
Management
SN2201 switch for every SU; for the 32‑node design this results in 4 SN2201 switches uplinked to the core via 2×100G links per switch.
200 GbE management fabric with high availability using two 100GbE connections to the core network.
All nodes are connected to 1Gb management switches, which are uplinked into the core network.
Additional Considerations
VLAN isolation separates the various fabrics on the converged (Node North/South) Network that are collapsed into the shared physical infrastructure
Rack layout must provide power supply redundancy; alternative layouts should be considered if this cannot be achieved
Number of NVIDIA HGX H100, H200 or B200 8‑GPU servers per rack depends on available rack power
64 Nodes with 512 HGX H100, H200 or B200 SXM GPUs#
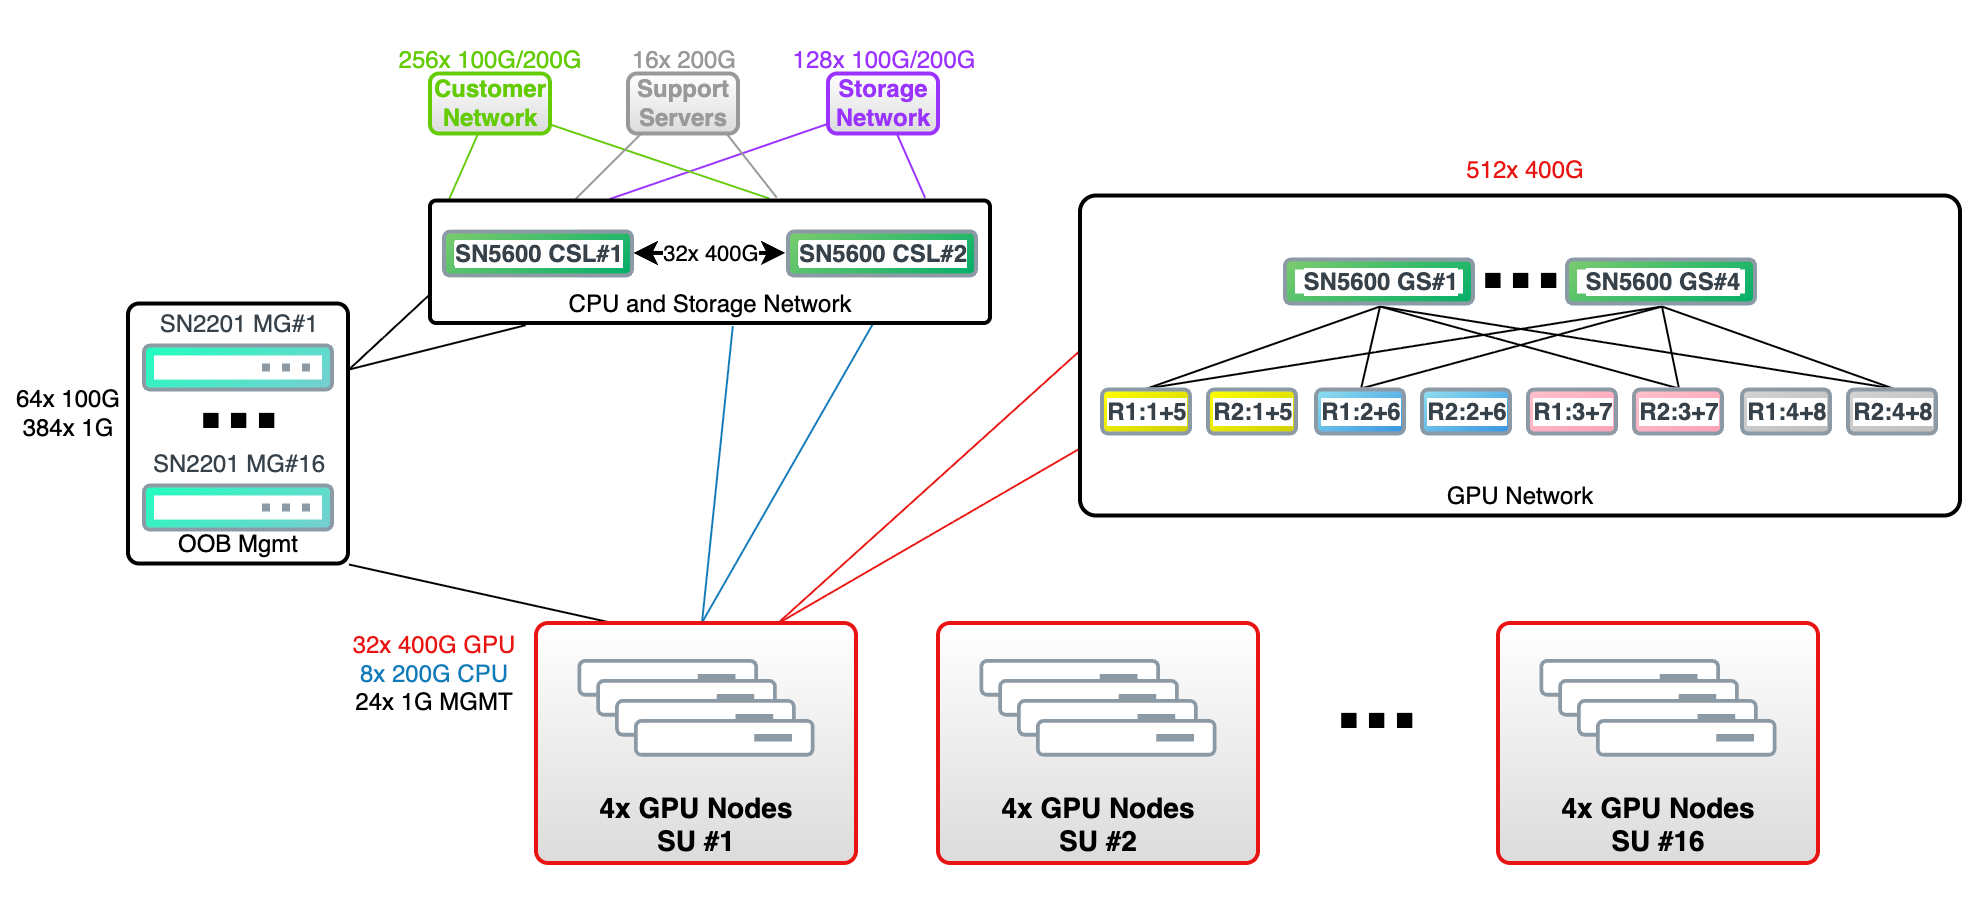
Figure 12 HGX H100, H200 or B200 8-GPU Spectrum RA with 64 servers (512 GPUs).#
Architecture Overview
64 NVIDIA HGX H100, H200 or B200 8‑GPU servers (512 GPUs) in 2‑8‑9‑400 configuration with NVIDIA Spectrum‑X compute fabric.
16 scalable units (SUs) with 4 server nodes per unit; networking infrastructure designed to scale between eight and sixteen SUs.
Network Design
Cost‑efficient spine‑leaf design for all fabrics except the GPU Compute (East/West) Network.
GPU Compute (East/West) Network uses a separate, isolated leaf‑spine architecture to provide high‑bandwidth, low‑latency node‑to‑node communication
Spectrum fabric for the Compute (Node East/West) Network is rail‑optimized and non‑blocking using 64‑port switches to deliver high availability, resiliency, and load‑balancing
In this design there are 8 leaf switches (in 2 planes of 4), with each leaf supporting 2 rails (1+5, 2+6, 3+7, 4+8)
Port breakout functionality is used wherever possible to consolidate ports while maintaining resiliency
Connectivity (Under Optimal Conditions)
32× 400G uplinks per SU for GPU Compute traffic (East/West)
8× 200G uplinks per SU for CPU traffic (North/South)
Cluster designed for up to 16 support server nodes, all dual‑connected at 200Gb
256× 100G/200G connections to the customer network, providing at least 25Gb of bandwidth per GPU
128× 100G/200G connections for storage attachment, providing at least 12.5Gb of bandwidth per GPU
Management
SN2201 switch for every SU; for the 64‑node design this results in 16 SN2201 switches uplinked to the core via 2× 100G links per switch
200 GbE management fabric with high availability using two 100GbE connections to the core network
All nodes are connected to 1Gb management switches, which are uplinked into the core network
Additional Considerations
VLAN isolation separates the various fabrics on the converged (Node North‑South) Network that are collapsed into the shared physical infrastructure
Rack layout must provide power supply redundancy; alternative layouts should be considered if this cannot be achieved
Number of NVIDIA HGX H100, H200 or B200 8‑GPU servers per rack depends on available rack power
128 Nodes with 1024 HGX H100, H200 or B200 SXM GPUs#
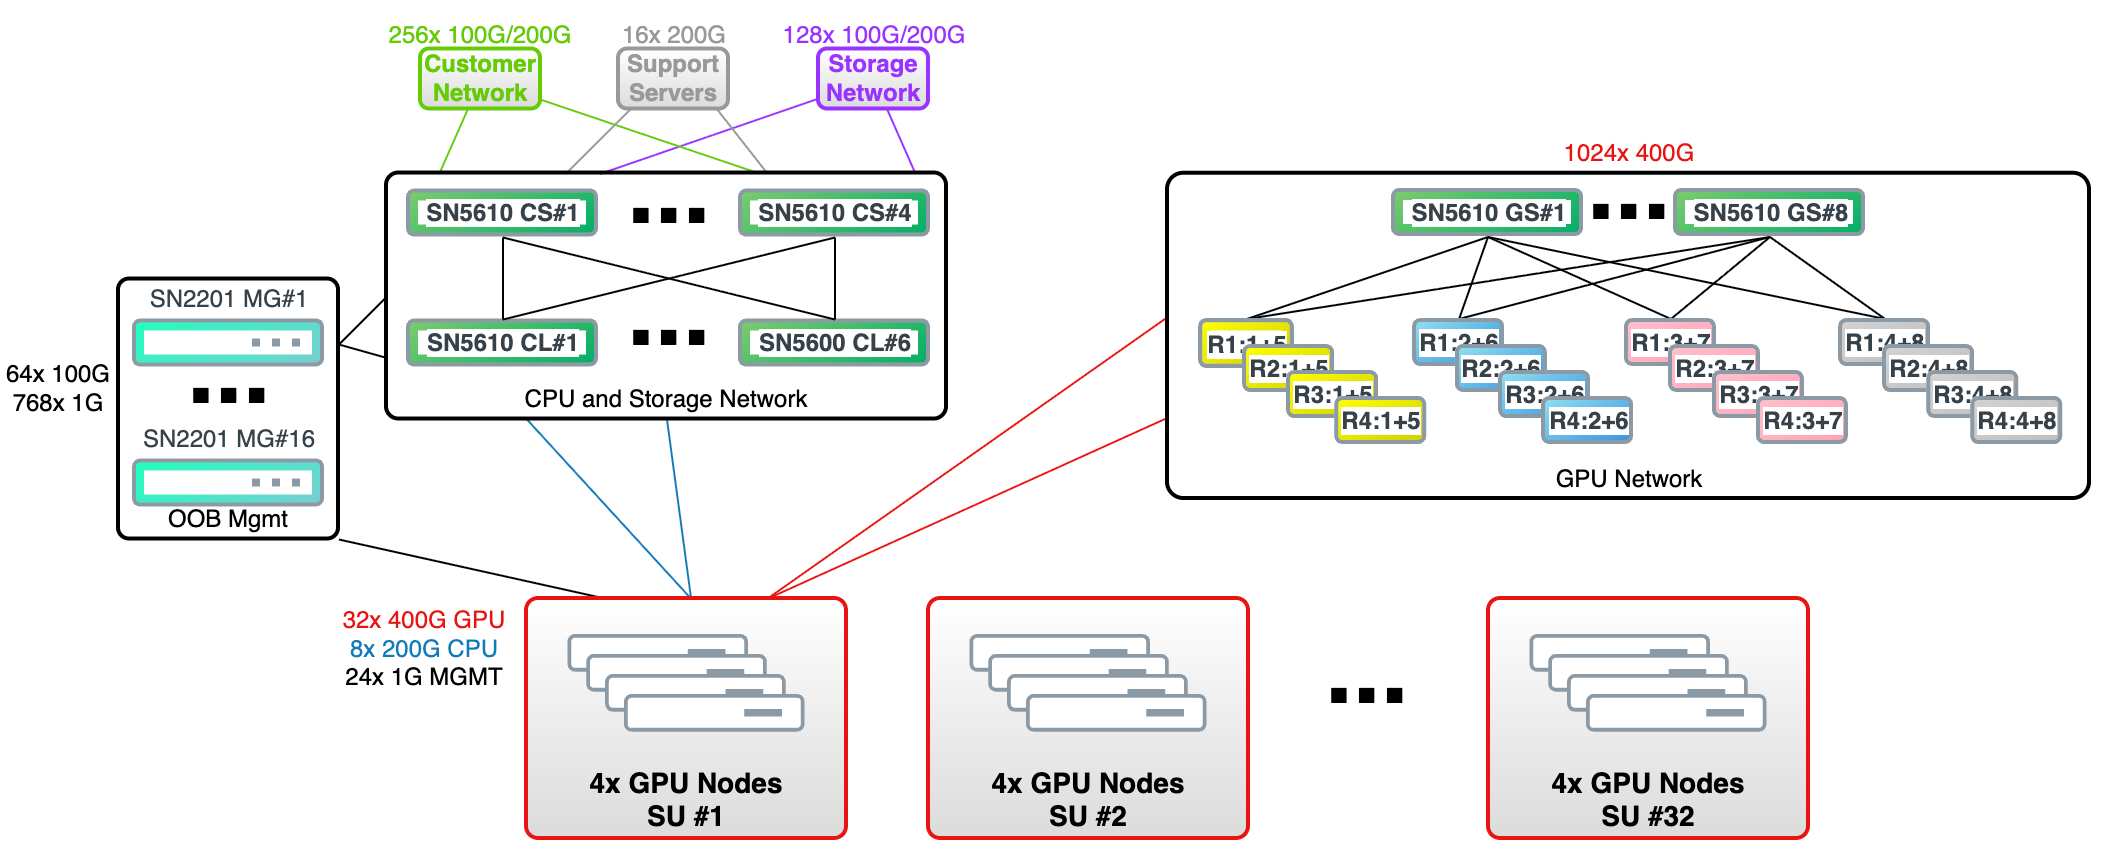
Figure 13 HGX H100, H200 or B200 8-GPU Spectrum RA with 128 servers (1,024 GPUs).#
Architecture Overview
128 NVIDIA HGX H100, H200 or B200 8‑GPU servers (1,024 GPUs) in 2‑8‑9‑400 configuration with NVIDIA Spectrum‑X compute fabric
32 scalable units (SUs) with 4 server nodes per unit; networking infrastructure designed to scale between eight and thirty‑two SUs
Network Design
Cost‑efficient spine‑leaf design for all fabrics except the GPU Compute (East/West) Network
GPU Compute (East/West) Network uses a separate, isolated leaf‑spine architecture to provide high‑bandwidth, low‑latency node‑to‑node communication
Spectrum fabric for the Compute (Node East/West) Network is rail‑optimized and non‑blocking using 64‑port switches to deliver high availability, resiliency, and load‑balancing
In this design there are 16 leaf switches (in 4 blocks of 4), with each leaf supporting 2 rails (1+5, 2+6, 3+7, 4+8)
Port breakout functionality is used wherever possible to consolidate ports while maintaining resiliency
Connectivity (Under Optimal Conditions)
32× 400G uplinks per SU for GPU Compute traffic (East/West)
8× 200G uplinks per SU for CPU traffic (North/South)
Cluster designed for up to 8 support server nodes, all dual‑connected at 200Gb
256× 100G/200G connections to the customer network, providing at least 25Gb of bandwidth per GPU
128× 100G/200G connections for storage attachment, providing at least 12.5Gb of bandwidth per GPU
Management
SN2201 switch for every SU; for the 128‑node design this results in 32 SN2201 switches uplinked to the core via 2× 100G links per switch.
200 GbE management fabric with high availability using two 100GbE connections to the core network.
All nodes are connected to 1Gb management switches, which are uplinked into the core network.
Additional Considerations
VLAN isolation separates the various fabrics on the converged (Node North‑South) Network that are collapsed into the shared physical infrastructure.
Rack layout must provide power supply redundancy; alternative layouts should be considered if this cannot be achieved.
Number of NVIDIA HGX H100, H200 or B200 8‑GPU servers per rack depends on available rack power.