


About Model-Free NIM#
Model-free NIM lets you run any supported model in NIM LLM and VLM without a model-specific container image.
By default, NIM containers ship with a built-in model manifest that defines which model to serve. In model-free mode, you point a generic NIM container at any supported model, such as a Hugging Face repository, an S3 bucket, or a local directory. NIM then generates a manifest at startup and serves that model.
Some images include tuned serving recipes, while other deployments require a separate recipe file. Recipe requirements depend on the model and image version.
How It Works#
When you start a model-free container, you supply a model location with NIM_MODEL_PATH or with the backend positional argument. NIM generates a runtime manifest for that source, selects a profile, and serves the model.
If you do not set a served name, NIM derives one from the model source by removing the URI scheme and any trailing :<version>, then replacing any : that remains. That derived name is the value to use in the model field of inference requests, and it is what /v1/models reports.
For air-gap redeploys, a network-connected start saves the generated manifest in the container cache (NIM_CACHE_PATH). If manifest generation fails during an offline restart, NIM falls back to that cached manifest. For the full air-gap workflow, refer to Air-Gap Deployment.
Profile listing, URI schemes, and download behavior are documented in the configuration sections that follow. For profile selection details, refer to Model Profiles and Selection. For source-specific download steps, refer to Model Download.
Limitations and Considerations#
The following limits apply when you choose a model-free NIM container.
Unsupported architectures: The backend in the container (vLLM or SGLang) must support the model architecture.
Remote URI first deploy: A remote
NIM_MODEL_PATH(for example,ngc://orhf://) requires network access and credentials on the first deployment so NIM can generate and cache the runtime manifest.
Note
Regardless of where the model is hosted, if its architecture is unsupported by the inference backend in your container (vLLM or SGLang), it is also unsupported by NIM.
Configuring the Model-Free NIM Container Image#
The latest model-free NIM container images are in the NGC Catalog:
Set NIM_LLM_IMAGE to the image name and tag from the catalog page. Model download commands use this value.
export NIM_LLM_IMAGE="nvcr.io/nim/nvidia/<nim-model-free-image-tag>:<version>"
Configuring the Model#
Supply the model path and name using either of these methods. If both are provided, the CLI positional argument takes precedence.
NIM_MODEL_PATH Environment Variable#
Use NIM_MODEL_PATH to point the container to the model at runtime:
docker run --gpus=all \
  -e NIM_MODEL_PATH=hf://meta-llama/Llama-3.1-8B-Instruct \
  -e HF_TOKEN=<yourtoken> \
  -p 8000:8000 \
  ${NIM_LLM_IMAGE}
Model Path as a Container Argument#
Pass the model path as the first positional argument to the container:
docker run --gpus=all \
  -e HF_TOKEN=<yourtoken> \
  -p 8000:8000 \
  ${NIM_LLM_IMAGE} \
  hf://meta-llama/Llama-3.1-8B-Instruct
Default Model Name#
If you do not set a name, NIM derives one from the model source by removing the URI
scheme and any trailing :<version>, then replacing any : still left. The result is
the name to use in the model field of inference requests, and it is what /v1/models
reports.
Model source |
Derived model name |
|---|---|
|
|
|
|
|
|
|
|
|
|
|
|
The derived name is the same regardless of which inference backend the image uses.
Note
A derived name never contains :. If the model source has one, NIM replaces it, because
some backends read : in the model field as a base-model:lora-adapter separator and
would reject every request.
A name you set yourself is used verbatim and is not adjusted. On a backend that reserves
:, setting one that contains it fails at startup with a message naming the value,
rather than starting and rejecting every request.
NIM_SERVED_MODEL_NAME Environment Variable#
Use NIM_SERVED_MODEL_NAME to set the model name used in inference requests:
docker run --gpus=all \
  -e NIM_SERVED_MODEL_NAME=meta-llama/Llama-3.1-8B-Instruct \
  ...
CLI Argument#
Use the CLI argument --served-model-name to pass the model name used in inference requests.
docker run --gpus=all \
  ...
  --served-model-name "meta-llama/Llama-3.1-8B-Instruct"
Run with a Downloaded Serving Recipe#
Model-free NIM can use generic defaults, an automatically selected built-in recipe, or a separately downloaded serving recipe. Use this workflow only when the model-free NIM specifies an NGC collection that includes a separate recipe for the model. Otherwise, use the standard launch commands on this page and any model-specific startup settings.
Before starting, check the model entry in the
Support Matrix under Model-Free NIM. If the
entry says that you need to download and select the recipe from a collection,
then use the following steps to download the applicable recipe and select it
using NIM_CONFIG_FILE.
Install and configure the NGC CLI. Run
ngc config setand follow the prompts to configure your NGC account before downloading resources.Open the model’s NGC collection and find the correct recipes asset. It should have type Resource.
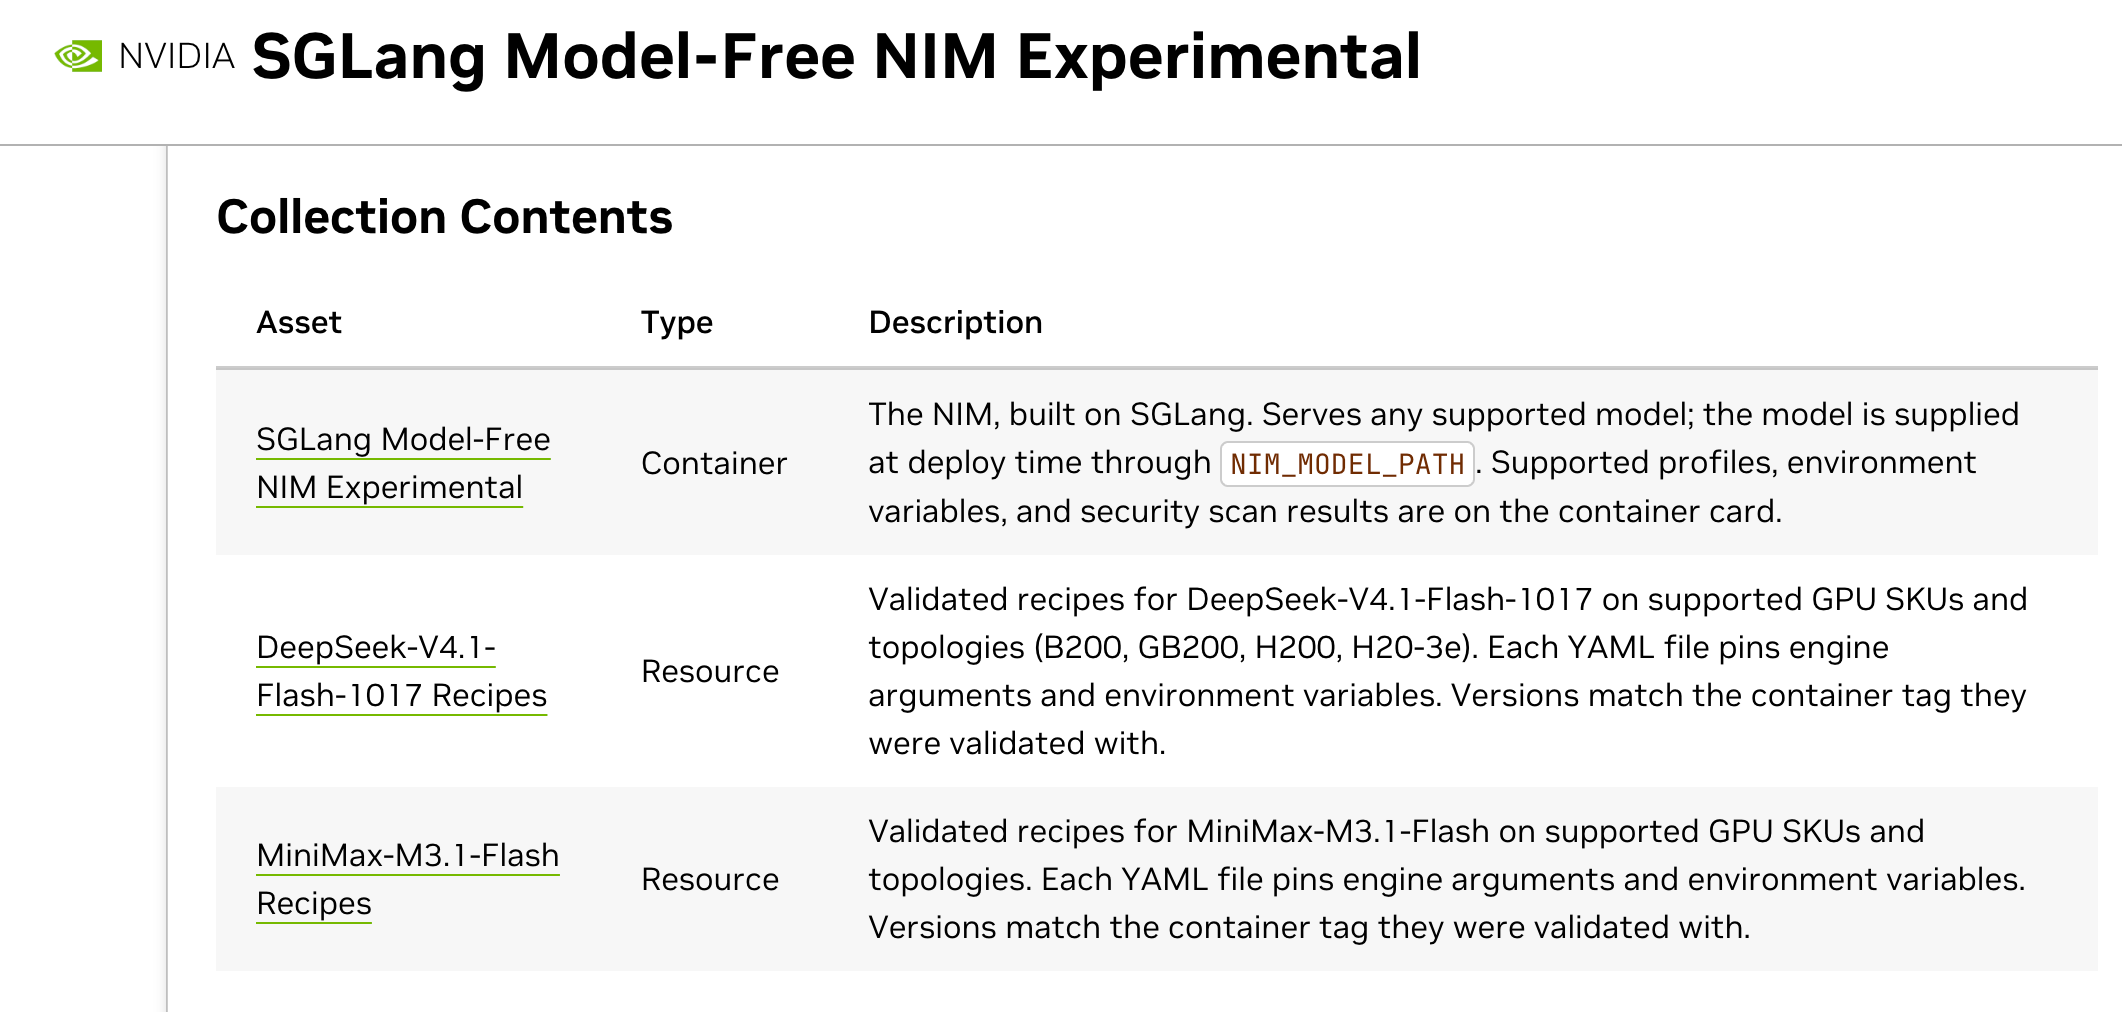
Click the link to the recipe.
Select the recipe version specified by the model guide for your container image. Click the Download button and then the copy button to copy the recipe download command.
Run the copied command in your terminal to download the recipes. The command has the following format:
ngc registry resource download-version "<org>/<team>/<recipe-resource>:<recipe-version>"
Select the YAML file for your checkpoint, GPU, and topology. Set the image, model source, absolute host path to the downloaded file, and required GPU count using values from the model guide:
export NIM_LLM_IMAGE="<container-image>:<matching-tag>"
export NIM_MODEL_PATH="hf://<publisher>/<checkpoint>"
export RECIPE="/absolute/path/to/downloaded/recipe.yaml"
export GPU_COUNT="<required-gpu-count>"
chmod 0644 "$RECIPE"
The recipe must be readable by the container user. Downloading the recipe does not download the model weights. NIM downloads those from
NIM_MODEL_PATHat startup.Configure
LOCAL_NIM_CACHEand model-source credentials by following Configuration. Apply any additional options required by the model guide, such as custom-code permissions, shared memory, or GPU interconnect settings. For multiple nodes, follow Multi-Node Deployment.Mount the recipe read-only and set
NIM_CONFIG_FILEto its path inside the container. The following command is a single-node launch template with Hugging Face credentials and a persistent cache:docker run --rm --gpus "$GPU_COUNT" --ipc=host --shm-size=32g \ -e NIM_MODEL_PATH="$NIM_MODEL_PATH" \ -e HF_TOKEN \ -e NIM_CONFIG_FILE=/opt/nim/recipe.yaml \ -v "$LOCAL_NIM_CACHE:/opt/nim/.cache" \ -v "$RECIPE:/opt/nim/recipe.yaml:ro" \ -p 8000:8000 \ "$NIM_LLM_IMAGE" \ nim-serve
In another terminal, wait for readiness, then query the served model name:
curl -f http://localhost:8000/v1/health/ready
curl -s http://localhost:8000/v1/models
Repeat the readiness check until it returns HTTP 200. Use the
idreturned by/v1/modelsin inference requests. A recipe can supply the served name.
Supported Model Sources#
The following table lists the model sources supported by model-free NIM, along with the required URI prefix and authentication method.
Prefix |
Source |
Example |
Authentication |
|---|---|---|---|
|
Hugging Face Hub |
|
|
|
NVIDIA NGC |
|
|
|
AWS S3 / S3-compatible |
|
|
|
ModelScope Hub |
|
|
|
Google Cloud Storage |
|
|
(absolute path) |
Local directory |
|
None |
For details on downloading models from each source (including URI formats, proxy configuration, and cache management), refer to Model Download.
Configuring Deployment Options#
Model-free NIM generates profiles for combinations of tensor parallelism (TP), pipeline parallelism (PP), and LoRA. To select a deployment configuration, use either of the following methods. If both are provided, backend CLI arguments take precedence.
NIM_MODEL_PROFILE Environment Variable#
Run list-model-profiles to see available profiles, then select one:
docker run --gpus=all \
  -e NIM_MODEL_PATH=hf://meta-llama/Llama-3.1-8B-Instruct \
  -e NIM_MODEL_PROFILE=<profile-id-or-description> \
  -e HF_TOKEN=<yourtoken> \
  -p 8000:8000 \
  ${NIM_LLM_IMAGE}
Generated descriptions take the form <engine>-tp<N>-pp<M>[-feat_lora]-<hash>, where <engine> is vllm or sglang depending on the image (for example vllm-tp2-pp1-<hash> or sglang-tp2-pp1-<hash>). Copy the exact ID or description from list-model-profiles output.
Container Arguments#
Use NIM environment variables or canonical CLI flags to configure settings shared by both inference engines:
docker run --gpus=all \
  -e NIM_TENSOR_PARALLEL_SIZE=2 \
  -e HF_TOKEN=<yourtoken> \
  -p 8000:8000 \
  ${NIM_LLM_IMAGE} \
  hf://meta-llama/Llama-3.1-8B-Instruct
Alternatively, pass the canonical flag --tensor-parallel-size 2 after the model path:
docker run --gpus=all \
  -e HF_TOKEN=<yourtoken> \
  -p 8000:8000 \
  ${NIM_LLM_IMAGE} \
  hf://meta-llama/Llama-3.1-8B-Instruct \
  --tensor-parallel-size 2
NIM translates canonical flags into the selected inference engine’s arguments. Common settings include:
Setting |
NIM Environment Variable |
Canonical Flag |
|---|---|---|
Tensor parallelism |
|
|
Pipeline parallelism |
|
|
For LoRA profile selection, refer to Fine-Tuning with LoRA. For backend-specific arguments and configuration precedence, refer to Advanced Configuration.
Listing Profiles#
Use the list-model-profiles command to view the profiles generated for a given model:
docker run --gpus=all \
  -e NIM_MODEL_PATH=hf://meta-llama/Llama-3.1-8B-Instruct \
  -e HF_TOKEN=<yourtoken> \
  ${NIM_LLM_IMAGE} \
  list-model-profiles
For more details on profile selection, refer to Model Profiles and Selection.
S3-Specific Environment Variables#
The following environment variables authenticate and configure S3 and S3-compatible endpoints:
Variable |
Required |
Purpose |
|---|---|---|
|
Yes |
AWS access key |
|
Yes |
AWS secret key |
|
Yes |
AWS region (for example, |
|
Only for S3-compatible |
Custom endpoint (for example, |
|
Only for S3-compatible |
Set to |
For complete authentication and configuration details for each source, refer to Model Download.
Air-Gap Deployments#
How model-free NIM behaves in an air-gap environment depends on the type of NIM_MODEL_PATH value
you use.
Local Path (/abs/path/to/model)#
NIM generates the manifest from the local directory with no network access or credentials. This is the simplest air-gap workflow — ensure the model directory is pre-staged and mounted into the container.
Remote URI (ngc://, hf://, s3://, and so on)#
NIM generates a runtime manifest from the URI and saves a copy in NIM_CACHE_PATH.
On restart, NIM attempts to generate a fresh manifest. If that fails, such as when the registry
is unavailable, NIM falls back to the cached manifest. For offline use, prepare the cache with
the same model and container image and include all required model assets.
This enables the following workflow for air-gap redeployment:
First deploy (network-connected): Run the container with credentials and the remote URI. NIM downloads the model, generates the manifest, and saves a copy to
NIM_CACHE_PATH.Transfer: Ensure the NIM cache is on a PVC or persistent volume that survives pod restarts, or transfer the cache directory to the air-gap environment.
Redeploy (air-gapped): Mount the same cache volume. When manifest generation fails offline, NIM uses the cached manifest and model assets. Do not pass registry credentials.
Tip
Use a separate cache for each model and container image. Before changing either in an air-gapped deployment, prepare and transfer a matching cache on a network-connected host.
For a complete walkthrough, refer to Air-Gap Deployment.
Examples#
Use the following examples to run model-free NIM with different model sources and profile selection methods. Each example lists the commands in order.
Hugging Face Model with Profile Selection#
Use this example to inspect available profiles for a Hugging Face model, select a profile, or override tensor parallelism.
Set the model path:
export MODEL=hf://meta-llama/Llama-3.2-1B
List the available profiles:
docker run --gpus=all \
  -v "$LOCAL_NIM_CACHE:/opt/nim/.cache" \
  -e HF_TOKEN \
  -e NIM_MODEL_PATH=$MODEL \
  ${NIM_LLM_IMAGE} \
  list-model-profiles
Example output:
- Compatible with system and runnable:
  - c214460d2ad7a379660126062912d2aeecaa74a3ce14ab9966cd135de49a73f2 (vllm-tp1-pp1-0bdd169fb413e457cef3feda64108b085f73d16b6252a860e5e9ee85f533de73) [requires >=13 GB/gpu]
- With LoRA support:
  - 289b03eb8c26104f416dd0a1055004e31fd9e4b0f84fe2e59754a3ceb710976a (vllm-tp1-pp1-feat_lora-0bdd169fb413e457cef3feda64108b085f73d16b6252a860e5e9ee85f533de73) [requires >=13 GB/gpu]
Note
The example output above is from a vLLM model-free image. On an SGLang model-free image, the profile descriptions are prefixed sglang- instead (for example, sglang-tp1-pp1-...).
Start NIM by using one of the following methods:
Select a profile with
NIM_MODEL_PROFILE, using an ID or description from your image’slist-model-profilesoutput:docker run --gpus=all \ -v "$LOCAL_NIM_CACHE:/opt/nim/.cache" \ -e HF_TOKEN \ -e NIM_MODEL_PROFILE=<profile-id-or-description> \ -e NIM_MODEL_PATH=$MODEL \ -p 8000:8000 \ ${NIM_LLM_IMAGE}
Override tensor parallelism with
NIM_TENSOR_PARALLEL_SIZE=2or the canonical flag--tensor-parallel-size 2:docker run --gpus=all \ -v "$LOCAL_NIM_CACHE:/opt/nim/.cache" \ -e HF_TOKEN \ -p 8000:8000 \ ${NIM_LLM_IMAGE} \ $MODEL --tensor-parallel-size 2
Model Hosted in S3 Using Default Profile from Automatic Profile Selection#
Use this example to serve a model from S3 and let NIM select the default compatible profile automatically.
Set the model path:
export MODEL=s3://my-bucket/my-org/my-fine-tuned-model
Start NIM with the required S3 credentials:
docker run --gpus=all \
  -v "$LOCAL_NIM_CACHE:/opt/nim/.cache" \
  -e NIM_MODEL_PATH=$MODEL \
  -e AWS_ACCESS_KEY_ID=<key> \
  -e AWS_SECRET_ACCESS_KEY=<secret> \
  -e AWS_REGION=us-east-1 \
  -p 8000:8000 \
  ${NIM_LLM_IMAGE}
Local Model with TP=8 Profile Specified#
Use this example to serve a local model and select a TP=8 profile explicitly.
Set the model path:
export MODEL=/mnt/models/my-120b-model
Start NIM with the selected profile:
docker run --gpus=all \
  -v "$LOCAL_NIM_CACHE:/opt/nim/.cache" \
  -v /mnt/models:/mnt/models \
  -e NIM_MODEL_PROFILE=<tp8_profile> \
  -e NIM_MODEL_PATH=$MODEL \
  -p 8000:8000 \
  ${NIM_LLM_IMAGE}