

Transformer Models for External Aerodynamics on Irregular Meshes#
This directory contains training and inference recipes for transformer-based surrogate models for CFD applications. This is a collection of transformer models including Transolver and GeoTransolver, both of which can be run on surface or volume data.
Models Overview#
Transolver#
Transolver is a high-performance surrogate model for CFD solvers. The Transolver model adapts the Attention mechanism, encouraging the learning of meaningful representations. In each PhysicsAttention layer, input points are projected onto state vectors through learnable transformations and weights. These transformations are then used to compute self-attention among all state vectors, and the same weights are reused to project states back to each input point.
By stacking multiple PhysicsAttention layers, the Transolver model learns to map from the functional input space to the output space with high fidelity. The PhysicsNeMo implementation closely follows the original Transolver architecture (thuml/Transolver), but introduces modifications for improved numerical stability and compatibility with NVIDIA TransformerEngine.
GeoTranSolver#
GeoTransolver adapts the Transolver backbone by replacing standard attention with GALE (Geometry-Aware Latent Embeddings) attention, which unifies physics-aware self-attention on learned state slices with cross-attention to geometry and global context embeddings. Inspired by Domino’s multi-scale ball query formulations, GeoTransolver learns global geometry encodings and local latent encodings that capture neighborhoods at multiple radii, preserving fine-grained near-boundary behavior and far-field interactions. Crucially, geometry and global features are projected into physical state spaces and injected as context in every transformer block, ensuring persistent conditioning and alignment between evolving latent states and the underlying domain.
GALE directly targets core challenges in AI physics modeling. By structuring self-attention around physics-aware slices, GeoTransolver encourages interactions that reflect operator couplings (e.g., pressure–velocity or field–material). Multi-scale ball queries enforce locality where needed while maintaining access to global signals, balancing efficiency with nonlocal reasoning. Continuous geometry-context projection at depth mitigates representation drift and improves stability, while providing a natural interface for constraint-aware training and regularization. Together, these design choices enhance accuracy, robustness to geometric and regime shifts, and scalability on large, irregular discretizations.
External Aerodynamics CFD Example: Overview#
This directory contains the essential components for training and evaluating models tailored to external aerodynamics CFD problems. The training examples use the DrivaerML dataset.
As a concrete example, we are training external aerodynamics surrogate models for automobiles. These models take as input a point cloud on the surface or surrounding the surface, iteratively processing it with transformer-based attention mechanisms to produce high-fidelity predictions.
Requirements#
These transformer models can use TransformerEngine from NVIDIA, as well as tensorstore (for IO), zarr, einops and a few other python packages. Install them with pip install -r requirements.txt as well as physicsnemo 25.11 or higher.
Using Transformer Models for External Aerodynamics#
Prepare the Dataset. These models use the same Zarr outputs as other models with DrivaerML.
PhysicsNeMohas a related project to help with data processing, called PhysicsNeMo-Curator. UsingPhysicsNeMo-Curator, the data needed to train can be setup easily. Please refer to these instructions on getting started withPhysicsNeMo-Curator. For specifics of preparing the dataset for this example, see the download and preprocessing instructions fromphysicsnemo-curator. Users should apply the preprocessing steps locally to producezarroutput files.Train your model. The model and training configuration is configured with
hydra, and configurations are available for both surface and volume modes (e.g.,transolver_surface,transolver_volume,geotransolver_surface,geotransolver_volume). Find configurations insrc/conf, where you can control both network properties and training properties. See below for an overview and explanation of key parameters that may be of special interest.Use the trained model to perform inference. This example contains inference examples for the validation set, already in Zarr format. The
.vtpinference pipeline is being updated to accommodate these models.
The following sections contain further details on the training and inference recipe.
Model Training#
To train the model, first we compute normalization factors on the dataset to make the predictive quantities output in a well-defined range. The included script, compute_normalizations.py, will compute the normalization factors. Once run, it should save to an output file similar to “surface_fields_normalization.npz”. This will get loaded during training. The normalization file location can be configured via data.normalization_dir in the training configuration (defaults to current directory).
By default, the normalization sets the mean to 0.0 and std to 1.0 of all labels in the dataset, computing the mean across the train dataset. You could adapt this to a different normalization, however take care to update both the preprocessing as well as inference scripts. Min/Max is another popular strategy.
To configure your training run, use hydra. The config contains sections for the model, data, optimizer, and training settings. For details on the model parameters, refer to the API for physicsnemo.models.transolver and physicsnemo.models.geotransolver.
To fit the training into memory, you can apply on-the-fly downsampling to the data with data.resolution=N, where N is how many points per GPU to use. This dataloader will yield the full data examples in shapes of [1, K, f] where K is the resolution of the mesh, and f is the feature space (3 for points, normals, etc. 4 for surface fields). Downsampling happens in the preprocessing pipeline.
During training, the configuration uses a flat learning rate that decays every 100 epochs, and bfloat16 format by default. The scheduler and learning rate may be configured.
The Optimizer for this training is the Muon optimizer - available only in pytorch>=2.9.0. While not strictly required, we have found the muon optimizer performs substantially better on these architectures than standard AdamW and a oneCycle schedule.
Parameter-Efficient Fine-Tuning (LoRA)#
To adapt a pretrained model to a new dataset cheaply — without retraining all weights — use the LoRA fine-tuning recipe in the `src/finetune/ <src/finetune/>`__ folder (src/finetune/finetune.py and src/finetune/deploy.py, with src/conf/finetune_lora.yaml). It freezes the base model and trains only small low-rank adapters, producing a compact adapter checkpoint that can be swapped at serve time or merged into the base. See src/finetune/README.md for the full workflow.
Training Precision#
These transformer architectures have support for NVIDIA’s TransformerEngine built in. You can enable/disable the transformer engine path in the model with model.use_te=[True | False]. Available precisions for training with transformer_engine are training.precision=["float32" | "float16" | "bfloat16" | "float8" ]. In float8 precision, the TransformerEngine Hybrid recipe is used for casting weights and inputs in the forward and backwards passes. For more details on float8 precision, see the fp8 guide from TransformerEngine. When using fp8, the training script will automatically pad and unpad the input and output, respectively, to use the fp8 hardware correctly.
Float8 precisions are only available on GPUs with fp8 tensorcore support, such as Hopper, Blackwell, Ada Lovelace, and others.
Other Configuration Settings#
Several other important configuration settings are available:
checkpoint_dirsets the directory for saving model checkpoints (defaults tooutput_dirif not specified), allowing separation of checkpoints from other outputs.compilewill usetorch.compilefor optimized performance. It is not compatible withtransformer_engine(model.use_te=True). If TransformerEngine is not used, and half precision is,torch.compileis recommended for improved performance.training.num_epochscontrols the total number of epochs used during training.training.save_intervalwill dictate how often the model weights and training tools are checkpointed.
Note Like other parameters of the model, changing the value of
model.use_tewill make checkpoints incompatible.
The training script supports data-parallel training via PyTorch DDP. A possible future change might enable domain parallelism usingShardTensor (with DDP or FSDP2 fully_shard on the data-parallel axis).
The script can be launched on a single GPU with, for example,
python train.py --config-name transolver_surface
or, for multi-GPU training, use torchrun or other distributed job launch tools.
Example output for one epoch of the script, in an 8 GPU run, looks like:
[2025-07-17 14:27:36,040][training][INFO] - Epoch 47 [0/54] Loss: 0.117565 Duration: 0.78s
[2025-07-17 14:27:36,548][training][INFO] - Epoch 47 [1/54] Loss: 0.109625 Duration: 0.51s
[2025-07-17 14:27:37,048][training][INFO] - Epoch 47 [2/54] Loss: 0.122574 Duration: 0.50s
[2025-07-17 14:27:37,556][training][INFO] - Epoch 47 [3/54] Loss: 0.125667 Duration: 0.51s
[2025-07-17 14:27:38,063][training][INFO] - Epoch 47 [4/54] Loss: 0.101863 Duration: 0.51s
[2025-07-17 14:27:38,547][training][INFO] - Epoch 47 [5/54] Loss: 0.113324 Duration: 0.48s
[2025-07-17 14:27:39,054][training][INFO] - Epoch 47 [6/54] Loss: 0.115478 Duration: 0.51s
...[remove for brevity]...
[2025-07-17 14:28:00,662][training][INFO] - Epoch 47 [49/54] Loss: 0.107935 Duration: 0.49s
[2025-07-17 14:28:01,178][training][INFO] - Epoch 47 [50/54] Loss: 0.100087 Duration: 0.52s
[2025-07-17 14:28:01,723][training][INFO] - Epoch 47 [51/54] Loss: 0.097733 Duration: 0.55s
[2025-07-17 14:28:02,194][training][INFO] - Epoch 47 [52/54] Loss: 0.116489 Duration: 0.47s
[2025-07-17 14:28:02,605][training][INFO] - Epoch 47 [53/54] Loss: 0.104865 Duration: 0.41s

Epoch 47 Average Metrics:
+-------------+---------------------+
|   Metric    |    Average Value    |
+-------------+---------------------+
| l2_pressure | 0.20262257754802704 |
| l2_shear_x  | 0.2623567283153534  |
| l2_shear_y  | 0.35603201389312744 |
| l2_shear_z  | 0.38965049386024475 |
+-------------+---------------------+

[2025-07-17 14:28:02,834][training][INFO] - Val [0/6] Loss: 0.114801 Duration: 0.22s
[2025-07-17 14:28:03,074][training][INFO] - Val [1/6] Loss: 0.111632 Duration: 0.24s
[2025-07-17 14:28:03,309][training][INFO] - Val [2/6] Loss: 0.105342 Duration: 0.23s
[2025-07-17 14:28:03,537][training][INFO] - Val [3/6] Loss: 0.111033 Duration: 0.23s
[2025-07-17 14:28:03,735][training][INFO] - Val [4/6] Loss: 0.099963 Duration: 0.20s
[2025-07-17 14:28:03,903][training][INFO] - Val [5/6] Loss: 0.092340 Duration: 0.17s

Epoch 47 Validation Average Metrics:
+-------------+---------------------+
|   Metric    |    Average Value    |
+-------------+---------------------+
| l2_pressure | 0.19346082210540771 |
| l2_shear_x  | 0.26041051745414734 |
| l2_shear_y  | 0.3589216470718384  |
| l2_shear_z  |  0.370105117559433  |
+-------------+---------------------+
Dataset Inference#
The validation dataset in Zarr format can be loaded, processed, and the L2 metrics summarized in inference_on_zarr.py. For surface data, this script will also compute the drag and lift coefficients and the R^2 correlation of the predictions.
To run inference on surface data, it’s necessary to add a line to your launch command:
python src/inference_on_zarr.py --config-name transolver_surface run_id=/path/to/model/
The data.return_mesh_features flag can also be set in the config file. It is disabled for training but necessary for inference. The model path should be the folder containing your saved checkpoints.
To ensure correct calculation of drag and lift, and accurate overall metrics, the inference script will chunk a full-resolution training example into batches, and stitch the outputs together at the end. Output will appear as a table with all metrics for that mode, for example:
| Batch | Loss | L2 Pressure | L2 Shear X | L2 Shear Y | L2 Shear Z | Predicted Drag Coefficient | Pred Lift Coefficient | True Drag Coefficient | True Lift Coefficient | Elapsed (s) |
|---------|--------|---------------|--------------|--------------|--------------|------------------------------|-------------------------|-------------------------|-------------------------|---------------|
| 0 | 0.0188 | 0.0491 | 0.0799 | 0.1023 | 0.1174 | 488.075 | 140.365 | 475.534 | 135.944 | 8.1281 |
| 1 | 0.0144 | 0.045 | 0.0659 | 0.0955 | 0.107 | 404.472 | 21.8897 | 406.484 | 35.6202 | 0.7348 |
| 2 | 0.0239 | 0.0505 | 0.0835 | 0.1101 | 0.1592 | 383.219 | 41.973 | 373.999 | 43.7198 | 1.6722 |
| 3 | 0.0255 | 0.0526 | 0.088 | 0.1151 | 0.1305 | 576.671 | 230.185 | 579.655 | 210.01 | 1.4369 |
| 4 | 0.0214 | 0.0498 | 0.0849 | 0.109 | 0.1229 | 451.478 | -45.3076 | 447.109 | -36.7298 | 1.8973 |
| 5 | 0.0147 | 0.0402 | 0.0671 | 0.0923 | 0.0992 | 419.76 | -87.7945 | 424.63 | -83.8417 | 1.7255 |
| 6 | 0.0171 | 0.0463 | 0.0742 | 0.1016 | 0.126 | 350.877 | -32.1908 | 338.721 | -25.5008 | 1.3738 |
| 7 | 0.0248 | 0.0596 | 0.0989 | 0.123 | 0.1299 | 420.122 | -42.3073 | 420.772 | -16.9301 | 1.9126 |
| 8 | 0.0178 | 0.0453 | 0.0736 | 0.1021 | 0.118 | 380.704 | -90.6937 | 374.134 | -87.2395 | 1.8081 |
| 9 | 0.0297 | 0.0629 | 0.1004 | 0.1245 | 0.1418 | 400.315 | -149.927 | 396.178 | -147.33 | 1.6693 |
| 10 | 0.0303 | 0.0674 | 0.0978 | 0.1233 | 0.1455 | 602.585 | 249.985 | 588.987 | 237.999 | 1.6581 |
| 11 | 0.0188 | 0.0514 | 0.0772 | 0.1006 | 0.1114 | 593.366 | 155.859 | 590.833 | 167.067 | 1.6914 |
| 12 | 0.0147 | 0.0436 | 0.0681 | 0.0929 | 0.1009 | 457.252 | 77.7093 | 449.866 | 77.2836 | 1.734 |
| 13 | 0.0226 | 0.0529 | 0.0902 | 0.1092 | 0.1319 | 374.561 | -88.923 | 372.675 | -101.469 | 1.3918 |
| 14 | 0.0186 | 0.0591 | 0.0758 | 0.1056 | 0.1199 | 516.445 | 275.197 | 512.238 | 274.633 | 1.7587 |
| 15 | 0.0145 | 0.0443 | 0.0691 | 0.0974 | 0.1083 | 397.664 | 44.4129 | 395.376 | 31.417 | 1.6531 |
| 16 | 0.019 | 0.0502 | 0.0828 | 0.1028 | 0.1145 | 502.079 | 75.96 | 501.056 | 77.4457 | 1.6815 |
| 17 | 0.0155 | 0.0459 | 0.0721 | 0.1003 | 0.1064 | 472.191 | 138.568 | 460.808 | 139.42 | 1.7288 |
| 18 | 0.0186 | 0.0549 | 0.0783 | 0.1074 | 0.1162 | 482.58 | 37.7236 | 482.344 | 37.2805 | 1.7915 |
| 19 | 0.0148 | 0.0425 | 0.078 | 0.1004 | 0.113 | 448.504 | 157.548 | 446.845 | 173.68 | 1.8042 |
| 20 | 0.0144 | 0.0424 | 0.072 | 0.0946 | 0.0993 | 500.781 | 81.4317 | 490.024 | 85.8991 | 1.7812 |
| 21 | 0.0142 | 0.0462 | 0.0669 | 0.0983 | 0.0982 | 483.057 | 134.258 | 473.958 | 121.551 | 1.8255 |
| 22 | 0.0149 | 0.0432 | 0.0671 | 0.0964 | 0.1004 | 510.518 | 162.651 | 504.159 | 164.953 | 1.8021 |
| 23 | 0.0182 | 0.05 | 0.074 | 0.101 | 0.116 | 388.014 | -223.932 | 393.797 | -229.571 | 2.6297 |
| 24 | 0.0188 | 0.0486 | 0.0774 | 0.1049 | 0.1064 | 477.557 | -11.9395 | 494.446 | 7.5967 | 0.8668 |
| 25 | 0.0229 | 0.0608 | 0.0867 | 0.1211 | 0.1507 | 348.804 | 5.3412 | 341.955 | 30.8778 | 1.5065 |
| 26 | 0.019 | 0.0544 | 0.0814 | 0.1063 | 0.119 | 467.791 | 170.149 | 466.67 | 186.732 | 1.8434 |
| 27 | 0.0154 | 0.047 | 0.0734 | 0.1014 | 0.1102 | 426.202 | -78.8968 | 417.572 | -78.867 | 1.8177 |
| 28 | 0.0159 | 0.0455 | 0.0724 | 0.0983 | 0.1051 | 523.8 | 165.693 | 512.567 | 150.064 | 1.7851 |
| 29 | 0.0243 | 0.0498 | 0.0873 | 0.112 | 0.1309 | 481.491 | 55.202 | 483.593 | 59.5569 | 1.7285 |
| 30 | 0.021 | 0.054 | 0.0808 | 0.1097 | 0.1232 | 508.089 | 200.01 | 496.295 | 194.816 | 1.7602 |
| 31 | 0.0186 | 0.0479 | 0.0771 | 0.1047 | 0.1351 | 422.298 | 80.0045 | 421.175 | 97.6633 | 1.532 |
| 32 | 0.0205 | 0.0589 | 0.0793 | 0.1129 | 0.1308 | 395.582 | -12.36 | 400.106 | 6.3091 | 1.5378 |
| 33 | 0.0129 | 0.0396 | 0.0679 | 0.0923 | 0.0953 | 431.082 | 7.8286 | 428.801 | 8.6182 | 1.8789 |
| 34 | 0.0144 | 0.0412 | 0.0662 | 0.0893 | 0.0979 | 530.599 | 179.193 | 532.033 | 158.92 | 1.8429 |
| 35 | 0.0139 | 0.0424 | 0.0716 | 0.0945 | 0.1006 | 430.982 | 7.3476 | 428.805 | -4.3425 | 1.711 |
| 36 | 0.0167 | 0.043 | 0.0702 | 0.0975 | 0.1217 | 381.859 | -45.0215 | 376.432 | -65.0582 | 1.4227 |
| 37 | 0.021 | 0.0516 | 0.0772 | 0.1106 | 0.1302 | 348.402 | -84.0741 | 347.672 | -69.1513 | 1.5184 |
| 38 | 0.029 | 0.0585 | 0.0895 | 0.1188 | 0.1347 | 596.764 | 287.068 | 586.433 | 236.509 | 1.6109 |
| 39 | 0.0176 | 0.0472 | 0.0758 | 0.1006 | 0.1115 | 470.259 | 25.2451 | 468.965 | 38.1292 | 1.7815 |
| 40 | 0.0309 | 0.0583 | 0.0827 | 0.1163 | 0.1649 | 579.514 | 186.451 | 587.644 | 177.782 | 1.6365 |
| 41 | 0.0188 | 0.0516 | 0.0776 | 0.1084 | 0.1369 | 349.04 | -106.107 | 341.44 | -94.3054 | 1.4013 |
| 42 | 0.014 | 0.0424 | 0.0673 | 0.0964 | 0.0977 | 477.916 | 120.4 | 474.075 | 116.718 | 1.8973 |
| 43 | 0.0171 | 0.0476 | 0.071 | 0.1054 | 0.1116 | 423.233 | 50.4327 | 420.448 | 69.2674 | 1.8893 |
| 44 | 0.0247 | 0.0613 | 0.0799 | 0.1171 | 0.141 | 426.292 | -2.5913 | 422.69 | 20.4068 | 1.4871 |
| 45 | 0.0161 | 0.0431 | 0.0736 | 0.0959 | 0.1007 | 538.835 | 71.1159 | 544.14 | 89.5933 | 1.7929 |
| 46 | 0.017 | 0.0442 | 0.0722 | 0.0986 | 0.1175 | 361.974 | -136.836 | 359.692 | -151.266 | 1.4659 |
| 47 | 0.0186 | 0.046 | 0.0778 | 0.1076 | 0.1114 | 502.144 | 80.8261 | 499.45 | 102.07 | 1.9431 |
[2025-12-01 08:19:42,350][training][INFO] - R2 score for lift: 0.9824
[2025-12-01 08:19:42,350][training][INFO] - R2 score for drag: 0.9904
[2025-12-01 08:19:42,351][training][INFO] - Summary:
| Batch | Loss | L2 Pressure | L2 Shear X | L2 Shear Y | L2 Shear Z | Predicted Drag Coefficient | Pred Lift Coefficient | True Drag Coefficient | True Lift Coefficient | Elapsed (s) |
|---------|--------|---------------|--------------|--------------|--------------|------------------------------|-------------------------|-------------------------|-------------------------|---------------|
| Mean | 0.0191 | 0.0496 | 0.0775 | 0.1047 | 0.1191 | 456.371 | 51.6484 | 453.193 | 53.624 | 1.8114 |
Transolver++#
Transolver++ is supported with the plus flag to the model. In our experiments, we did not see gains, but you are welcome to try it and share your results with us on GitHub!
Uncertainty Quantification#
GeoTransolver supports three complementary UQ methods:
Method |
Granularity |
Cost at inference |
|---|---|---|
Variational GP Head |
one scalar (drag coefficient) per geometry |
single pass |
Field Variational GP Head |
per-point, per-channel field |
single pass |
Concrete Dropout / MC-Dropout |
per-point, per-channel field |
N stochastic passes |
They can be used independently or together. The two GP heads are siblings built on the same variational-GP machinery — the scalar head pools a geometry to one embedding, while the field head keeps the point dimension.
Dependencies#
Both GP heads need gpytorch. Install it using:
pip install nvidia-physicsnemo[uq-extras]
# or simply:
pip install gpytorch
Variational GP Head#
Overview#
This recipe extends the GeoTransolver backbone with a variational Gaussian Process (GP) head that provides calibrated uncertainty estimates on a scalar quantity of interest — in this case, the aerodynamic drag coefficient (Cd). The GP head enables two complementary uncertainty signals:
Query-by-Committee disagreement — The GeoTransolver predicts Cd by integrating its per-point field predictions; the GP head predicts Cd directly from the learned geometry embeddings. When these two independent predictions disagree, the input is likely out-of-distribution (OOD).
GP predictive variance — The GP’s posterior variance provides a data-driven measure of how far a new input lies from the training distribution in embedding space. Unlike an ensemble of GeoTransolvers, the GP learns from a finite set of inducing points and its uncertainty naturally grows as inputs move away from the in-distribution region, providing a principled distance-aware uncertainty signal.
Together, these signals form a joint UQ estimate suitable for flagging OOD samples, which can be used to guide active learning sample selection and build trust in surrogate-model predictions.
Active learning — An active-learning loop that uses the joint UQ signal to automatically select the most informative geometries for labelling is coming soon.
Architecture#
                                              ┌───────────────────────────┐
                                              │  Variational GP Head      │
Input geometry ──► GeoTransolver ──┬──► x ──► │  (VariationalGPHead)      │──► Cd_GP, σ²
                                   │          └───────────────────────────┘
                                   │
                   embedding_states│    ┌──────────────────────┐
                   (B, H, S, D_c)  ├──► │  AttentionPooling    │──► embedding (B, D)
                                   │    └──────────────────────┘         │
                                   │                                     ▼
                                   │                            ┌─────────────────┐
                                   └──► field integration ───►  │ Cd_GeoTransolver│
                                                                └─────────────────┘
The GeoTransolver’s embedding_states — the geometry/global context of shape (B, H, S, D_c) computed before the GALE cross-attention blocks — capture what the geometry looks like before any flow-field prediction. Here D_c is the per-head context dimension from the GeoTransolver, while D (the final GP input dimension) is the reduced embedding size after attention pooling. The pooling step reduces the variable-length (B, H, S, D_c) states to a fixed-size (B, D) embedding that is then fed to the GP head.
Key library modules used:
Module |
Location |
Purpose |
|---|---|---|
|
|
Learnable attention-weighted pooling over variable-length point sequences |
|
|
Variational GP with Matérn-5/2 ARD kernel, float64 internals, optional DKL MLP |
Training#
Training is a two-phase process using a single script (train_gp_combined.py):
Warmup (epochs 0–49): Only the GeoTransolver backbone is trained with per-point field MSE loss. The GP head is frozen during this phase because it needs meaningful geometric embeddings — training it on random, untrained backbone representations would produce a poorly conditioned variational posterior.
Joint training (epochs 50+): The GP head, embedding reduction, and consistency loss activate via a linear ramp. Three losses are combined:
Field MSE — standard per-point loss on pressure + wall shear stress
GP ELBO — variational evidence lower bound on the drag prediction
Consistency — MSE between GP-predicted drag and field-integrated drag from the same forward pass (zero extra memory)
Launch training:
torchrun --nproc_per_node=8 \
    src/train_gp_combined.py \
    --config-name=geotransolver_surface_gp \
    ++run_id=geotransolver/surface/my_gp_experiment \
    ++data.train.data_path=/path/to/surface_files_zarr/class_F/train \
    ++data.val.data_path=/path/to/surface_files_zarr/class_F/val \
    ++data.resolution=51200 \
    ++data.geometry_sampling=51200 \
    ++data.return_mesh_features=true
The default config (geotransolver_surface_gp.yaml) includes tuned GP hyperparameter priors and embedding normalization settings. The data-path overrides above point to the DrivAerStar surface zarr files; resolution and geometry_sampling are lowered from the defaults (200k / 300k) to 51200 to fit in GPU memory.
Evaluation and OOD Detection#
After training, run the evaluation script to generate diagnostic plots:
python src/plot_gp_predictions.py \
    --config-name=geotransolver_surface_gp \
    ++run_id=geotransolver/surface/my_gp_experiment \
    ++data.train.data_path=/path/to/surface_files_zarr/class_F/train \
    ++data.val.data_path=/path/to/surface_files_zarr/class_F/val \
    ++data.resolution=51200 \
    ++data.geometry_sampling=51200 \
    ++data.return_mesh_features=true \
    ++data.test_notchback.data_path=/path/to/surface_files_zarr/class_N/val \
    ++data.test_estateback.data_path=/path/to/surface_files_zarr/class_E/val
This produces: - Scatter plots — true vs predicted Cd for both the GP and GeoTransolver - Disagreement histograms — distribution of |Cd_GP − Cd_GeoTransolver| - GP std dev histograms — distribution of GP predictive standard deviation - Joint UQ scatter — Cd predictions with combined uncertainty bands - KDE overlays — kernel density estimates comparing ID vs OOD distributions
OOD test sets are auto-discovered from the config — any key matching test_* under data: is loaded automatically. Add as many as you like via command-line overrides (++data.test_myclass.data_path=...). The evaluation results are saved to prediction_results.npz for offline re-plotting without re-running inference.
Example: KDE of ID vs OOD signals#
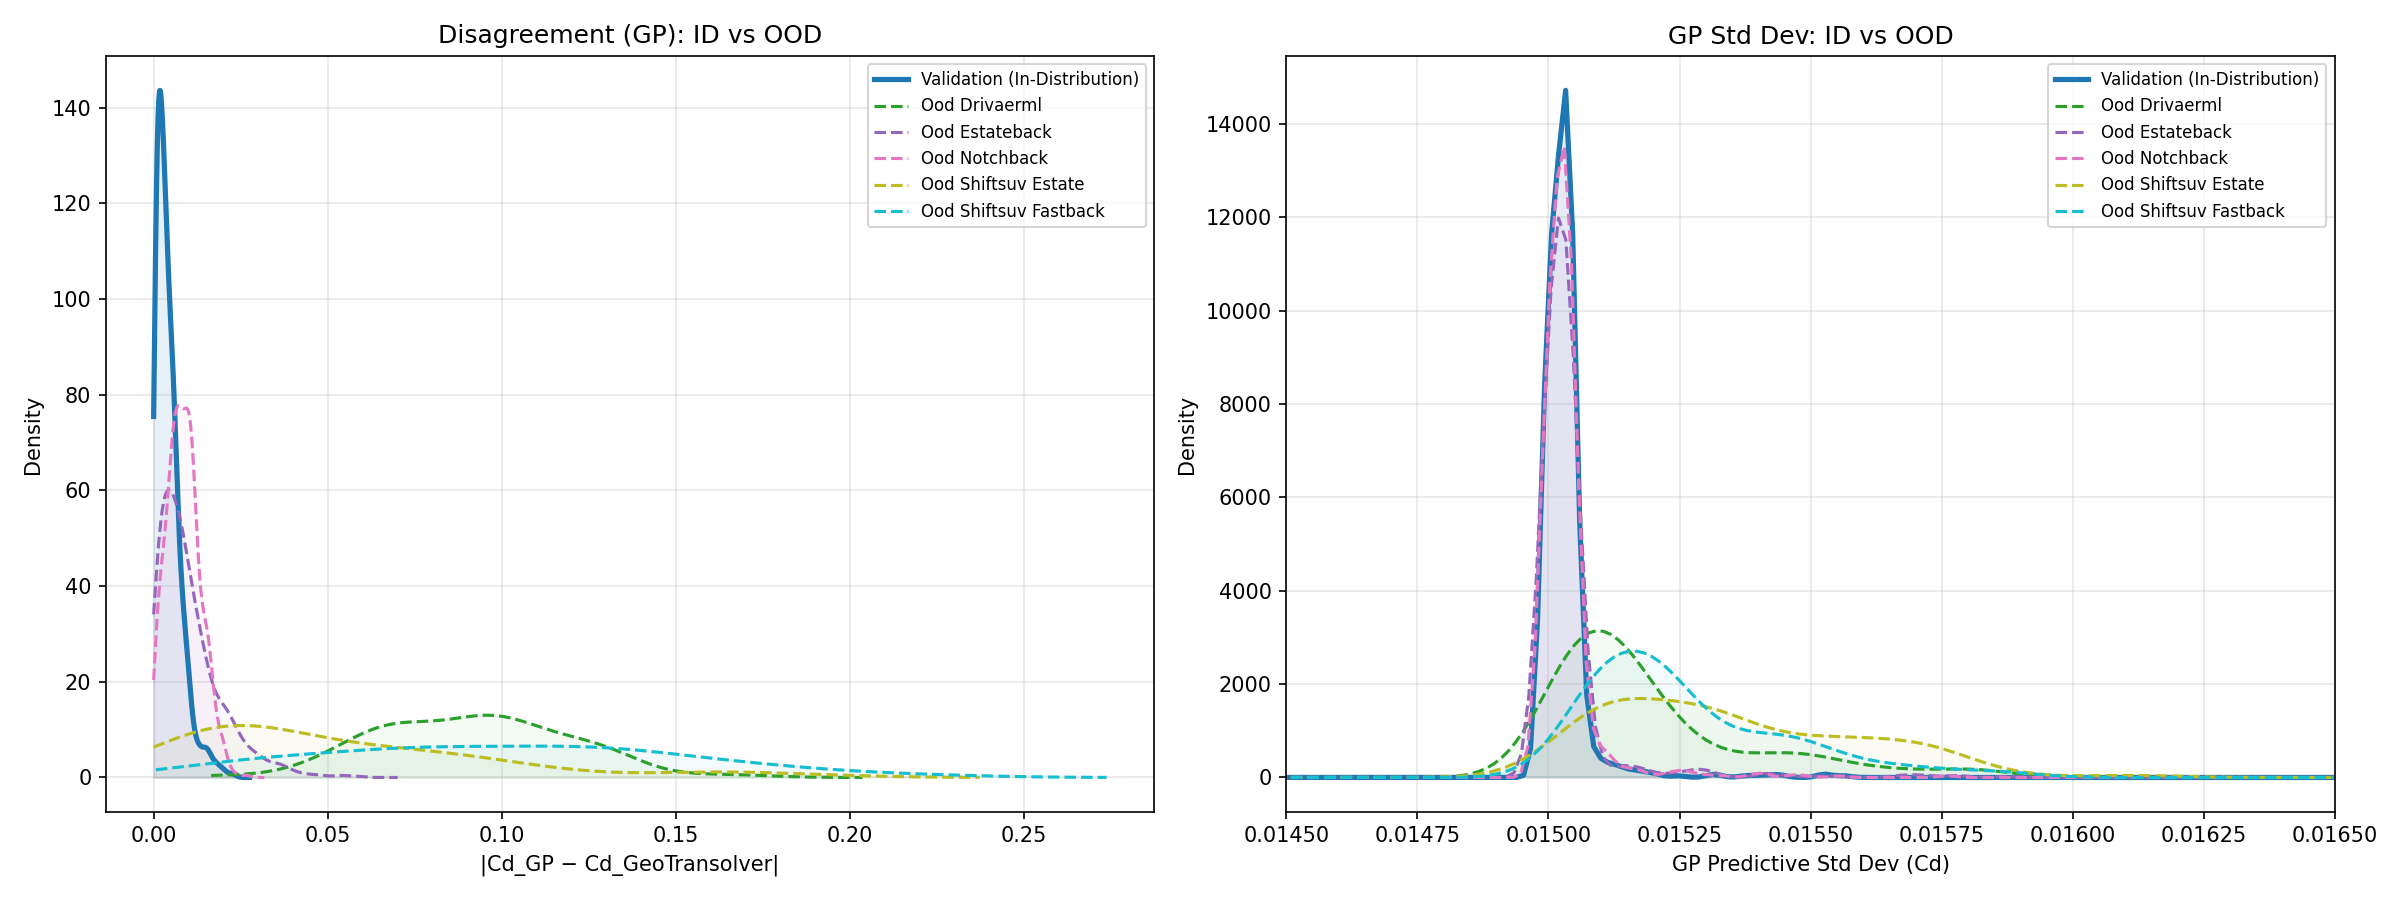
KDE of disagreement and GP std dev for in-distribution vs OOD samples#
The model was trained exclusively on DrivAerStar Fastback geometries (class F). The figure above shows kernel density estimates of the two UQ signals evaluated on the in-distribution Fastback validation set and five OOD vehicle classes from different sources and body styles.
Left — Disagreement: The distribution of |Cd_GP − Cd_GeoTransolver| is tightly concentrated near zero for in-distribution Fastback samples (solid blue), indicating strong agreement between the two independent drag predictions. OOD classes exhibit heavier tails and wider spread, meaning the GP and GeoTransolver diverge more when encountering unfamiliar geometries. Notably, the disagreement signal correlates with geometric similarity to the training distribution: Notchback — the DrivAerStar body style most resembling Fastback — shows a relatively modest shift, while Estateback (a more distinct rear-end shape) and the DrivaerML / ShiftSUV classes (entirely different vehicle datasets) produce substantially larger disagreement. This query-by-committee disagreement provides a strong, interpretable OOD detection signal.
Right — GP Predictive Std Dev: The GP’s posterior standard deviation shows a subtle but consistent shift: in-distribution samples cluster in a narrow peak, while OOD samples spread to higher values. The signal is weaker than disagreement alone, but the two are complementary — the joint UQ metric, for example max(|disagreement|, 2 * GP_std) combines both for more robust OOD flagging.
Key Design Choices#
Choice |
Rationale |
|---|---|
Float64 GP internals |
Short lengthscales on L2-normalized embeddings make K_uu ill-conditioned in float32. Float64 eliminates Cholesky failures at the source. |
L2-normalized embeddings |
Constrains pairwise distances to [0, 2], making GP lengthscale priors more interpretable and stable. |
Spectral norm on embedding layers |
Preserves distances in the embedding space (SNGP-style), preventing the encoder from collapsing different inputs to the same point. |
Matérn-5/2 ARD kernel |
Smooth, twice-differentiable, with per-dimension lengthscales that learn which embedding dimensions matter. |
Gamma priors on lengthscale & outputscale |
Prevents the GP from collapsing to trivial solutions (infinite lengthscale → constant predictions, zero outputscale → zero variance). |
``embedding_states`` as GP input |
These capture geometry context before the flow-field GALE blocks, giving the GP access to what the shape looks like rather than the (already processed) flow prediction. |
Subsampled consistency loss |
Reuses the training forward pass — no extra full-mesh evaluation needed, making the consistency signal nearly free. |
Customization Guide#
The config file src/conf/geotransolver_surface_gp.yaml exposes all tunable parameters. Common adjustments:
Switching to an MLP baseline head:
++head_type=mlp ++lambda_gp=1.0
The DragMLP head provides the same forward_and_loss / predict interface. Downstream scripts work unchanged.
Adjusting GP capacity:
embed_dim: 64         # Larger embedding → more expressive GP (default: 32)
n_inducing: 256       # More inducing points → better coverage (default: 128)
gp_mlp_hidden: [64, 32]  # Add DKL feature extractor before GP kernel
Relaxing / tightening GP priors:
gp_lengthscale_range: [0.01, 2.0]   # Wider allowed range
gp_lengthscale_prior: [3.0, 6.0]    # Gamma(3, 6) → mean 0.5
gp_outputscale_prior: [2.0, 0.5]    # Gamma(2, 0.5) → mean 4.0
Disabling consistency loss:
lambda_consistency: 0.0
Enabling gradients through the GeoTransolver in the consistency path:
consistency_detach_transolver: false # default; set true to save memory
References#
DrivaerML dataset: DrivaerML: A Large-Scale Parametric Car Dataset — Elahi et al., NeurIPS 2024
DrivAerStar dataset: DrivAerStar: A Body-Fitted Overset Mesh Dataset for Automotive External Aerodynamics — Qiu et al., 2025
GeoTransolver: Built on the Transolver architecture (Wu et al., 2024) with GALE attention
Variational GPs: Scalable Variational Gaussian Process Classification — Hensman et al., 2015
Deep Kernel Learning: Deep Kernel Learning — Wilson et al., 2016
SNGP / DUE: Simple and Principled Uncertainty Estimation with Deterministic Deep Learning — van Amersfoort et al., 2020
Field Variational GP Head#
Overview#
Where the scalar GP head above predicts one number per geometry, the field GP head (FieldVariationalGPHead) replaces the GeoTransolver readout and predicts the surface field itself: one independent Gaussian posterior per point, per channel (pressure + 3 wall-shear-stress components). The posterior mean is the field prediction and the posterior variance is the per-point uncertainty, so a single forward pass yields both — no ensembling and no MC-Dropout sampling.
The uncertainty is distance-aware: it grows as a point’s features move away from the learned inducing points, which is what makes it usable for out-of-distribution detection and active learning rather than just error bars.
Architecture#
                                     ┌──────────────────────────────┐
Input geometry ──► GeoTransolver ──► │  FieldVariationalGPHead      │
                   (per-point        │                              │
                    features,        │  DKL MLP ──► feature norm    │──► mean      (B, N, 4)
                    pre-readout)     │       └──► Matérn-5/2 ARD    │──► variance  (B, N, 4)
                    (B, N, D)        │            multitask VGP     │──► epistemic (B, N, 4)
                                     │       └──► noise MLP         │
                                     └──────────────────────────────┘
Module |
Location |
Purpose |
|---|---|---|
|
|
Per-point independent multitask variational GP with Matérn-5/2 ARD kernel, float64 internals, optional DKL MLP and input-dependent observation noise |
The variance decomposition#
predict() returns the total predictive variance and its epistemic part separately, so the two can be used for different jobs:
total_variance(x)  =  epistemic_variance(x)  +  sigma^2(x)
                      ^^^^^^^^^^^^^^^^^^^^      ^^^^^^^^^
                      GP posterior variance     input-dependent
                      (distance-aware; grows    observation noise
                      away from inducing pts)   (the noise MLP)
Use epistemic_variance for “where is the model uncertain?” maps, out-of-distribution detection and active-learning acquisition; use the total variance for calibrated prediction intervals and for calibration metrics (z-RMS, coverage, NLPD).
Naming the second term. In the loss it is exactly the variance of the Gaussian likelihood, so the methods-level name is input-dependent observation noise — the standard heteroscedastic-GP quantity (Goldberg et al., 1998; Lázaro-Gredilla & Titsias, 2011). Do not read it as measurement noise here. DrivAerStar targets are deterministic steady-RANS solutions, so a geometry maps to one field and there is no irreducible observational scatter to learn. What sigma^2(x) actually absorbs is the part of the residual the GP mean cannot represent, which makes it a learned model-discrepancy variance in the Kennedy & O’Hagan (2001) sense — a map of where the surrogate is structurally wrong. That reading, not “inherent flow variability”, is what the per-point noise field supports.
We therefore avoid the word aleatoric for it, and reuse only the mechanism from Kendall & Gal (2017): sigma(x) is amortized by a small MLP on the same DKL features the kernel sees, trained through the noise-attenuated Gaussian log-likelihood.
It is a point estimate, and that has a cost. The classical variational treatment places a second GP on the log-noise, so the objective carries its own KL(q(g)||p(g)) term that actively resists the noise function running to extremes. Amortizing with a deterministic network drops both the prior and that KL, so nothing shrinks sigma(x). gp_head.noise_std_range and head_grad_clip_norm are the substitute guard, and they are load-bearing rather than cosmetic: without an adequate floor on sigma the noise collapsed mid-training.
Why a network rather than a second GP. Cost at this scale. The alternative — a second variational process on the log-noise, as in Liu et al. (2018b) — needs its own inducing set, Cholesky factor and KL term, roughly doubling the head’s variational state and adding a second O(M^3) factorization per step, where the noise MLP adds two [64, 64] layers.
Training#
The settled recipe is the config’s defaults, so no hyperparameter overrides are needed — only the data paths and a run id:
export PYTORCH_CUDA_ALLOC_CONF=expandable_segments:True
torchrun --nproc-per-node=8 src/train_field_gp.py \
    data.train.data_path=/data/datasets/drivaerstar/surface_files_zarr/class_F/train \
    data.val.data_path=/data/datasets/drivaerstar/surface_files_zarr/class_F/val \
    run_id=geotransolver/surface/field_gp
The loss is
w_nll * neg_elbo + lambda_mean_mse * mse + dist_penalty_weight * dist_pen
with both beta (the KL weight) and w_nll (the weight on the whole negative ELBO) ramped from 0 over the first 30 epochs. The ordering matters: the mean-MSE anchor leads the early epochs so the backbone and GP mean become accurate before the likelihood term is free to shrink the variance.
The auxiliary terms#
The terms around neg_elbo — the mean anchor, the two ramps, the latent distance penalty and the gradient clipping — belong to the training script rather than to the head, so they are configured here:
Config key |
Default |
What it controls |
|---|---|---|
|
|
Weight of a direct MSE on the GP posterior mean, which keeps the mean accurate while the ELBO is free to trade accuracy for variance. |
|
|
Epoch window over which |
|
|
Epoch window over which the KL weight ramps 0 → 1, so the data-fit term shapes the posterior before the prior pulls on it. |
|
|
Constant multiplier on the KL weight once the ramp completes. Below |
|
|
Max global grad-norm over the head’s parameters ( |
|
|
One-sided hinge pushing point pairs with distant targets apart in kernel space, so the kernel can assign them different variance. Both distances are normalized by their batch mean, so only relative geometry is shaped. |
These are load-bearing rather than cosmetic. Without the mean anchor and the ramps the ELBO can buy likelihood by inflating the variance before the mean field is accurate, and the run settles into a collapsed variance.
Two further knobs are cost rather than stability decisions: gp_points_per_step: 12288 bounds the O(points) GP solve per step (null uses every point the dataloader provides), and gp_head.n_inducing: 1024 sets how finely the posterior can resolve the feature space, at O(M³) per step. Those inducing points are seeded from real backbone features once, before the first epoch, rather than left at their random-normal defaults — see the learning-rate discussion below and the porting notes.
The head itself is a hydra _target_ block under gp_head, so the config is the single source of truth for its structure and every script (train, inference, plotting) instantiates it identically. Only input_dim and n_train are supplied in code, since they are runtime quantities. Three of the defaults are load-bearing and worth understanding before changing them:
``gp_head.feature_norm: l2_radial`` — fixes the GP-input feature scale so the kernel lengthscale (not the DKL map) does the smoothing, while appending the standardized feature magnitude as an extra ARD dimension. Normalizing onto the unit sphere without that magnitude erases the radial OOD cue and drives the OOD/in-distribution std ratio to ~1.0x.
``gp_head.noise_mlp_hidden: [64, 64]`` — makes the observation noise input-dependent. With one constant noise per channel the total predictive std ranks points identically to the epistemic std, so per-point error ranking gets no benefit from the (dominant) noise share of the variance.
``gp_head.noise_std_range: [0.01, 10.0]`` — the heteroscedastic ELBO weights each point by
1/σ²(x), and the0.01floor caps that weight at1e4on unit-scale normalized fields, so no single point can dominate the gradient. It sits just below the σ band the trained noise head occupies, which bounds the weight without reshaping the noise field being learned. The floor also applies at inference, sincepredict()evaluatesσ(x)through the same clamp.
Normalization — DrivAerStar surface fields are stored in raw physical units (Pa), so this config points
data.normalization_diratsrc/normalization/drivaerstar/. The stats insrc/are nondimensional (pressure-coefficient form) and belong to the DrivAer AWS runs; using them here would mis-scale every field.
Choosing the head learning rates#
The head gets its own AdamW, combined with the backbone’s Muon (2-D weights) + AdamW (everything else) in a single CombinedOptimizer. Muon is configured with adjust_lr_fn="match_rms_adamw" at the same rate, so training.optimizer.lr (1e-3 by default) is the one reference number the head’s rates are set against:
Head parameter group |
Rate |
vs. backbone |
|---|---|---|
|
|
10x |
|
|
10x |
|
|
10x |
|
|
10x |
|
|
1x |
|
|
1x |
The split is by parameter kind, not by module. Network weights train at the backbone’s rate; GP-native parameters — a variational distribution, kernel hyperparameters, a noise scale — train 10x faster. The heteroscedastic noise model straddles that line deliberately: log_base_noise is a per-task scale in the same family as the likelihood noise, while noise_head produces the input-dependent modulation around it and is ordinary MLP weights.
The 10x suits what those parameters are. They are few, low-dimensional and parameterize a distribution directly, so they tolerate large steps — and they are chasing a moving target, since the features beneath them shift with every backbone step. Inducing points are seeded from real backbone features once, before the first epoch, and the variational parameters are what keep the posterior aligned with those features as they drift. Holding the DKL and noise MLPs at the backbone rate keeps the composed map (backbone → DKL → kernel) advancing at one speed, so the kernel’s input distribution stays as stable as the features feeding it. train_gp_combined.py applies the same 10x / 1x convention to the scalar head, which keeps the two directly comparable.
To retune, move the two regimes together and keep the ratio: set the MLP groups to the new training.optimizer.lr and the GP-native groups to 10x it. These rates live in the head_param_groups list in src/train_field_gp.py, so it is a code edit rather than a config override. StepLR wraps the combined optimizer and scales every group by the same factor, so the ratio holds for the whole run; with the default step_size: 100 and num_epochs: 100 no decay lands inside the run, making it effectively constant-rate. Head weight decay is 1e-4, matching the backbone.
Inference#
python src/inference_field_gp.py \
    run_id=geotransolver/surface/field_gp \
    +checkpoint_epoch=100
Example: uncertainty across DrivAerStar body styles#
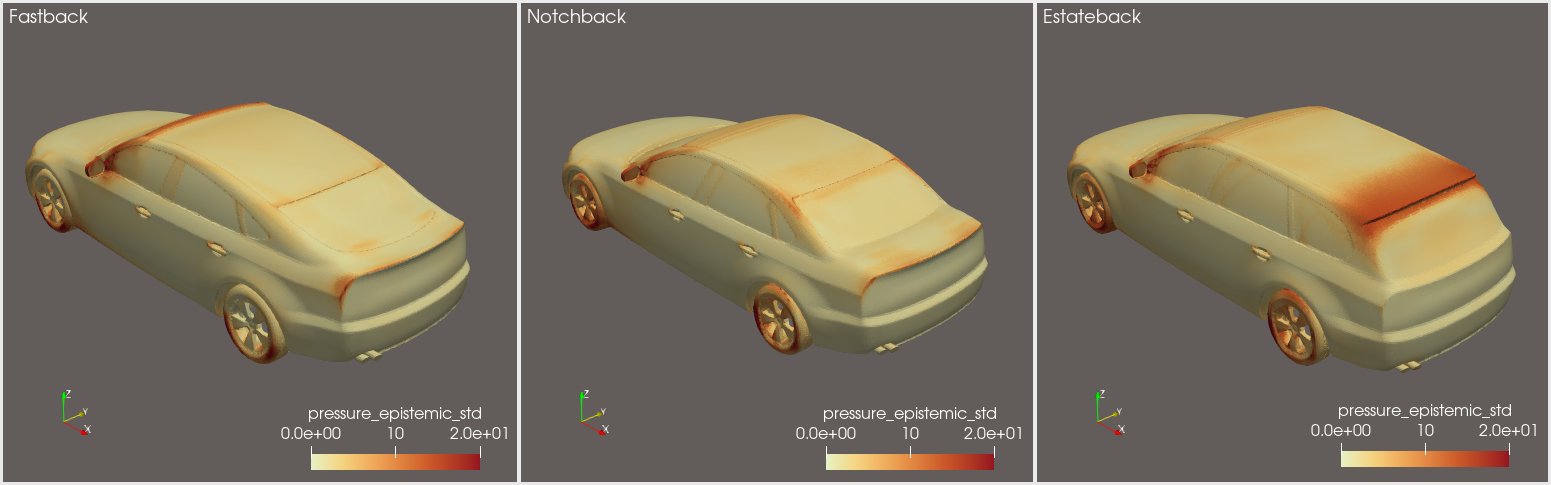
Per-point epistemic std of surface pressure on three DrivAerStar body styles#
The head was trained on Fastback geometries (class F) alone and then evaluated on the Notchback and Estateback classes. Each panel shows the per-point epistemic standard deviation of surface pressure on a shared color scale, all of it from a single forward pass.
The uncertainty field is smooth and follows the geometry rather than scattering as per-point noise, and its magnitude tracks geometric similarity to the training set. The Notchback, the closest of the three to a Fastback, stays near the in-distribution level, while the Estateback’s extended roof and tailgate are the most uncertain region in the figure.
Using the head with another backbone#
The head is model-agnostic: it consumes a feature tensor and nothing else. There is no dependency on mesh topology, and coordinates are not a separate input (any positional encoding the backbone applies simply arrives inside the features). The contract is:
the backbone emits per-point features with last dimension
input_dim— any leading batch/point dims are flattened internally, so(B, N, D),(N, D)and(B, T, N, D)all work;targets are
(..., num_tasks)with matching leading dims.
So attaching it to DoMINO, MeshGraphNet or any other point-wise encoder means exposing whatever that model computes before its final projection:
from physicsnemo.experimental.uq import FieldVariationalGPHead

head = FieldVariationalGPHead(
    input_dim=feat_dim,          # backbone feature width
    num_tasks=4,                 # output channels
    n_train=n_points_per_epoch,  # ELBO normalizer
    mlp_hidden=[128, 16],
    feature_norm="l2_radial",
)

feats = backbone.encode(batch)              # (B, N, feat_dim)
mean, neg_elbo = head.forward_and_loss(feats, targets, beta=beta)
loss = neg_elbo + lambda_mse * mse(mean, targets)
The snippet runs, but it is not the full recipe. The terms in The auxiliary terms live in the training script, so a new backbone needs its own copy of them. Most carry over unchanged; two need retuning:
The noise floor scales with your targets.
noise_std_range[0]works by sitting just below the σ band the noise head settles into, which depends entirely on how the targets are normalized. The0.01here suits unit-variance standardized fields. On a different target scale the same number either binds at every point or stops guarding the1/σ²(x)weighting altogether, so move it with the targets and check it against the σ range the run actually logs.The warmup windows are in epochs, not fractions.
30of100here; a shorter or longer run needs the window moved to keep the same ordering, since a ramp that ends after training does nothing but scale the loss down.
The mean anchor, gradient clipping and the 0.5 KL weight are backbone-agnostic and can be carried over as they are. The distance penalty is the one genuinely optional term (dist_penalty_weight: 0.0 disables it) and it costs one extra transform_features call per step.
Three further practical notes:
Seed the inducing points from real features once the backbone is warm (
head.set_inducing_points(...)); random-normal inducing locations in a feature space the backbone has never visited start the GP badly conditioned.``n_train`` is the total number of training points per epoch (geometries x points per geometry), not the number of geometries. It only sets the ELBO’s KL normalization, but getting it wrong rescales the KL term.
Prefer config over code for anything structural. Inside this example the head is never constructed with literals as shown above; it comes from the
gp_headblock viahydra.utils.instantiate, which is what keeps training and evaluation in agreement about the checkpoint’s layout. A new backbone needs its owngp_headblock (onlyinput_dimchanges, in general) rather than a second copy of these arguments in Python.
References#
Sparse variational GP — the inducing points and the ELBO:
Variational Learning of Inducing Variables in Sparse Gaussian Processes: Titsias, AISTATS 2009 — the inducing-point variational bound
Gaussian Processes for Big Data: Hensman, Fusi & Lawrence, UAI 2013 — the minibatch
(1/N) * sum E_q[log p] - KLform._hetero_neg_elbomirrors this normalization deliberately so it matches GPyTorch’sVariationalELBO, andn_trainis theNhere
GP on neural-network features:
Stochastic Variational Deep Kernel Learning: Wilson, Hu, Salakhutdinov & Xing, NeurIPS 2016 — the construction this head implements (DKL MLP feeding a variational GP)
The Promises and Pitfalls of Deep Kernel Learning: Ober, Rasmussen & van der Wilk, UAI 2021 — documents the DKL overfitting and feature-collapse modes. Directly relevant to why
gp_head.feature_normand the lengthscale priors are not optional here
Input-dependent observation noise:
Regression with Input-dependent Noise: A Gaussian Process Treatment: Goldberg, Williams & Bishop, NIPS 1997 — the original heteroscedastic GP
Variational Heteroscedastic Gaussian Process Regression: Lázaro-Gredilla & Titsias, ICML 2011 — the variational treatment, with a second GP on the log-noise
Large-scale Heteroscedastic Regression via Gaussian Process: Liu, Ong & Cai, 2018b — a sparse, minibatch-capable heteroscedastic ELBO; the closest published objective to ours, with the noise carried by a second GP rather than our noise MLP
What Uncertainties Do We Need in Bayesian Deep Learning for Computer Vision?: Kendall & Gal, NeurIPS 2017 — the amortized-network noise head and noise-attenuated likelihood we actually use. We borrow the mechanism, not the “aleatoric” interpretation (see The variance decomposition)
Interpreting the noise term, and multi-output structure:
Bayesian Calibration of Computer Models: Kennedy & O’Hagan, JRSS-B 2001 — model discrepancy: the gap between a deterministic simulator and truth, which is what
sigma^2(x)absorbs on a deterministic RANS datasetRemarks on Multi-Output Gaussian Process Regression: Liu, Cai & Ong, Knowledge-Based Systems 2018a — multi-output GP structure; this head uses the independent-per-task case (no cross-channel covariance)
Concrete Dropout / MC-Dropout#
GeoTransolver supports model uncertainty quantification (UQ) via Concrete Dropout (Gal, Hron & Kendall, NeurIPS 2017). Model UQ captures the uncertainty arising from the model itself – given finite training data, there are many plausible sets of model weights, and model UQ estimates how much predictions vary across them. Instead of manually tuning per-layer dropout rates, Concrete Dropout learns the optimal dropout probability for each layer during training using a differentiable relaxation. At inference time, MC-Dropout (Monte Carlo Dropout) approximates Bayesian inference by running multiple stochastic forward passes, producing both a mean prediction and a per-point uncertainty estimate.
Training with Concrete Dropout#
Enable Concrete Dropout by setting two configuration options:
python train.py --config-name geotransolver_surface \
    model.concrete_dropout=true \
    training.lambda_reg=1e-4
model.concrete_dropout=truereplaces standard dropout layers with learnableConcreteDropoutlayers throughout the model (GALE attention, context projectors, and FFN blocks).training.lambda_regcontrols the weight of the dropout entropy regularization loss. This term encourages the learned dropout rates away from trivial values (0 or 1). A value of0.0(default) disables the regularization. Typical values are in the range1e-5to1e-3.
During training, the learned dropout rates for each layer are logged to TensorBoard under dropout_rates/.
Inference with MC-Dropout#
After training a model with Concrete Dropout, run MC-Dropout inference by specifying the number of stochastic forward passes:
python src/inference_on_zarr.py --config-name geotransolver_surface \
    run_id=/path/to/model/ \
    mc_dropout_samples=20
python src/inference_on_vtk.py --config-name geotransolver_surface \
    run_id=/path/to/model/ \
    mc_dropout_samples=20
mc_dropout_samplessets the number of stochastic forward passes. Each pass uses the learned dropout masks to produce a different prediction. The mean across passes gives the final prediction, and the standard deviation provides a per-point uncertainty estimate.When
mc_dropout_samples=0(the default), inference runs in standard deterministic mode with no dropout.The VTK inference script (
inference_on_vtk.py) writes the mean and standard deviation fields to the output VTK files alongside the deterministic predictions.
Note: MC-Dropout inference requires a model that was trained with
concrete_dropout=true. Ifmc_dropout_samples > 0is set but no ConcreteDropout layers are found in the checkpoint, the script will log a warning and fall back to deterministic inference.