> This page is for Self-Hosted, version v3.0 (default).
> For other versions, use one of these documentation indexes:
> - v3.0 (default): https://docs.nvidia.com/run-ai/self-hosted/v3.0/llms.txt
> - v2.26: https://docs.nvidia.com/run-ai/self-hosted/v2.26/llms.txt
> - v2.25: https://docs.nvidia.com/run-ai/self-hosted/v2.25/llms.txt
> - v2.24: https://docs.nvidia.com/run-ai/self-hosted/v2.24/llms.txt
> For clean Markdown of any page, append .md to the page URL.
> For a complete documentation index, see https://docs.nvidia.com/run-ai/llms.txt.
> For AI client integration (Claude Code, Cursor, etc.), connect to the MCP server at https://docs.nvidia.com/run-ai/_mcp/server.
# Deploy Infrastructure Quick Start
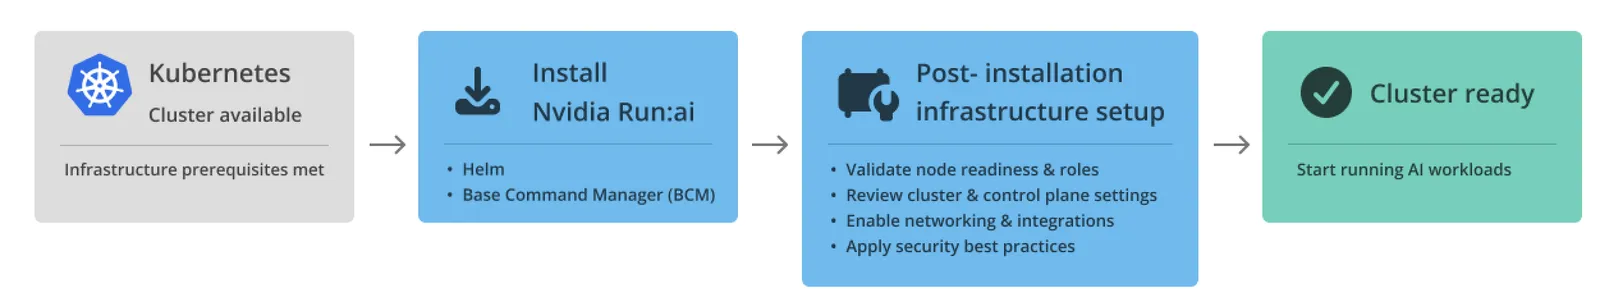
This guide walks through the initial deployment of NVIDIA Run:ai infrastructure: preparing your environment, installing the platform, and completing the onboarding wizard. This is part of Day 1 (Setup) of the platform lifecycle and assumes Day 0 planning is complete. For the full picture, see the [Installation and Configuration overview](/run-ai/self-hosted/documentation/installation-and-configuration/overview).
## Prerequisites
Before you begin, ensure that:
* A Kubernetes cluster is up and running.
* [Helm](https://helm.sh/) 3.14 or later is installed.
* You have `kubectl` access to the cluster with admin-level permissions.
* You have reviewed [System Requirements](/run-ai/self-hosted/documentation/installation-and-configuration/system-requirements) and prepared your Kubernetes environment accordingly.
## Install the Platform
The platform supports the following installation paths, depending on your environment. All three are available for both Open Source and NVIDIA Run:ai Support-Entitled, except BCM, which is available for NVIDIA Run:ai Support-Entitled only.
* [Guided Installation](/run-ai/self-hosted/documentation/installation-and-configuration/install/guided-installation) (Recommended) - `runai-installer` CLI - reads a single configuration YAML file and performs the full installation. Best for most deployments.
* [Manual Helm](/run-ai/self-hosted/documentation/installation-and-configuration/install/manual-helm/preparations) - NVIDIA Run:ai Helm charts, deployed directly. Best for organizations managing deployments through their own tooling (for example, Argo CD), or needing granular control over Helm values.
* [BCM](/run-ai/self-hosted/documentation/installation-and-configuration/install/bcm-install) (NVIDIA Run:ai Support-Entitled only) - NVIDIA Base Command Manager. Best for DGX SuperPOD environments managed by BCM.
## Complete the Onboarding Wizard
After installation, sign in to the NVIDIA Run:ai UI. The onboarding wizard launches automatically and guides you through the required steps.
The wizard includes both infrastructure-level and organizational steps. Complete the infrastructure-related steps below, then continue with authentication and the remaining organizational setup in the [Configure the Platform Quick Start](/run-ai/self-hosted/documentation/getting-started/quick-starts/configure-the-platform-quick-start#complete-the-onboarding-wizard).
**Note**
Do not close the wizard before all steps are complete. The onboarding wizard cannot be reopened once dismissed.
### Connect Your Cluster
**Note**
If the NVIDIA Run:ai cluster is already deployed and connected to the control plane (e.g., via BCM installation or a pre-run Helm installation), the wizard will automatically detect the connection and skip this part.
A cluster is your organization's compute infrastructure, where AI workloads are executed. The wizard generates the [Helm](/run-ai/self-hosted/documentation/installation-and-configuration/install/manual-helm/preparations) command that you run on your Kubernetes cluster to install the required components and prepare the cluster for workload scheduling.
The wizard displays **Waiting for cluster to connect** while the cluster is being installed and connected to the control plane. Once the installation completes successfully and the cluster establishes communication with the control plane, the wizard updates to **Cluster connected**. After completing the wizard flow, the cluster is added to the [Clusters](/run-ai/self-hosted/documentation/installation-and-configuration/operate/clusters) table.
### Configure Email Server
Configure the [email server](/run-ai/self-hosted/documentation/platform-management/settings/general-settings/notifications#email-notifications) used by NVIDIA Run:ai to send system notifications and user invitations. Email configuration ensures that users receive onboarding emails, password resets, and other platform notifications. This step prepares the platform for user onboarding and ongoing communication.
## Next Steps
Once the platform is installed and connected, continue with the rest of Day 1 [Configuration](/run-ai/self-hosted/documentation/installation-and-configuration/config) to make the cluster production-ready, then Day 2 [Operations](/run-ai/self-hosted/documentation/installation-and-configuration/operate) to keep it running reliably. See the [Installation and Configuration overview](/run-ai/self-hosted/documentation/installation-and-configuration/overview) for the full lifecycle, including upgrade and troubleshooting guidance.