> This page is for Self-Hosted, version v3.0 (default).
> For other versions, use one of these documentation indexes:
> - v3.0 (default): https://docs.nvidia.com/run-ai/self-hosted/v3.0/llms.txt
> - v2.26: https://docs.nvidia.com/run-ai/self-hosted/v2.26/llms.txt
> - v2.25: https://docs.nvidia.com/run-ai/self-hosted/v2.25/llms.txt
> - v2.24: https://docs.nvidia.com/run-ai/self-hosted/v2.24/llms.txt
> For clean Markdown of any page, append .md to the page URL.
> For a complete documentation index, see https://docs.nvidia.com/run-ai/llms.txt.
> For AI client integration (Claude Code, Cursor, etc.), connect to the MCP server at https://docs.nvidia.com/run-ai/_mcp/server.
# Over Quota, Fairness and Preemption
This quick start provides a step-by-step walkthrough of the core scheduling concepts - [over quota](/run-ai/self-hosted/documentation/platform-management/runai-scheduler/scheduling/concepts-and-principles#over-quota), [fairness](/run-ai/self-hosted/documentation/platform-management/runai-scheduler/scheduling/concepts-and-principles#fairness-fair-resource-distribution), and [preemption](/run-ai/self-hosted/documentation/platform-management/runai-scheduler/scheduling/concepts-and-principles#priority-and-preemption). It demonstrates the simplicity of resource provisioning and how the system eliminates bottlenecks by allowing users or teams to exceed their resource quota when free GPUs are available.
* **Over quota** - In this scenario, team-a runs two training workloads and team-b runs one. Team-a has a quota of 3 GPUs and is over quota by 1 GPU, while team-b has a quota of 1 GPU. The system allows this over quota usage as long as there are available GPUs in the cluster.
* **Fairness and preemption** - Since the cluster is already at full capacity, when team-b launches a new b2 workload requiring 1 GPU , team-a can no longer remain over quota. To maintain fairness, the [NVIDIA Run:ai Scheduler](/run-ai/self-hosted/documentation/platform-management/runai-scheduler/scheduling/how-the-scheduler-works) preempts workload a1 (1 GPU), freeing up resources for team-b.
## Prerequisites
* You have created two [projects](/run-ai/self-hosted/documentation/platform-management/manage-ai-initiatives/organization/projects) - team-a and team-b - or have them created for you.
* Each project has an assigned quota of 2 GPUs. In this example, we have 4 GPUs on 2 machines with 2 GPUs each.
**Note**
Flexible workload submission is enabled by default. If unavailable, contact your administrator to enable it under **General settings** → Workloads → Flexible workload submission.
## Step 1: Logging In
Browse to the provided NVIDIA Run:ai user interface and log in with your credentials.
Run the below --help command to obtain the login options and log in according to your setup:
```sh
runai login --help
```
To use the API, you will need to obtain a token as shown in [API authentication](/run-ai/self-hosted/reference/rest-api/getting-started/how-to-authenticate-to-the-api).
## Step 2: Submitting the First Training Workload (team-a)
1. Go to Workload manager → Workloads
2. Click **+NEW WORKLOAD** and select **Training**
3. Select under which **cluster** to create the workload
4. Select the **project** named team-a
5. Under **Workload architecture**, select **Standard**
6. Select **Start from scratch** to launch a new training quickly
7. Enter **a1** as the workload **name**
8. Click **CONTINUE**
In the next step:
9. Under **Environment**, enter the **Image URL** - `kubeflow/pytorch-dist-mnist:latest`
10. Under **Runtime settings**, click **+COMMAND & ARGUMENTS**, then set the **Arguments** to `--epochs 100`.
11. Under **Compute resources**, click the **load** icon. A side pane appears, displaying a list of available compute resources. Select the **‘one-gpu’** compute resource for your workload.
* If ‘one-gpu’ is not displayed, follow the below steps to create a one-time compute resource configuration:
* Set **GPU devices** per pod - 1
* Optional: set the **CPU compute** per pod - 0.1 cores (default)
* Optional: set the **CPU memory** per pod - 100 MB (default)
12. Click **CREATE TRAINING**
1. Go to the Workload Manager → Workloads
2. Click **+NEW WORKLOAD** and select **Training**
3. Select under which **cluster** to create the workload
4. Select the **project** named team-a
5. Under **Workload architecture**, select **Standard**
6. Select **Start from scratch** to launch a new training quickly
7. Enter **a1** as the workload **name**
8. Click **CONTINUE**\
In the next step:
9. Create a new environment:
* Click **+NEW ENVIRONMENT**
* Enter quick-start as the **name** for the environment. The name must be unique.
* Enter the **Image URL** - `kubeflow/pytorch-dist-mnist:latest`
* Set the runtime settings for the environment. Click **+COMMAND & ARGUMENTS** and enter the arguments - `--epochs 100`
* Click **CREATE ENVIRONMENT**
The newly created environment will be selected automatically
10. Select the **‘one-gpu’** compute resource for your workload
* If ‘one-gpu’ is not displayed in the gallery, follow the below steps:
* Click **+NEW COMPUTE RESOURCE**
* Enter one-gpu as the **name** for the compute resource. The name must be unique.
* Set **GPU devices** per pod - 1
* Optional: set the **CPU compute** per pod - 0.1 cores (default)
* Optional: set the **CPU memory** per pod - 100 MB (default)
* Click **CREATE COMPUTE RESOURCE**
The newly created compute resource will be selected automatically
11. Click **CREATE TRAINING**
Copy the following command to your terminal. For more details, see [CLI reference](/run-ai/self-hosted/reference/cli/runai/training/runai-training-submit):
```sh
runai training submit a1 -i kubeflow/pytorch-dist-mnist:latest -g 1 -p team-a -- --epochs 100
```
Copy the following command to your terminal. Make sure to update the following parameters. For more details, see [Trainings](https://docs.nvidia.com/run-ai/self-hosted/v3.0/reference/rest-api/endpoints/workloads/trainings/create-training-1) API.
```bash
curl --location 'https:///api/v1/workloads/trainings' \
--header 'Content-Type: application/json' \
--header 'Authorization: Bearer ' \
--data '{
"name": "a1",
"projectId": "",
"clusterId": "",
"spec": {
"image":"kubeflow/pytorch-dist-mnist:latest",
"args": "--epochs 100",
"compute": {
"gpuDevicesRequest": 1
}
}
}'
```
* `` - The link to the NVIDIA Run:ai user interface
* `` - The API access token obtained in [Step 1](/run-ai/self-hosted/documentation/platform-management/runai-scheduler/scheduling/quick-starts/over-quota#a13adq7eth7w)
* `` - The ID of the Project the workload is running on. You can get the Project ID via the [Get Projects](https://docs.nvidia.com/run-ai/self-hosted/v3.0/reference/rest-api/endpoints/organizations/projects/get-projects) API.
* `` - The unique identifier of the Cluster. You can get the Cluster UUID via the [Get Clusters](https://docs.nvidia.com/run-ai/multi-tenant/v3.0/reference/rest-api/endpoints/organizations/clusters/get-clusters) API.
**Note**
The above API snippet runs with NVIDIA Run:ai clusters of 2.18 and above only.
## Step 3: Submitting the Second Training Workload (team-a)
1. Go to the Workload Manager → Workloads
2. Click **+NEW WORKLOAD** and select **Training**
3. Select the **cluster** where the previous training workload was created
4. Select the **project** named team-a
5. Under **Workload architecture**, select **Standard**
6. Select **Start from scratch** to launch a new training quickly
7. Enter **a2** as the workload **name**
8. Click **CONTINUE**\
In the next step:
9. Under **Environment**, enter the **Image URL** - `kubeflow/pytorch-dist-mnist:latest`
10. Under **Runtime settings**, click **+COMMAND & ARGUMENTS**, then set the **Arguments** to `--epochs 100`.
11. Under **Compute resources**, click the **load** icon. A side pane appears, displaying a list of available compute resources. Select the **‘two-gpus’** compute resource for your workload.
* If ‘two-gpus’ is not displayed, follow the below steps to create a one-time compute resource configuration:
* Set **GPU devices** per pod - 2
* Optional: set the **CPU compute** per pod - 0.1 cores (default)
* Optional: set the **CPU memory** per pod - 100 MB (default)
12. Click **CREATE TRAINING**
1. Go to the Workload Manager → Workloads
2. Click **+NEW WORKLOAD** and select **Training**
3. Select the **cluster** where the previous training workload was created
4. Select the **project** named team-a
5. Under **Workload architecture**, select **Standard**
6. Select **Start from scratch** to launch a new training quickly
7. Enter **a2** as the workload **name**
8. Click **CONTINUE**\
In the next step:
9. Select the environment created in [Step 2](/run-ai/self-hosted/documentation/platform-management/runai-scheduler/scheduling/quick-starts/over-quota#i3c9jpfzerlq)
10. Select the **‘two-gpus’** compute resource for your workload
* If ‘two-gpus’ is not displayed in the gallery, follow the below steps:
* Click **+NEW COMPUTE RESOURCE**
* Enter two-gpus as the **name** for the compute resource. The name must be unique.
* Set **GPU devices** per pod - 2
* Optional: set the **CPU compute per pod** - 0.1 cores (default)
* Optional: set the **CPU memory per pod** - 100 MB (default)
* Click **CREATE COMPUTE RESOURCE**
The newly created compute resource will be selected automatically
11. Click **CREATE TRAINING**
Copy the following command to your terminal. For more details, see [CLI reference](/run-ai/self-hosted/reference/cli/runai/training/runai-training-submit):
```sh
runai training submit a2 -i kubeflow/pytorch-dist-mnist:latest -g 2 -p team-a -- --epochs 100
```
Copy the following command to your terminal. Make sure to update the following parameters. For more details, see [Trainings](https://docs.nvidia.com/run-ai/self-hosted/v3.0/reference/rest-api/endpoints/workloads/trainings/create-training-1) API.
```bash
curl --location 'https:///api/v1/workloads/trainings' \
--header 'Content-Type: application/json' \
--header 'Authorization: Bearer ' \
--data '{
"name": "a2",
"projectId": "",
"clusterId": "",
"spec": {
"image":"kubeflow/pytorch-dist-mnist:latest",
"args": "--epochs 100",
"compute": {
"gpuDevicesRequest": 2
}
}
}'
```
* `` - The link to the NVIDIA Run:ai user interface
* `` - The API access token obtained in [Step 1](/run-ai/self-hosted/documentation/platform-management/runai-scheduler/scheduling/quick-starts/over-quota#a13adq7eth7w)
* `` - The ID of the Project the workload is running on. You can get the Project ID via the [Get Projects](https://docs.nvidia.com/run-ai/self-hosted/v3.0/reference/rest-api/endpoints/organizations/projects/get-projects) API.
* `` - The unique identifier of the Cluster. You can get the Cluster UUID via the [Get Clusters](https://docs.nvidia.com/run-ai/multi-tenant/v3.0/reference/rest-api/endpoints/organizations/clusters/get-clusters) API.
**Note**
The above API snippet runs with NVIDIA Run:ai clusters of 2.18 and above only.
## Step 4: Submitting the First Training Workload (team-b)
1. Go to the Workload Manager → Workloads
2. Click **+NEW WORKLOAD** and select **Training**
3. Select the **cluster** where the previous training was created
4. Select the **project** named team-b
5. Under **Workload architecture**, select **Standard**
6. Select **Start from scratch** to launch a new training quickly
7. Enter **b1** as the workload **name**
8. Click **CONTINUE**
In the next step:
9. Under **Environment**, enter the **Image URL** - `kubeflow/pytorch-dist-mnist:latest`
10. Under **Runtime settings**, click **+COMMAND & ARGUMENTS**, then set the **Arguments** to `--epochs 100`.
11. Under **Compute resources**, click the **load** icon. A side pane appears, displaying a list of available compute resources. Select the **‘one-gpu’** compute resource for your workload.
* If ‘one-gpu’ is not displayed, follow the below steps to create a one-time compute resource configuration:
* Set **GPU devices** per pod - 1
* Optional: set the **CPU compute** per pod - 0.1 cores (default)
* Optional: set the **CPU memory** per pod - 100 MB (default)
12. Click **CREATE TRAINING**
1. Go to the Workload Manager → Workloads
2. Click **+NEW WORKLOAD** and select **Training**
3. Select the **cluster** where the previous training was created
4. Select the **project** named team-b
5. Under **Workload architecture**, select **Standard**
6. Select **Start from scratch** to launch a new training quickly
7. Enter **b1** as the workload **name**
8. Click **CONTINUE**\
In the next step:
9. Create a new environment:
* Click **+NEW ENVIRONMENT**
* Enter quick-start as the **name** for the environment. The name must be unique.
* Enter the **Image URL** - `kubeflow/pytorch-dist-mnist:latest`
* Set the runtime settings for the environment. Click **+COMMAND & ARGUMENTS** and enter the arguments - `--epochs 100`
* Click **CREATE ENVIRONMENT**
The newly created environment will be selected automatically
10. Select the **‘one-gpu’** compute resource for your workload
* If ‘one-gpu’ is not displayed in the gallery, follow the below steps:
* Click **+NEW COMPUTE RESOURCE**
* Enter one-gpu as the **name** for the compute resource. The name must be unique.
* Set **GPU devices** per pod - 1
* Optional: set the **CPU compute** per pod - 0.1 cores (default)
* Optional: set the **CPU memory** per pod - 100 MB (default)
* Click **CREATE COMPUTE RESOURCE**
The newly created compute resource will be selected automatically
11. Click **CREATE TRAINING**
Copy the following command to your terminal. For more details, see [CLI reference](/run-ai/self-hosted/reference/cli/runai/training/runai-training-submit):
```sh
runai training submit b1 -i kubeflow/pytorch-dist-mnist:latest -g 1 -p team-b -- --epochs 100
```
Copy the following command to your terminal. Make sure to update the following parameters. For more details, see [Trainings](https://docs.nvidia.com/run-ai/self-hosted/v3.0/reference/rest-api/endpoints/workloads/trainings/create-training-1) API.
```bash
curl --location 'https:///api/v1/workloads/trainings' \
--header 'Content-Type: application/json' \
--header 'Authorization: Bearer ' \
--data '{
"name": "b1",
"projectId": "",
"clusterId": "",
"spec": {
"image":"kubeflow/pytorch-dist-mnist:latest",
"args": "--epochs 100",
"compute": {
"gpuDevicesRequest": 1
}
}
}'
```
* `` - The link to the NVIDIA Run:ai user interface
* `` - The API access token obtained in [Step 1](/run-ai/self-hosted/documentation/platform-management/runai-scheduler/scheduling/quick-starts/over-quota#a13adq7eth7w)
* `` - The ID of the Project the workload is running on. You can get the Project ID via the [Get Projects](https://docs.nvidia.com/run-ai/self-hosted/v3.0/reference/rest-api/endpoints/organizations/projects/get-projects) API.
* `` - The unique identifier of the Cluster. You can get the Cluster UUID via the [Get Clusters](https://docs.nvidia.com/run-ai/multi-tenant/v3.0/reference/rest-api/endpoints/organizations/clusters/get-clusters) API.
**Note**
The above API snippet runs with NVIDIA Run:ai clusters of 2.18 and above only.
### Over Quota Status
System status after run:
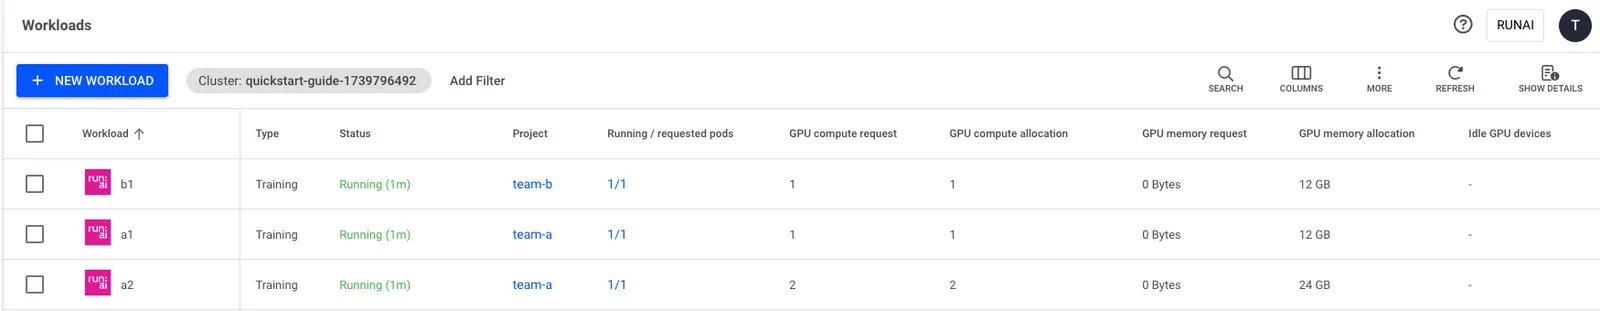
System status after run:
```sh
~ runai workload list -A
Workload Type Status Project Running/Req.Pods GPU Alloc.
────────────────────────────────────────────────────────────────────────────
a2 Training Running team-a 1/1 2.00
b1 Training Running team-b 1/1 1.00
a1 Training. Running team-a 0/1 1.00
```
System status after run:
```
curl --location 'https:///api/v1/workloads' \
--header 'Content-Type: application/json' \
--header 'Authorization: Bearer ' \ # is the API access token obtained in Step 1.
--data ''
```
## Step 5: Submitting the Second Training Workload (team-b)
1. Go to the Workload Manager → Workloads
2. Click **+NEW WORKLOAD** and select **Training**
3. Select the **cluster** where the previous training was created
4. Select the **project** named team-b
5. Under **Workload architecture**, select **Standard**
6. Select **Start from scratch** to launch a new training quickly
7. Enter **b2** as the workload **name**
8. Click **CONTINUE**
In the next step:
9. Under **Environment**, enter the **Image URL** - `kubeflow/pytorch-dist-mnist:latest`
10. Under **Runtime settings**, click **+COMMAND & ARGUMENTS**, then set the **Arguments** to `--epochs 100`.
11. Under **Compute resources**, click the **load** icon. A side pane appears, displaying a list of available compute resources. Select the **‘one-gpu’** compute resource for your workload.
* If ‘one-gpu’ is not displayed, follow the below steps to create a one-time compute resource configuration:
* Set **GPU devices** per pod - 1
* Optional: set the **CPU compute** per pod - 0.1 cores (default)
* Optional: set the **CPU memory** per pod - 100 MB (default)
12. Click **CREATE TRAINING**
1. Go to the Workload Manager → Workloads
2. Click **+NEW WORKLOAD** and select **Training**
3. Select the **cluster** where the previous training was created
4. Select the **project** named team-b
5. Under **Workload architecture**, select **Standard**
6. Select **Start from scratch** to launch a new training quickly
7. Enter **b2** as the workload **name**
8. Click **CONTINUE**\
In the next step:
9. Select the environment created in [Step 4](/run-ai/self-hosted/documentation/platform-management/runai-scheduler/scheduling/quick-starts/over-quota#i3c9jpfzerlq-2)
10. Select the compute resource created in [Step 4](/run-ai/self-hosted/documentation/platform-management/runai-scheduler/scheduling/quick-starts/over-quota#i3c9jpfzerlq-2)
11. Click **CREATE TRAINING**
Copy the following command to your terminal. For more details, see [CLI reference](/run-ai/self-hosted/reference/cli/runai/training/runai-training-submit):
```sh
runai training submit b2 -i kubeflow/pytorch-dist-mnist:latest -g 1 -p team-b -- --epochs 100
```
Copy the following command to your terminal. Make sure to update the following parameters. For more details, see [Trainings](https://docs.nvidia.com/run-ai/self-hosted/v3.0/reference/rest-api/endpoints/workloads/trainings/create-training-1) API.
```bash
curl --location 'https:///api/v1/workloads/trainings' \
--header 'Content-Type: application/json' \
--header 'Authorization: Bearer ' \
--data '{
"name": "b2",
"projectId": "",
"clusterId": "",
"spec": {
"image":"kubeflow/pytorch-dist-mnist:latest",
"args": "--epochs 100",
"compute": {
"gpuDevicesRequest": 1
}
}
}'
```
* `` - The link to the NVIDIA Run:ai user interface
* `` - The API access token obtained in [Step 1](/run-ai/self-hosted/documentation/platform-management/runai-scheduler/scheduling/quick-starts/over-quota#a13adq7eth7w)
* `` - The ID of the Project the workload is running on. You can get the Project ID via the [Get Projects](https://docs.nvidia.com/run-ai/self-hosted/v3.0/reference/rest-api/endpoints/organizations/projects/get-projects) API.
* `` - The unique identifier of the Cluster. You can get the Cluster UUID via the [Get Clusters](https://docs.nvidia.com/run-ai/multi-tenant/v3.0/reference/rest-api/endpoints/organizations/clusters/get-clusters) API.
**Note**
The above API snippet runs with NVIDIA Run:ai clusters of 2.18 and above only.
### Basic Fairness and Preemption Status
Workloads status after run:
![]()
Workloads status after run:
```sh
~ runai workload list -A
Workload Type Status Project Running/Req.Pods GPU Alloc.
────────────────────────────────────────────────────────────────────────────
a2 Training Running team-a 1/1 2.00
b1 Training Running team-b 1/1 1.00
b2 Training Running team-b 1/1 1.00
a1 Training. Pending team-a 0/1 1.00
```
Workloads status after run:
```bash
curl --location 'https:///api/v1/workloads' \
--header 'Content-Type: application/json' \
--header 'Authorization: Bearer ' \ # is the API access token obtained in Step 1.
--data ''
```
## Next Steps
Manage and monitor your newly created workload using the [Workloads](/run-ai/self-hosted/documentation/workloads-in-nvidia-run-ai/workloads) table.