
Overview#
NVIDIA® vGPU (Virtual GPU) for Compute gives virtualized workloads GPU access through a dedicated-style device in each VM, backed by a whole physical GPU, a fraction of one, or several GPUs. This page explains core terms, how components fit together, the three vGPU™ modes - Time-Sliced vGPU, MIG-Backed vGPU, and Time-Sliced MIG-Backed vGPU - and headline features, before you install or size a deployment. For platform-specific known issues and host/guest constraints, refer to Limitations.
NVIDIA AI Enterprise is NVIDIA’s supported software stack for production AI (tools, libraries, and frameworks) in cloud and data center environments. It spans the application layer and the infrastructure layer.
NVIDIA vGPU for Compute is licensed only through NVIDIA AI Enterprise. It allocates GPU capacity to VMs flexibly: a dedicated GPU for a workload that needs one, a fraction of a GPU so several workloads can run on fewer physical GPUs, or several GPUs aggregated into a single VM. On top of that allocation it adds host-side management and monitoring and lifecycle operations such as Suspend/Resume, Live Migration, and Warm Updates, which matter to cloud service providers (CSPs) and IT teams running shared infrastructure.
Quick Start#
New to NVIDIA vGPU for Compute? Follow this recommended path:
Understand the Basics - This Overview for concepts, architecture, and vGPU configuration modes; Features for capability detail; Limitations for platform-specific known issues.
Install Components - Installation for NGC™ CLI, Virtual GPU Manager, and guest drivers.
Configure Licensing - Licensing to connect VMs to NVIDIA License System.
Configure vGPU - Configuration for MIG-backed vGPU and profile selection.
Reference vGPU Types - Types Reference for vGPU type tables by GPU.
Key Terms#
For definitions of vGPU Manager, vGPU Guest Driver, NVIDIA Licensing System, and NVIDIA AI Enterprise Infra Collection, refer to the Glossary.
NVIDIA vGPU Architecture Overview#
Under the NVIDIA Virtual GPU Manager on the hypervisor, one physical GPU can expose multiple vGPUs, each attachable to a guest VM as its own GPU device.
Download the latest vGPU for Compute drivers from the NVIDIA AI Enterprise Infra 9 collection.
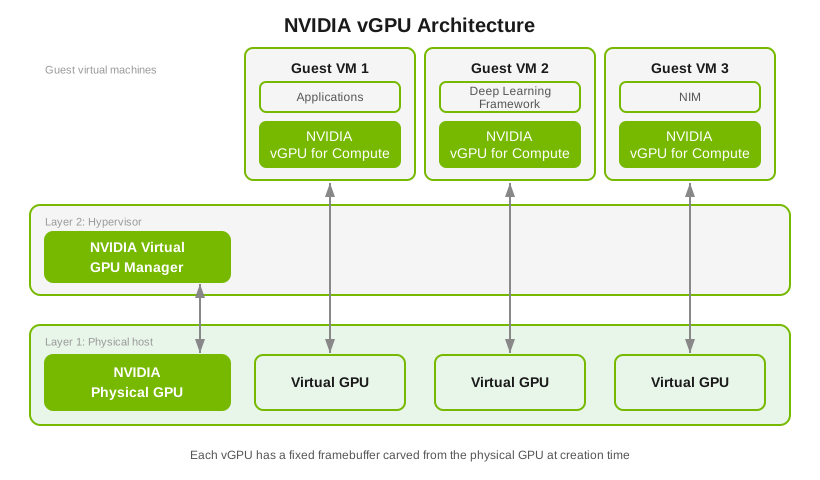
Each vGPU behaves like a GPU with a fixed framebuffer carved from the physical GPU at creation time; that memory stays reserved for that vGPU until the vGPU is destroyed.
NVIDIA vGPU for Compute Configurations#
Supported modes depend on the physical GPU:
Time-sliced vGPUs are available on all NVIDIA AI Enterprise supported GPUs.
On GPUs with Multi-Instance GPU (MIG), these MIG-backed variants are supported:
MIG-backed vGPUs that use a whole GPU instance
Time-sliced vGPUs within a MIG instance (time-sliced, MIG-backed)
vGPU Mode |
Description |
GPU Partitioning |
Isolation |
Use Cases |
Supported GPUs |
|---|---|---|---|---|---|
Time-Sliced vGPU |
Multiple Compute VMs time-share the same physical GPU: SMs and engines are used one vGPU at a time in scheduled slices. |
Temporal |
Strong hardware memory and fault isolation; round-robin scheduling yields solid throughput when strict per-VM compute isolation is not required. |
Workloads tolerating shared compute time, or platforms without MIG-backed vGPU. Typical fits: lighter inference, preprocessing, and model dev/test before large training. |
|
MIG-backed vGPU |
Built from one or more MIG slices on a MIG-capable GPU; each VM owns the SMs and engines of its GPU instance and runs in parallel with VMs on other instances on the same card. Refer to Virtual GPU Types for Supported GPUs for profiles and sizing. |
Spatial |
Strong hardware memory and fault isolation; dedicated cache and memory bandwidth per instance with lower scheduling jitter than pure time-slicing on the full GPU. |
Multi-tenant or SLA-sensitive setups: consistent inference, fine-tuning, or smaller training jobs that need predictable isolation on one physical GPU. |
|
Time-Sliced, MIG-Backed vGPU |
Uses part of a MIG instance; VMs on that instance time-share its SMs and engines. Introduced with the RTX™ PRO 6000 and RTX PRO 4500 Blackwell Server Edition GPUs. Profile details: Types Reference. |
Spatial between MIG instances; temporal within each instance. |
Hardware isolation between instances; within an instance, time-sharing similar tradeoffs to full-GPU time-slicing but scoped to the MIG partition. |
Dense multi-tenant layouts that need hard boundaries between tenant groups but more than one light workload per MIG slice - for example:
|
RTX PRO 6000 Blackwell Server Edition, RTX PRO 4500 Blackwell Server Edition |
Tip
For a full inference / multi-tenant mode decision table, refer to Choosing a vGPU Mode for Inference.
NVIDIA vGPU for Compute Key Features#
Beyond basic partitioning, vGPU for Compute adds networking, migration, scheduling, and memory features aimed at AI, ML, and HPC in virtualized clusters.
Capability |
Description |
Feature page |
|---|---|---|
MIG-Backed vGPU |
Hardware-level GPU partitioning with spatial isolation for multi-tenant workloads. |
|
Device Groups |
Automated detection and provisioning of physically connected devices for optimal topology. |
|
GPUDirect® RDMA and Storage |
Direct memory access and storage I/O bypass that reduces CPU overhead and latency for GPU-to-GPU and GPU-to-storage transfers. |
|
Heterogeneous vGPU |
Mixed vGPU profiles on a single GPU for diverse workload requirements. |
|
Live Migration |
VM migration with minimal downtime (seconds of stun time) for maintenance and load balancing on supported hypervisors. |
|
Multi-vGPU and P2P |
Multiple vGPUs per VM with peer-to-peer communication. |
|
NVIDIA NVSwitch™ |
High-bandwidth GPU-to-GPU interconnect fabric through NVLink™. |
|
NVLink Multicast |
Efficient one-to-many data distribution for distributed training. |
|
Scheduling Policies |
Workload-specific GPU scheduling algorithms. |
|
Suspend-Resume |
VM state preservation for resource management. |
|
Unified Virtual Memory |
Single memory address space across CPU and GPU. |
For platform support, configuration requirements, and compatibility tables per feature, refer to Features.
Platform Limitations and Known Issues#
For host monitoring caveats, hypervisor-specific known issues, MMIO requirements for large-memory VMs, NVIDIA Grace platform constraints, and Microsoft Windows Server constraints, refer to Limitations.