

Attention
Scaled Dot Product Attention
This operation computes the scaled dot product attention (SDPA), as
using the FlashAttention-2 algorithm as described in the paper FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning. It is applicable for both training and inference phases, with an option to generate a stats tensor to be used for backwards training computation.
Accumulation type for unified forward SDPA
The existing C++ SDPA_attributes::set_compute_data_type() and Python
compute_data_type argument specify the requested accumulation type. An unset
operation inherits the graph’s compute type; if both are unset, unified SDPA
defaults to FLOAT. This is independent of Q/K/V/O storage types: HALF or
BFLOAT16 tensors do not themselves request reduced-precision accumulation.
cuDNN 9.29.0 and newer expose
CUDNN_ATTR_OPERATION_SDPA_FWD_COMP_TYPE. The frontend forwards non-default
requests through that attribute, gated on the header version and, for dynamic
loading, the runtime backend version. FLOAT retains compatibility with older
headers and backends; a HALF request requires 9.29.0 or newer.
The matching backend currently rejects HALF at descriptor finalization:
this change adds precision plumbing, not an FP16-accumulator kernel.
Other accumulation types are rejected. Softmax reductions and statistics
remain FP32. Composite SDPA and backward SDPA are unchanged.
Support Matrix
cudnn SDPA operation requires SM80 (Ampere) or newer architectures and cuda toolkit 12.x or newer.
The support matrix is based on cuDNN backend version 9.18.1. Later sections note support changes introduced in newer cuDNN versions.
Glossary
¹ Interleaved q,k,v tensors. Generally they have layouts as BS3HD, B3SHD.
² Padded, variable length sequences (requires padding mask). When sequences in a batch have different lengths, use use_padding_mask=True with sequence length tensors.
Setup:
- Set use_padding_mask=True
- Provide seq_len_q tensor of shape (B, 1, 1, 1) with actual query sequence lengths
- Provide seq_len_kv tensor of shape (B, 1, 1, 1) with actual key/value sequence lengths
Example:
Batch with sequences “aa” (length 2) and “bbb” (length 3), max length S=8:
seq_len_q = [2, 3]seq_len_kv = [2, 3]- Dimensions:
- Strides: (standard BHSD)
cuDNN automatically masks out padding tokens during attention computation.
³ Ragged Layout.
For memory efficiency, variable-length sequences can be packed together without padding. This is called THD layout where is the total number of valid tokens.
Requirements:
- Must set ragged offset tensor via
tensor.set_ragged_offset(ragged_offset_tensor)
Ragged Offset Tensor:
- Shape:
- Contains cumulative token offsets in elements (not bytes)
- Last element is the total number of tokens
Ragged Offset Multiplier (cuDNN 9.24+, UNIFIED forward only):
tensor.set_ragged_offset_multiplier(value)lets the ragged offsets be stored in coarser units; the engine multiplies each offset byvalueto recover element offsets.max_total_seq_len_q/max_total_seq_len_kvdeclare the packed token totals of the ragged Q and K/V. A ragged tensor’s dims stay(B, H, S_max, D)and the per-sequence starts live in a device-side offset tensor, so the packed total is not otherwise expressible in the graph. Supplying it lets the implementation bound the token axis exactly rather than inferring an upper bound from the bound buffers’ extents — which matters when a buffer is allocated larger than the tokens it holds, since rows past the real total are masked but still take part inP @ Vand so must be finite. The values only ever tighten the inferred bound, never widen it, and are accepted only on a ragged layout.sdpa_backwardhas taken the same two arguments since cuDNN 9.6.- Example: with a multiplier of , a token-unit cumulative-sequence-length tensor (e.g.
cu_seq_len_q) can be bound directly as the ragged offset, avoiding a conversion pass.
Memory Layout visualization:
Example:
Same sequences “aa” and “bbb” packed together:
-
seq_len_q = [2, 3] -
seq_len_kv = [2, 3] -
Dimensions: (S is still max sequence length)
-
Strides: (strides unchanged, but ignored for ragged)
-
Ragged offset:
Partially Packed Layout:
Tokens within each batch can be contiguous without being globally packed.
- Ragged offset:
Not Supported:
Tokens that are not contiguous within a batch cannot be represented.
seq_len_q = [2, 3]
Note that Q,K,V and their gradients can be individually ragged or not.
Backward Pass with THD:
When using THD layout with cudnn, maximum total tokens are needed for efficient workspace allocation. If not set, defaults to which may overallocate memory.
⁴ None, Causal, Sliding window, Additive Bias, Softcap, Arbitrary masking.
⁵ d_qo should be equal to d_kv. (Except when d_qk == 192 and d_vo = 128, which is also supported.)
Important Notes on Support Surface
- All attention flavors MHA, MQA, GQA are supported.
- The head dim (d) should be a multiple of 8 for fp16/bf16 and multiple of 16 for fp8 data-types.
- The seqlens s_q, and s_kv can have arbitrary value.
- The layout of q,k,v,o and dq, dk, dv, do can be independent of each other.
- Dropout: Randomly zeros some of the attention weights after the softmax as a form of regularization.
You can configure dropout in two ways:
- Philox RNG dropout (more performant): Provide:
- An RNG seed tensor (INT32 or INT64)
- An RNG offset tensor (INT32 or INT64)
- A float representing the dropout probability (probability that any weight is set to zero)
- (Debug only) Output RNG dump tensor to capture the generated dropout mask
- Custom dropout mask: Provide:
- A
dropout masktensor matching the attention weights’ dimensions. Dimensions set to 1 will broadcast. - A
dropout scaletensor to adjust remaining weights, typically .
- A
- Philox RNG dropout (more performant): Provide:
- Stats from fprop is supported (Max, Sum). In addition QKClip required for KimiK2, Qwen are also supported optionally.
Benchmarks
To run the sdpa benchmarks, refer to benchmarks/sdpa folder. Current results:
GB200 - Llama 3.1 Causal (top_left)
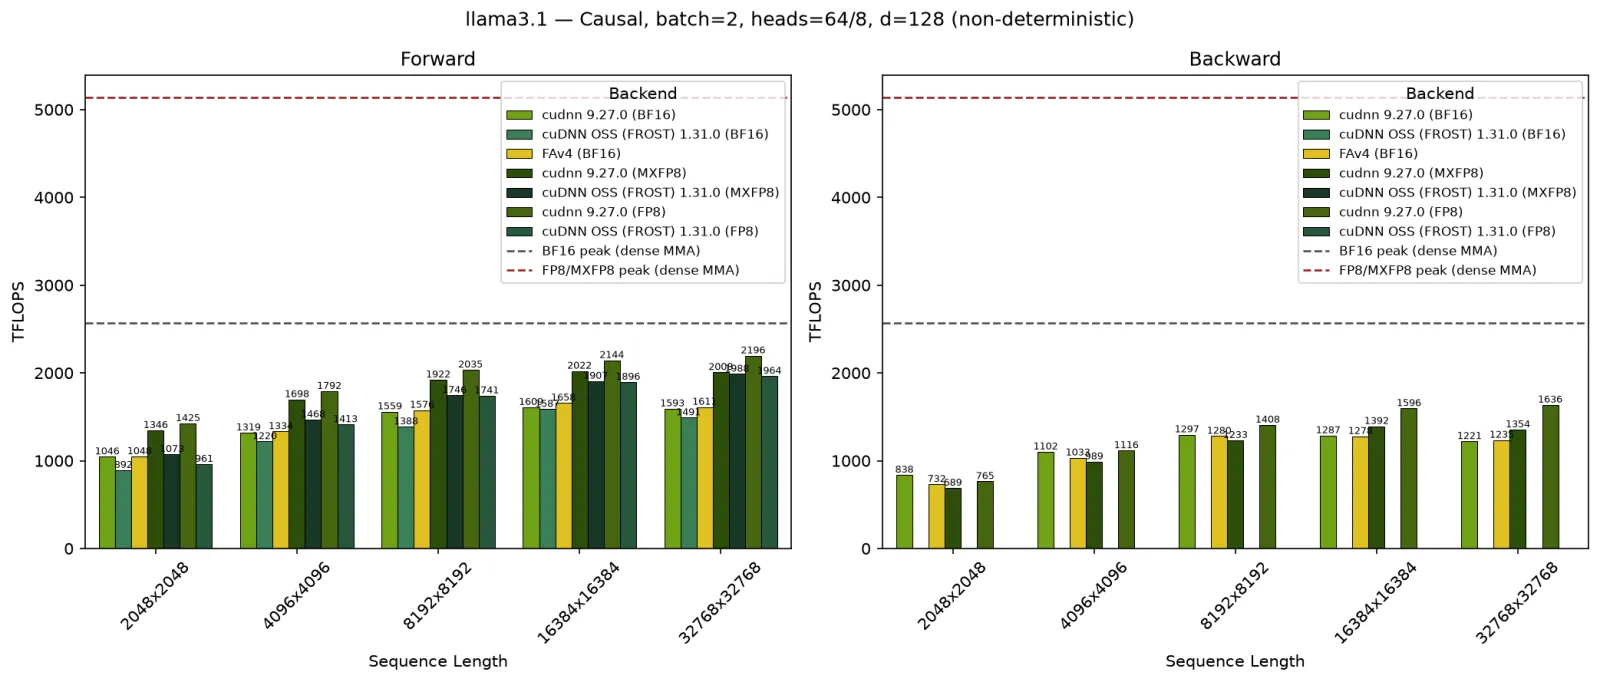
- SDPA parameters:
batch=1; num_q_heads=64; num_kv_heads=8; head_dim=128; is_causal=True - Sequence lengths shown on x-axis
- Results obtained on NVIDIA GB200 GPU
GB200 - Llama 3.1 Non-Causal (no_mask)
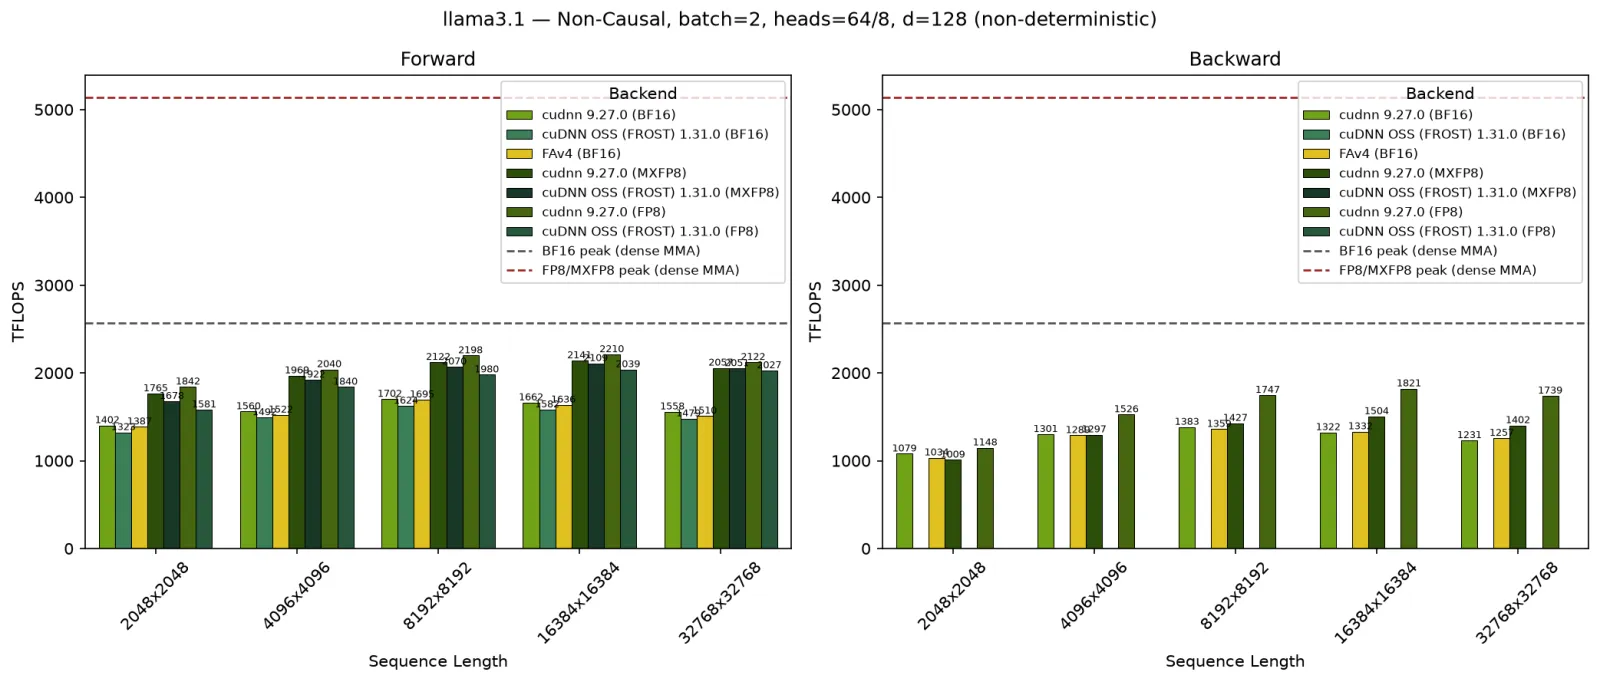
- SDPA parameters:
batch=1; num_q_heads=64; num_kv_heads=8; head_dim=128; is_causal=False - Sequence lengths shown on x-axis
- Results obtained on NVIDIA GB200 GPU
GB200 - DeepSeek V3 Causal (top_left)
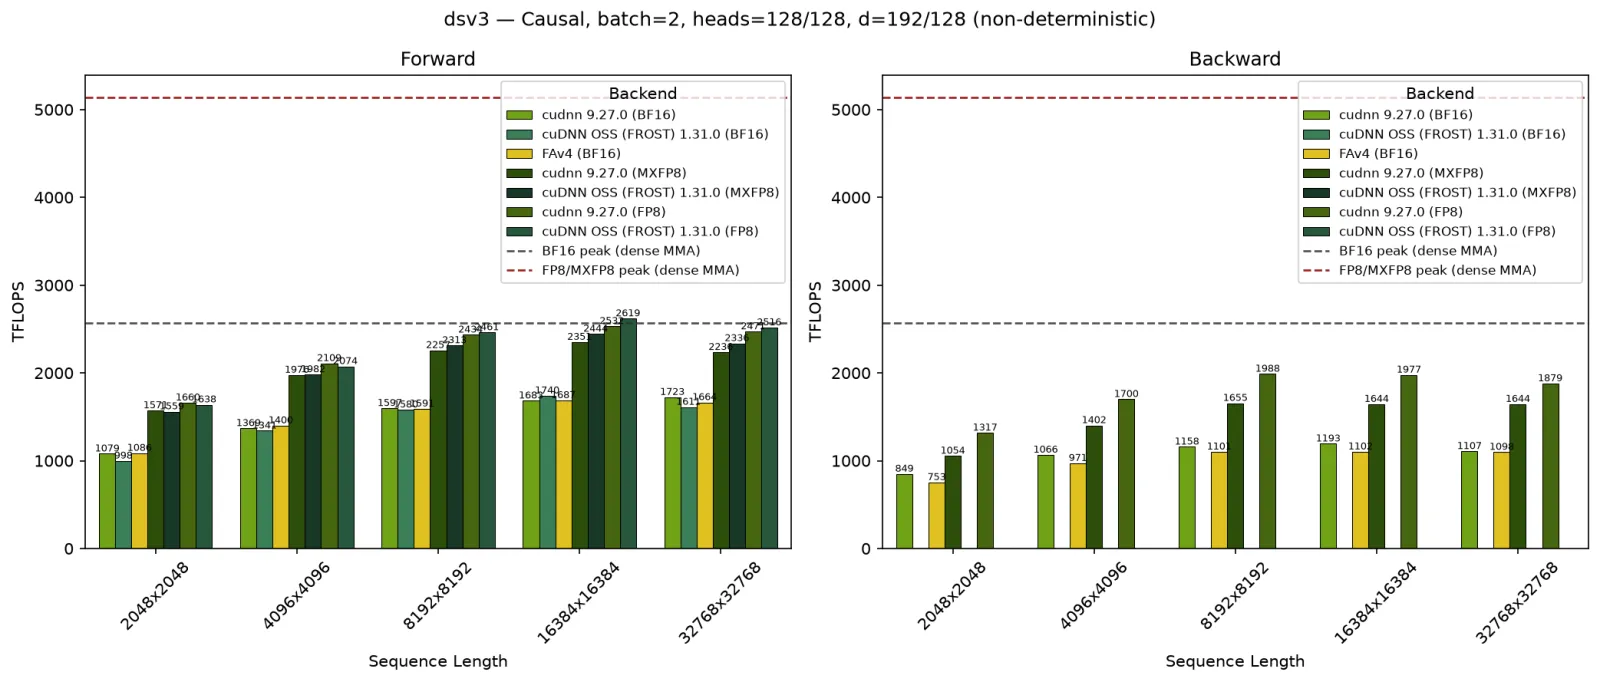
- SDPA parameters:
batch=1; num_q_heads=128; num_kv_heads=128; head_dim_qk=192; head_dim_vo=128; is_causal=True - Sequence lengths shown on x-axis
- Results obtained on NVIDIA GB200 GPU
GB300 - Llama 3.1 Causal (top_left)
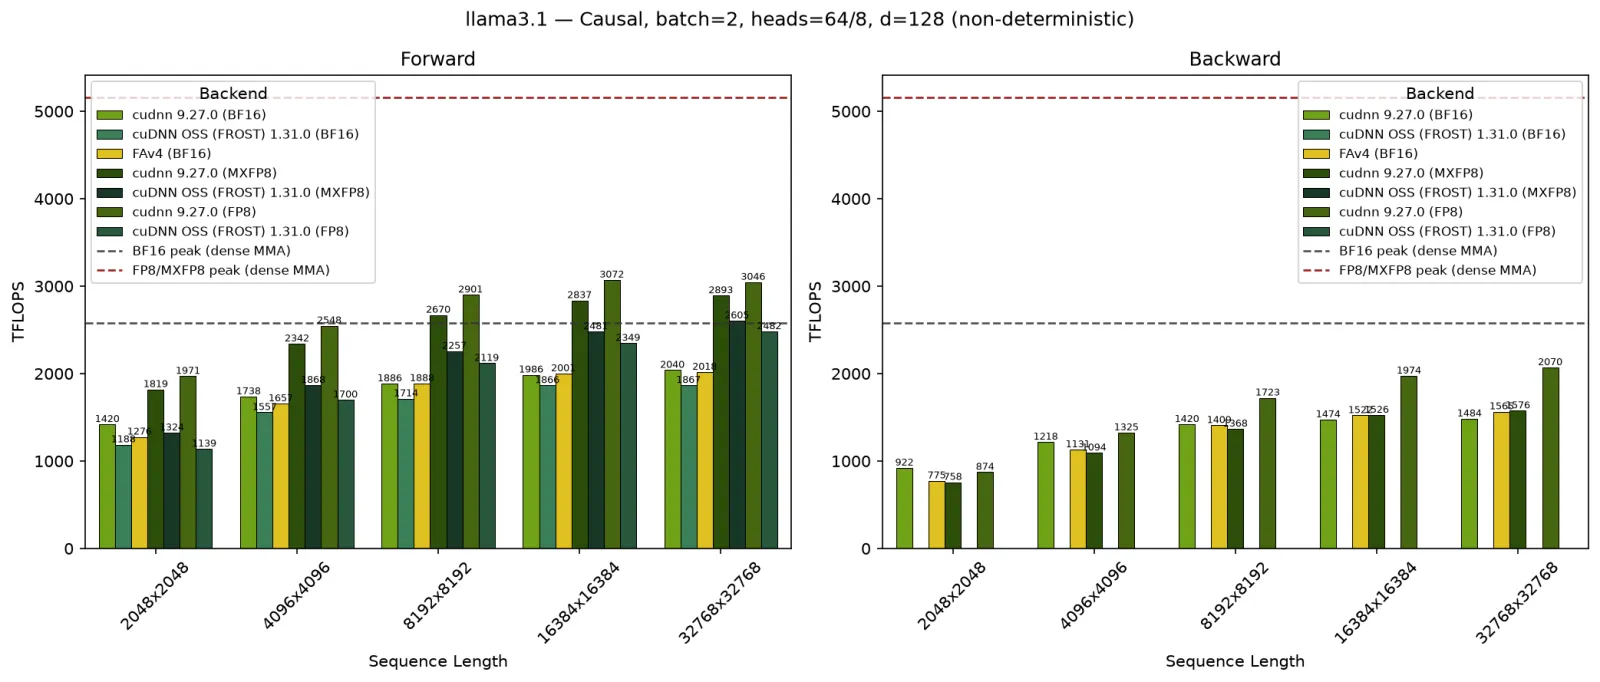
- SDPA parameters:
batch=1; num_q_heads=64; num_kv_heads=8; head_dim=128; is_causal=True - Sequence lengths shown on x-axis
- Results obtained on NVIDIA GB300 GPU
GB300 - Llama 3.1 Non-Causal (no_mask)
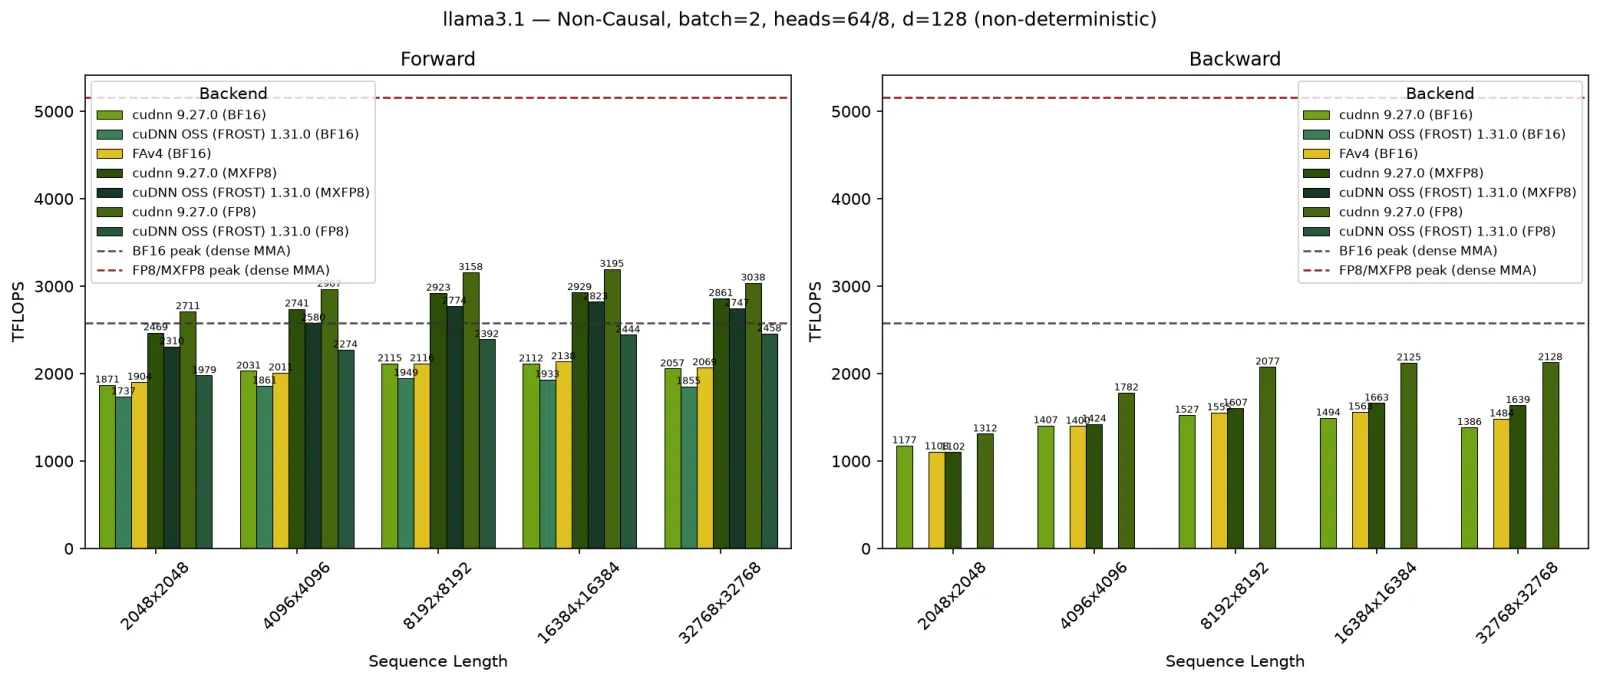
- SDPA parameters:
batch=1; num_q_heads=64; num_kv_heads=8; head_dim=128; is_causal=False - Sequence lengths shown on x-axis
- Results obtained on NVIDIA GB300 GPU
GB300 - DeepSeek V3 Causal (top_left)
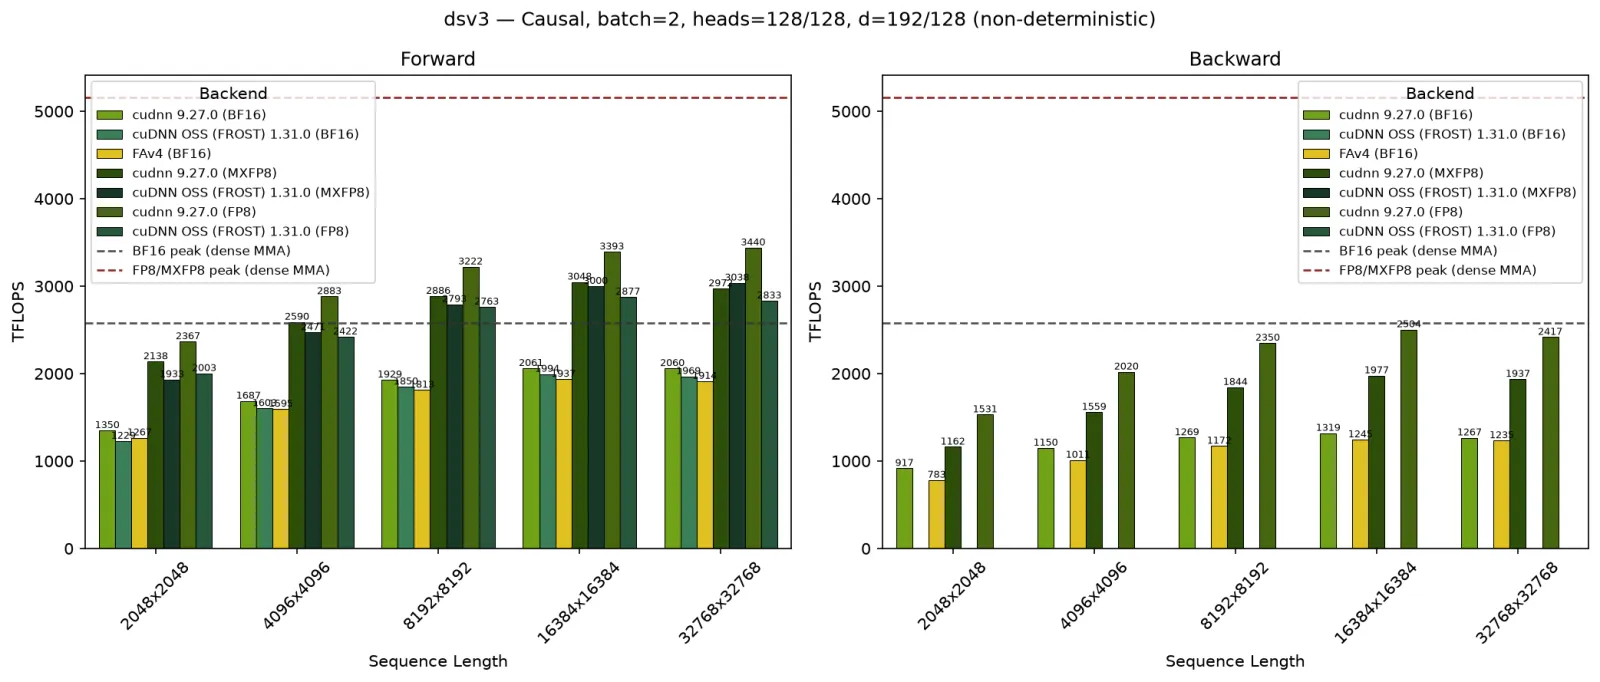
- SDPA parameters:
batch=1; num_q_heads=128; num_kv_heads=128; head_dim_qk=192; head_dim_vo=128; is_causal=True - Sequence lengths shown on x-axis
- Results obtained on NVIDIA GB300 GPU
API
SDPA FP16/BF16 Forward
C++ API
The options parameter of type SDPA_attributes is used to control the attributes of the forward operation, as detailed below:
Python API
Args:
q(cudnn_tensor): The query data with shape .k(cudnn_tensor): The key data. Whenpaged_attention_k_tableis provided, this is a container of non-contiguous key blocks.v(cudnn_tensor): The value data. Whenpaged_attention_v_tableis provided, this is a container of non-contiguous value blocks.attn_scale(Optional[Union[float, cudnn_tensor]]): Scale factor for attention scores. Typically . Default is None, which lowers to no scaling (1.0).bias(Optional[cudnn_tensor]): Additive bias mask for attention scores. Supports broadcasting.sink_token(Optional[cudnn_tensor]): Per-head attention-sink logit, fp32 with shape and broadcast over batch and query rows. It contributes one extra column to the softmax denominator: , sostats,score_maxandscore_sum_expinclude the sink column (the sink logit participates in the max). For training, pass the same tensor assdpa_backward’ssink_token, and adSink_tokentensor of the same shape to receive the sink gradient.block_mask(Optional[cudnn_tensor]): Block-level mask for 128x128 tiles. Only supported with UNIFIED implementation. On SM10x, the native backend requires cuDNN 9.26.0 or newer: older kernels can return NaNs when the first KV tile is masked out. This restriction is checked during native validation/planning; ordinary attention and FROST admission are unaffected. Because mask contents may change between executions, the requirement applies to every graph with a block-mask tensor, including one initially containing an all-visible mask.use_alibi_mask(Optional[bool]): Enable ALiBi (Attention with Linear Biases) positional encoding. Requiresdiagonal_band_right_bound=0.use_padding_mask(Optional[bool]): Enable variable sequence length masking. Must also provide a Q-side and a KV-side length tensor, each in per-batch (seq_len_q/seq_len_kv) or cumulative (cu_seq_len_q/cu_seq_len_kv) form.seq_len_q(Optional[cudnn_tensor]): Per-batch query sequence lengths with shape .seq_len_kv(Optional[cudnn_tensor]): Per-batch key/value sequence lengths with shape .cu_seq_len_q(Optional[cudnn_tensor]): Cumulative query sequence lengths (prefix sums with a leading 0) with shape or 1-D (promoted automatically), int32 or int64. Mutually exclusive withseq_len_q(a side cannot use both forms); a KV-side length tensor (seq_len_kvorcu_seq_len_kv) must also be provided, anduse_padding_mask=Trueis required. The two sides may use different forms (e.g.cu_seq_len_qwithseq_len_kv), which requires cuDNN 9.25+. Supplyingcu_seq_len_qrequires cuDNN 9.24+ and the UNIFIED implementation.cu_seq_len_kv(Optional[cudnn_tensor]): Cumulative key/value sequence lengths; same shape, type, and constraints ascu_seq_len_q.diagonal_alignment(Optional[cudnn.diagonal_alignment]): Alignment for diagonal masking.TOP_LEFTfor standard causal,BOTTOM_RIGHTfor prefix-LM style. It only composes with the diagonal-band bounds (diagonal_band_left_bound/diagonal_band_right_bound);use_causal_maskalways applies a top-left mask and ignores this alignment. For a bottom-right causal mask useuse_causal_mask_bottom_right.diagonal_band_left_bound(Optional[int]): Left bound for sliding window attention. Masks columns at or beforerow_idx - left_bound.diagonal_band_right_bound(Optional[int]): Right bound for causal masking. Set to 0 for causal mask. Masks columns beyondrow_idx + right_bound.dropout(Optional[tuple]): Dropout configuration. Either(probability, seed, offset)for Philox RNG or(mask, scale)for custom mask.rng_dump(Optional[cudnn_tensor]): Debug tensor with shape and fp32 data that captures the Philox dropout mask. Its entries are the binary keep mask (0.0 or 1.0); the graph multiplies kept probabilities by before , so applying the mask to the softmax probabilities needs that same scale to reproduceo.score_max(Optional[cudnn_tensor]): Side output, fp32 : per query row the maximum of the (scaled) attention scores the softmax normalizes against, in natural units; with an attention sink the sink logit counts as one more column. See Score side outputs.score_sum_exp(Optional[cudnn_tensor]): Side output, fp32 : per query row , the fp32 sum of exponentials normalized byscore_max(the softmax denominator).statsscore_maxscore_sum_exp.paged_attention_k_table(Optional[cudnn_tensor]): Page table with block offsets into the K container. It is int32 with shape(B, 1, ceil(S_kv / page_size), 1);page_sizeis the third dimension of the K container, which is laid out[num_pages, H_kv, page_size, D].paged_attention_v_table(Optional[cudnn_tensor]): Page table with block offsets into the V container. Same shape and dtype aspaged_attention_k_table; the V container follows the K container’s layout.paged_attention_max_seq_len_kv(Optional[int]): Logical maximum KV sequence lengthS_kv, used as given. It need not be a multiple ofpage_size: it is bounded by the capacity the page table addresses (table entries per request timespage_size), so a 61-token maximum withpage_size=16uses four table entries and stays 61. Abiasorrng_dumpmust use this length as its last dimension. When it is omitted and both caches are paged, it is taken frombiasorrng_dumpif present, and otherwise inferred as that page capacity. Recommended when using paged attention.generate_stats(Optional[bool]): If True, output softmax statistics for backward pass. Required for training.stats_use_log2(Optional[bool]): If True,statsis returned in base 2, , instead of the default natural-log form . This is the convention of flash-attention-style kernels (FA2/FA3, TRT-LLM) that fold into the softmax scale, so consumers that mix LSE tensors from several backends (cascade/split-KV merges, speculative decoding) get one convention without an extra elementwise pass. Only affectsstats;score_maxandscore_sum_expare unchanged, andsdpa_backwardstill expects natural-log stats. Served by the FROST SDPA engines and, on cuDNN 9.27.0+, by both theUNIFIEDandCOMPOSITEimplementations (CUDNN_ATTR_OPERATION_SOFTMAX_STATS_LOG2on the softmax operation descriptor used by both implementations); on older backends both decline it at validation, so only a FROST engine can serve it there.implementation(Optional[cudnn.attention_implementation]): SDPA implementation to use.AUTO(default),COMPOSITE, orUNIFIED.unfuse_fma(Optional[bool]): Use unfused mul/add in the softmax computation.softmax_precision(Optional[cudnn.data_type]): Precision of the softmax exponent and probability path.None(the default) is the f32 pipeline every engine runs and leaves the engine choice open.HALFasks for the f16x2 exponent arm of the FROST FP8 and MXFP8 forward engines on cc 10.7 (head-dim flavors 128, 192x128, 256 and 512): the exponent runs on packed f16 pairs and P is cast from f16 straight to the FP8 pair format, halving the transcendental work of the softmax warps. Numerics-changing (P moves by about one f16 ulp of the exponent), so it is an op attribute rather than a tuning knob: the cuDNN backend has no field for it, a set value keeps the graph on the python engines (serialize()andkey()refuse it), and an engine without the arm declines instead of degrading. An explicitFLOATis also a set value: it selects the f32 pipeline on the python engines only, so omit the attribute unless that is intended.stats, when requested, always come from the exact f32 row sum; on the d256 and d512 FP8 / MXFP8 kernels (which normalize O with a register row sum) a HALF forward withoutstatsnormalizes O with an f16 pair sum of the stored probabilities instead, so on those flavors O under HALF is not bit-identical with and withoutgenerate_stats(both within the family bound; d128, d192x128 and the FLOAT pipeline are unaffected). Forward only:sdpa_backwarddeclines it. The f16 arm rounds the exponent argument to f16 before the FP8 cast of P, so a probability within one f16 rounding step of an FP8 code midpoint can land one code away from the f32 pipeline’s (one E5M2 code is a 25 % step, one E4M3 code 12.5 %); on O that is at most one code step of that key’s weight times its V — rare, bounded, and budgeted by the FP8 test harnesses like the f32 pipeline’s own midpoint flips.attn_scale_prefolded(Optional[bool]): Declares that Q was already multiplied byattn_scale * log2(e)(before quantization for FP8 / MXFP8 inputs), so the engine applies no softmax scale;attn_scalemust stay unset. Served by the FROST MXFP8 and f16/bf16 forward engines on cc 10.7 (head-dim flavors 128, 192x128, 256 and 512; not over paged KV; not on per-tensor FP8, whose kernels fold the descale factors into the softmax scale).statskeep their usual form. On a graph withoutstats,attn_scale_prefolded=Truetogether withsoftmax_precision=HALFfuses the per-score shift and the f32-to-f16 convert into one instruction per pair (measured 6-7 % faster on the d128 MXFP8 kernel at 32k context).False(or0) is the default and counts as unset. Forward only:sdpa_backwarddeclines it.causal_exclude_own_block(Optional[int],sdpa_mxfp8only;Noneor0= plain causal): Tightens the causal mask so that queryireads only keysj < B * floor(i / B), i.e. it also drops the query’s own aligned block ofBkeys; rows0 .. B-1read no key (O = 0,stats = -inf). WithB = 32, the MXFP8 V scale block, every columnwise V scale the kernel reads covers fully visible tokens only, so no later token can change how an earlier visible value is rounded (TransformerEngine#3248). This is the completed-block half of causal MXFP8 attention whose P·V stays MXFP8: the caller computes the query’s own block separately (for example with token-local V scales) and merges the two partials through theirstats. Requires a causal mask (use_causal_mask=Trueordiagonal_band_right_bound=0, top-left or square bottom-right) without a sliding window. Served by the FROST SM100 MXFP8 forward engine on cc 10.0 / 10.3 atB = 32and D = 128, dense, unpadded and unpaged, including its split-KV and PackGQA plans; a top-left graph withS_q > S_kvandS_kvnot a multiple of 128 declines it, as does every other engine. That engine is otherwise opt-in (CUDNN_FRONTEND_ENABLE_FROST_ENGINES=1), but a graph that sets this attribute is offered it without the flag, since nothing else can serve the graph. Numerics-changing, so it is an op attribute: the cuDNN backend has no field for it and a set value keeps the graph on the python engines. Forward only:sdpa_mxfp8_backwarddeclines it.compute_data_type(Optional[cudnn.data_type]): Data type for internal computation.name(Optional[str]): Name for the operation.
Returns:
o(cudnn_tensor): The output attention data with shape .stats(Optional[cudnn_tensor]): Softmax statistics with shape whengenerate_stats=True. Natural log by default (); base 2 whenstats_use_log2=True.
Configurable Options
-
Attention scale (
attn_scale): Applies a scaling factor to attention scores before the softmax, such as . Default is None, which lowers to no scaling (1.0). Can be passed as a float or as a tensor. -
Bias mask: Applies an additive bias mask to attention scores. You must pass a bias tensor as specified in the tensors section below. The dimensions that are passed as 1 will apply a broadcasted mask over attention scores.
-
Block mask: Masks out tiles of attention scores at a 128x128 block granularity. The block mask is a uint8 tensor where each bit represents whether a 128x128 tile should be computed (1) or masked out (0). This is supported with the UNIFIED implementation.
-
ALiBi mask: Attention with Linear Biases (ALiBi) is an additive mask applied to the attention scores as described in the paper Train Short, Test Long: Attention with Linear Biases Enables Input Length Extrapolation. When using ALiBi,
diagonal_band_right_boundmust be set to exactly 0 (causal masking). -
Padding mask (Variable Sequence Length): Masks out padded time steps to ignore them in computation. You must pass per-batch sequence length tensors as specified in the tensors section below. In padded or ragged layout (discussed below) where the actual seqlen can be less than the max seqlens of a graph, certain batches can be skipped by setting the actual seqlen of the corresponding batch to 0.
-
Diagonal masking options: These options control causal and sliding window masking:
-
Diagonal Alignment (
diagonal_alignment): Specifies where the diagonal starts. Options are:TOP_LEFT: The diagonal starts at the top-left of the attention matrix. Used for standard causal masking.BOTTOM_RIGHT: The diagonal starts at the bottom-right of the attention matrix, aligned with the actual sequence length. Useful for prefix-LM or when .
-
Diagonal Band Right Bound (
diagonal_band_right_bound): Specifies that attention scores beyond columnrow_idx + right_boundare masked with negative infinity. Setting this to 0 enables causal masking. -
Diagonal Band Left Bound (
diagonal_band_left_bound): Specifies that attention scores at or before columnrow_idx - left_boundare masked with negative infinity. This enables sliding window attention. Note that0is not “no left bound”: it masks every key at or before the diagonal, so withdiagonal_band_right_bound=0every key is masked and the rows follow the empty-row convention (O = 0, see thekv_masksection). Omit the attribute to disable left masking. -
Common masking patterns:
- Causal mask (top-left):
diagonal_alignment=TOP_LEFT,right_bound=0 - Causal mask (bottom-right):
diagonal_alignment=BOTTOM_RIGHT,right_bound=0 - Sliding window: Set
left_boundto window size - Band attention: Set both
left_boundandright_bound
- Causal mask (top-left):
-
Paged attention: Enables non-contiguous K/V caches to reduce memory fragmentation. See the PagedAttention paper.
- Requirements:
- Pass the
paged_attention_k_tabletensor with block offsets into the K container (optional if K is not paged) - Pass the
paged_attention_v_tabletensor with block offsets into the V container (optional if V is not paged) - Enable
use_padding_mask=Trueand pass sequence length tensors (seq_len_q,seq_len_kv, or thecu_seq_len_*forms) for both sides; paged caches are declined without them - Optionally pass
paged_attention_max_seq_len_kvfor the maximum KV sequence length (recommended)
- Pass the
- FROST engines (opt-in, f16/bf16): paged decode and MTP graphs run a dedicated decode tile instead of the prefill pipeline. On the SM100 line:
S_q * pack_g <= 128on the d128 flavor (pack_g= the packed head group for a PackGQA plan —H_q/H_kv, or its largest divisor of 128 — and 1 otherwise;TILE_CGA_M=1). On cc 10.7 (Rubin): the d256 flavor’s swap-AB decode tile over a dense or a paged cache — PackGQA packs the whole group into the tile’s Q rows (24/2 = 12 rows), the KV range splits (dense or paged) through the shared combine, which also applies the fused epilogue gate when the plan splits, and an MTP step rides it in token units (S_q * G <= 16packed rows in one unit of the 16-column tile, rows in (16, 32] on the 32-column tile, a packed group in up to two token units). Other shapes run the prefill pipeline. Seepython/cudnn/sdpa/frost/SUPPORT_MATRIX_TRACKER.md. On cc 10.7 (SM107) the f16/bf16 row serves paged KV for packed (THD / ragged-Q) queries on the d128 and d256 flavors, with or withoutsink_token— prefill- and decode-shaped packed batches (per-request Q of 1 / 4 / 8), GQA with PackGQA, HND and NHD pools — through the paged prefill pipeline; dense (BSHD) paged queries are declined there except the decode-shaped d256 graphs the decode tile serves (above), and a sink graph is never split on any row. - MXFP8 page pools (
sdpa_mxfp8withpaged_attention_*): the descales are page pools too (descale_k [num_pages, H_kv, page_size, ceil4(D/32)],descale_v [num_pages, H_kv, page_size/32, D], F8_128x4, sopage_sizeis a multiple of 128; for D > 128 thedescale_vplanes are D-plane-major across the whole pool); the cuDNN backend has no engine for them — the FROST MXFP8 engines serve them on the SM100 line (every native flavor, dense queries) and on cc 10.7 (d128 / d256, dense queries, sinks compose); THD (ragged-Q) queries over MXFP8 pools decline on every arch today. Seepython/cudnn/sdpa/frost/SUPPORT_MATRIX_TRACKER.md. - FROST engines (cc 10.7, f16/bf16): dense d128 graphs whose
S_q * pack_g <= 128ride the same decode tile (TILE_CGA_M=1, the shared body compiled for sm_107a; issue #1472) and dense d128 GQA packs on the shared prefill body under a diagonal band (a mask-free graph whose rows fit the decode tile unpacked rides it unpacked); paged THD queries keep the prefill pipeline there. Withsink_token, dense d128 decode / verify graphs inside the measured band (bottom-right causalS_q <= 16or mask-freeS_q == 1, GQA 4 / 8 / 16, at least 32 (batch, KV-head) units, caches 1k-16k, no window) are served by these plans by default, without the opt-in flag. Paged THD queries with GQA 4 / 8 / 16 pack by default there, with or withoutsink_token, and a sink no longer changes the scheduling or tile-width choice of a paged THD plan. Seepython/cudnn/sdpa/frost/SUPPORT_MATRIX_TRACKER.md. - Offset calculation:
- Packed page tables: Page tables can also use ragged offsets to pack only the necessary block indices, useful for frameworks that prefer packed representations.
- Requirements:
-
Implementation: Select the underlying SDPA implementation:
AUTO(default): Auto-selects the best implementation. Recommended for most users.COMPOSITE: Standard cuDNN graph representing SDPA as distinct operations.UNIFIED: Optimized fused SDPA operation (cuDNN 9.13.1+). Supports a subset of features including block masking.
-
Unfuse FMA (
unfuse_fma): Uses unfused mul/add in the softmax computation. -
Generate stats (
generate_stats): WhenTrue, outputs softmax statistics needed for backward pass during training. Set toTruefor training,Falsefor inference. -
Stats in base 2 (
stats_use_log2): Returnsstatsas rather than the natural-log default. The value is exactly the natural-log stats times , so it is a convention switch, not a different quantity; the backward pass is unaffected and continues to take natural-log stats.
Per-key mask (kv_mask, python engines only)
kv_mask is an optional input tensor of shape (one entry per key, contiguous along ; a
batch extent of 1 broadcasts one row over the batch) in one of two forms:
- BOOLEAN (the bit-word form): a key whose entry is
Falseis excluded from every query’s softmax, exactly like a key at or pastseq_len_kv. A query whose every key is masked follows this frontend’s empty-row convention (O = 0,stats = −inf), not the uniform average an eager finite−1e9bias produces — see the conventions paragraph below. - An additive vector in the Q/K/V dtype or FLOAT: its values are added to the scaled scores of every query row
(
s·scale + v, the eager models’ finite−1e9fold applied as a VALUE), so a key at−1e9contributesexp(−1e9) = 0while a row whose every key is−1e9is the uniform average of V, exactly as in eager math; a−infentry reproduces the BOOLEAN form. The vector is read as 16-byte granules: must be a multiple of 8 and a batch stride a 16-byte multiple (a 16-bit vector must be the Q/K/V dtype; cast an fp16 vector for a bf16 graph). An fp32 vector together with the additivebiasruns the 64-wide KV tile only: the heuristics pickTILE_N = 64for that pair (its 128-wide rendering spills on the softmax role), an explicitTILE_N = 128request is declined typed rather than degraded, and casting the fp32 mask to the Q/K/V dtype is the fast path.
Both forms compose with the padding mask, every diagonal band (bottom-right causal included) and the additive bias (the
graph contract does not admit bottom-right causal together with bias). The cuDNN backend has no field for kv_mask, so a
graph that binds it is served by the python engines that fold it (today the SM107 f16/bf16 32- and 64-wide tiles at any
— neither form stages anything in shared memory; the same tiles take the additive bias as a resident SMEM block up
to the sequence lengths listed in the support matrix, and the heuristics then pick the narrowest cluster width whose block
holds the sequence); binding it on any other configuration makes the graph unsupported rather than silently unmasked.
Score side outputs (score_max, score_sum_exp)
The two optional ports expose the operands the softmax statistics are built from, per query row and in natural units:
score_max over the row’s unmasked (scaled, biased) scores and score_sum_exp as the
fp32 sum of exponentials, so stats score_max score_sum_exp to fp32 rounding. score_max is the raw row
maximum of the scaled scores themselves (the value a reference computes as scores.amax(-1)), not the -scaled
maximum a flash-attention-style kernel carries internally, so it compares directly with a reference’s row maximum. With an attention sink the
sink logit is one more softmax column: it enters the max and contributes to the sum. stats_use_log2
scales stats alone; the two side outputs keep their natural units. Both tensors are fp32 in any
non-overlapping B/H/S stride order, and either may be requested without the other and without generate_stats.
Rows without a single valid key — a batch with seq_len_kv = 0, a bottom-right row above the diagonal, a query row at or
past seq_len_q — follow the same convention as O and stats on this frontend’s engines (O = 0, stats = −inf):
score_max = −inf and score_sum_exp = 0; with a sink the row holds the sink’s mass alone, score_max = sink_logit,
score_sum_exp = 1 (stats = sink_logit). Two other conventions are in circulation and matter when results are compared
across libraries: some kernels zero such rows (o = lse = max = 0) when the mask is given as per-row key lengths, while a
dense finite mask value leaves them un-zeroed (lse = max = −1e9, o = the uniform average of V); eager PyTorch with a finite
additive mask likewise returns the uniform average. Compare rows that have at least one key, and assert the degenerate rows against the convention of the implementation
under test.
Under CUDNN_FRONTEND_ENABLE_FROST_ENGINES=1 the FROST f16/bf16 forward engines serve both ports on their d128 prefill flavor
(SM100 / SM103 and SM107: dense, unsplit, unpaged plans of the 2-CTA tile; the outputs are stored by the kernel’s epilogue
next to stats, with O bitwise unchanged and stats within one fp32 rounding of the plan without them), and decline every
other selection so the cuDNN backend serves it. Unlike the backend’s composite softmax, which outputs stats alone or the
pair alone, these engines serve any combination of the three. See
python/cudnn/sdpa/frost/SUPPORT_MATRIX_TRACKER.md.
Limitations
- Head dimension must be a multiple of 8.
- Q, K, V and O (and dO, dQ, dK, dV in backward) must meet the tensor’s declared alignment, 16 bytes by default. If a non-unit stride is not a whole number of alignments in bytes, the native lowering declines the graph. If a device pointer is misaligned,
executerefuses it before launching. Without these checks, the native kernels returned wrong output on SM90/SM100 and faulted on SM80/SM89 (#1571). - ALiBi requires causal masking (
diagonal_band_right_bound=0). - Block masking is only supported with the UNIFIED implementation.
- Ampere/Ada architectures are limited to head dimensions up to 256 for prefill, 128 for decode and backward. On SM89 (Ada), the FROST
sdpa_bwd_sm89engine serves FP16/BF16 backward up to head dimension 256 when the backend declines the graph.
Fused epilogue gate (FROST, SM107)
A gated attention tail — the SDPA output multiplied by the sigmoid of a per-element gate tensor G of O’s shape,
O_gated = O * sigmoid(G) — is built as three graph nodes, an sdpa (or sdpa_fp8 / sdpa_mxfp8) node followed by
sigmoid and mul pointwise nodes on O. The Rubin d256 FROST forward engines serve the whole tail fused when they
serve the graph: the MXFP8 row (sdpa_fwd_prefill_sm107_mxfp8) is offered by default and leads on cc 10.7, so the fused
tail is its default execution; the half row (sdpa_fwd_prefill_sm107) is offered by default but its placement keeps the
backend first for dense d256 graphs, which then run the tail unfused as the three nodes — it serves the tail fused when it
leads the plan list, when the backend declines, or under CUDNN_FRONTEND_ENABLE_FROST_ENGINES=1; the FP8 row
(sdpa_fwd_prefill_sm107_fp8) serves it under that flag. On the fused path the gate tile is TMA-staged by the kernel’s load
warp and applied in the epilogue after the
dead-row select, so the gated O (and the quantized O on the FP8 / MXFP8 rows) is written once. Served today at
d_qk = d_v = 256 with a bf16 G, dense / unsplit / non-PackGQA / non-paged layouts; any other combination
falls back to the unfused three-node execution — with one exception on the f16/bf16 engine: a decode-shaped
graph (S_q times the packed GQA group within the decode tile’s routed rows: 16 in one unit of the 16-column
tile, (16, 32] on the 32-column tile, a packed group in up to two token units) whose plan splits the KV range
runs on the d256 decode tile, and there the gate is applied by the split combine on the fp32 merged value
before the single cast (the
same h * tanh(g / 2) + h arithmetic as the fused epilogue: one rounding, so the split and the unsplit gated
plans differ only by the attention’s summation order), over a dense or a paged cache, packed or not — not when the graph enables
execute-time shape overrides (the combine binds G to the declared shape; such a graph keeps the unsplit fused kernel). Two
contracts hold on the fused path: Stats (LSE) is
independent of G, and Amax_O — an output of the sdpa node, which precedes the gate on the graph — is the
amax of the un-gated normalised O (in scale_o units on FP8, unscaled on MXFP8), while the stored O is
the gated value. The per-engine claims are tracked in
python/cudnn/sdpa/frost/SUPPORT_MATRIX_TRACKER.md.
The same fusion is reachable without the graph API through the
gated attention block (fuse_gate=True).
Tensors
Input Tensors
Output Tensors
Where:
- is the batch size
- is the number of query heads
- is the number of key heads
- is the number of value heads
- is the sequence length of the query
- is the sequence length of the key and value
- is the embedding dimension per head of query and key
- is the embedding dimension per head of value
- is the (power of 2) block size of the K container
- is the (power of 2) block size of the V container
- is the number of blocks in the K container
- is the number of blocks in the V container
Samples and Tests
-
Python forward sample: samples/python/50_sdpa_forward.ipynb
-
Python backward sample: samples/python/51_sdpa_backward.ipynb
-
Python prefill sample with paged caches: samples/python/52_sdpa_with_paged_caches.ipynb
-
Python decode sample with packed paged caches: samples/python/53_sdpa_decode_with_paged_caches.ipynb
-
C++ sample: samples/cpp/sdpa
-
Python tests (v2 with randomized configurations): test/python/sdpa/graph/test_mhas_v2.py
Example Usage:
SDPA FP16/BF16 Backward
This operation computes gradient tensors for scaled dot product attention (SDPA) using the FlashAttention-2 algorithm as described in the paper FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning. You are required to pass the stats tensor from the forward operation to the backward operation as input.
C++ API
The options parameter of type SDPA_backward_attributes is used to control the attributes of backward operation, as detailed below:
Python API
Args:
q(cudnn_tensor): The query data from the forward pass.k(cudnn_tensor): The key data from the forward pass.v(cudnn_tensor): The value data from the forward pass.o(cudnn_tensor): The output data from the forward pass.dO(cudnn_tensor): The gradient of the loss with respect to the output.stats(cudnn_tensor): The softmax statistics tensor from the forward pass (generate_stats=True), in its natural-log form.sdpa_backwardhas no log2 flag: if the forward pass usedstats_use_log2=True, rescale the tensor byln(2)first — a log2 tensor passed as-is produces wrong gradients without any error.attn_scale(Optional[Union[float, cudnn_tensor]]): The attention scale factor. Must match the forward pass.bias(Optional[cudnn_tensor]): The bias tensor from the forward pass.dBias(Optional[cudnn_tensor]): Output tensor to store the bias gradient.use_alibi_mask(Optional[bool]): Enable ALiBi. Must match the forward pass configuration.use_padding_mask(Optional[bool]): Enable variable sequence length masking. Must match forward pass.seq_len_q(Optional[cudnn_tensor]): Per-batch query sequence lengths.seq_len_kv(Optional[cudnn_tensor]): Per-batch key/value sequence lengths.max_total_seq_len_q(Optional[int]): Token-axis capacity bound for the ragged Q side, including gaps between sequences. Used for workspace allocation. The bound must cover the token positions addressed by Q, O, dO, Stats and dQ. Defaults toNone(no explicit packed-capacity bound).max_total_seq_len_kv(Optional[int]): Token-axis capacity bound for the ragged K/V side, including gaps between sequences. Used for workspace allocation. The bound must cover the token positions addressed by K, V, dK and dV. Defaults toNone(no explicit packed-capacity bound).diagonal_alignment(Optional[cudnn.diagonal_alignment]): Must match the forward pass.diagonal_band_left_bound(Optional[int]): Must match the forward pass.diagonal_band_right_bound(Optional[int]): Must match the forward pass.dropout(Optional[tuple]): Dropout configuration. Must match the forward pass to ensure the same dropout mask is applied.use_deterministic_algorithm(Optional[bool]): If True, forces deterministic gradient computation. This ensures bitwise-identical results across multiple runs but may be slower. Default is False.compute_data_type(Optional[cudnn.data_type]): Data type for internal computation.name(Optional[str]): Name for the operation.
Returns:
dQ(cudnn_tensor): The gradient with respect to the query tensor.dK(cudnn_tensor): The gradient with respect to the key tensor.dV(cudnn_tensor): The gradient with respect to the value tensor.
Important Notes:
-
The backward operation does NOT support paged attention. K and V must be contiguous tensors.
-
All masking and dropout configurations must exactly match the forward pass to ensure correct gradients.
-
Omitting a bound is not equivalent to explicitly passing or . With no bound, the native backward path uses padded intermediate workspace layouts instead of copying ragged offsets into those intermediates. Behavior depends on the engine and backend: the native path discards explicit bounds on cuDNN older than 9.6.0, when a head dimension is not a multiple of 16, and on SM8x/SM12x GPUs with cuDNN 9.18.1 or newer, falling back to padded layouts; some FROST THD backward engines reject graphs that do not declare both totals. Where a bound is kept, it enables packed intermediate layouts and must cover their addressed span.
-
When setting
max_total_seq_len_qandmax_total_seq_len_kv, use an upper bound on the physical token span, including gaps and any nonzero starting offset. For a fully packed buffer starting at token zero, the sum of sequence lengths suffices. For a partially packed buffer, use at leastmax(start_token[b] + seq_len[b])over all sequences and all tensors on the corresponding side; convert ragged element offsets to token positions using each tensor’s layout first. -
For example, two 128-token sequences beginning at token positions 0 and 256 need a bound of at least 384, although their lengths sum to 256. Passing 256 can under-allocate intermediate workspace and corrupt gradients or memory. The frontend cannot infer this span while building a graph because ragged offsets reside in device memory.
-
Python sample: samples/python/51_sdpa_backward.ipynb
-
C++ sample: samples/cpp/sdpa
-
Python tests (v2 with randomized configurations): test/python/sdpa/graph/test_mhas_v2.py
Tensors
Input Tensors
Output Tensors
Example Usage:
Block Sparse Attention FE OSS API
The experimental Block Sparse Attention API provides CuTe DSL forward and explicit backward kernels driven by per-query-block lists of selected key/value blocks. It is a standalone Python FE OSS API and is separate from the cuDNN Graph API described above.
HSTU Attention FE OSS API (SM100/SM103)
The experimental HSTU Attention API
provides packed-variable-length forward and backward CuTe DSL kernels for
Blackwell SM100/SM103 GPUs. HSTU applies SiLU to scaled QK scores without
softmax, supports its specialized mask modes, and exposes the sequence
normalization factor separately as scaling_seqlen. FP16 and BF16 arbitrary-mask
forward and backward automatically build private block metadata on the active
CUDA stream without adding public API parameters; D256 backward builds both
Q-to-K and K-to-Q views from one coarse classification.
Gated Attention Block FE OSS API (SM107)
The experimental Gated Attention Block API is a model-level FE OSS
API for NVIDIA Rubin (SM107): the QKV+gate projection, QK-RMSNorm (optional) with partial RoPE, GQA SDPA,
sigmoid gate and out projection of a Qwen3.5-style gated attention sub-layer behind one class, one workspace
and one execute(), every stage a FROST kernel; on a QsaSpec geometry the in-block indexer serves its decode and extend steps
over the paged side caches. It runs bf16 / fp16, per-tensor FP8 and MXFP8 — the MXFP8
pipeline optionally with MXFP4 (e2m1 x E8M0) projection weights and with an NVFP4 or MXFP4 block-quantized output
feeding an fp4 x fp4 out projection — with two fusion knobs (fuse_norm_rope, fuse_gate) that take the block to
three launches (four with the fp4 output), plus a bf16 backward with a recompute policy. It is separate from the
cuDNN Graph API above; the fused epilogue gate it uses is also available as the graph pattern described under
“Fused epilogue gate”.
SDPA PyTorch Custom Ops (cudnn::sdpa_fwd / cudnn::sdpa_bwd)
PyTorch custom ops (torch.library) exposing the full cuDNN SDPA feature
surface — the features torch.nn.functional.scaled_dot_product_attention’s
aten contract cannot express:
- attention sinks — per-Q-head logits folded into the softmax denominator
- diagonal bands —
window_leftandwindow_right. The two bounds use different conventions, matchingdiagonal_band_left_bound/diagonal_band_right_bound:window_leftcounts visible tokens including self (so FA2’s(w, 0)maps towindow_left = w + 1), whilewindow_rightis the last visible column past the diagonal, with no offset (FA2’s(_, r)maps towindow_right = r).window_right=0is exactly causal;window_right > 0admits future columns and so cannot be combined withis_causal, which the op rejects rather than silently resolving. - bottom-right causal alignment — inference-style diagonals
- padded batches — per-batch actual lengths via
seq_len_q/seq_len_kv - THD / varlen packing — FlashAttention-style
(T, H, D)+cu_seqlens
The ops build cuDNN pygraph sdpa / sdpa_backward nodes; the engine Router
picks the best serving plan (FROST OSS kernels or cuDNN-backend engines) per
configuration. Graphs are cached per configuration (bounded, thread-safe;
cuDNN handles are thread-local).
Usage
Contracts and limits
- Dense tensors are BHSD
(B, H, S, D)(any strides; the graph declares the actual layout). Varlen tensors are packed(T, H, D); non-contiguous views (e.g. K/V slices of a fused(T, 2, H, D)KV projection) are declared with their true strides. On the varlen path, a non-dense innermost dim or a misaligned base pointer is repaired by one copy (warned as slow path); the dense path declares the given strides as-is. - One io dtype per call (
fp16orbf16); mixed-dtype inputs are rejected. sdpa_bwdserves the THD/varlen path. Dense backward and sink backward (dSink) are follow-ups and raiseNotImplementedError. It consumes a padded(B, H, max_seqlen_q, 1)fp32 LSE (backend restriction: bprop THD rejects ragged LSE on SM8X/SM12X).- Autograd (
register_autograd) requiresreturn_lse=Trueon the forward; the glue converts the packed TH1 stats to the padded layout device-side. - Both ops ship
register_fakemeta kernels.cudnn::sdpa_fwdpassestorch.library.opcheckon the dense and varlen paths, including dynamic-shape AOT dispatch (torch.compile-ready); the opcheck autograd case exercisescudnn::sdpa_bwdthrough the registered backward.
Requirements
nvidia-cudnn-frontend, cuDNN backend ≥ 9.6 (THD token-major stats), sm80+.
Tests: test/python/sdpa/torch/test_torch_ops.py.
SDPA FP8 Forward
This operation computes the scaled dot product attention (SDPA) in the 8-bit floating point (FP8) datatype, using the FlashAttention-2 algorithm as described in the paper FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning. It is applicable for both training and inference phases, with an option to generate a stats tensor to be used for backwards training computation.
The FP8 datatype consists of two encodings:
FP8_E4M3(1 sign bit, 4 exponent bits, and 3 mantissa bits)FP8_E5M2(1 sign bit, 5 exponent bits, 2 mantissa bits).
Due to the limited numerical precision of FP8 data type, for practical use cases, you must scale values computed in FP32 format before storing them in FP8 format, and descale the values stored in FP8 format before performing computations on them. For more information, refer to the Transformer Engine FP8 Primer.
The suggested value for the scaling factor is computed as: (Max representable value in the fp8 format) / (Max absolute value seen in the tensor for the previous layer).
- For E4M3, the suggested scaling factor is
448.f/ prev_layer_tensor_amax(rounded to the nearest lower power of two) - For E5M2, the suggested scaling factor is
57344.f/ prev_layer_tensor_amax(rounded to the nearest lower power of two)
The suggested value for the descale factor is the reciprocal of the scale factor.
Since scaling and descaling are critical for convergence with FP8 datatype, you are required to pass scaling and descaling input tensors, as well as amax output tensors.
C++ API
The options parameter of type SDPA_fp8_attributes is used to control the attributes of the forward operation, as detailed below:
Python API
Configurable Options
The current FP8 support is a subset of the options supported in FP16 and BF16 support.
- Attention scale (
attn_scale): Applies a scaling factor to attention scores before the softmax, such as . Default is None, which lowers to no scaling (1.0). - Causal mask: Fills the upper triangular matrix of attention scores with negative infinity.
- Padding mask (
use_padding_mask): Variable sequence lengths, provided either as per-batch lengths (seq_len_q/seq_len_kv) or as cumulative sequence lengths (cu_seq_len_q/cu_seq_len_kv; cuDNN 9.25+, UNIFIED implementation only).
Limitations
- Requires Hopper (SM90) or newer architecture.
- Head dimension must be a multiple of 16.
- Masking support is limited compared to FP16/BF16; FP8 supports causal, padding and bias masks.
- Requires explicit scale/descale tensors for all FP8 inputs and outputs.
Tensors
The tensors in forward operation are defined as the following:
Input Tensors
Output Tensors
Where:
- is the batch size
- is the number of query heads
- is the number of key heads
- is the number of value heads
- is the sequence length of the query
- is the sequence length of the key and value
- is the embedding dimension per head of query and key
- is the embedding dimension per head of value
Amax S (deprecated)
Amax_S is deprecated. Leave it virtual (do not call set_output(True) on it) and set scale_s from the bounds below: 448.f (the E4M3 maximum) without dropout, with dropout probability , and with a custom dropout mask and scale ( for a 0/1 mask and ; when or is all zero, kept entries are 0 and any finite scale_s, such as 448.f, is safe). Declaring it as an output restricts the graph to cuDNN backend engines, because the FROST engines do not produce it. On some shapes that costs about 2x: on Rubin, a d256 GQA causal FP8 prefill runs 1.7-2.3x slower on the backend than on the FROST FP8 row. FE logs a warning, once per process, when a graph declares it on a device where a FROST FP8 row would otherwise consider the graph.
A data-derived scale_s gains nothing over 448.f. Amax_S is the maximum of over the whole tensor, before scale_s. Without dropout, every entry of is at most 1, so deriving scale_s from the E4M3 maximum and an amax of 1 (448.f) never saturates , whatever the previous step’s value was. With dropout probability , the graph scales kept entries by before scale_s, so scale_s = is a conservative choice that keeps the same guarantee. A custom dropout mask with scale multiplies kept entries by , so keeps it. If, in addition, there is no sink_token and every row has at least one unmasked key, every row of sums to 1 and the value is at least ; for example, row 0 of a top-left causal mask (one key) gives exactly 1.
- E4M3 is a floating-point format, so a
scale_sabove448.f(from anAmax_Sbelow 1) does not change the relative precision of ; it only moves the underflow threshold lower. - A graph that declares
Amax_Sis declined by every FROST FP8 row, so it runs only if a cuDNN backend engine supports it; otherwise the graph has no supported plan (for example the FP8 decode cases in #1415). - On SM100, the backend currently reports a value below the true maximum when is short (#1613).
Samples and tests
- C++ sample: samples/cpp/sdpa
SDPA FP8 Backward
This operation computes the gradients for scaled dot product attention (SDPA) 8-bit floating point (FP8) datatype, using the FlashAttention-2 algorithm as described in the paper FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning. You are required to pass the stats tensor from the forward operation to the backward operation as input.
- C++ sample: samples/cpp/sdpa
C++ API
The options parameter of type SDPA_fp8_backward_attributes is used to control the attributes of the backward operation, as detailed below:
set_max_total_seq_len_q / set_max_total_seq_len_kv declare the packed token totals of a ragged (THD) layout, exactly as on SDPA_backward_attributes (see the glossary above); they are accepted only when the Q/K/V/O/dO/Stats or the gradients carry a ragged offset. The same two attributes serve the MXFP8 backward (sdpa_mxfp8_backward builds SDPA_fp8_backward_attributes too).
Python API
Limitations
- Requires Hopper (SM90) or newer architecture.
- Dropout is not supported in FP8 backward pass.
- Only causal masking is supported.
- Requires explicit scale/descale tensors for all FP8 inputs and outputs.
Tensors
The tensors in backward operation are defined as the following:
Input Tensors
Output Tensors
Where:
- is the batch size
- is the number of query heads
- is the number of key heads
- is the number of value heads
- is the sequence length of the query
- is the sequence length of the key and value
- is the embedding dimension per head of query and key
- is the embedding dimension per head of value
Execute-Time Shape Overrides
Unified SDPA forward distinguishes the shape a graph declares from the shape a run uses:
The declaration is the envelope the plan is built for, not a promise about any one run. One plan can then serve many extents without being rebuilt, which is what a serving stack wants when it groups requests into length buckets.
The example requires a frontend compiled against cuDNN >= 9.21 and a cuDNN
= 9.23 runtime for the workspace query with overrides. Its 64-row extent is from the measured plan below; validate other plans before using that window.
What an override does and does not do
- Buffers are sized for the declaration. An override says how much of a
declared buffer this run uses; it neither shrinks the allocation nor re-packs
the layout, and the strides describe the declared storage. Allocating only the
run’s extent leaves the kernel addressing past the buffer.
override_stridesthat differ from the declared strides are accepted but not used: the kernel reads and writes with the declared strides (#1570). - The plan is chosen at build time.
override_*does not re-run the heuristic and does not reselect an engine, so grouping lengths into buckets is the caller’s policy rather than something this feature does. Two graphs declared at different extents are two different plans. - It is not
set_dynamic_shape_enabled/ the kernel cache. That feature reuses compiled kernels across dynamic-shape graphs (see Dynamic Shapes and Kernel Cache); this one keeps a single plan and re-describes its operands per run. - It is not CUDA graph capture/replay. Overrides are an execute-path argument; capturing a graph populated with a fixed variant pack is a separate contract.
Boundaries
Measured on an L20 (SM89), cuDNN 9.26, FP16, B=1 H=4 D=64, plan
eng8_k24=1_k27=0_k38=0_k40=3_k41=1 for prefill and
eng8_k24=1_k27=0_k38=0_k40=2_k41=1 for decode. Buffers cover the declared
extent, or the larger override for the explicitly oversized probe:
These are observations of this platform and plan, not a portable supported-shape contract. The tests gate measured overrides and strict xfails on the device, runtime version, and selected plan. The oversized probe allocates physical storage for every overridden row; an xfail does not make an undersized CUDA allocation safe. Acceptance outside the declaration is not a correctness guarantee.
Two consequences for callers:
- Decode and prefill are different engine classes. A declared prefill graph
cannot be overridden to
s_q == 1, and a graph declared ats_q == 1should not be expected to serve prefill lengths. Keep one graph per class. - The legal window is narrower than “anything up to the declaration”. When
the declared
s_kvis a multiple of the plan’s KV tile, a non-causal run is correct only ats_kvoverrides that are also multiples of that tile; other lengths attend to the padding rows up to the tile boundary and return wrong output without an error. Thes_qoverride is not affected, and the causal mask hides the extra rows. The KV tile is 128 on the first-ranked H100/B200 plans (eng9/eng10), so there evens_kv = 64is wrong. Two forms served every override measured, on A100, L40S, H100 and B200 with cuDNN 9.27: a declaration off the KV tile (e.g. 255), and a graph that also carries the real lengths inseq_len_q/seq_len_kvwithuse_padding_mask=True(dense and ragged) (#1567). Validate the window you intend to use against your own plan and shapes before relying on it.
The s_q == 1 boundary and the declared-max-length sensitivity of the heuristic
(an eng8 -> eng10 flip between a declared 128 and 256, and 2.0-2.3x cost on
4-token rows on B200) were reported in
#1087 for SM100/SM107.
Those numbers belong to the reporter’s platform; the table above is this
repository’s L20 measurement, and on that configuration the plan list did not
change between a declared 64 and a declared 256. The split-KV note in the same
report (an override forces the split-KV factor to 1; 1.2-1.6x on low-occupancy
shapes for the per-batch seq_len form) is likewise the reporter’s measurement
and has not been repeated here.
FAQs
Logical vs Physical Layout
BHSD Layout (Batch-Head-Sequence-Dim)
The default logical layout where dimensions are ordered as .
- Dimensions:
- Strides:
This is the most common layout and matches PyTorch’s default attention tensor ordering.
BSHD Layout (Batch-Sequence-Head-Dim)
A physical layout where sequence comes before heads in memory, while maintaining the logical dimension order.
- Dimensions: (logical order, unchanged)
- Strides:
Note: The dimension order remains but strides are reordered so that in memory, sequence varies faster than head.
Determinism Support
Fprop
Always deterministic on all architectures
Bprop
SM100 - Deterministic requires cuDNN backend version 9.19.0 or later. SM80 and SM120 do not support deterministic algorithm with ragged input tensor. SM90 - Determinism is supported.
cuDNN Flex Attention API
SDPA forward operations accept set_score_mod, and SDPA backward operations accept both set_score_mod and set_score_mod_bprop, which allow modification of the attention score matrix and its backward propagation. These functions can be used to program a sub-graph of pointwise operations that can subsequently be used to program the score modifier. Note that this function usage is mutually exclusive to the usage of ready made options. Also, note that the graph argument in the score_mod function is not the same as the sdpa graph. So, any tensor to be passed as input to the score-mod sub-graph must first be registered with main graph and subsequently passed as argument to the score_mod function. The SDPA operation also now accepts the function set_block_mask, which applies a block mask to the score matrix. The implementation assumes a 128 x 128 block size.
cuDNN Version History for SDPA
This section documents features and fixes introduced in each cuDNN version for SDPA operations.
Version 9.21.0
set_unfuse_fma/unfuse_fmasupport for Unified SDPA forward on SM100
Version 9.19.0
- FP8 deterministic algorithm support on Blackwell
- d_qk=192 with d_v=128 support for FP8
Version 9.18.0
- THD/Ragged support on Ampere and Ada (SM80/SM89)
- Deterministic algorithm on Blackwell for FP16/BF16
Version 9.15.0
- Padding mask support for Unified SDPA
- Paged attention inputs for Unified SDPA
Version 9.14.0
- Block mask support for Unified SDPA
- Known Issue: Non-causal + s_kv > 1024 + sliding window may have issues
Version 9.13.0
- Unified SDPA implementation (requires 9.13.1)
- FP8 output in FP16/BF16 format on Blackwell
- Sink token support
Version 9.11.0
- DeepSeek configuration (d_qk=192, d_v=128) backward on Hopper
- Blackwell backward support with d_qk=192
Version 9.10.2
- Paged attention with packed page tables
Version 9.10.0/9.10.1
- Known Issues: General stability issues - recommend using 9.10.2+
Version 9.9.0
- Various head dimension expansions for decode mode
Version 9.7.0
- Bottom-right causal masking for FP8 (SM100+)
- Paged + ragged combination support
Version 9.6.0
- GQA with ragged offset support
- Bottom-right causal mask seqlen flexibility
Version 9.5.0
- Paged attention support
- dBias with variable sequence lengths
Version 9.3.0
- Bottom-right causal masking for FP16/BF16
- Minimum recommended version for new deployments
Version 9.2.0
- Sliding window attention
Version 9.1.0
- FP8 SDPA support (Hopper+)
Version 9.0.0
- Sequence length flexibility (s_q, s_kv not required to be multiples of 64)
Version 8.9.6
- Padding mask, ALiBi mask support
- Bias mask support
Version 8.9.3
- Initial SDPA support (SM80+)