
Simultaneous Compute and Graphics#
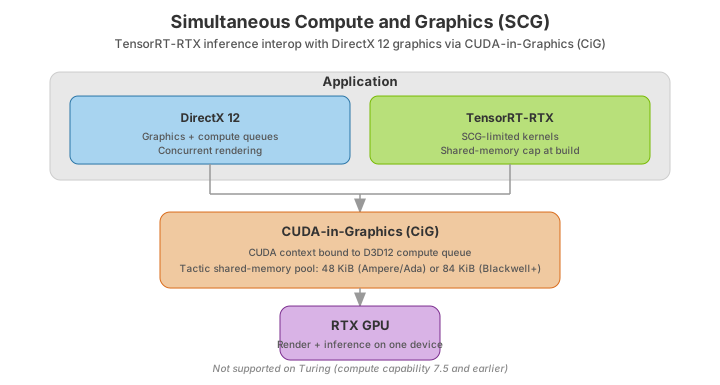
TensorRT-RTX provides support for inference while simultaneously running graphics workloads (simultaneous compute and graphics = SCG). The most common use case is video games, where generative AI features such as NPC dialog generation typically execute concurrently with 3D rendering.
The following diagram shows how an application reaches the GPU through a CUDA context that is shared with the graphics workload.
CUDA Context in CiG Mode#
Before starting inference at runtime, ensure that the current CUDA context runs in CUDA-in-Graphics (CiG) mode. Refer to the CUDA Driver API documentation for more information.
Important
CiG mode is available in CUDA version 12.6 and later (NVIDIA RTX driver 555 and later). It does not work with earlier CUDA or driver versions.
Note
While recent driver versions support CiG with the Vulkan graphics API, TensorRT-RTX supports only DirectX operability in this release. Vulkan support is planned for a future release.
The following code demonstrates how to enable CiG in the CUDA context.
Note
The cuCtxCreate_v4 function automatically associates the newly created CUDA context with the current thread. Therefore, you can use the following code for normal setup of TensorRT-RTX for inference.
// Get CUDA device ID, assuming single device on current system
int deviceIndex;
cudaGetDevice(&deviceIndex);
CUdevice device;
cuDeviceGet(&device, deviceIndex);
// Check that CiG is supported for the current hardware with DirectX
int isSupported;
cuDeviceGetAttribute(&isSupported, CU_DEVICE_ATTRIBUTE_D3D12_CIG_SUPPORTED, device);
if (!isSupported){
    throw "Simultaneous graphics / compute not supported for current hardware";
}
// Create DirectX device
ID3D12Device *dxDevice;
D3D12CreateDevice(nullptr, D3D_FEATURE_LEVEL_11_0, IID_PPV_ARGS(&dxDevice));

// Create two DirectX command queues for graphics and computation
D3D12_COMMAND_QUEUE_DESC graphicsQueueDesc{};
graphicsQueueDesc.Flags = D3D12_COMMAND_QUEUE_FLAG_NONE;
graphicsQueueDesc.Type = D3D12_COMMAND_LIST_TYPE_DIRECT;
void* graphicsQueue;
dxDevice->CreateCommandQueue(&graphicsQueueDesc, IID_PPV_ARGS(&graphicsQueue));

D3D12_COMMAND_QUEUE_DESC computeQueueDesc{};
computeQueueDesc.Flags = D3D12_COMMAND_QUEUE_FLAG_NONE;
computeQueueDesc.Type = D3D12_COMMAND_LIST_TYPE_COMPUTE;
computeQueueDesc.Priority = D3D12_COMMAND_QUEUE_PRIORITY_HIGH;
void* dxComputeQueue;
dxDevice->CreateCommandQueue(&computeQueueDesc, IID_PPV_ARGS(&dxComputeQueue));

// Set context creation parameters
CUctxCigParam ctxCigParam;
ctxCigParam.sharedDataType = CIG_DATA_TYPE_D3D12_COMMAND_QUEUE;
ctxCigParam.sharedData = dxComputeQueue;
CUcontextCreateParams ctxCreateParams;
// Exactly one of execAffinityParams and cigParams must be non-null
ctxCreateParams.execAffinityParams = nullptr;
ctxCreateParams.numExecAffinityParams = 0;
ctxCreateParams.cigParams = &ctxCigParam;
// Create a CUDA context with CiG enabled
CUcontext ctx;
cuCtxCreate_v4(&ctx, &ctxCreateParams, 0, device);
// Verify that the current CUDA context has CiG enabled
size_t limit;
cuCtxGetLimit(&limit, CU_LIMIT_CIG_ENABLED);
if (limit == 0){
    throw "Enabling CiG in the current CUDA context failed";
}
Next Steps#
CPU-Only AOT and TensorRT-RTX Engines: Specifying compute capabilities for engine builds
Best Practices: Measuring and optimizing inference performance in CiG mode
Working with CUDA Graphs: Reducing kernel launch overhead with CUDA graphs