

NVIDIA Requirements for AI Clouds
The following table lists the revision history for this guide.
Introduction
Purpose and Intent
This document serves three main purposes:
- Setting requirements for NVIDIA Cloud Partners (NCP) delivering GPU capacity to NVIDIA. This is the primary requirements document from NVIDIA to any NCP providing NVIDIA GPU and AI compute and software services. These requirements cover the full stack of AI cloud infrastructure services and operations needed to run NVIDIA DGX Cloud, expanding on the NVIDIA hardware reference design.
- Providing a reference set of requirements for the industry. NVIDIA is publishing this document openly so that NCPs, GPU data center operators, and AI practitioners can use it as a reference for the capabilities a large GPU consumer requires.
- Defining the NVIDIA service delivery expectations. NVIDIA expects services to be delivered as Generally Available (GA) to all customers, not as bespoke implementations built for NVIDIA alone. NVIDIA expects operational excellence, transparent communication, and proactive engagement from all partners.
NVIDIA will consider additional services that an NCP offers or plans to offer beyond what is described here.
Refer to the Definitions section for defined terms used throughout this guide.
Interpretation and Definitions
Interpretation
The interpretations and defined terms in this section apply throughout this guide. A more specific definition or measurement rule stated for a particular requirement or service applies within that narrower scope.
Provider-specific product names and resource constructs may differ from the terminology used here. Compliance is determined by whether the provider’s implementation satisfies the meaning and required outcome stated in this guide.
Normative Language
This guide uses the following normative terms to indicate requirement levels.
- Shall and must indicate a mandatory requirement.
- Should indicates a recommended but non-mandatory capability or practice. If a capability is intended to be required for compliance, the requirement must use shall or must.
- May indicates a permitted option.
- Preferred and nice-to-have indicate non-mandatory evaluation preferences and do not establish minimum compliance requirements.
Relationship to Deployment-Specific Requirements
An Ancillary Services Document or other deployment-specific agreement may establish site-specific quantities, topology, performance targets, schedules, and additional requirements. It does not waive or weaken a baseline requirement in this guide unless it expressly identifies the affected requirement and the approved exception.
Definitions
The following table defines the terms used throughout this guide.
Capacity Attributes
The following capacity terms are overlapping attributes, not mutually exclusive lifecycle states. A resource can be Delivered, Reserved, Allocated, Healthy, and In Use at the same time.
Testing Compliance
NVIDIA aims to test conformance to all of the requirements described in this document. Not all requirements are easily testable. For example, many operational requirements and SLAs require measurement over long periods of time or during failure scenarios. For requirements without a clear test mechanism, compliance is checked through a self-grading process and review.
AI Cloud Ready
Where possible, NVIDIA provides testing capabilities. NVIDIA has created the AI Cloud Ready test suite. This suite is continually evolving, but one of its main goals is to test as many of the requirements found in this document as possible. Refer to the AI Cloud Ready documentation for details on how to run the tests. Tests are added regularly, so review the Requirements Test Matrix to find which tests validate which requirements.
Exemplar Performance
While some performance testing happens in AI Cloud Ready, the primary mechanism to validate real-world cluster performance is the NVIDIA Exemplar program. This program seeks to improve performance per total cost of ownership (TCO) with hardware and software recipes, references, tools, and capabilities. Run the latest publicly available benchmark test suite from the NVIDIA Exemplar Performance repository and always pick the latest release version from that repository. The release must be completed on one uniform hardware cluster type. Run all the workloads for a given release and share the results in the following template.
Service Levels
NCPs should be able to demonstrate the ability to meet the service-level agreements (SLAs) to be considered for NVIDIA consumption, which is sometimes called NVIDIA offtake or offtake.
Unless otherwise stated, published availability, response, performance, metering, and telemetry targets in this guide are minimum service levels to be incorporated into the applicable SLA. Mandatory capabilities that are not measured service levels are stated as requirements.
Support and Incident Response
The NCP may use its own published incident and ticket severity scale, and the NVIDIA expectation is at least three levels. For NVIDIA services, SLA targets are measured against the following NVIDIA severity model: Sev-1 (critical or outage), Sev-2 (major or degraded), Sev-3 (minor), and Sev-4 (request or informational).
The NCP shall maintain a documented mapping from its severity scale to the NVIDIA model. Where the NCP severity scale has fewer than four levels, or an NCP severity level spans more than one NVIDIA severity level, the more severe NVIDIA level and its associated targets shall apply.
The following response targets apply to the NVIDIA severity model.
- Sev-1 (critical or outage) initial response: 15 minutes. The NCP shall work continuously, 24x7, until service is restored or a workaround is available.
- Sev-2 through Sev-4: Response and resolution targets shall be defined and published by the NCP and measured against the corresponding NVIDIA severity level.
Storage
The following service levels apply to NCP-provided storage.
- Performance: The NCP shall provision and sustain the contracted minimum performance. Performance below 85% of contracted targets sustained for 5 minutes or more constitutes an incident.
- Availability: 99.9%, measured per PB per month, defined as the fraction of time in which client mounts are healthy and no I/O request stalls beyond 60 seconds.
- Durability: 99.9999% per year against data loss or silent corruption, excluding tenant-initiated deletion. Data acknowledged as written must survive any single component failure.
Managed Kubernetes Service
The definitions for the Managed Kubernetes Service elements are provided in the Definitions section of this document.
The management service API must provide the following service levels.
- Availability: 99.95%, measured by the endpoint’s health status and ability to accept, durably store, and respond to the submitted requests.
- Durability: At least 99.999% of successfully acknowledged mutating service-management requests shall remain durably recorded and recoverable. Ensure that retrying such requests does not cause duplicate operations or unintended effects. Non-mutating requests need not be durably retained during service impairment.
The managed Kubernetes cluster control plane must provide the following service levels.
- Availability: 99.95% per managed cluster, measured by the API server endpoint’s health status and ability to accept, durably store, and respond to the submitted requests.
- Durability: At least 99.9% of successfully acknowledged mutating API requests. Idempotency must be guaranteed.
Managed Inference Endpoints (If Present)
Where offered, this SLA applies to each NCP-managed, tenant-facing production endpoint used to submit inference requests and receive model responses. Management and control-plane APIs are covered separately.
- Availability: 99.9% per endpoint per calendar month, measured by the endpoint’s ability to accept and successfully complete conforming inference requests.
Metering for Consumption Measurement
The following accuracy target applies to consumption metering.
- Accuracy: Within ±0.5% per month for shared or serverless capacity, and within ±0.1% per month for dedicated capacity.
Telemetry
The following SLA applies to all required telemetry, measured from observation at the source until the record is available through the agreed ingestion interface.
- Delivered Latency: The NCP shall make at least 99.95% of required telemetry records (including metrics and logs) available within 120 seconds of observation at the source.
Functional Requirements
This section describes the functional requirements across a wide range of domains.
Compute and Network Provisioning
This section outlines the requirements for provisioning compute and network resources. Compute instances can be provided as either bare-metal instances through Bare Metal-as-a-Service (BMaaS) or virtual machines through Virtual Machine-as-a-Service (VMaaS) to support the NVIDIA DGX Cloud engagement. All operations must be controlled through a fully documented and secure API. All systems are expected to scale and perform at scale.
General, Compute, and Lifecycle Management
The following table lists the general compute and lifecycle management requirements.
Boot Process and Disks
The following table lists the boot process and disk requirements.
SDN and Virtual Networking
This section covers the virtual networking requirements. Physical transport and network requirements are described in the Transport and Networking Requirements section.
The following table lists the software-defined networking and virtual networking requirements.
Kubernetes as a Service (KaaS) Requirements
Kubernetes Conformance, Versioning, and Compliance
The following table lists the Kubernetes conformance, versioning, and compliance requirements.
Kubernetes Operational Excellence
The following table lists the Kubernetes operational excellence requirements.
Robust Kubernetes Security
The following table lists the Kubernetes security requirements.
Kubernetes Component and Extension Requirements
The following table lists the Kubernetes component and extension requirements.
Kubernetes Functionality
The following table lists the Kubernetes functionality requirements.
Security and Identity Management
Identity and Access Management (IAM)
The platform must provide a centralized system for authentication, identity federation, authorization, and lifecycle provisioning across all platform services. It shall integrate with a trusted external or platform-hosted identity provider and consume OIDC-based identity tokens for user authentication. Upstream identity sources and protocols, such as enterprise directories, may be used through federation with the identity provider.
The following table lists the identity and access management requirements.
Cryptography and Key Management
The following table lists the cryptography and key management requirements.
Network Isolation and Encryption
The following table lists the network isolation and encryption requirements.
Edge Network Security
The following table lists the edge network security requirements.
Hardware Security and Compliance
The following table lists the hardware security and compliance requirements.
Break-Fix Requirements
The NCP must provide a specific break-fix API to support fleet reliability. Any node-level remediation must not affect other parts of the tenancy. Specifically, NVLink must be reconfigured properly to take a node out of the tenancy.
The API must enable the actions in the following table.
Telemetry Requirements
The telemetry requirements consist of two core components that require alignment between DGX Cloud and the NCP:
- Delivery method. This component defines how the NCP delivers telemetry to DGX Cloud for ingestion.
- Telemetry scope. This component defines what telemetry the NCP delivers to DGX Cloud.
All telemetry should be delivered within the latency target defined in the Telemetry service-level section.
Delivery Method
The NCP must deliver all required telemetry, including metrics and logs, in a manner that allows for ingestion into DGX Cloud systems with a latency of no longer than 120 seconds. Native OpenTelemetry Protocol delivery is preferred.
Telemetry Scope
NVIDIA will provide to the NCP, at the appropriate time in the engagement, a list of the telemetry artifacts, including the required metrics and logs. After receipt, the NCP must provide a formal written response that details the following:
- Confirmation of its ability to deliver the specified metrics and logs.
- Projected timelines for delivery.
- Specific technical details, including metric names, label names, and label values.
Network Telemetry
The NCP must provide network telemetry across the following domains:
- North-south, or front-end, network, including client-facing and external interconnects.
- East-west, or back-end, network, including GPU-to-GPU interconnects.
- Management network, including control plane and orchestration traffic.
- NVSwitch fabric, including intra-node GPU switching, applicable only to GB200 and later clusters.
- Host network, including NIC-level and server connectivity.
Storage Telemetry
The NCP storage services shall provide telemetry using the common delivery method and delivery target defined in the Telemetry service levels.
The required key telemetry includes the following:
- End-to-end visibility covering both the client and storage service, including provisioned and maximum throughput, IOPS, metadata operations, and latency. Granularity by filesystem, volume, client, Kubernetes pod, and Slurm job ID, where applicable.
- Capacity, including used, available, and total capacity, and file, object, and inode counts.
- Client health and I/O state, including connection status, queue depth, outstanding and blocked I/O, errors, retries, timeouts, throttling, failovers, and degraded states.
- Alerting on critical events, including inode count, capacity, performance saturation, and component failure.
Logs
DGX Cloud requires the NCP to provide logs from various network technologies, including but not limited to the following:
- Fabric Manager logs for the NVLink domain, where applicable.
- Subnet Manager logs for the NVLink domain, where applicable.
- VPC flow logs for all ingress and egress traffic.
- UFM event logs.
- General switch logs.
- Switch syslogs.
- Switch kernel logs.
- BMC SEL logs.
- Syslogs.
- Management logs.
Storage Requirements
The NCP must provide shared storage solutions, where applicable, that are manageable through standard APIs and UIs, including auditing rights for NVIDIA access.
File System Storage for Home Directory and High-Speed File System
The following table lists the requirements that apply to both home directory storage and high-speed file system storage.
High-Speed Storage Service Requirements
The following table lists the requirements for provisioning and interacting with the provider’s service offering.
High-Speed Filesystem Requirements
The following table lists the capabilities required for the high-speed filesystem.
Data Movement Systems Requirements
The data movement system is used to copy data from an external data source, such as NVIDIA or another cloud, to the NCP data center.
The following table lists the data movement system requirements.
DGXC-Managed Storage System Deployment
For scenarios where DGXC, rather than the NCP, deploys and manages the storage-system software, the following requirements apply. These requirements enable DGXC to operate storage systems, such as high-speed parallel filesystems, capacity object storage, or block storage, using NCP-provided infrastructure while maintaining operational control. For storage systems provided by the NCP, disregard this section.
Host Provisioning and Lifecycle
The following table lists the host provisioning and lifecycle requirements for DGXC-managed storage systems.
Network Transport and Fabric Visibility
Backend Switch Fabric API
The purpose of this API is to expose sufficient information about the cluster network topology to enable efficient scheduling, placement, and optimization of multi-node GPU workloads. Understanding the network hierarchy between compute instances and switches, as well as intra-node and inter-node NVLink domains, is essential for minimizing communication latency and maximizing throughput. This applies to north-south, east-west, and NVLink networks, but not to the management network. Refer to the Appendix for a DGXC-recommended reference implementation.
The following table lists the backend switch fabric API requirements.
Transport and Networking Requirements
Non-Conflicting IP Space Allocation for the DGXC Cluster
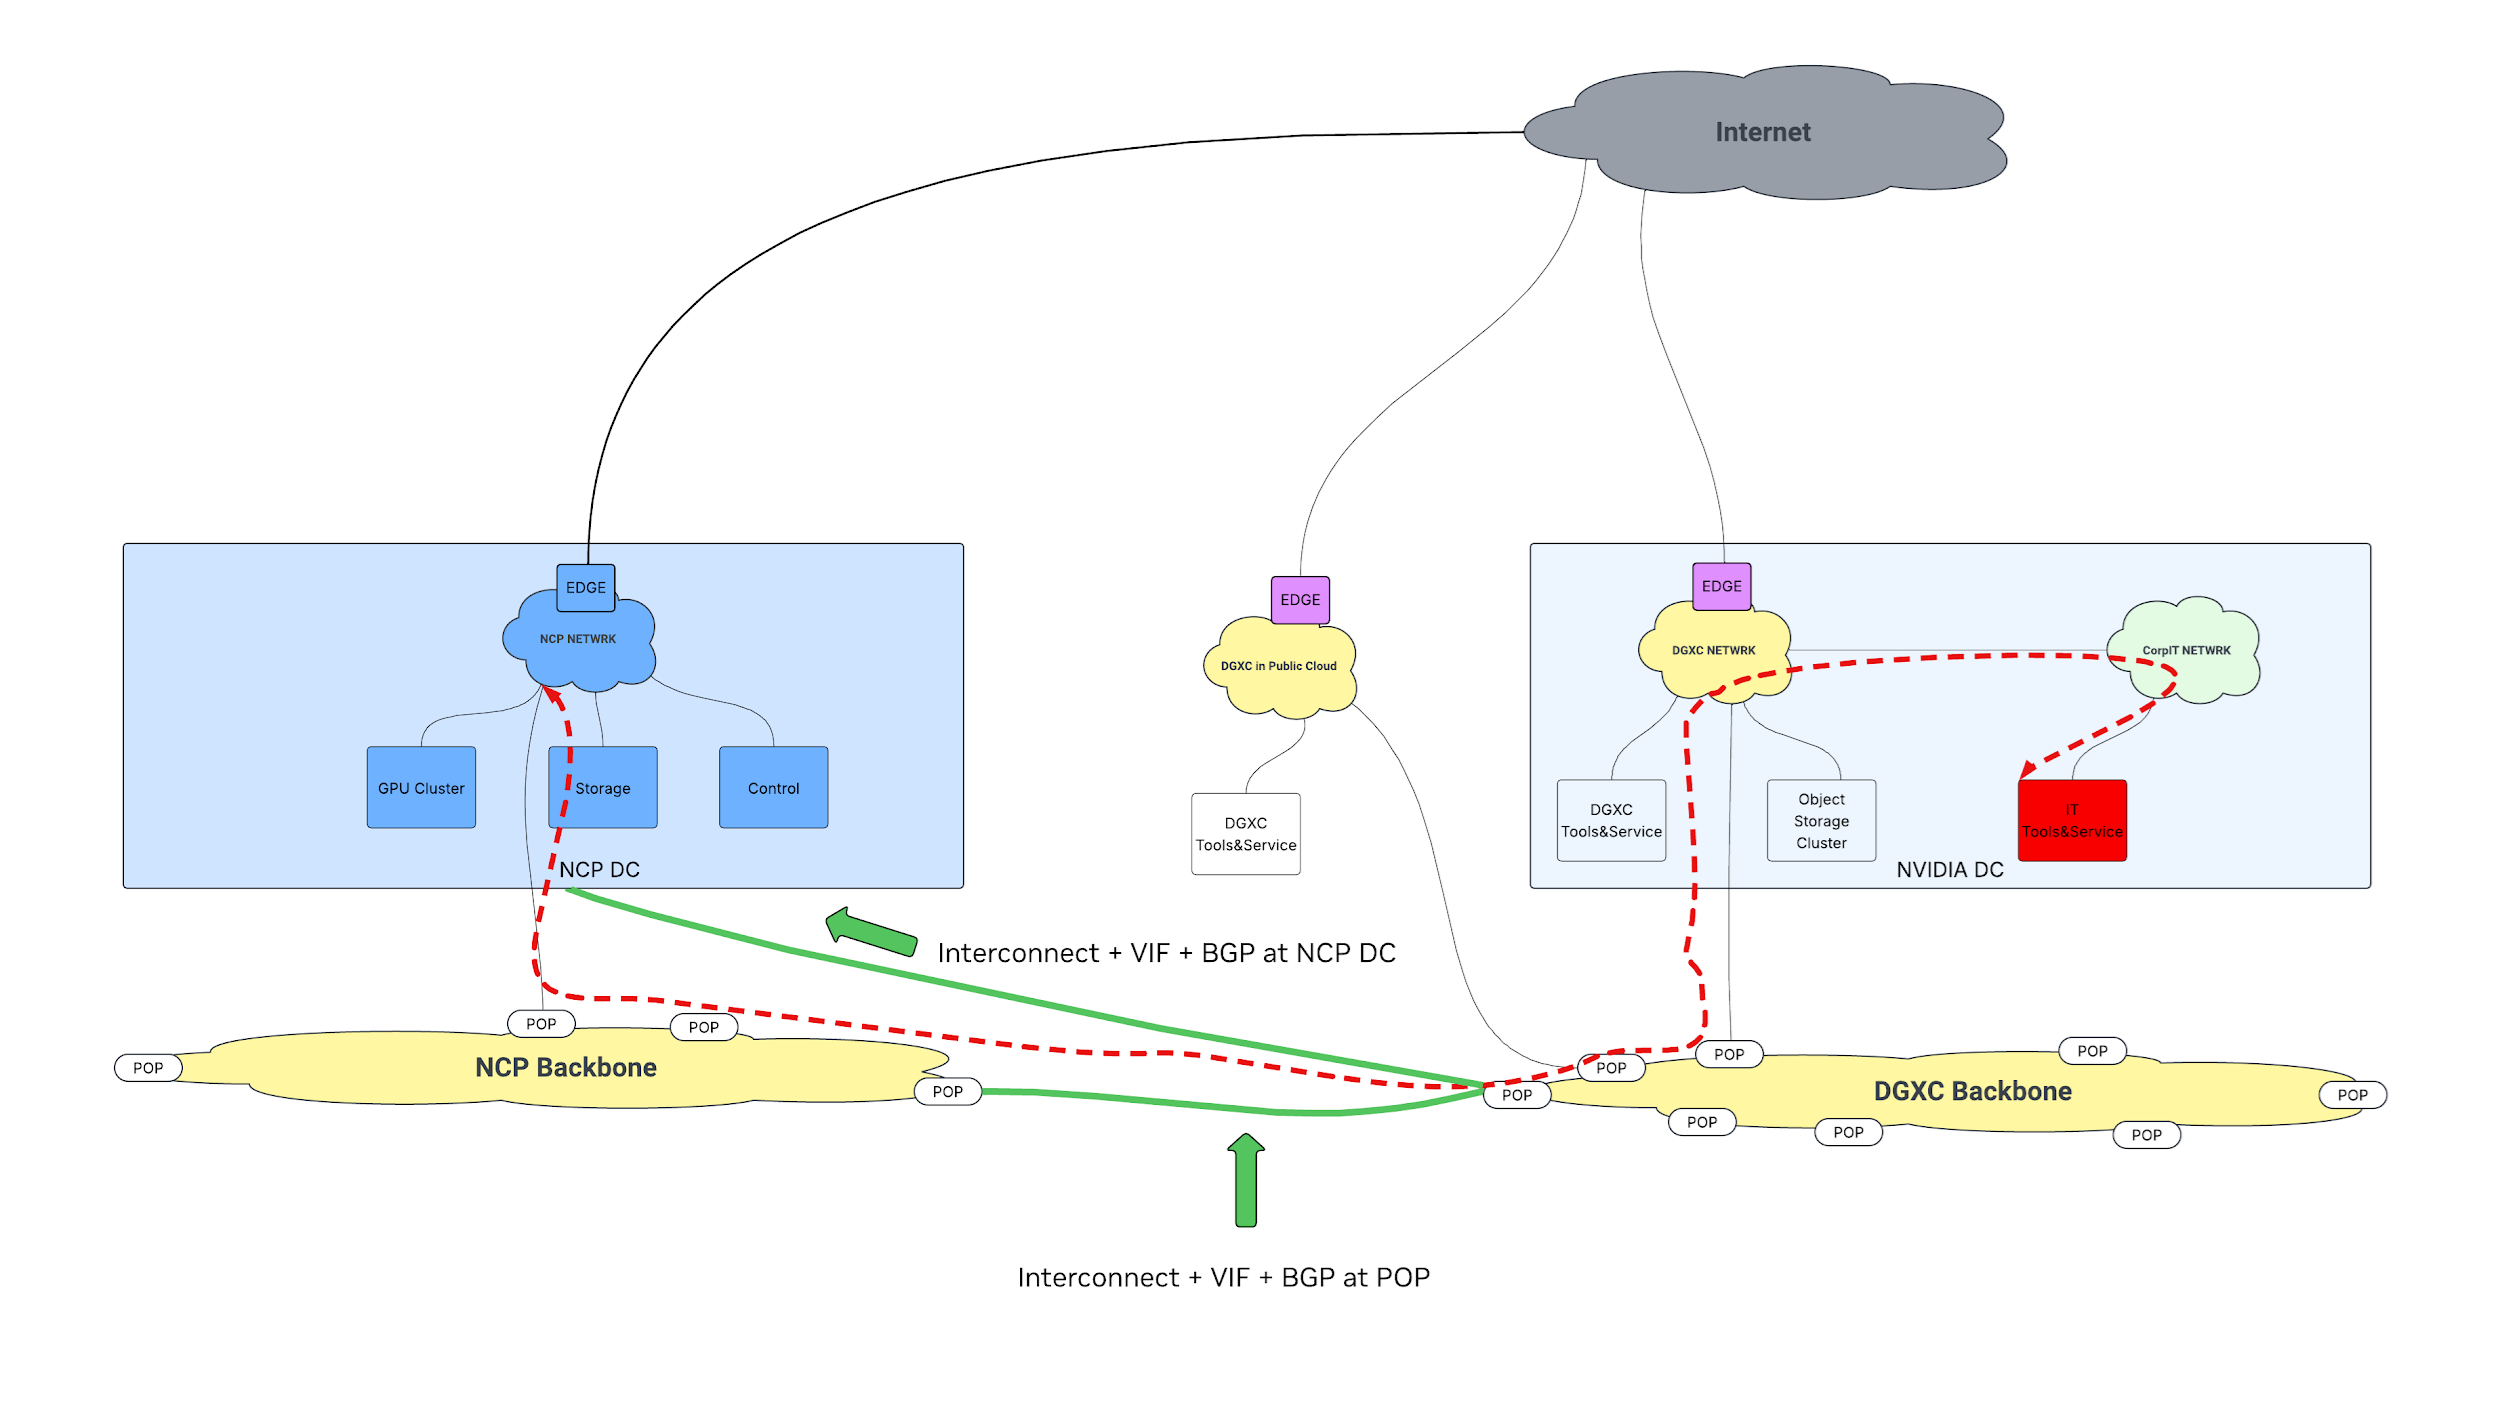
The purpose of this requirement is to ensure that DGXC GPU clusters deployed in the NCP environment can access the NVIDIA DGXC and CorpIT network directly through routing exchange. DGXC cluster IP addresses must not conflict with existing NVIDIA private IP space.
Connection to NVIDIA CorpIT Network
The purpose of this requirement is to provide a connection from DGXC GPU clusters within the NCP environment to NVIDIA CorpIT for internal command, control, and administrative access.
The following diagram shows Private Cloud Interconnect with VIF and BGP for CorpIT access.
Connection to DGXC Storage
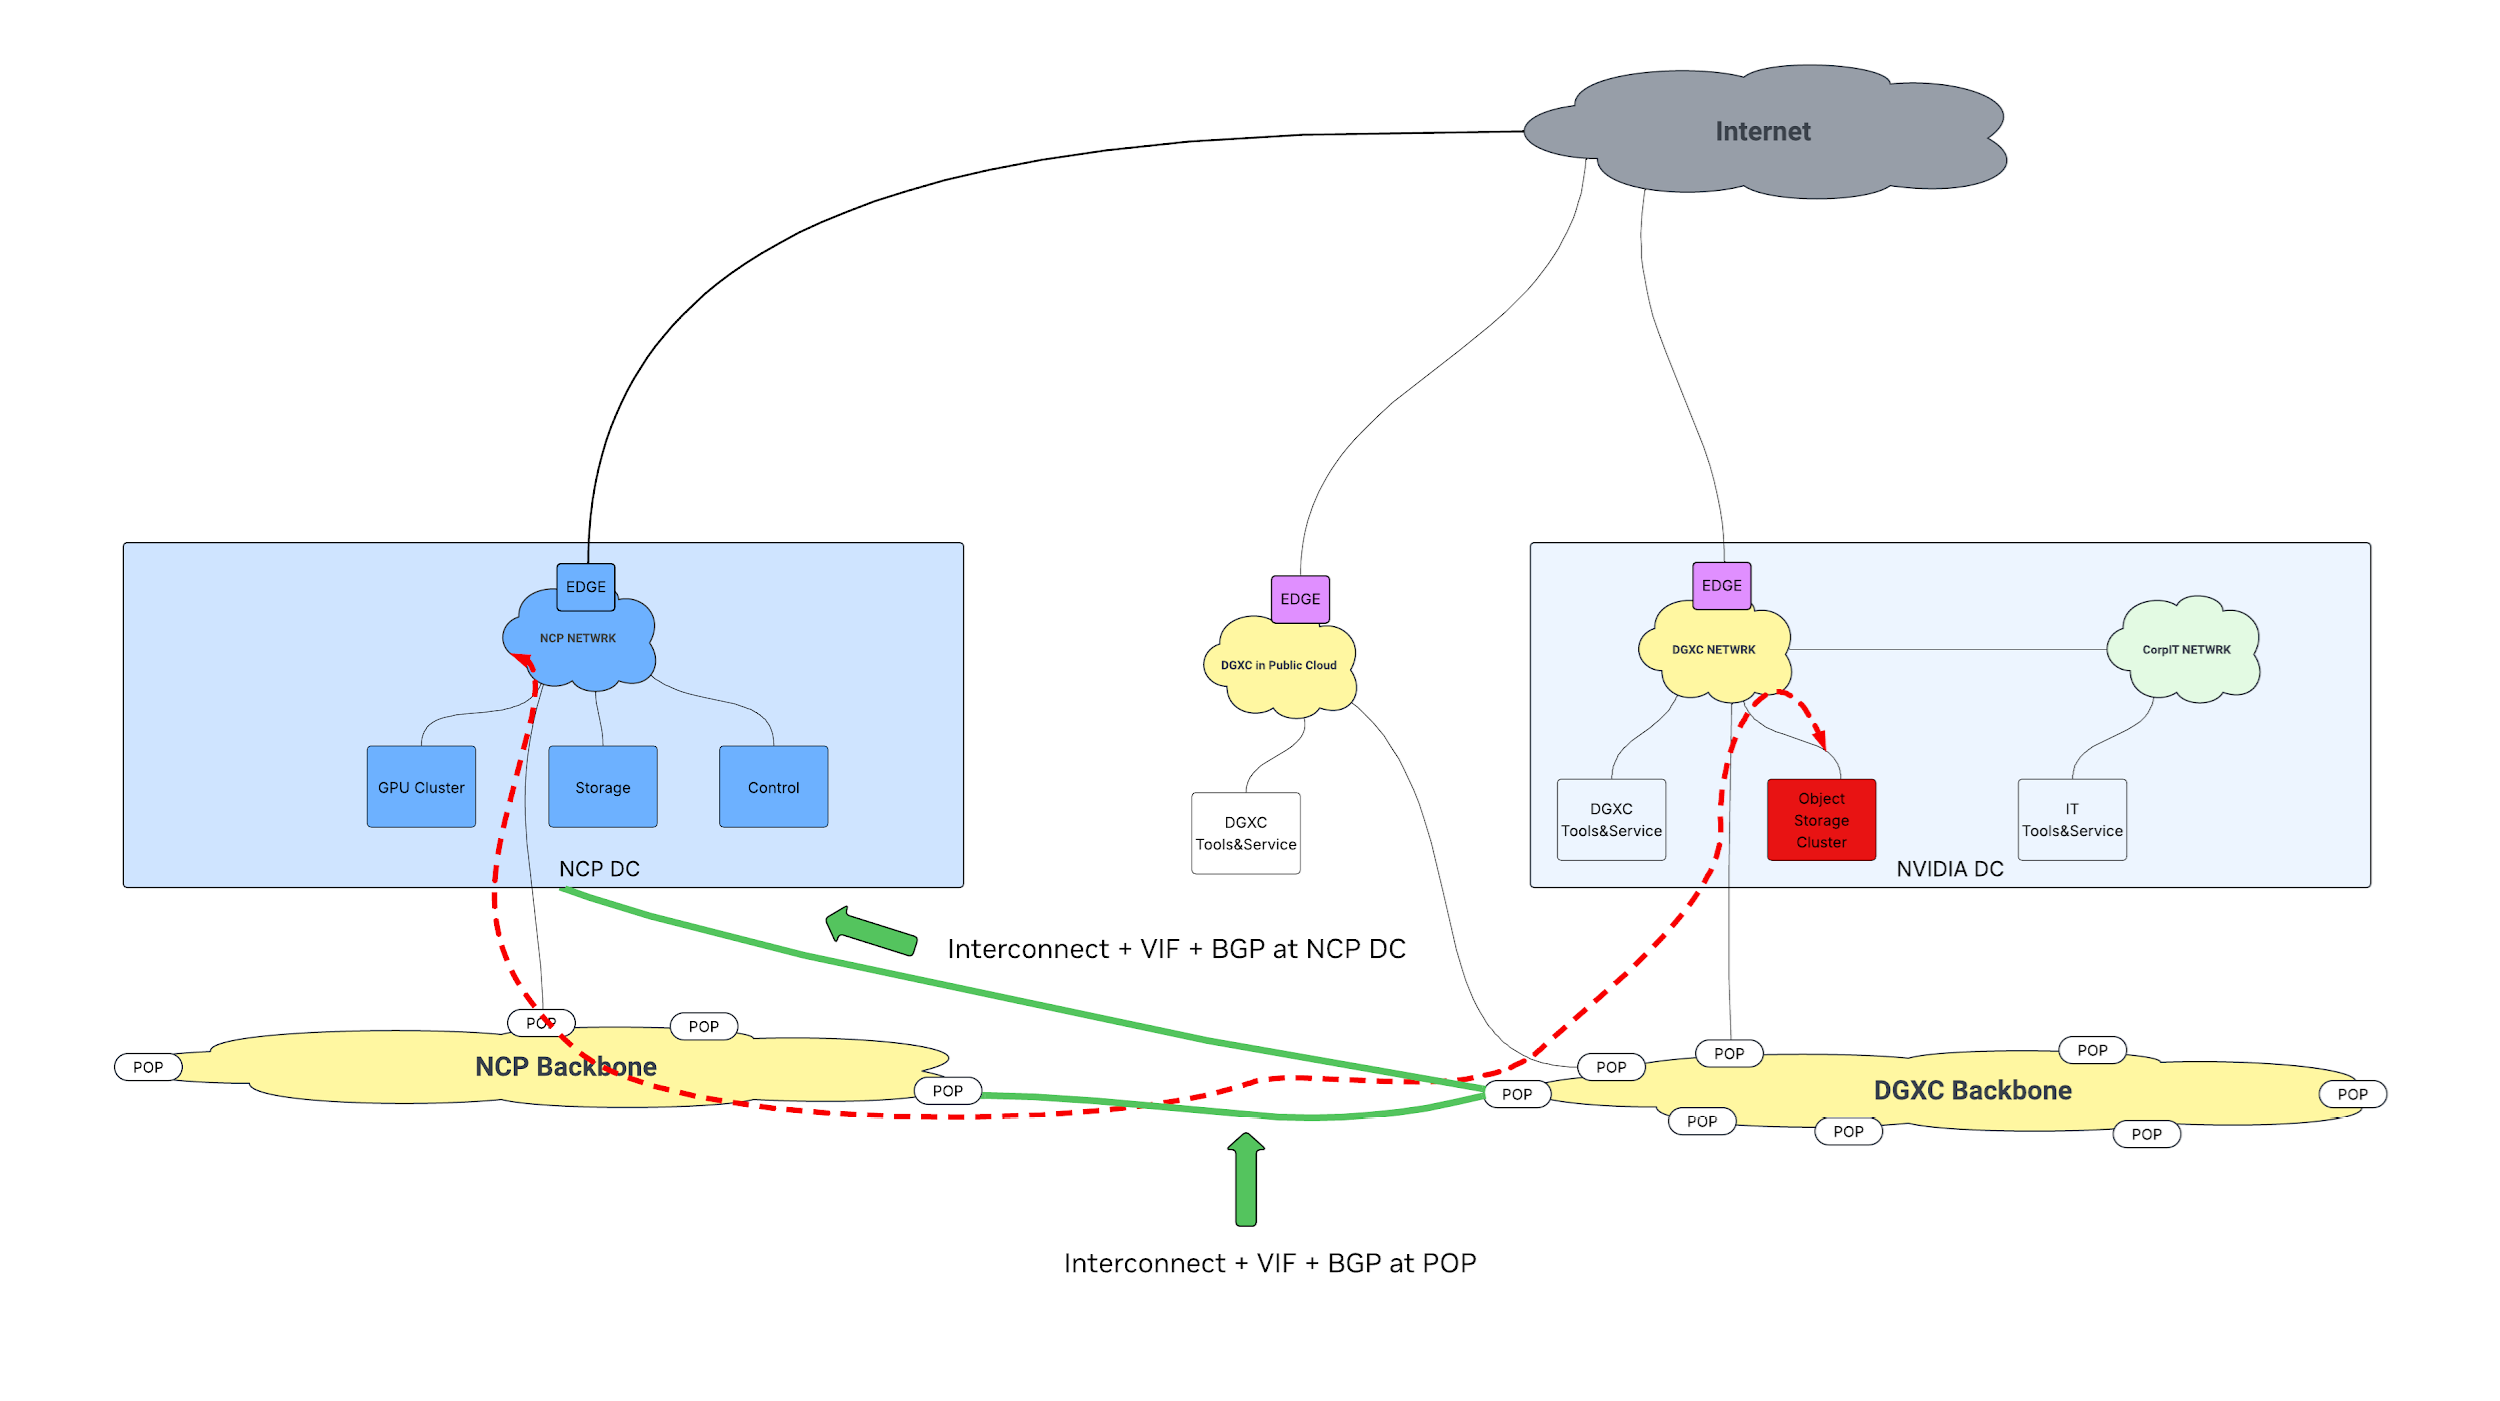
The purpose of this requirement is to enable high-bandwidth, end-to-end MACsec-encrypted, fail-closed access between the DGXC GPU clusters in the NCP environment and NVIDIA DGXC on-premises object storage for large-scale data movement.
The following diagram shows the storage connectivity path between the DGXC GPU clusters and NVIDIA DGXC object storage.
Cluster Local Internet Access
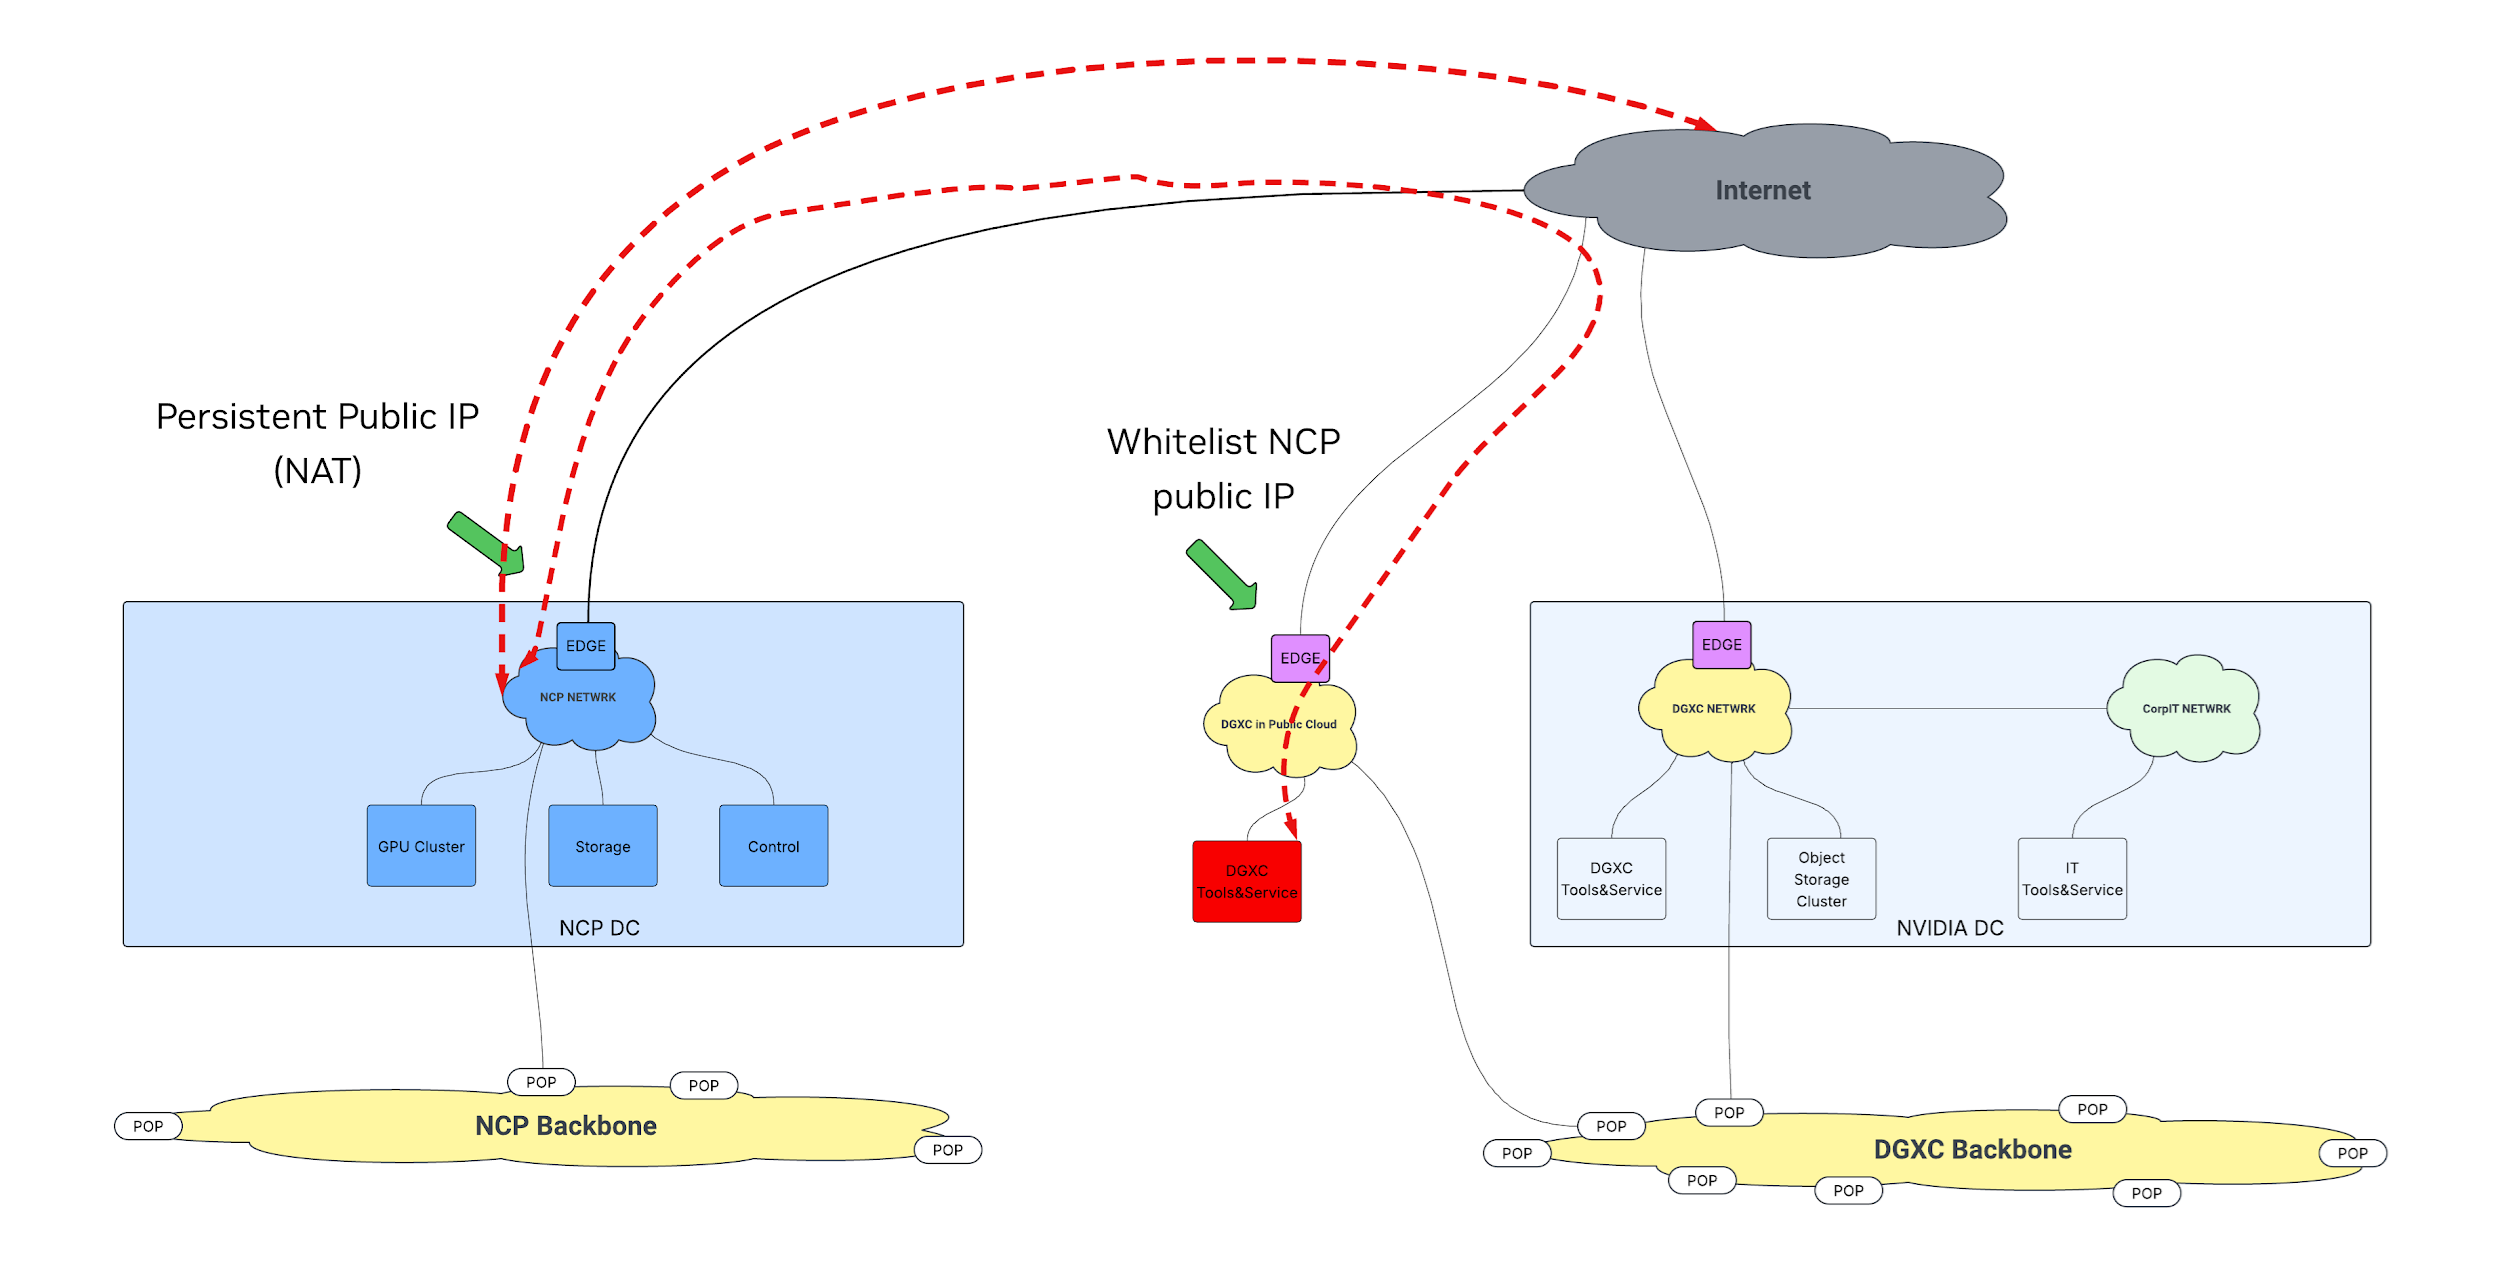
The purpose of this requirement is to provide DGXC GPU clusters within the NCP environment with general internet access, including access to NVIDIA DGXC services hosted on third-party public cloud services.
The following diagram shows public internet access for DGXC-hosted services.
Capacity and Fleet Management
This section defines the essential metrics required for standardized monitoring and reporting of fleet health in partner engagements, supporting operations and contractual SLAs.
The following table lists the capacity and fleet management requirements.
Operational Requirements
This section defines how the NCP operates the service. Where an earlier section defines a capability, such as incident management or telemetry delivery, this section defines the operational practice around that capability and references it rather than repeating it. Numeric service-level targets are stated once, in the Service Levels section, and operational models and processes are defined here. These operational expectations describe generally available operational maturity, and they are not bespoke to NVIDIA. Requirement levels are carried in the description text through the words must and shall, consistent with the rest of this document.
Support and Ticketing
The NCP must provide staffed, responsive support with a system of record for every issue NVIDIA raises, classified under the common severity model and driven to the targets in the Service Levels section.
The following table lists the support and ticketing requirements.
Incident, Outage, and Escalation Management
The NCP must detect, classify, communicate, and resolve service-impacting events, and drive each to durable resolution through root-cause analysis. The NCP must ultimately take permanent steps to ensure there is no recurrence. Fault signals are defined in the Telemetry Requirements section and remediation primitives in the Break-Fix Requirements section, and this section defines how they are operationalized. The severity model here is the single model used across this section, including ticketing.
The following table lists the incident, outage, and escalation management requirements.
Security Incident and Breach Notification
This section governs security incidents and confirmed or suspected compromise of NVIDIA tenancy, data, or infrastructure. It complements the Security and Identity Management section, which defines the underlying controls.
The following table lists the security incident and breach notification requirements.
Service Health and Status Communications
The NCP must give NVIDIA an authoritative, always-available view of service health, active incidents, and planned maintenance.
The following table lists the service health and status communication requirements.
Change and Release Management
Changes to production infrastructure must be controlled so that each change is approved, reversible, and communicated. High-risk changes progress through a staged rollout.
The following table lists the change and release management requirements.
Fleet Health and Maintenance
Planned and emergency maintenance must be declared, scheduled with NVIDIA, and tracked. A hand-back window is how long the tenant has to return the instance, and the maintenance window is how long the NCP has to perform the service.
The following table lists the fleet health and maintenance requirements.
Operational Access and Activity Logging
The NCP operational access to production infrastructure must follow the security best practice of least privilege, be strongly authenticated, and be fully logged. This section governs operator and provider access. Tenant-facing identity and access management is defined in the Security and Identity Management section, and these requirements reference rather than restate it.
The following table lists the operational access and activity logging requirements.
Vulnerability and Patch Management
The NCP must identify, prioritize, remediate, and, where relevant, disclose vulnerabilities across the infrastructure, and track them to closure.
The following table lists the vulnerability and patch management requirements.
Monitoring, Alerting, and On-Call
The NCP must monitor infrastructure and services, alert on defined conditions, and staff on-call to respond to alert notifications 24 hours a day, 365 days a year, independent of regional holidays and observances and of local and geographical events. Telemetry content and delivery are defined in the Telemetry Requirements section, and this section defines the operational response layer.
The following table lists the monitoring, alerting, and on-call requirements.
Capacity and Availability Management
The NCP must plan capacity, measure availability against the published targets, and remedy misses. Fleet inventory and health metrics are defined in the Capacity and Fleet Management section, the numeric targets in the Service Levels section, and the measurement mechanics in the next section.
The following table lists the capacity and availability management requirements.
Service-Level Measurement and Definitions
Availability and other service-level targets are enforceable only if measurement is defined. This section states how targets are measured, what is excluded, and how misses are reconciled, complementing the numeric targets in the Service Levels section.
The following table lists the service-level measurement requirements.
Disaster Recovery and Business Continuity
This section defines disaster recovery (DR) and business continuity planning, backup verification, recovery objectives, and recovery testing for NCP-delivered services.
The following table lists the disaster recovery and business continuity requirements.
Provisioning and Onboarding
The NCP must run a defined lifecycle for standing up, scaling, and tearing down NVIDIA tenancy, including verifiable data deletion on exit. New-capacity delivery timelines are defined in the Service Levels section, and capacity discovery is defined in the Capacity and Fleet Management section.
The following table lists the provisioning and onboarding requirements.
Appendix
This section contains links to reference documents and implementation guidance that provide additional details for NCPs. Refer to requirement level key words for the well-known definition of certain terms used in the document.
Implementation Guidance
The following reference documents provide additional information on implementing some of the requirements in this guide.
- Network topology discovery: NVIDIA Topograph. Aligning with this YAML format may be useful. Topograph currently provides in-cluster topology.
- Exemplar Cloud: NVIDIA Exemplar Cloud and the DGXC benchmarking repository.
- Kubernetes security guidance: Kubernetes Security Response Committee.
Other Feature Considerations (Not Minimum Requirements)
The following capabilities are not minimum requirements, but NVIDIA considers them valuable additions.
- Disk cloning. Disk-cloning capability for network-attached block devices. It should be possible to clone a disk even on a running instance.
- Managed control plane autoscaling. Strong preference for the control plane to automatically add capacity when load increases.
- Threat detection. Control planes, management planes, and hosts under the service provider control should deploy threat-detection and anomaly-detection solutions that can identify active threats, for example, a host-based intrusion detection system (HIDS) and a network-based intrusion detection system (NIDS).
- Break-glass administrative access. The platform should support a limited break-glass access mechanism for designated NVIDIA administrative users when federated SSO is unavailable, misconfigured, compromised, or otherwise prevents authorized access to the tenant. Break-glass accounts should use local platform credentials independent of the external identity provider, be explicitly excluded from SSO enforcement, and be protected by strong authentication controls including MFA. Their use should be auditable, generate security-relevant logs and alerts, and support periodic review, rotation, disablement, and testing.