TensorRT-LLM Sidecar
Run Dynamo beside a TensorRT-LLM engine through its OpenEngine gRPC API.
Experimental. The sidecars and their deployment examples are experimental. Manifests, flags, and behavior may change without notice.
dynamo-trtllm-sidecar connects a Dynamo worker to TensorRT-LLM’s OpenEngine
gRPC server. See Sidecar Backends
for the architecture.
For the best and latest support, use the upstream TensorRT-LLM nightly image,
which carries the latest gRPC server updates. Nightly builds are the
nvcr.io/nvidia/tensorrt-llm/release:<version>.dev<date> tags on
NGC.
KV routing is available in
nvcr.io/nvidia/tensorrt-llm/release:1.4.0a0.dev202610180820, which includes
native KVCM2 event streaming and OpenEngine routing load support.
Support Matrix
Launch Locally
See lib/sidecar/trtllm/launch/
for all topologies. For example, aggregated serving on one GPU:
In a second terminal:
Deploy on Kubernetes
See lib/sidecar/trtllm/deploy/
for all manifests. For example, aggregated serving:
Before applying, replace <your-registry>/dynamo-sidecar in the manifest with a
sidecar image and create the hf-token-secret
Secret that the manifest reads.
Topologies
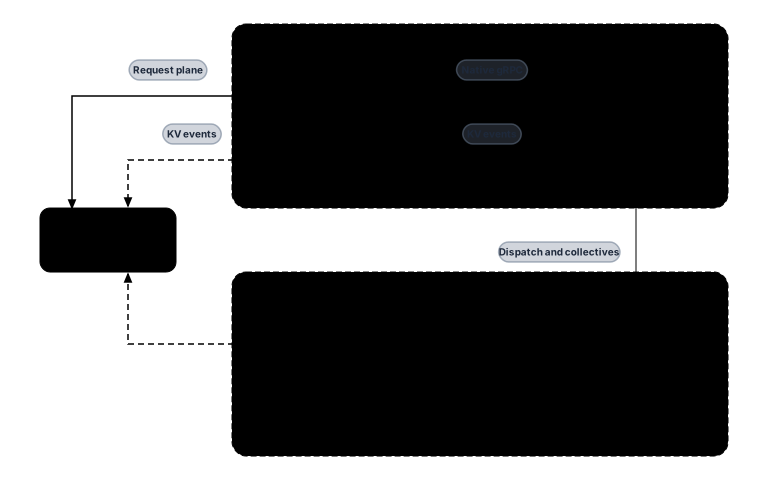
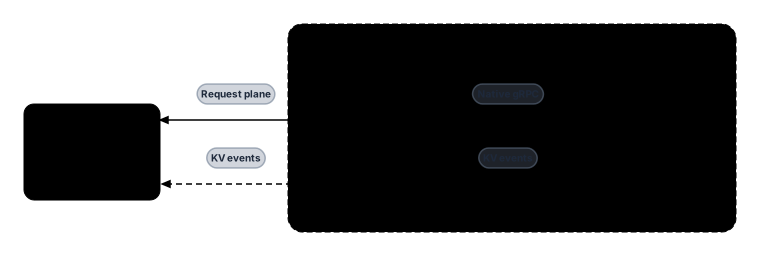
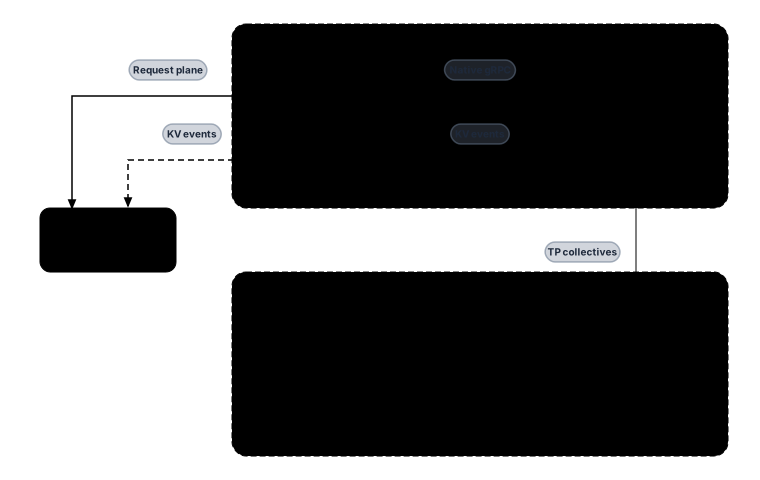
The frontend sends inference requests to each engine’s leader sidecar, which forwards them to OpenEngine over gRPC and polls routing load for all attention-DP ranks. Each sidecar discovers its node’s KV event sources through OpenEngine and relays local KV events through Dynamo’s event plane. Follower sidecars do not serve inference requests.
Single-Node TP
One engine on one node, with one sidecar.
Multi-Node TP
One engine spans two nodes. Only the leader node has a sidecar; the follower node holds the remaining TP ranks.
Multi-Node DP
The sidecar forwards the selected attention-DP rank to OpenEngine for KV-aware routing when the engine has more than one attention-DP rank. For single-rank engines, it omits the redundant rank hint and does not synthesize a conversation ID for anonymous requests. Explicit session IDs are preserved.
For multi-rank engines with conversation affinity enabled, OpenEngine currently requires a conversation ID with a rank hint. The sidecar supplies a request-scoped ID when the client provides no session. With KVCM2 block_reuse_config.policy: per_conversation, those one-shot IDs can retain conversation state until cache reset or engine restart, causing host memory to grow with anonymous request count. Avoid this combination for sustained anonymous traffic until TensorRT-LLM accepts rank hints without conversation IDs or bounds retained conversation state.