

Using AIPerf to Benchmark
NVIDIA AIPerf is a client-side generative AI benchmarking tool, providing key metrics such as TTFT, ITL, TPS, RPS and more. It supports any LLM inference service conforming to the OpenAI API specification, a widely accepted de facto standard in the industry. This section includes a step-by-step walkthrough, using AIPerf to benchmark a Llama-3 model inference engine, powered by NVIDIA NIM.
Step 1. Setting Up an OpenAI-Compatible LLama-3 Inference Service with NVIDIA NIM
NVIDIA NIM provides the easiest and quickest way to put a LLM into production. See the NIM LLM documentation to get started, beginning with hardware requirements, and setting your NVIDIA NGC API keys.
For convenience, the following commands have been provided for deploying NIM and executing inference from the Getting Started Guide:
This example sets up the Meta llama3-8b-instruct model and uses that name as the name of the container. The examples refer to and mount a local directory as a cache directory. During startup, the NIM container downloads the required resources and begins serving the model behind an API endpoint. The following message indicates a successful startup.
Once up and running, NIM provides an OpenAI-compatible API that you can query, as shown in the following example.
In our extensive benchmarking tests, we have observed that by specifying additional Docker flags, either --security-opt seccomp=unconfined (which disables the Seccomp security profile) or --privileged (which grants the container almost all the capabilities of the host machine, including direct access to hardware, device files, and certain kernel functionalities), inference performance can be further improved, up to 5% with the NIM TensorRT-LLM v0.10.0 backend, and up to 20% with the OSS vLLM (tested on v0.4.3) or the NIM vLLM backend (tested on NIM 1.0.0). This has been verified on DGX A100 and H100 systems, but potentially broadly applicable to other GPU systems. Disabling Seccomp or using privileged mode can eliminate some of the overhead associated with containerization security measures, allowing NIM and vLLM to utilize resources more efficiently. However, while there are performance benefits, these flags should be used with utmost diligence due to the elevated security vulnerabilities. See Docker documentation for further details.
Step 2. Setting Up AIPerf and Warming Up: Benchmarking a Single Use Case
Once the NIM LLama-3 inference service is running, you can set up a benchmarking tool. The easiest way to do this is using a pre-built docker container. We recommend starting a AIPerf container on the same server as NIM to avoid network latency, unless you specifically want to factor in the network latency as part of the measurement.
Consult AIPerf documentation for a comprehensive guide for getting started.
Run the following commands to use the pre-built container.
Once inside the container, you first install AIperf with:
This test will use the llama-3 tokenizer from HuggingFace, which is a guarded repository. You will need to apply for access, then login with your HF credential.
After that, you can start the AIPerf evaluation harness as follows, which runs a warming load test on the NIM backend.
This example specifies the input and output sequence length and a concurrency to test. It also tells the backend to ignore the special “EOS” tokens, so that the output reaches the intended length.
See AIPerf documentation for the full set of options and parameters.
Upon successful execution, you should see the results similar to the following in the terminal:
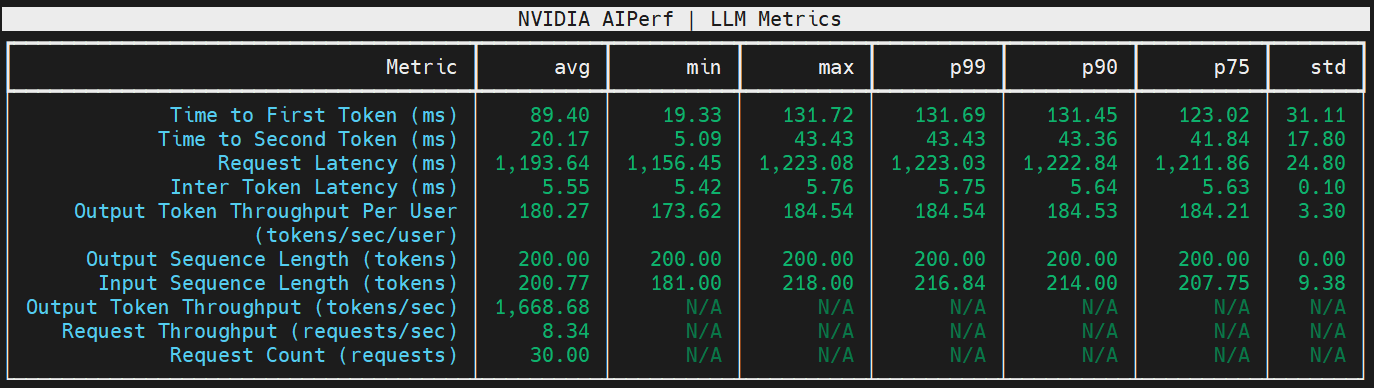
Step 3. Sweeping through a Number of Use Cases
Typically with benchmarking, a test would be set up to sweep over a number of use cases, such as input/output length combinations, and load scenarios, such as different concurrency values. Use the following bash script to define the parameters so that AIPerf executes through all the combinations.
Before doing a benchmarking sweep, it is recommended to run a warming-up test. In our case, this was performed in Step 3 previously.
Save this script in a working directory, such as under /workdir/benchmark.sh. You can then execute it with the following command.
The “—request-count” parameter specifies the number of requests for the measurement, which we set to 3x the concurrency level to obtain a stable measurement. However, high concurrency on a large model with a large ISL/OSL scenario can result in a significantly longer benchmarking time.
Step 4. Analyzing the Output
When the tests are complete, AIPerf generates the structured outputs in a directory named “artifact” under your mounted working directory (/workdir in these examples), organized by input/output length and concurrency. Your results should resemble the following.
The “profile_export_aiperf.json” files contain the main benchmarking results. Using the following Python code snippet to parse a file for a given use case into a JSON object.
You can also read all the tokens-per-second and TTFT metrics across all concurrencies for a given use cases using the following Python script.
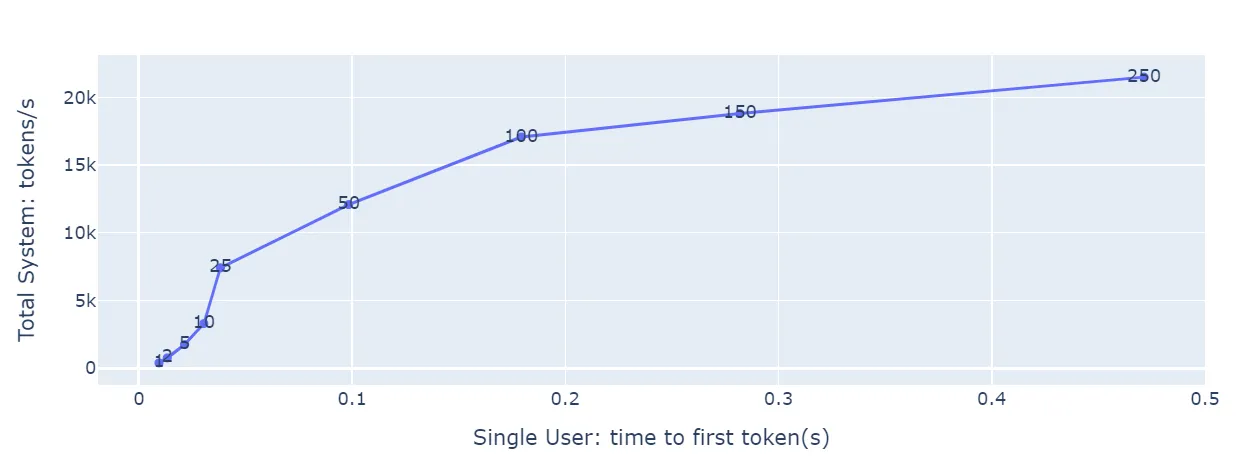
Finally, we can plot and analyze the latency-throughput curve using the collected data with the code below. Here, each data point corresponds to a concurrency value.
The resulting plot using AIPerf measurement data looks like the following.
Step 5. Interpreting the Results
The previous plot shows TTFT on the x-axis, total system throughput on the y-axis, and concurrencies on each dot. There are two ways to use the plot:
- An LLM application owner who has the latency budget, where the maximum TTFT that is acceptable, uses that value for x, and looks for the matching y value and the concurrencies. That shows the highest throughput that can be achieved with that latency limit and corresponding concurrency value.
- An LLM application owner can use the concurrency values to locate the dot on the graph. The x and y values that match show the latency and throughput for that concurrency level.
The plot also shows the concurrencies where latency grows quickly with little or no throughput gain. For example, in the plot above, concurrency=100 is one such value.
Similar plots can use ITL, e2e_latency, or TPS_per_user as X-axis, showing the trade-off between total system throughput and individual user latency.