Skip to navigation

Basic Inference

View as MarkdownOpen in Claude

After the NIM is running, confirm that the gRPC service is ready. Then, use the sample client to send a video and tracked bounding-box annotations and produce per-frame pose results.

Verify the Service and Install the Client

Complete the following steps before you send an inference request.

  1. Perform a health check on the gRPC endpoint.

    • Install grpcurl from github.com/fullstorydev/grpcurl/releases.

      Example commands to run on Ubuntu:

      wget https://github.com/fullstorydev/grpcurl/releases/download/v1.9.1/grpcurl_1.9.1_linux_amd64.deb
      sudo dpkg -i grpcurl_1.9.1_linux_amd64.deb

      Without sudo, extract the same package into a directory you own and put its binary on your PATH:

      dpkg-deb -x grpcurl_1.9.1_linux_amd64.deb grpcurl-pkg
      export PATH="$PWD/grpcurl-pkg/usr/bin:$PATH"
    • Run the health check. The server enables gRPC reflection, so no proto file is needed:

      grpcurl --plaintext localhost:8001 grpc.health.v1.Health/Check

      If the service is ready, you get a response similar to the following:

      { "status": "SERVING" }

      The same reflection exposes the inference method, nvidia.ai4m.body_pose.v1.BodyPoseService/EstimateBodyPose, a bidirectional stream described in Input and Output.

    While the NIM loads and warms up the model, the gRPC port does not accept connections yet, so the health check fails to connect instead of returning a status. Retry it until it returns `SERVING` before sending inference requests.
    For using grpcurl with an SSL-enabled server, avoid using the `--plaintext` argument, and use `--cacert` with a CA certificate, `--key` with a private key, or `--cert` with a certificate file. For more details, refer to `grpcurl --help`.
  2. Download the 3D Body Pose client code by cloning the gRPC client repository (NVIDIA-Maxine/nim-clients):

    git clone https://github.com/NVIDIA-Maxine/nim-clients.git
    # Go to the 'body-pose' folder
    cd nim-clients/body-pose/

    Run the install and proto steps from nim-clients/body-pose/. The client itself runs from the scripts folder, so the client commands on this page use paths relative to nim-clients/body-pose/scripts/, and the sample assets are in ../assets/.

  3. For the Python client, create a virtual environment and install the required dependencies. The client requires Python 3.10 to 3.12 with pip and venv available. The virtual environment is required on distributions whose system Python is marked externally managed, where a plain pip install fails with error: externally-managed-environment.

    python3 -m venv .venv
    source .venv/bin/activate
    pip install -r requirements.txt

    On Debian and Ubuntu, python3 -m venv requires the python3-venv package (sudo apt install python3-venv). On Windows, activate with .venv\Scripts\activate instead of source .venv/bin/activate. Keep the environment active for every python command on this page.

Compile the Protos (Optional)

The client ships pre-generated Python stubs under interfaces/. If you use those stubs, you can skip this step.

The proto files are available in the protos/proto folder. You can compile them to generate client interfaces in your preferred programming language. For more details, refer to Supported languages in the gRPC documentation. Use the grpcio-tools version pinned in requirements.txt.

Python

To compile protos on Linux, run the following commands:

cd protos/linux/
chmod +x compile_protos.sh
./compile_protos.sh
cd ../../

To compile protos on Windows, run the following commands:

cd protos/windows/
compile_protos.bat
cd ../../

Input and Output

The 3D Body Pose NIM exposes a bidirectional streaming gRPC API. A single call processes one video stream:

  1. The client sends a first request that carries the stream configuration (BodyPoseConfig) and the full tracked bounding-box annotation for the video, covering all frames. The annotation can instead be split across several requests, provided every one of them arrives no later than the first video_data chunk; boxes sent after the video has started are not read. The server assembles the whole annotation before it decodes the video, not incrementally; only the video itself is streamed.
  2. The client streams the compressed video file as byte chunks.
  3. The server decodes the frames, estimates the pose for each tracked box, and streams back frame-aligned pose results, followed by a final response that marks the stream as flushed.

Inputs

  • Video: A compressed video file, streamed as raw byte chunks: H.264 (preferred), H.265, AV1, VP8 or VP9, in an MP4 or WebM/Matroska container, 4:2:0 chroma, 8-bit — the only pixel format this NIM accepts, on every codec; see Input Media. 10- and 12-bit content (HDR included) and 4:2:2/4:4:4 chroma are refused on the container header before any decoding, as is a codec this GPU’s decoder does not decode at all; a header that states neither chroma nor depth passes the product rule, so only the hardware rule and then the first-frame watchdog stand between it and the decoder. H.264 in MP4 is what these pages use in examples and what is tested most heavily. SDR only — HDR content is not supported. The server decodes the video; the client never decodes it. Constant frame rate (CFR) is required, and it is enforced. The decoder rejects a clip whose frame interval varies, including a constant-rate clip with a single dropped frame, with INVALID_ARGUMENT (see Validation rules). The requirement itself follows from the annotation format rather than from the decoder — boxes are addressed by frame_id, so a frame index has to mean the same instant to your tracker and to the server. Under VFR it does not, and the poses would be matched to the wrong boxes without anything appearing to fail. Re-encode a VFR source to CFR before sending it.
  • Tracked bounding boxes: One box per tracked body per frame, in full-image pixel coordinates. The NIM does not run body detection, so this annotation is required. See Tracked Bounding-Box Annotation Format.

Output

The NIM returns pose data, not a rendered video. Each result carries the index of the decoded input frame it belongs to and one entry per tracked body in that frame: the box, 2D and 3D keypoints, confidences, joint rotations, rest pose, and root pose. All per-joint arrays have 77 entries in the Nova-77 skeleton order. For the fields and types, refer to Output Format.

Delayed Outputs

The model uses a temporal window, so pose results arrive behind the input. The server buffers approximately 120 frames before it emits the first result and sends keep-alive messages while it decodes and infers. Each result carries the index of the input frame it belongs to, so results stay frame-aligned. After the input ends, the server drains the buffered frames and sends a final response that marks the stream as flushed.

A constant frame rate is required. Tracked boxes are matched to frames by frame_id, so a variable-frame-rate clip, or a constant-rate clip with a dropped frame, is rejected with INVALID_ARGUMENT. Re-encode such a clip before sending it, for example with ffmpeg -i in.mp4 -r 30 -c:v libx264 -pix_fmt yuv420p out.mp4.

Tracked Bounding-Box Annotation Format

The client reads the tracked boxes from a text file with one row per tracked body per frame:

{number_of_tracked_bodies}
{frame_id} {tracking_id} {x} {y} {width} {height}
...
  • Line 1 is the number of tracked bodies, from 1 to 50.
  • frame_id is the index of the decoded frame, starting at 0.
  • Boxes are in full-image pixel coordinates, where x, y is the top-left corner. Integer and floating-point values are both accepted.
  • A box that overlaps a frame edge, including one with a negative origin, is passed to the model unclipped.

For example, two tracked bodies across two frames:

2
0 1 120.5 340.0 80.0 220.0
0 2 500.0 300.0 90.0 240.0
1 1 122.0 341.5 80.0 220.0
1 2 501.0 300.5 90.0 240.0

The client package ships a sample pair, assets/sample_video.mp4 and assets/sample_bbox.txt, which tracks 15 bodies over the 300 frames of the clip.

Limits

The sample client validates the annotation file before streaming any video, so an invalid file fails without a round trip to the server. The server validates the entire annotation again for every request because it does not trust the client. If it detects a violation, it ends the call with INVALID_ARGUMENT. This server-side validation is the only enforcement available to callers that use the gRPC API directly and bypass the sample client.

RuleEnforced by
At most 50 boxes per frame.Client and server
tracking_id must be unique within a frame.Server
Every coordinate must be finite.Server
A box must overlap the frame by at least one pixel.Server
Only the exact quadruple -1 -1 -1 -1 marks an absent body. The row is skipped and the frame is kept with no box on it. Any other non-positive width or height is malformed and rejected.Server (the client skips sentinel rows and sends every other row as it is)
Line 1 must be a positive tracked-body count, no greater than 50.Client
The annotation must contain at least one box.Server
At most 108,000 annotated frames and 1,000,000 boxes in total.Server

The server also guards against a malformed or hostile annotation with two ceilings no real clip approaches — 108,000 annotated frames (an hour at 30 fps) and 1,000,000 boxes in total — and answers INVALID_ARGUMENT above them.

Validation rules and silent fallbacks

  • An annotation file that covers fewer frames than the video limits the result set to the annotated frames, and the RPC succeeds. The output file still has one line per decoded frame, and a frame without an annotation carries an empty detections list. The client’s summary line, Received poses for {n} frame(s), counts only the frames that carry a body, so a count below the video’s frame count is the signal. Nothing on the wire flags it — a direct gRPC caller sees only that fewer ready responses contained bodies. If your tracker drops frames, check the annotated frame count against the video’s frame count before relying on the result count.
  • An annotation file that names frames beyond the end of the video fails with INVALID_ARGUMENT, reporting both counts, for example annotation names frame index 299 (300 frames) but the video decoded only 150 frame(s) (indices 0-149). The server knows how many frames the video holds only once it has decoded all of them, so this check completes at the end of the stream: a long clip is decoded and inferred in full, and earlier poses are returned, before the rejection arrives. Compare your annotation’s highest frame_id against the video’s real frame count before you send it.
  • Constant frame rate is required, and it is enforced. The decoder measures the interval between consecutive frames and rejects the request with INVALID_ARGUMENT when that interval varies — which includes a constant-rate clip with a single dropped frame. Because tracked boxes are addressed by frame_id, a missing frame would match every later pose to the wrong box, so the rejection is deliberate. The check needs three frames to form a verdict and fires when the deviating frame arrives, so a clip can fail part-way through after returning earlier poses. Re-encode at a constant frame rate, or trim the clip before the gap, and retry.
  • An invalid focal_length (for example NaN or a negative value) silently falls back to the SDK auto-derived default instead of raising an error.
  • Which mode a request used (see Input Modes) is only observable via server log lines (Video streamable: True/False, spooled N bytes for transactional decode) — there is no field in the response that reports it.

Quick Test with a Sample Input

To smoke-test the pipeline without a real detector or tracker, generate a short synthetic clip and a matching bounding-box file that tracks one full-frame body for every frame. Run these from nim-clients/body-pose/ with the virtual environment active; the first command moves to the scripts folder, where the client runs, and the two files land there. FFmpeg is a prerequisite; refer to Streaming Mode.

cd scripts
# Generate a 5-second, 1280x720, 30fps test clip.
ffmpeg -f lavfi -i testsrc=duration=5:size=1280x720:rate=30 -c:v libx264 -pix_fmt yuv420p quick_test.mp4
# Generate a matching tracked-bbox file: one full-frame box (tracking ID 1) per frame.
# Line 1 is the number of tracked bodies (1 here), not the number of frames.
python -c "
frames = 5 * 30
print(1)
for i in range(frames):
print(f'{i} 1 0 0 1280 720')
" > quick_test_bbox.txt

Send the pair to the NIM and write the poses to quick_test.json:

python body_pose.py --target 127.0.0.1:8001 --video-input quick_test.mp4 --bbox-input quick_test_bbox.txt --output quick_test.json

A full-frame box does not need to contain a real person; it only exercises the end-to-end path (streaming, decode, inference, output).

This is a pipeline smoke test, not a pose-quality test. For meaningful pose output, supply real tracked bounding boxes for actual people in the frame.

Do not use this 150-frame clip to measure throughput. The model buffers approximately 120 frames before the first result (see Delayed Outputs), so roughly 80% of a 150-frame run is startup fill, not steady-state processing — an fps figure computed over the whole clip will read far below the Performance Results tables, which explicitly exclude that buffering window. Benchmark with a clip of at least a few hundred frames, or measure only the post-buffer drain rate.

Expect the client to print Received poses for 150 frame(s) and exit 0. The output has 150 lines, one per frame, each carrying 77 (Nova-77) keypoints and rotations for tracking ID 1 — the model still runs on the full-frame box even though testsrc contains no person, so the values are not meaningful pose data. To count the lines:

wc -l quick_test.json

Anything else (a non-zero exit, fewer than 150 lines, or an error) means the smoke test failed.

Error Contract

Each row names the gRPC status, what triggers it, the message template, and which side raises it; a direct gRPC caller is subject to the server rows only. Placeholders in {braces} are substituted at runtime; everything outside them is literal.

Most server-side annotation rejections share one envelope:

Invalid 3D body pose input:
- <first problem>
- <second problem>

A row whose message starts with frame {frame_id}: is a bullet inside this envelope, not the whole details string, and one rejection can carry bullets from several frames: the per-frame checks — non-finite coordinates, malformed box sizes, duplicate tracking_ids and the per-frame box ceiling — are collected and reported together. The whole-annotation ceilings (MaxAnnotatedFrames, MaxAnnotatedBoxes) and the frame-overlap check stop at the first offender.

The sample client prints whatever the server returned as gRPC error: {STATUS}: {details} and exits 1. It checks its arguments and the annotation file before it connects, and prints a failure there as Configuration error: {message}, also exiting 1; the client rows below give the {message} part.

gRPC statusTrigger conditionMessage templateRaised by
INVALID_ARGUMENTFirst request carries no BodyPoseConfigFirst request must include BodyPoseConfigServer
INVALID_ARGUMENTNo tracked_bboxes in the leading requests at all. An all-sentinel annotation does not land here — see the client row below, which stops it earlierFirst request(s) must include tracked_bboxes for the video framesServer
INVALID_ARGUMENTMore than 108,000 annotated frames (one hour at 30 fps){n} annotated frames > MaxAnnotatedFrames (108000)Server
INVALID_ARGUMENTMore than 1,000,000 boxes across the whole annotation, sentinels includedannotation exceeds MaxAnnotatedBoxes (1000000) in totalServer
INVALID_ARGUMENTMore than 50 boxes in one frame, counting only the boxes that passed every other check — sentinels, malformed boxes and duplicate tracking_ids do not count towards itframe {frame_id}: {n} boxes > MaxBoxesPerFrame (50)Server (the client also rejects an over-capacity frame from the file before streaming, but counts every row except the sentinel, malformed and duplicate ones included — so it can refuse a file the server would have accepted)
INVALID_ARGUMENTtracking_id repeated within one frameframe {frame_id}: duplicate tracking_id {tracking_id} (tracking_id must be unique within a frame)Server
INVALID_ARGUMENTNaN or an infinity in x, y, width or heightframe {frame_id}: non-finite bbox coordinate(s) ({x}, {y}, {width}, {height})Server
INVALID_ARGUMENTAny non-positive width or height on a box that is not the exact -1 -1 -1 -1 sentinel — malformed, not a sentinel. 0 0 0 0 and 10 10 -1 -1 are both malformedframe {frame_id}: malformed bbox size (width={width}, height={height})Server
INVALID_ARGUMENTBox shares no pixel with the decoded frame. Checked on frame 0, once the real frame size exists, so the video header is streamed firstframe {frame_id}: bbox (x={x}, y={y}, width={width}, height={height}) lies entirely outside the {width}x{height} frame. A box that overlaps the frame at all is accepted as given, including one with a negative origin; this one shares no pixel with it.Server
INVALID_ARGUMENTAnnotation names frames the video never contained, by any number of frames. A bullet in the envelope above. The server can count the decoded frames only once the input has ended, so this check completes at the end of the stream: a long clip is decoded and inferred in full, and earlier poses are returned, before the rejection arrivesannotation names frame index {n} ({n+1} frames) but the video decoded only {m} frame(s) (indices 0-{m-1}); the tracked-bbox annotation names frames beyond what this video containsServer
INVALID_ARGUMENTCumulative video_data exceeds NV_AI4M_MAX_INPUT_FILE_SIZE_BYTES (default 1 GiB)Invalid 3D body pose input: followed by the bullet - input exceeds NV_AI4M_MAX_INPUT_FILE_SIZE_BYTES ({max_bytes} bytes) — the same envelope as the annotation errors aboveServer
INVALID_ARGUMENTNo decodable video track — a truncated or headerless uploadNo decodable video stream found in the input. The file may be truncated or the video track may be missing.Server
INVALID_ARGUMENTContainer the decoder does not recognise — the header matches neither supported signatureUnsupported video container format. Expected MP4/QuickTime or Matroska/WebM, but file header did not match either signature. Supported containers: MP4, WebM/MKV.Server
INVALID_ARGUMENTContainer header names a codec other than H.264, H.265, AV1, VP8 or VP9; nothing was decodedunsupported video codec: {codec_label}. Supported: H.264, H.265, AV1, VP8, VP9 (see Support Matrix -> Input Media).Server
INVALID_ARGUMENTContainer header states a chroma subsampling other than 4:2:0 or a bit depth other than 8 (an RGB 4:4:4 WebM, a 10-bit HDR10 MP4, …); nothing was decoded. This is the product rule and does not depend on the GPU. {codec_label} is H.264, H.265, AV1, VP8 or VP9; {chroma} is 4:2:0, 4:2:2, 4:4:4 or 4:0:0 (monochrome); {profile_suffix} is (profile N) when the header carries a profile, else empty. See Input Mediaunsupported video format: {codec_label} {chroma} {bit_depth}-bit{profile_suffix} -- this NIM accepts 4:2:0 8-bit only (SDR; HDR and 10/12-bit content are not supported). See Support Matrix -> Input Media.Server
INVALID_ARGUMENTContainer header names a codec whose 4:2:0 8-bit entry is missing from this GPU’s decoder caps — the GPU does not decode that codec at all (AV1 on a GPU without AV1 decode, say); nothing was decoded. This is the hardware rule; it is skipped when the caps are unknown. {decodable_codecs} is the comma-separated list of served codecs this GPU does decode at 4:2:0 8-bit, in the order H.264, H.265, VP8, VP9, AV1, or the word nothingunsupported video format: {codec_label} 4:2:0 8-bit -- this GPU's decoder does not decode {codec_label} (it decodes: {decodable_codecs}). See Support Matrix -> Input Media.Server
INVALID_ARGUMENTNo frame decoded within BODY_POSE_DECODE_FIRST_FRAME_TIMEOUT_SEC (default 10) of the input being ready to decode — the upload spooled, or, in streaming mode, the last chunk the decoder accepted (the clock restarts on every chunk and at end of input, so a slow upload does not trip it). The last resort when the header did not reveal the formatno video frame was decoded within {timeout:g}s of receiving the input (BODY_POSE_DECODE_FIRST_FRAME_TIMEOUT_SEC). The codec or pixel format is probably not supported by this GPU's decoder -- see Support Matrix -> Input Media. If this input decodes elsewhere, raise the timeout.Server
INVALID_ARGUMENTDecode fails in a way attributable to the bytes sentthe decoder’s own text, passed through unchangedServer
INVALID_ARGUMENTThe decoder’s frame-interval check fires: consecutive-frame spacing varies beyond max(2 ms, 5 %), which a single dropped frame in a constant-rate clip also triggers. Needs three frames to form a verdict, so this can arrive part-way through a stream — see Validation rulesVariable frame rate input is not supported. This NIM accepts constant frame rate video with no dropped frames: a single missing frame is rejected because poses either side of it would be matched to the wrong boxes. Re-encode at a constant frame rate, or trim the clip before the gap, and retry.Server
RESOURCE_EXHAUSTEDNo admission slot freed within BODY_POSE_REQUEST_ADMISSION_TIMEOUT_SEC (default 15). Nothing was read or processed, so the request is safe to resend — but resending it against an unchanged server fails identically. Serialise your streams, or raise NV_AI4M_MAX_CONCURRENCY_PER_GPU (default 1) and restartServer at capacity: all {n} admission slot(s) in use and none freed within {timeout}s (BODY_POSE_REQUEST_ADMISSION_TIMEOUT_SEC). Retrying without changing anything will fail the same way. Serialise your streams, or raise NV_AI4M_MAX_CONCURRENCY_PER_GPU on the server and restart it.Server
RESOURCE_EXHAUSTEDA single request message is larger than NV_AI4M_GRPC_MAX_MESSAGE_SIZE_BYTES (default 20 MiB) — in practice the first message, which carries the whole tracked-box annotation. gRPC refuses it before the NIM reads it, so the text is gRPC’s own: {n} is the message size and {m} the limit. The sample client sends the whole annotation in its first message, so raise NV_AI4M_GRPC_MAX_MESSAGE_SIZE_BYTES on the server above {n} (refer to Advanced Tuning Variables), or process the clip in shorter segments. A direct gRPC caller can also split the annotation across several requests, each under the limit, sent no later than the first video_data chunk (refer to Input and Output)SERVER: Received message larger than max ({n} vs. {m}). The sample client prints it as gRPC error: RESOURCE_EXHAUSTED: SERVER: Received message larger than max ({n} vs. {m}), followed by Hint: the annotation is sent as one message and exceeds the server's size limit. Raise NV_AI4M_GRPC_MAX_MESSAGE_SIZE_BYTES on the server, or process the clip in shorter segments.Server (gRPC)
(none — accepted, with a warning)enable_contact differs from the value this server was started with. The stream is processed with the server’s value; the text below is sent as the warning entry of the response’s initial metadata and logged by the server. Retrying against the same server repeats it — use a server started with the value you needenable_contact={requested} requested, but this server runs with enable_contact={loaded}, which is fixed for its lifetime. Processing with enable_contact={loaded}. For enable_contact={requested}, use a server started with BODY_POSE_ENABLE_CONTACT={0 or 1}.Server
INTERNALAny other server-side fault. This is the retryable bucket by construction: only the caller-attributable exception types above become INVALID_ARGUMENT, everything else stays INTERNALServer error: {ExceptionType}: {message}Server
DEADLINE_EXCEEDEDThe client’s own RPC deadline expires. A deadline shorter than the admission timeout reports this instead of RESOURCE_EXHAUSTED and hides the real cause; the sample client’s --timeout defaults to 3600 sgRPC’s own textClient deadline
UNAVAILABLEThe client could not connect: the NIM is not running, or is still loading and its gRPC port does not accept connections yet; --target names the HTTP port (8000) instead of the gRPC port (8001); or --ssl-mode does not match the server’s NIM_SSL_MODEgRPC’s own textClient connection
(none — accepted)Box overlaps a frame edge, including a negative originnone; passed to the model unclipped. This is the contract, not a tolerance—
(none — accepted)The exact quadruple -1 -1 -1 -1none; the absent-body sentinel. The client skips the row, the server drops the box, and the frame is kept with no box on it. Any other non-positive extent is malformed, and is rejected by the malformed bbox size row above—
(none — accepted)Annotation covers fewer frames than the videonone on the wire; the output keeps one line per decoded frame, with an empty detections list on each frame that has no box, and the client’s summary line Received poses for {n} frame(s) counts only the frames that carry a body—
(none — accepted)focal_length is NaN, negative or zeronone; silently resolves the same way an absent value doesServer
(client, exit 1)Line 1 of the annotation file is not a number, or is not between 1 and 50{path}: line 1 must be the number of tracked bodies, between 1 and 50Client, before connecting
(client, exit 1)A data row does not have exactly 6 fields{path}: line {lineno} has {n} fields, expected 6 (frame_id tracking_id x y w h)Client, before connecting
(client, exit 1)A data row has 6 fields but one will not parse as a number{path}: line {lineno}: {reason}Client, before connecting
(client, exit 1)One or more frames carry more than 50 boxes, not counting -1 -1 -1 -1 sentinel rows{path}: {n} frame(s) have more than 50 boxes, starting with frame {frame_id}Client, before connecting
(client, exit 1)Every data row is the exact -1 -1 -1 -1 absent-body sentinel, so the annotation carries no box. A row that is merely non-positive is not a sentinel: it is streamed, and the server rejects it as malformed{path}: no bounding box to send, every row is absentClient, before connecting
(client, exit 1)--video-input or --bbox-input names a file that does not existFile '{path}' not foundClient, before connecting
(client, exit 1)A file has an extension the client does not acceptOnly MP4, WebM and MKV video files are supported, Only TXT format is supported for the bounding-box file, Output pose file must have a .json extension, or Overlay output file must have a .mp4 extensionClient, before connecting
(client, exit 1)--overlay-output names the input videoOverlay output file must differ from the input videoClient, before connecting
(client, exit 1)--client-session-id is not printable ASCII--client-session-id must be printable ASCIIClient, before connecting
(client, exit 1)The stream failed after poses were already writtenIncomplete output moved to {output}.partial, on stderr, before the gRPC error: lineClient
(client, exit 1)The stream completed but no frame contained a bodyError: The server returned no poses; check the server log. An output file already opened is renamed .partial too, with the line aboveClient
(startup — no RPC)SSL files unreadable by the container’s uid 1000ERROR:inference:SSL configuration is invalid; refusing to start. / nimlib.exceptions.SSLConfigurationError: Error verifying SSL files: [Errno 13] Permission deniedServer, refuses to start
(startup — no RPC)NIM_MODEL_PROFILE pinned to a profile that does not match the GPUModel validation failed after {n}s (gpu_cc={cc}, model_dir={model_dir}). — the container exits once NV_AI4M_MODEL_READY_TIMEOUT_S (default 120 seconds) expires, before it ever becomes ready. Refer to Model Manifest ProfilesServer, exits
(startup — no RPC)A model directory, or an *.engine.trtpkg inside it, that the container’s uid 1000 cannot read (e.g. chmod 000 on the host). This is the read-permission case, distinct from the cache write-permission row below; it fails immediately rather than waiting out NV_AI4M_MODEL_READY_TIMEOUT_S, which a missing or truncated asset still doesModel asset(s) unreadable by this container's uid ({uid}): {paths}. ... Fix the permissions on the host (chmod a+rX) and restart.Server, exits 1
(startup — no RPC)LOCAL_NIM_CACHE not writable by the container’s uid (e.g. chmod 700)ManifestDownloadError: Error downloading manifest: I/O error Permission denied (os error 13) — the container exits 1 before it ever listens. See Launching the NIM ContainerServer, exits
(startup — no RPC)The key in NGC_API_KEY cannot read the model on NGCManifestDownloadError: ... Guest access denied ... set a valid NGC_API_KEYServer, exits

Run Inference Using a Python Script

Run the client from the scripts folder (nim-clients/body-pose/scripts/), with the virtual environment active:

python body_pose.py \
--target <server_ip:port> \
--video-input <input_video_file_path> \
--bbox-input <tracked_bbox_file_path> \
--output <output_pose_file_path>

To view details of all command-line arguments, run:

python body_pose.py -h

The first request after the container reaches SERVING takes slightly longer than the following ones because of one-time connection setup. Subsequent requests reflect the actual processing performance.

Command-Line Arguments

ArgumentDefault ValueRequired?Description
-h, --helpn/aOptionalShow help and exit.
--target127.0.0.1:8001Optionalhost:port of the gRPC service.
--video-input../assets/sample_video.mp4OptionalPath to the input video file (.mp4, .webm, or .mkv).
--bbox-input../assets/sample_bbox.txtOptionalPath to the tracked bounding-box annotation file (.txt). Refer to Tracked Bounding-Box Annotation Format.
--outputbody_pose_output.jsonOptionalPose output path. The output is JSON Lines, one object per frame, and the path must end in .json. Refer to Output Format.
--overlay-outputNoneOptionalAlso render the skeleton overlay onto the input video and write it to this path (.mp4). Refer to Render the Skeleton Overlay.
--draw-keypointsbothOptionalKeypoints drawn on the overlay: 2d, 3d, or both.
--focal-length0.0OptionalPinhole focal length in pixels. 0 uses the default derived from the image size. Refer to Focal Length.
--enable-contact / --no-enable-contactUnsetOptionalRequest contact correction on or off. Unset accepts the server’s setting. Refer to Contact Correction.
--timeout3600.0OptionalRPC deadline in seconds. 0 disables the deadline.
--client-session-idNoneOptionalA session identifier of your own, printable ASCII only, sent as gRPC metadata (client-session-id). The server echoes it in the ServiceInfo message. Refer to Service Information in the Response. A value that is not printable ASCII is refused before the client connects, with Configuration error: --client-session-id must be printable ASCII.
--ssl-modeDISABLEDOptionalDISABLED, TLS, or MTLS. Must match the server’s NIM_SSL_MODE. Refer to SSL Enablement.
--ssl-root-cert../ssl_key/ssl_ca_cert.pemOptionalCA certificate (PEM) that signed the server’s certificate. Used with TLS and MTLS.
--ssl-cert../ssl_key/ssl_cert_client.pemOptionalClient certificate (PEM). Used with MTLS.
--ssl-key../ssl_key/ssl_key_client.pemOptionalClient private key (PEM). Used with MTLS.
--preview-modeFalseOptionalSend the request to the preview NVCF endpoint instead of a self-hosted NIM. Requires --api-key and --function-id.
--api-keyNoneOptionalNGC API key. Required with --preview-mode.
--function-idNoneOptionalNVCF function ID. Required with --preview-mode.

Example Commands

The shipped sample is 300 frames at 1080p50 with 15 tracked bodies, so it takes far longer than the Quick Test: from under a minute to a few minutes, depending on the GPU. Because results are delayed by the model’s temporal window (refer to Delayed Outputs), the client prints the service-info banner and one Buffering: line, then nothing more while the server fills its window; the poses then arrive frame-aligned behind the input. In an interactive terminal, a Receiving poses progress bar counts the frames as they arrive. When the output is not a terminal, for example when a script captures it, the client prints nothing after the Buffering line until the stream completes and it prints its summary. That is the expected shape of a run, not a stall.

  • Estimate poses for the sample clip and write JSON Lines:

    python body_pose.py --target 127.0.0.1:8001 --video-input ../assets/sample_video.mp4 --bbox-input ../assets/sample_bbox.txt --output body_pose_output.json
  • Also render the skeleton overlay onto the input video:

    python body_pose.py --target 127.0.0.1:8001 --video-input ../assets/sample_video.mp4 --bbox-input ../assets/sample_bbox.txt --output body_pose_output.json --overlay-output body_pose_overlay.mp4
  • Supply a known camera focal length, in pixels:

    python body_pose.py --target 127.0.0.1:8001 --video-input ../assets/sample_video.mp4 --bbox-input ../assets/sample_bbox.txt --output body_pose_output.json --focal-length 1200

Render the Skeleton Overlay

--overlay-output renders the Nova-77 skeleton onto the input video once the stream completes. The client reads the input video locally with OpenCV, draws each frame’s poses, and writes an MP4 with the same frame size and frame rate. 2D keypoints are drawn in green, 3D keypoints reprojected with a pinhole camera in red, and each tracked box in a per-track color with its ID. --draw-keypoints 2d or --draw-keypoints 3d draws only one of the two keypoint sets. For the command, refer to Example Commands.

When it finishes, the client prints Overlay video written to {path} ({n} frames). The pose output file is written as usual.

Supported Formats

Format typeSupported formats
Video inputH.264 (preferred), H.265, AV1, VP8, or VP9, in an MP4 or WebM/Matroska container. 4:2:0 chroma, 8-bit, SDR (HDR is not supported), constant frame rate. For the rejection messages, refer to Input Media.
Bounding-box inputPlain text. Refer to Tracked Bounding-Box Annotation Format.
Pose outputJSON Lines (.json), one object per frame. Refer to Output Format.
Overlay outputMP4 (.mp4), written only when --overlay-output is set.

A constant frame rate is required, and the requirement is enforced. Tracked boxes are matched to frames by frame_id, so a variable-frame-rate clip, or a constant-rate clip with a dropped frame, is rejected with INVALID_ARGUMENT. Re-encode before sending, for example with ffmpeg -i in.mp4 -r 30 -c:v libx264 -pix_fmt yuv420p out.mp4.

By default, the NIM accepts input videos up to 1 GiB. To change the limit, set NV_AI4M_MAX_INPUT_FILE_SIZE_BYTES on the container, as described in Environment Variables.

Output Format

Every per-joint array follows this Nova-77 joint order. The client package ships the same image as assets/nova77_skeleton.png.
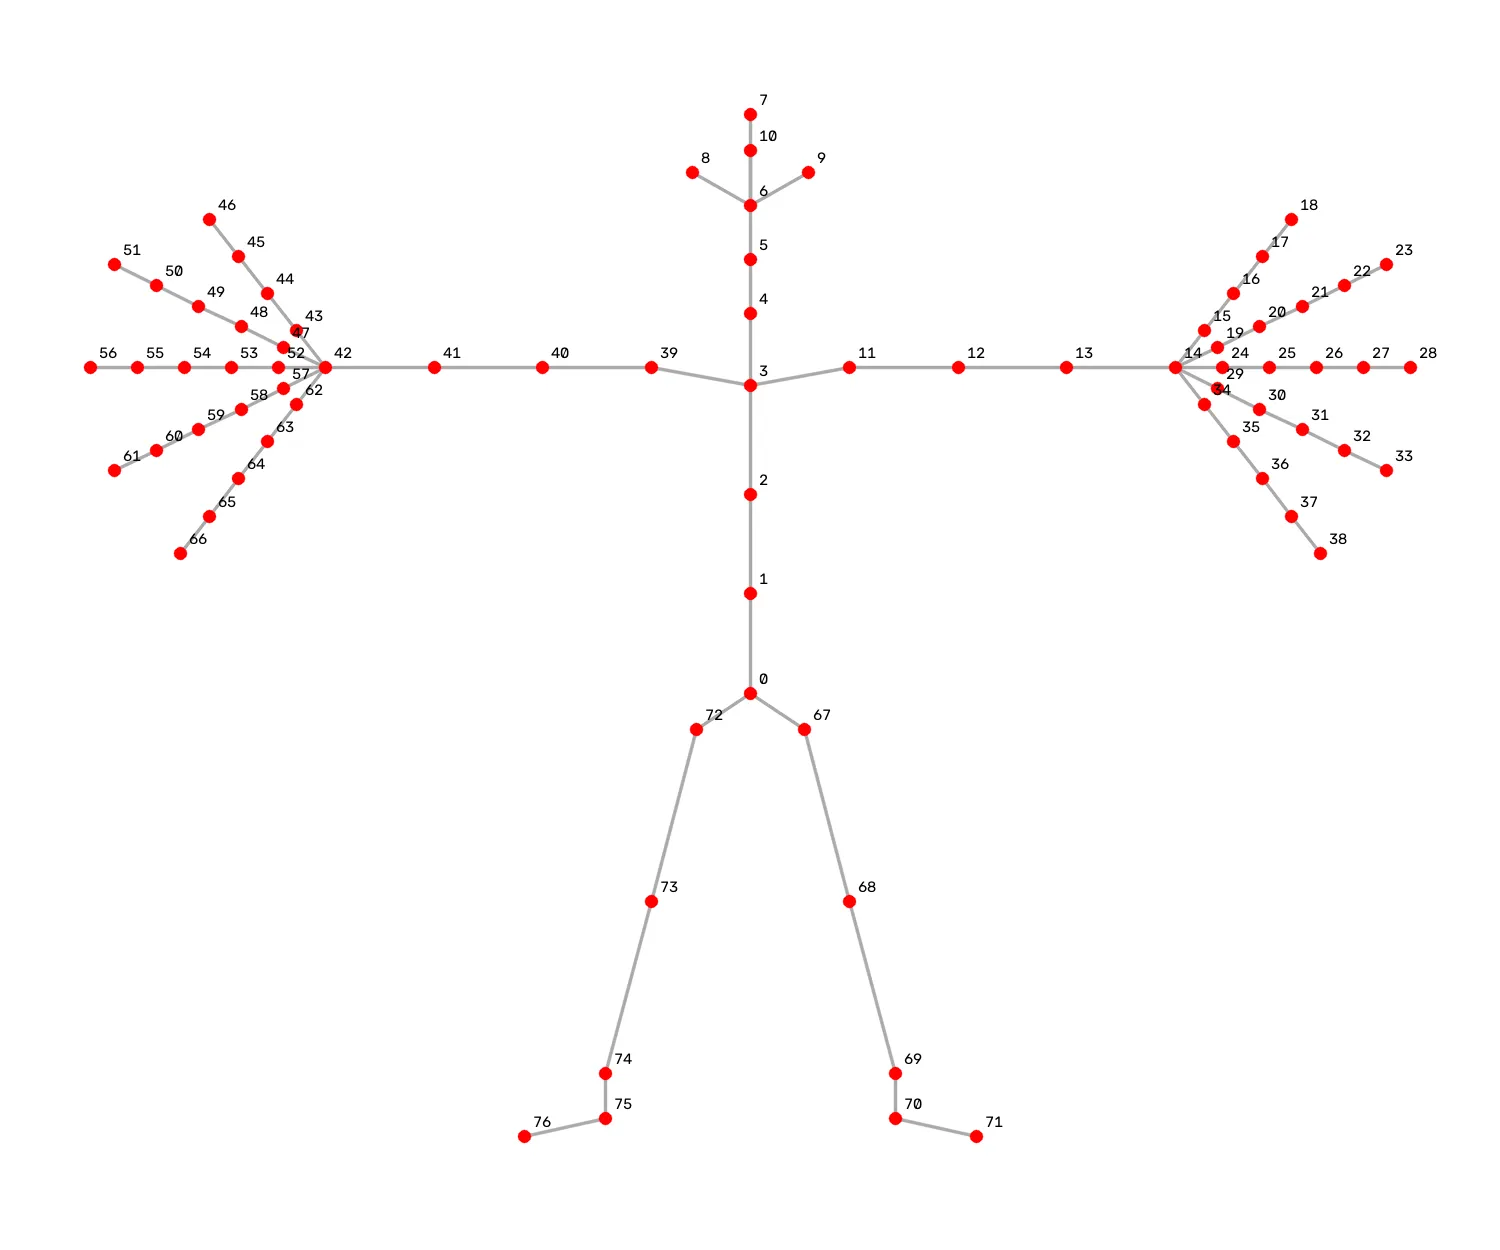
Nova-77 skeleton joint layout

The client writes JSON Lines: one JSON object per line, one line for each frame the server returned, in frame order. Each line carries the frame index and one entry per tracked body in that frame:

{"frame_id": 0, "detections": [{"tracking_id": 1, "bbox": [x, y, w, h], "keypoints_2d": [[x, y], ...], "keypoints_confidence": [c, ...], "keypoints_3d": [[x, y, z], ...], "rest_pose": [[x, y, z], ...], "joint_rotations": [[x, y, z, w], ...], "root_pose": {"translation": [x, y, z], "rotation": [x, y, z, w]}}]}
FieldTypeDescription
frame_idintegerIndex of the decoded input frame this line belongs to, starting at 0.
detectionslistOne entry per tracked body in the frame. Empty for a frame that has no box in the annotation.
tracking_idintegerTracking ID carried through from your bounding-box annotation.
bbox4 numbersThe tracked box this pose was estimated from, as [x, y, width, height] in pixels.
keypoints_2d77 × 2 numbersPer-joint 2D keypoints, in image pixels.
keypoints_confidence77 numbersPer-joint confidence scores. Values slightly above 1.0 can occur, so use them for relative thresholding within a frame.
keypoints_3d77 × 3 numbersPer-joint 3D joint positions, in meters, in camera coordinates.
rest_pose77 × 3 numbersModel-predicted rest-pose joint positions, root-relative, in meters.
joint_rotations77 × 4 numbersPer-joint local rotations relative to the rest pose, as normalized quaternions [x, y, z, w].
root_poseobjectRoot pose in camera coordinates: translation [x, y, z] in meters and rotation as a quaternion [x, y, z, w].

To read the file in Python, parse one line at a time. For example, to print the number of frames and the number of bodies in the first frame of body_pose_output.json:

python -c "
import json
with open('body_pose_output.json') as f:
frames = [json.loads(line) for line in f]
print(len(frames), 'frames;', len(frames[0]['detections']), 'bodies in frame', frames[0]['frame_id'])
"

Input Modes

The NIM detects whether the input video is streamable and selects the corresponding mode automatically.

Streaming ModeTransactional Mode
When it is usedThe input is a streamable MP4: the moov atom precedes the mdat atom.The input is a non-streamable MP4, or any WebM/Matroska input.
BehaviorThe NIM decodes and infers on chunks as they arrive, and returns results before the whole file has been received.The NIM buffers the whole input file before processing begins.
RecommendationRecommended.Use only when the input cannot be made streamable.

Streaming Mode

To convert an existing MP4 into a streamable one, move the moov atom to the front of the file with FFmpeg.

FFmpeg is a prerequisite for this step and for the transcode in Input Media. It runs on your own machine to prepare a clip before you send it; it is not part of the NIM and is not installed in the container. Check with ffmpeg -version, and if it is missing, install it from your distribution’s package manager or from a build listed at ffmpeg.org/download.html.

The shipped assets/sample_video.mp4 is not streamable, so it runs in transactional mode as shipped. From the scripts folder, convert it:

ffmpeg -i ../assets/sample_video.mp4 -c copy -movflags +faststart sample_video_streamable.mp4

You can then specify the streamable video as input to the NIM:

python body_pose.py --target 127.0.0.1:8001 --video-input sample_video_streamable.mp4 --bbox-input ../assets/sample_bbox.txt --output body_pose_output.json

Transactional Mode

If the input video is not streamable, the NIM waits until the complete file is received before it decodes and infers. No client change is needed; the server selects the mode.

For best performance, convert your videos to a streamable format so that the NIM can use streaming mode. Refer to the FFmpeg command earlier on this page.