

Topograph Slinky Engine
Overview
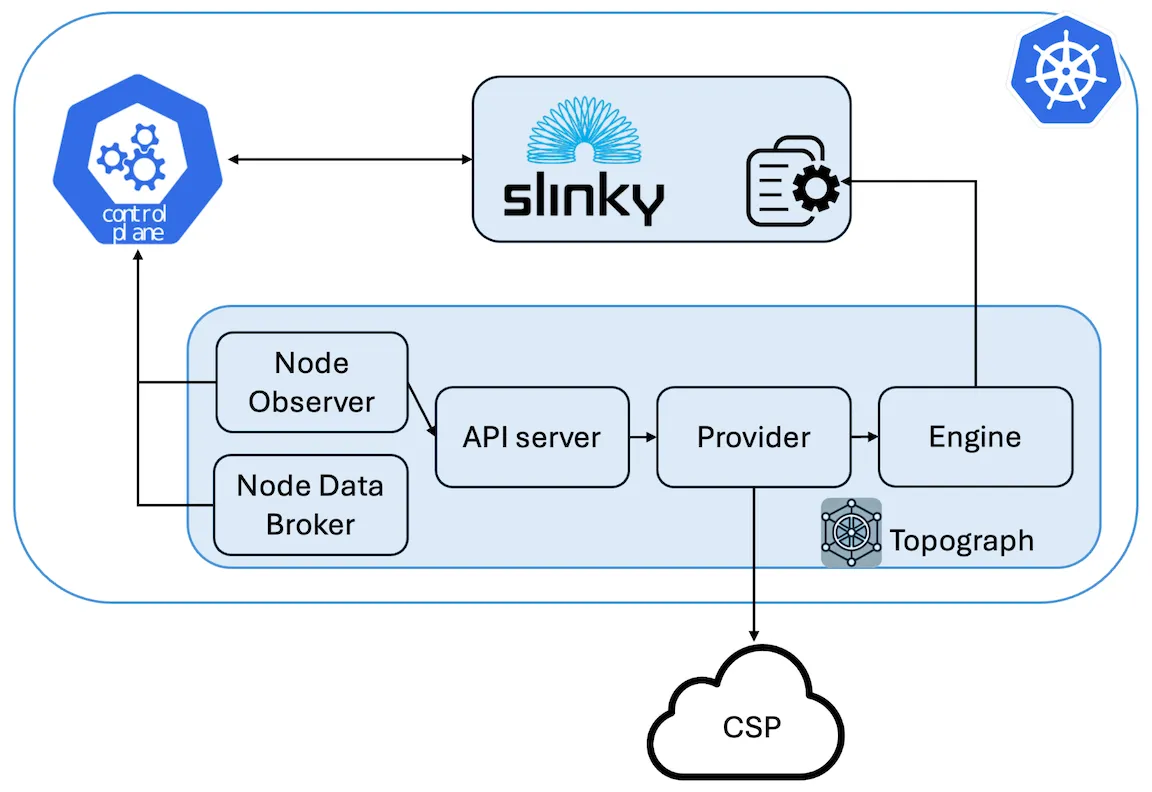
The slinky engine is Topograph’s engine for SLURM clusters running on Kubernetes. It is designed to work with the Slinky project - an open-source set of integration tools by SchedMD that brings SLURM capabilities into Kubernetes environments.
While the Slinky project provides comprehensive SLURM-on-Kubernetes orchestration (operators, schedulers, exporters, etc.), Topograph’s slinky engine complements this ecosystem by providing topology discovery and configuration management for SLURM clusters running in Kubernetes.
The Slinky engine bridges the gap between Kubernetes infrastructure and SLURM workload management by updating SLURM topology configurations stored in Kubernetes ConfigMaps.
How It Works
- Node Discovery: Queries Kubernetes nodes and SLURM pods to build a topology map
- Topology Generation: Creates SLURM topology configuration (tree or block format)
- ConfigMap Management: Updates the specified ConfigMap with new topology data including metadata annotations for tracking and debugging
Configuration
Topograph is deployed as a standard Kubernetes application using a Helm chart.
Topograph is configured using a configuration file stored in a ConfigMap and mounted to the Topograph container at /etc/topograph/topograph-config.yaml.
In addition, when sending a topology request, the request payload includes additional parameters.
The parameters for the configuration file and topology request are defined in the global section of the Helm values file, as shown below:
Shared with the Kubernetes engine: because the Topograph API server runs as a Kubernetes workload regardless of the engine, anything about the chart’s deployment surface — values-schema validation,
helm testhooks, access patterns (ClusterIP port-forward, Ingress, Gateway APIHTTPRoute), PrometheusServiceMonitor,NetworkPolicyguidance, and the chart’sREADME.md— is shared with the Kubernetes engine and documented authoritatively inengines/k8s.mdandengines/k8s.md#exposing-the-topograph-api. Those sections apply equally to Slinky deployments.
Per-partition topologies
When per-partition topologies are configured, each entry may declare how its node membership is resolved:
nodes and podSelector are mutually exclusive on the same entry; configuring both returns a validation error at engine load time.
Using nvidia.com/gpu.clique for block topology
On MNNVL Kubernetes clusters, the NVIDIA GPU Operator can label nodes with nvidia.com/gpu.clique. When useGpuCliqueLabel is enabled, the Slinky engine uses that label as the source for topology/block domains instead of the accelerator domains returned by the provider. This is useful with cloud API providers whose InstanceTopology.AcceleratorID describes a broader provider domain than the GPU Operator clique label.
The option only affects block topology. Tree topology still comes from the selected provider, and the engine still maps Kubernetes nodes to Slurm nodes through the configured slurmd pod selector.
If useGpuCliqueLabel is enabled for a block topology and no matching nodes have the nvidia.com/gpu.clique label plus the Topograph instance annotation, topology generation fails with a 502 error instead of falling back to provider accelerator domains.
ConfigMap Annotations
Slinky automatically adds metadata annotations to managed ConfigMaps for improved observability:
Annotation Reference
Usage Examples
Topograph runs autonomously in Kubernetes environments, including Slinky. When the Node Observer detects a selected node or pod change, or sees the Topograph API server become ready after startup or a container restart, it sends topology requests to the API server. The API server then triggers an update to the network topology information within the cluster. However, if you want to manually trigger network topology discovery, you can send HTTP requests to the API server, as shown below.