

Attention
Scaled Dot Product Attention
This operation computes the scaled dot product attention (SDPA), as
using the FlashAttention-2 algorithm as described in the paper FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning. It is applicable for both training and inference phases, with an option to generate a stats tensor to be used for backwards training computation.
Support Matrix
cudnn SDPA operation requires SM80 (Ampere) or newer architectures and cuda toolkit 12.x or newer.
The support matrix is based on the latest cudnn backend version 9.18.1
Glossary
¹ Interleaved q,k,v tensors. Generally they have layouts as BS3HD, B3SHD.
² Padded, variable length sequences (requires padding mask). When sequences in a batch have different lengths, use use_padding_mask=True with sequence length tensors.
Setup:
- Set use_padding_mask=True
- Provide seq_len_q tensor of shape (B, 1, 1, 1) with actual query sequence lengths
- Provide seq_len_kv tensor of shape (B, 1, 1, 1) with actual key/value sequence lengths
Example:
Batch with sequences “aa” (length 2) and “bbb” (length 3), max length S=8:
seq_len_q = [2, 3]seq_len_kv = [2, 3]- Dimensions:
- Strides: (standard BHSD)
cuDNN automatically masks out padding tokens during attention computation.
³ Ragged Layout.
For memory efficiency, variable-length sequences can be packed together without padding. This is called THD layout where is the total number of valid tokens.
Requirements:
- Must set ragged offset tensor via
tensor.set_ragged_offset(ragged_offset_tensor)
Ragged Offset Tensor:
- Shape:
- Contains cumulative token offsets in elements (not bytes)
- Last element is the total number of tokens
Ragged Offset Multiplier (cuDNN 9.24+, UNIFIED forward only):
tensor.set_ragged_offset_multiplier(value)lets the ragged offsets be stored in coarser units; the engine multiplies each offset byvalueto recover element offsets.max_total_seq_len_q/max_total_seq_len_kvdeclare the packed token totals of the ragged Q and K/V. A ragged tensor’s dims stay(B, H, S_max, D)and the per-sequence starts live in a device-side offset tensor, so the packed total is not otherwise expressible in the graph. Supplying it lets the implementation bound the token axis exactly rather than inferring an upper bound from the bound buffers’ extents — which matters when a buffer is allocated larger than the tokens it holds, since rows past the real total are masked but still take part inP @ Vand so must be finite. The values only ever tighten the inferred bound, never widen it, and are accepted only on a ragged layout.sdpa_backwardhas taken the same two arguments since cuDNN 9.6.- Example: with a multiplier of , a token-unit cumulative-sequence-length tensor (e.g.
cu_seq_len_q) can be bound directly as the ragged offset, avoiding a conversion pass.
Memory Layout visualization:
Example:
Same sequences “aa” and “bbb” packed together:
-
seq_len_q = [2, 3] -
seq_len_kv = [2, 3] -
Dimensions: (S is still max sequence length)
-
Strides: (strides unchanged, but ignored for ragged)
-
Ragged offset:
Partially Packed Layout:
Tokens within each batch can be contiguous without being globally packed.
- Ragged offset:
Not Supported:
Tokens that are not contiguous within a batch cannot be represented.
seq_len_q = [2, 3]
Note that Q,K,V and their gradients can be individually ragged or not.
Backward Pass with THD:
When using THD layout with cudnn, maximum total tokens are needed for efficient workspace allocation. If not set, defaults to which may overallocate memory.
⁴ None, Causal, Sliding window, Additive Bias, Softcap, Arbitrary masking.
⁵ d_qo should be equal to d_kv. (Except when d_qk == 192 and d_vo = 128, which is also supported.)
Important Notes on Support Surface
- All attention flavors MHA, MQA, GQA are supported.
- The head dim (d) should be a multiple of 8 for fp16/bf16 and multiple of 16 for fp8 data-types.
- The seqlens s_q, and s_kv can have arbitrary value.
- The layout of q,k,v,o and dq, dk, dv, do can be independent of each other.
- Dropout: Randomly zeros some of the attention weights after the softmax as a form of regularization.
You can configure dropout in two ways:
- Philox RNG dropout (more performant): Provide:
- An RNG seed tensor (INT32 or INT64)
- An RNG offset tensor (INT32 or INT64)
- A float representing the dropout probability (probability that any weight is set to zero)
- (Debug only) Output RNG dump tensor to capture the generated dropout mask
- Custom dropout mask: Provide:
- A
dropout masktensor matching the attention weights’ dimensions. Dimensions set to 1 will broadcast. - A
dropout scaletensor to adjust remaining weights, typically .
- A
- Philox RNG dropout (more performant): Provide:
- Stats from fprop is supported (Max, Sum). In addition QKClip required for KimiK2, Qwen are also supported optionally.
Benchmarks
To run the sdpa benchmarks, refer to benchmarks/sdpa folder. Current results:
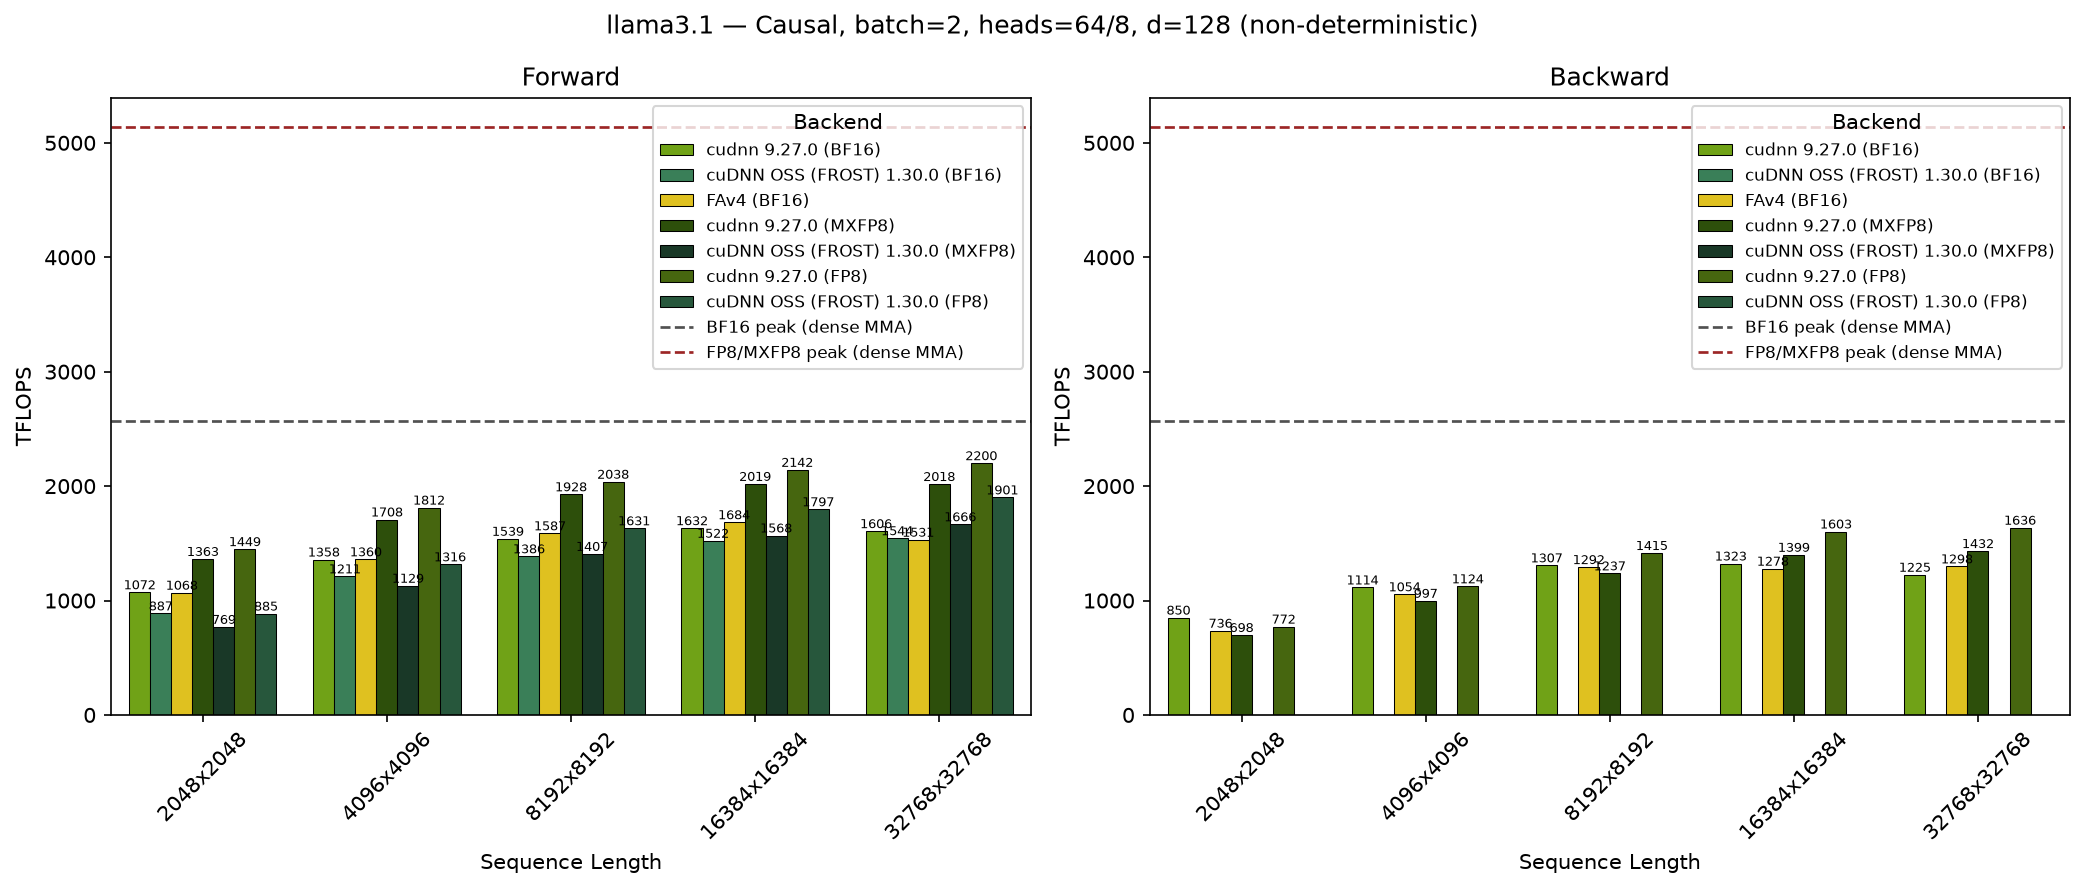
GB200 - Llama 3.1 Causal (top_left)
- SDPA parameters:
batch=1; num_q_heads=64; num_kv_heads=8; head_dim=128; is_causal=True - Sequence lengths shown on x-axis
- Results obtained on NVIDIA GB200 GPU
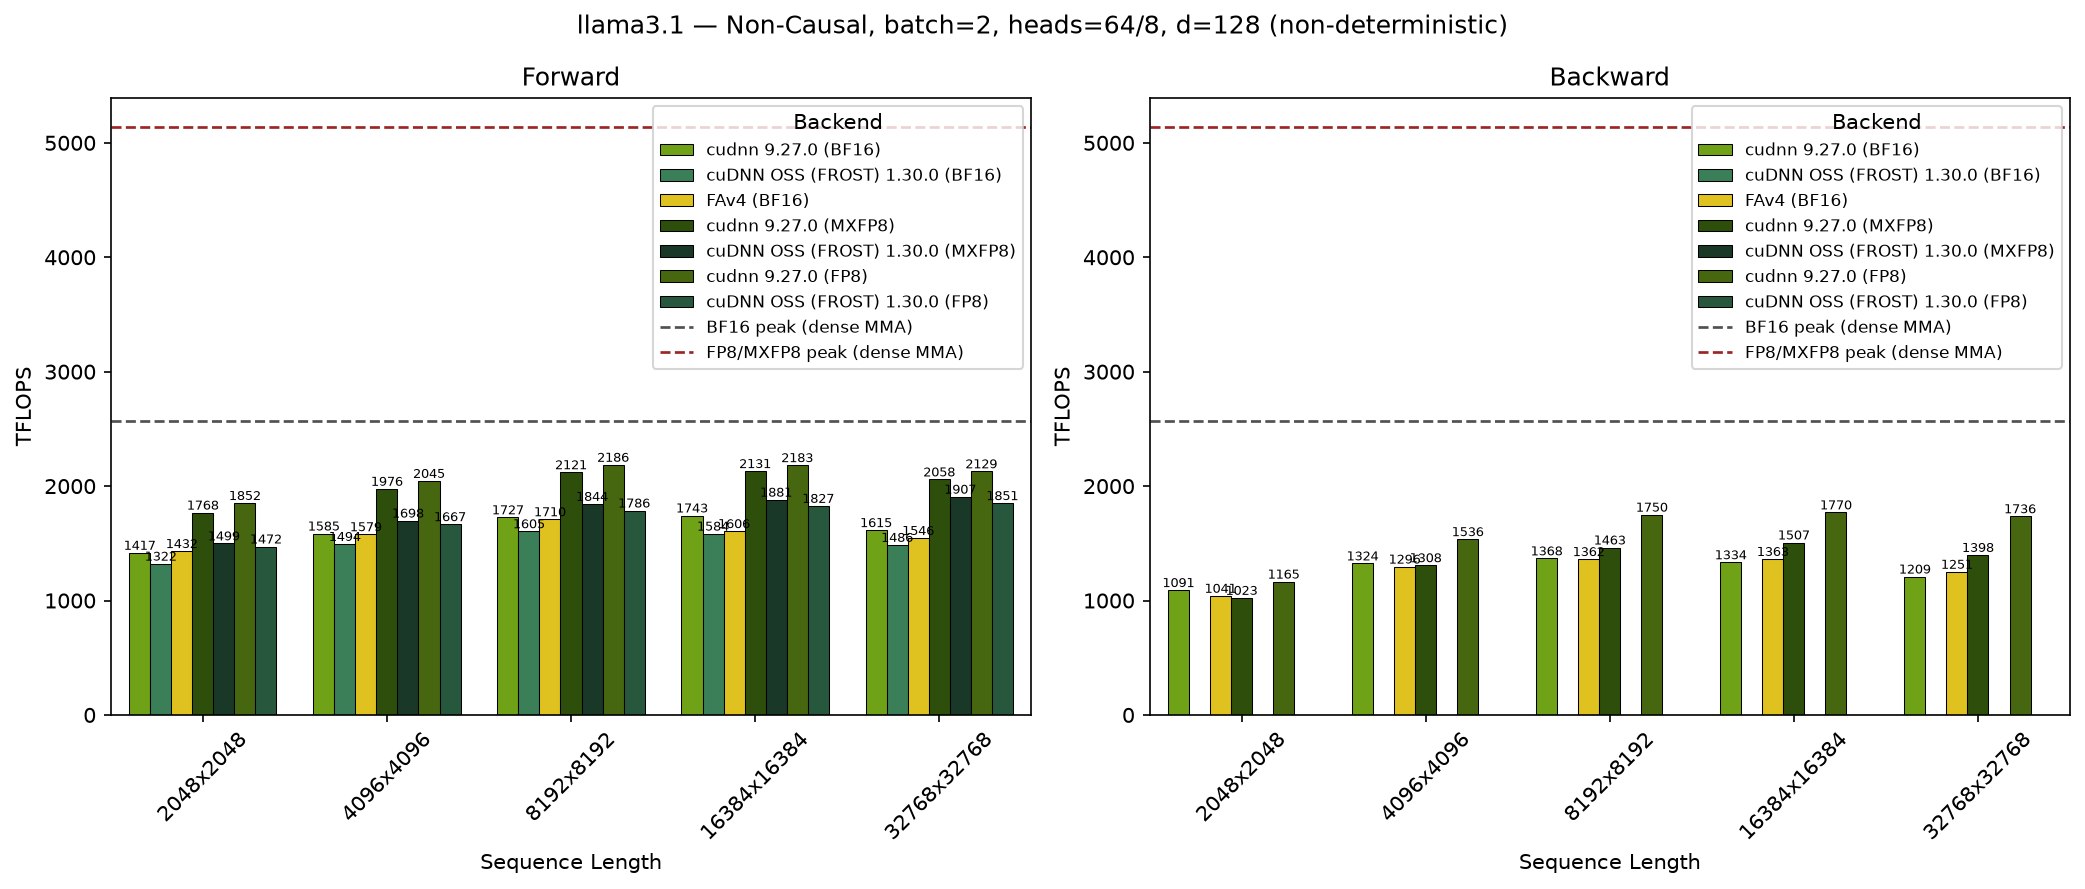
GB200 - Llama 3.1 Non-Causal (no_mask)
- SDPA parameters:
batch=1; num_q_heads=64; num_kv_heads=8; head_dim=128; is_causal=False - Sequence lengths shown on x-axis
- Results obtained on NVIDIA GB200 GPU
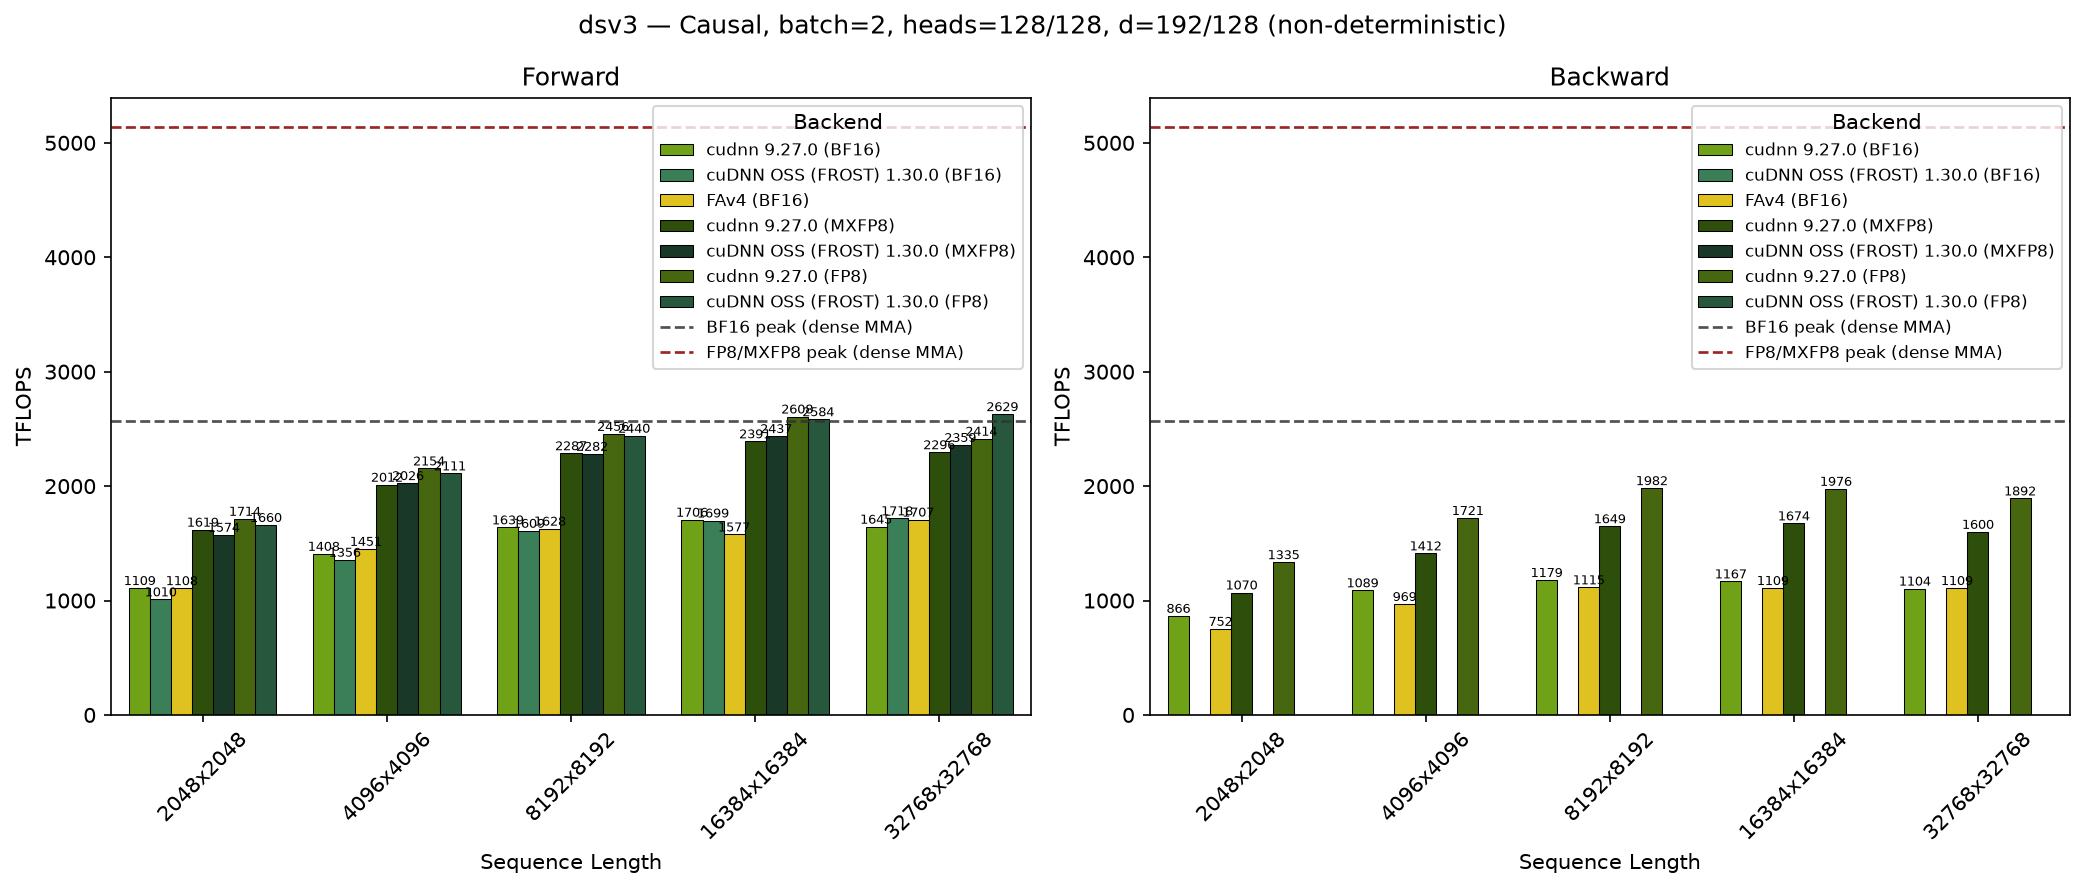
GB200 - DeepSeek V3 Causal (top_left)
- SDPA parameters:
batch=1; num_q_heads=128; num_kv_heads=128; head_dim_qk=192; head_dim_vo=128; is_causal=True - Sequence lengths shown on x-axis
- Results obtained on NVIDIA GB200 GPU
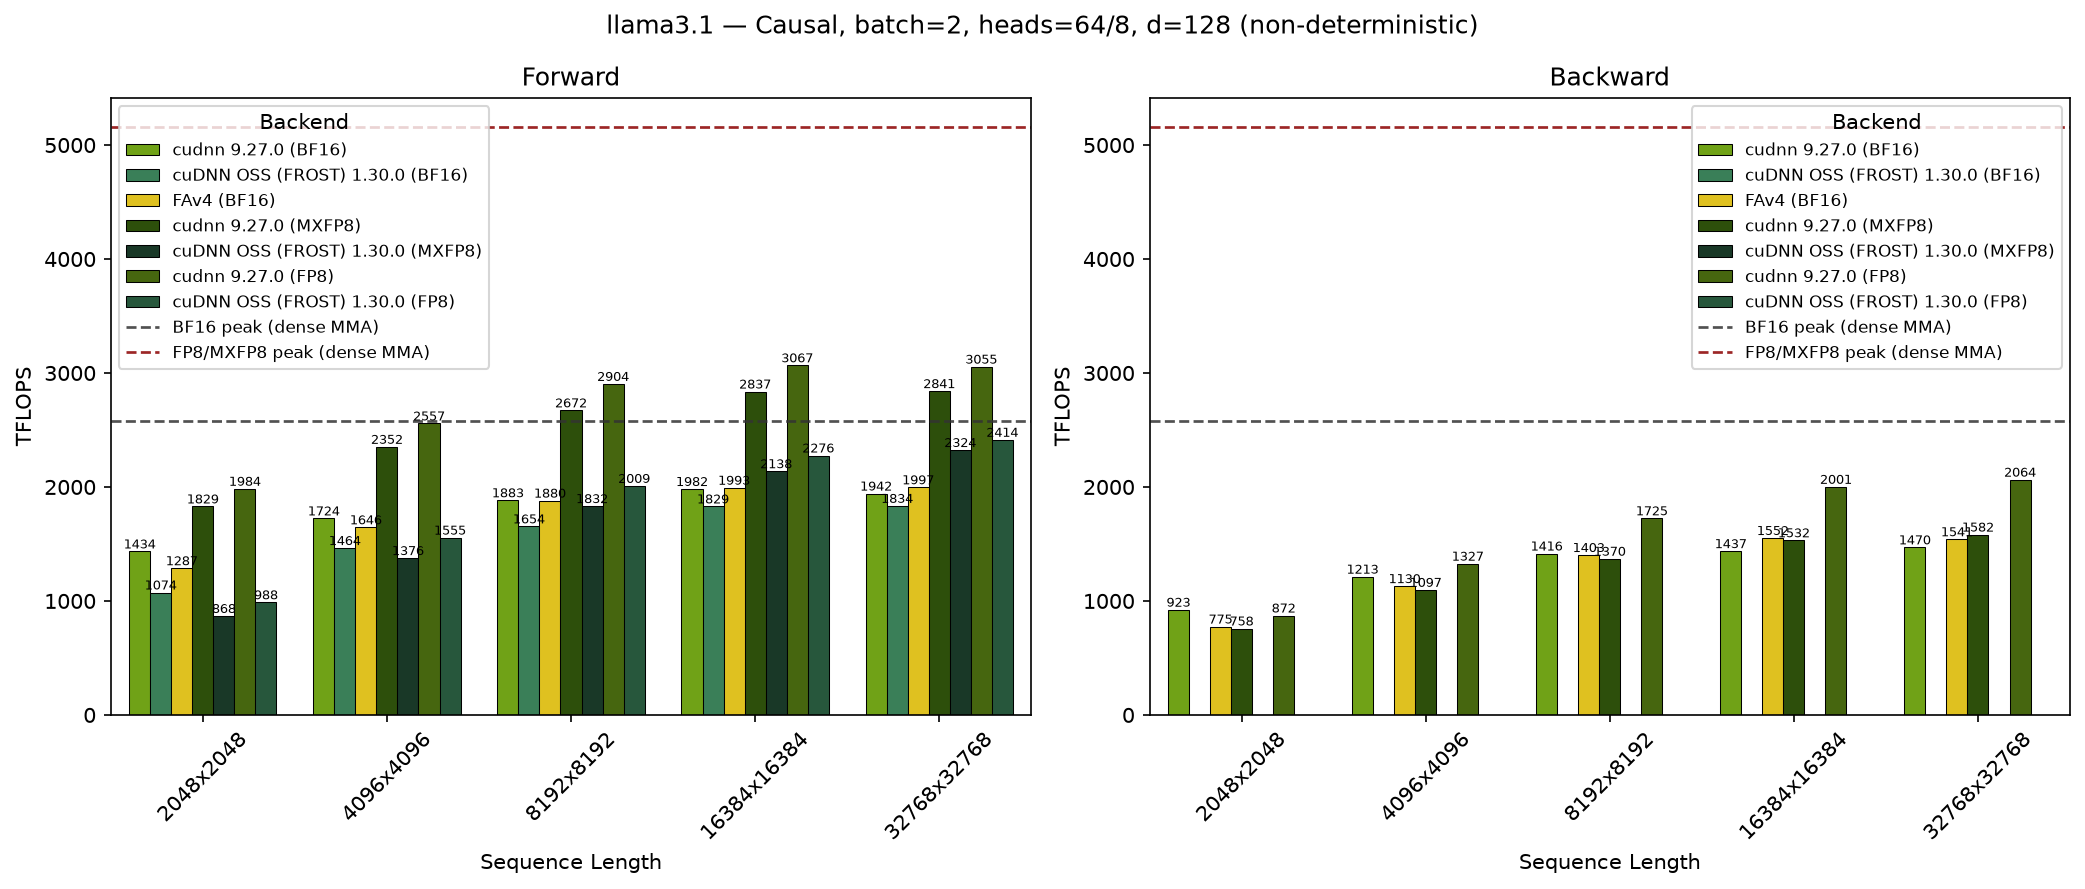
GB300 - Llama 3.1 Causal (top_left)
- SDPA parameters:
batch=1; num_q_heads=64; num_kv_heads=8; head_dim=128; is_causal=True - Sequence lengths shown on x-axis
- Results obtained on NVIDIA GB300 GPU
GB300 - Llama 3.1 Non-Causal (no_mask)
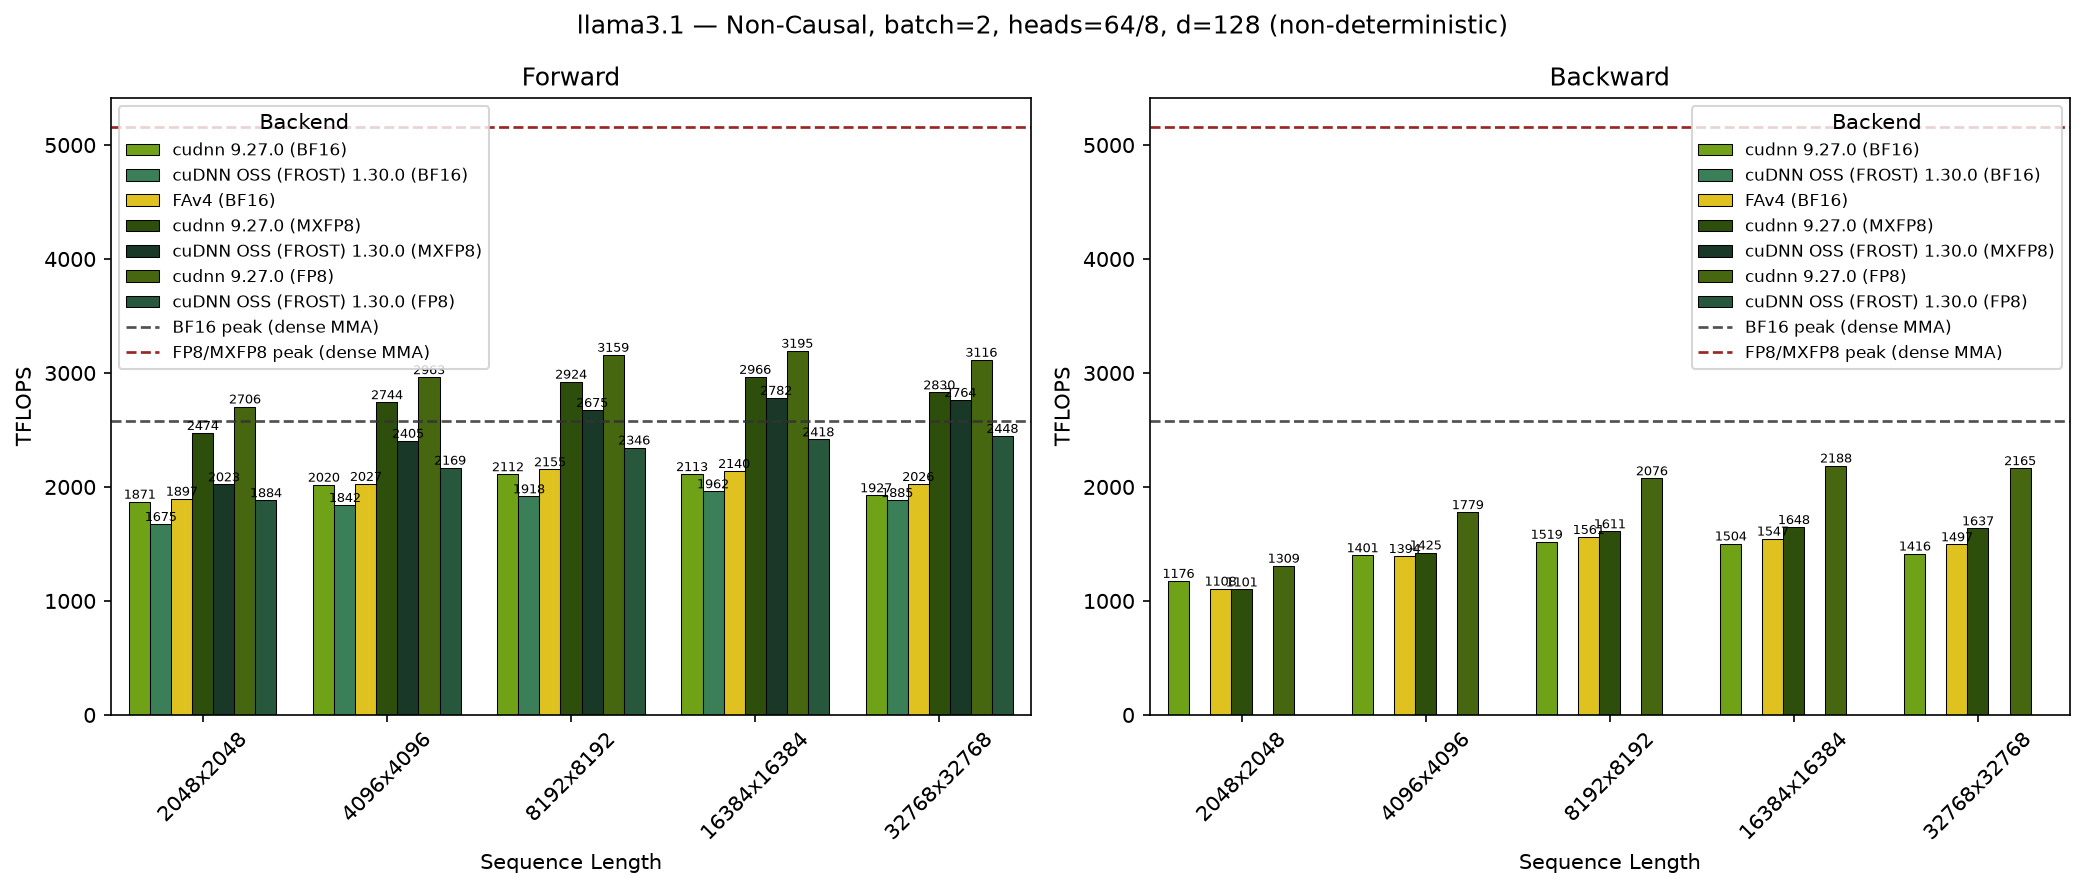
- SDPA parameters:
batch=1; num_q_heads=64; num_kv_heads=8; head_dim=128; is_causal=False - Sequence lengths shown on x-axis
- Results obtained on NVIDIA GB300 GPU
GB300 - DeepSeek V3 Causal (top_left)
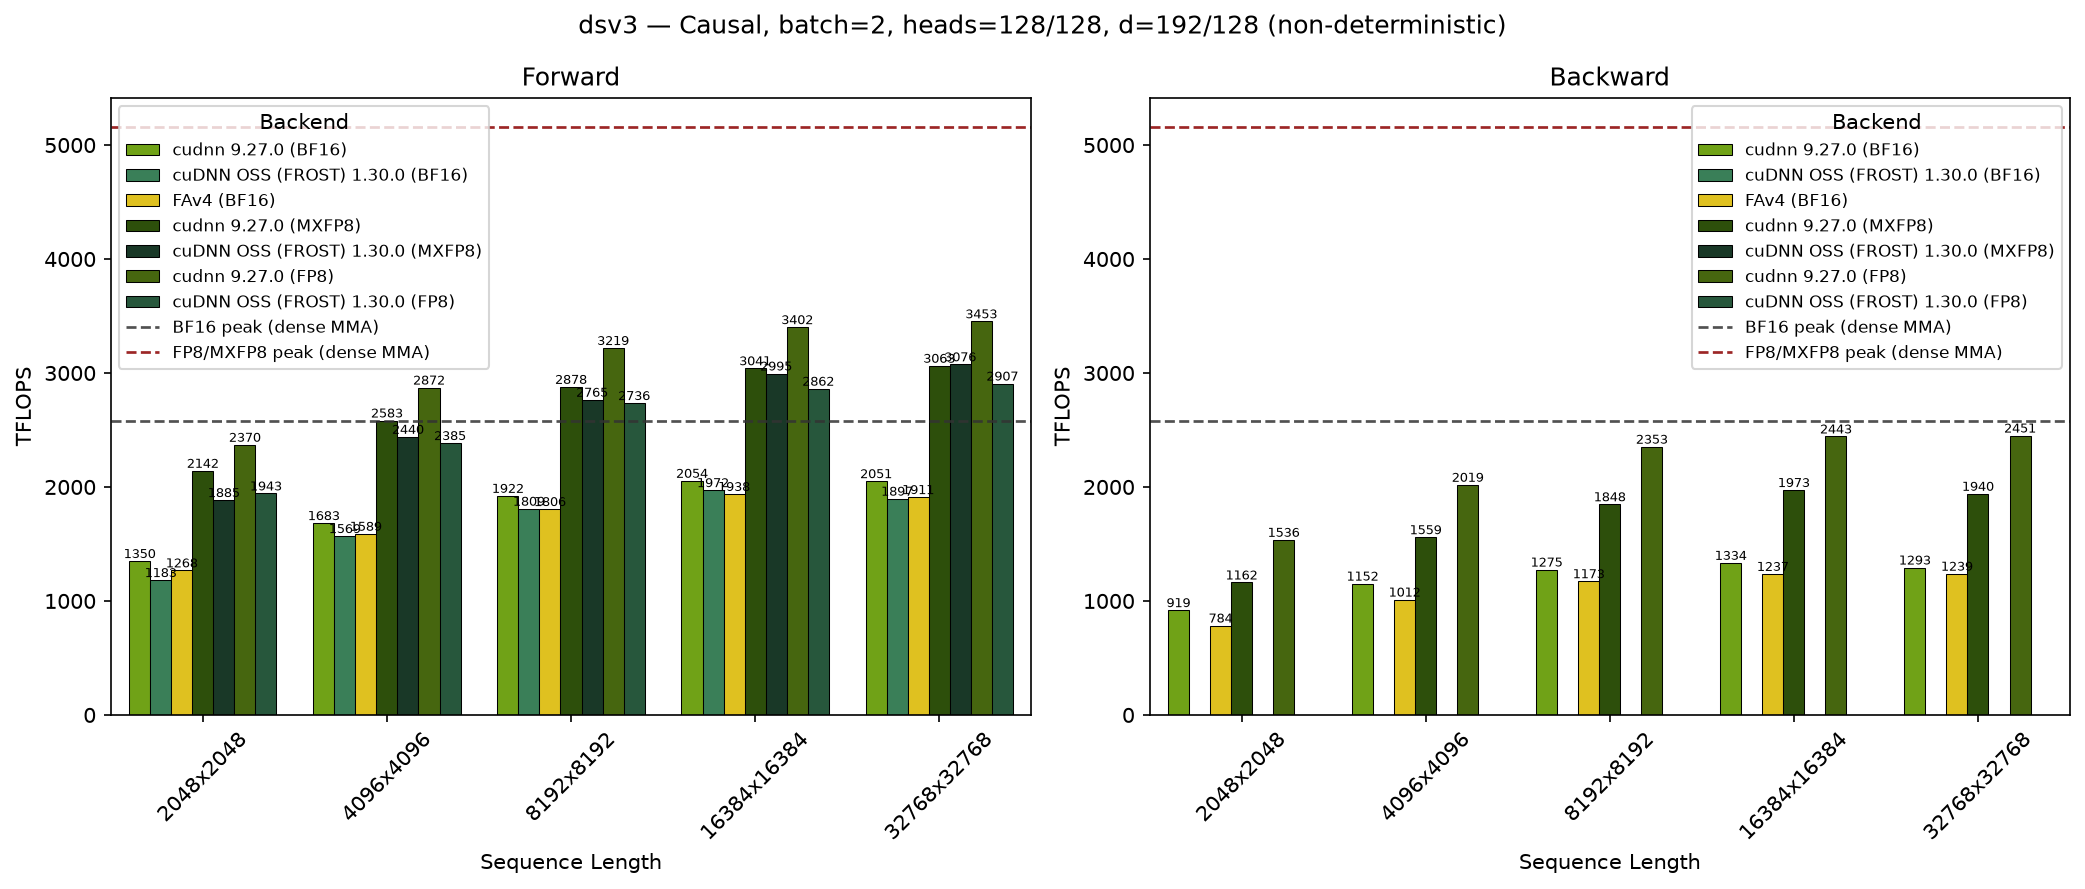
- SDPA parameters:
batch=1; num_q_heads=128; num_kv_heads=128; head_dim_qk=192; head_dim_vo=128; is_causal=True - Sequence lengths shown on x-axis
- Results obtained on NVIDIA GB300 GPU
API
SDPA FP16/BF16 Forward
C++ API
The options parameter of type SDPA_attributes is used to control the attributes of the forward operation, as detailed below:
Python API
Args:
q(cudnn_tensor): The query data with shape .k(cudnn_tensor): The key data. Whenpaged_attention_k_tableis provided, this is a container of non-contiguous key blocks.v(cudnn_tensor): The value data. Whenpaged_attention_v_tableis provided, this is a container of non-contiguous value blocks.attn_scale(Optional[Union[float, cudnn_tensor]]): Scale factor for attention scores. Typically . Default is None (no scaling).bias(Optional[cudnn_tensor]): Additive bias mask for attention scores. Supports broadcasting.block_mask(Optional[cudnn_tensor]): Block-level mask for 128x128 tiles. Only supported with UNIFIED implementation. On SM10x, the native backend requires cuDNN 9.26.0 or newer: older kernels can return NaNs when the first KV tile is masked out. This restriction is checked during native validation/planning; ordinary attention and FROST admission are unaffected. Because mask contents may change between executions, the requirement applies to every graph with a block-mask tensor, including one initially containing an all-visible mask.use_alibi_mask(Optional[bool]): Enable ALiBi (Attention with Linear Biases) positional encoding. Requiresdiagonal_band_right_bound=0.use_padding_mask(Optional[bool]): Enable variable sequence length masking. Must also provide a Q-side and a KV-side length tensor, each in per-batch (seq_len_q/seq_len_kv) or cumulative (cu_seq_len_q/cu_seq_len_kv) form.seq_len_q(Optional[cudnn_tensor]): Per-batch query sequence lengths with shape .seq_len_kv(Optional[cudnn_tensor]): Per-batch key/value sequence lengths with shape .cu_seq_len_q(Optional[cudnn_tensor]): Cumulative query sequence lengths (prefix sums with a leading 0) with shape or 1-D (promoted automatically), int32 or int64. Mutually exclusive withseq_len_q(a side cannot use both forms); a KV-side length tensor (seq_len_kvorcu_seq_len_kv) must also be provided, anduse_padding_mask=Trueis required. The two sides may use different forms (e.g.cu_seq_len_qwithseq_len_kv), which requires cuDNN 9.25+. Supplyingcu_seq_len_qrequires cuDNN 9.24+ and the UNIFIED implementation.cu_seq_len_kv(Optional[cudnn_tensor]): Cumulative key/value sequence lengths; same shape, type, and constraints ascu_seq_len_q.diagonal_alignment(Optional[cudnn.diagonal_alignment]): Alignment for diagonal masking.TOP_LEFTfor standard causal,BOTTOM_RIGHTfor prefix-LM style.diagonal_band_left_bound(Optional[int]): Left bound for sliding window attention. Masks columns at or beforerow_idx - left_bound.diagonal_band_right_bound(Optional[int]): Right bound for causal masking. Set to 0 for causal mask. Masks columns beyondrow_idx + right_bound.dropout(Optional[tuple]): Dropout configuration. Either(probability, seed, offset)for Philox RNG or(mask, scale)for custom mask.rng_dump(Optional[cudnn_tensor]): Debug tensor to capture the Philox RNG dropout mask.paged_attention_k_table(Optional[cudnn_tensor]): Page table with block offsets into the K container.paged_attention_v_table(Optional[cudnn_tensor]): Page table with block offsets into the V container.paged_attention_max_seq_len_kv(Optional[int]): Maximum sequence length for K/V caches. Recommended when using paged attention.generate_stats(Optional[bool]): If True, output softmax statistics for backward pass. Required for training.stats_use_log2(Optional[bool]): If True,statsis returned in base 2, , instead of the default natural-log form . This is the convention of flash-attention-style kernels (FA2/FA3, TRT-LLM) that fold into the softmax scale, so consumers that mix LSE tensors from several backends (cascade/split-KV merges, speculative decoding) get one convention without an extra elementwise pass. Only affectsstats;score_maxandscore_sum_expare unchanged, andsdpa_backwardstill expects natural-log stats. Served by the FROST SDPA engines and, on cuDNN 9.27.0+, by both theUNIFIEDandCOMPOSITEimplementations (CUDNN_ATTR_OPERATION_SOFTMAX_STATS_LOG2on the softmax operation descriptor used by both implementations); on older backends both decline it at validation, so only a FROST engine can serve it there.implementation(Optional[cudnn.attention_implementation]): SDPA implementation to use.AUTO(default),COMPOSITE, orUNIFIED.unfuse_fma(Optional[bool]): Use unfused mul/add in the softmax computation.compute_data_type(Optional[cudnn.data_type]): Data type for internal computation.name(Optional[str]): Name for the operation.
Returns:
o(cudnn_tensor): The output attention data with shape .stats(Optional[cudnn_tensor]): Softmax statistics with shape whengenerate_stats=True. Natural log by default (); base 2 whenstats_use_log2=True.
Configurable Options
-
Attention scale (
attn_scale): Applies a scaling factor to attention scores before the softmax, such as . Set to 1.0 by default. Can be passed as a float or as a tensor. -
Bias mask: Applies an additive bias mask to attention scores. You must pass a bias tensor as specified in the tensors section below. The dimensions that are passed as 1 will apply a broadcasted mask over attention scores.
-
Block mask: Masks out tiles of attention scores at a 128x128 block granularity. The block mask is a uint8 tensor where each bit represents whether a 128x128 tile should be computed (1) or masked out (0). This is supported with the UNIFIED implementation.
-
ALiBi mask: Attention with Linear Biases (ALiBi) is an additive mask applied to the attention scores as described in the paper Train Short, Test Long: Attention with Linear Biases Enables Input Length Extrapolation. When using ALiBi,
diagonal_band_right_boundmust be set to exactly 0 (causal masking). -
Padding mask (Variable Sequence Length): Masks out padded time steps to ignore them in computation. You must pass per-batch sequence length tensors as specified in the tensors section below. In padded or ragged layout (discussed below) where the actual seqlen can be less than the max seqlens of a graph, certain batches can be skipped by setting the actual seqlen of the corresponding batch to 0.
-
Diagonal masking options: These options control causal and sliding window masking:
-
Diagonal Alignment (
diagonal_alignment): Specifies where the diagonal starts. Options are:TOP_LEFT: The diagonal starts at the top-left of the attention matrix. Used for standard causal masking.BOTTOM_RIGHT: The diagonal starts at the bottom-right of the attention matrix, aligned with the actual sequence length. Useful for prefix-LM or when .
-
Diagonal Band Right Bound (
diagonal_band_right_bound): Specifies that attention scores beyond columnrow_idx + right_boundare masked with negative infinity. Setting this to 0 enables causal masking. -
Diagonal Band Left Bound (
diagonal_band_left_bound): Specifies that attention scores at or before columnrow_idx - left_boundare masked with negative infinity. This enables sliding window attention. -
Common masking patterns:
- Causal mask (top-left):
diagonal_alignment=TOP_LEFT,right_bound=0 - Causal mask (bottom-right):
diagonal_alignment=BOTTOM_RIGHT,right_bound=0 - Sliding window: Set
left_boundto window size - Band attention: Set both
left_boundandright_bound
- Causal mask (top-left):
-
Paged attention: Enables non-contiguous K/V caches to reduce memory fragmentation. See the PagedAttention paper.
- Requirements:
- Pass
page_table_ktensor with block offsets into the K container (optional if K is not paged) - Pass
page_table_vtensor with block offsets into the V container (optional if V is not paged) - Pass sequence length tensors (
seq_len_q,seq_len_kv) for padding mask - Optionally pass
paged_attention_max_seq_len_kvfor the maximum KV sequence length (recommended)
- Pass
- FROST engines (opt-in, SM100 line, f16/bf16): paged decode and MTP graphs (
S_q * pack_g <= 128on the d128 flavor,pack_g= the packed head group for a PackGQA plan —H_q/H_kv, or its largest divisor of 128 — and 1 otherwise) run a dedicated decode tile (TILE_CGA_M=1); other shapes run the prefill pipeline. Seepython/cudnn/sdpa/frost/SUPPORT_MATRIX_TRACKER.md. - Offset calculation:
- Packed page tables: Page tables can also use ragged offsets to pack only the necessary block indices, useful for frameworks that prefer packed representations.
- Requirements:
-
Implementation: Select the underlying SDPA implementation:
AUTO(default): Auto-selects the best implementation. Recommended for most users.COMPOSITE: Standard cuDNN graph representing SDPA as distinct operations.UNIFIED: Optimized fused SDPA operation (cuDNN 9.13.1+). Supports a subset of features including block masking.
-
Unfuse FMA (
unfuse_fma): Uses unfused mul/add in the softmax computation. -
Generate stats (
generate_stats): WhenTrue, outputs softmax statistics needed for backward pass during training. Set toTruefor training,Falsefor inference. -
Stats in base 2 (
stats_use_log2): Returnsstatsas rather than the natural-log default. The value is exactly the natural-log stats times , so it is a convention switch, not a different quantity; the backward pass is unaffected and continues to take natural-log stats.
Limitations
- Head dimension must be a multiple of 8.
- ALiBi requires causal masking (
diagonal_band_right_bound=0). - Block masking is only supported with the UNIFIED implementation.
- Ampere/Ada architectures are limited to head dimensions up to 256 for prefill, 128 for decode and backward.
Fused epilogue gate (FROST, SM107)
A gated attention tail — the SDPA output multiplied by the sigmoid of a per-element gate tensor G of O’s shape,
O_gated = O * sigmoid(G) — is built as three graph nodes, an sdpa (or sdpa_fp8 / sdpa_mxfp8) node followed by
sigmoid and mul pointwise nodes on O. Under CUDNN_FRONTEND_ENABLE_FROST_ENGINES=1 the Rubin d256 FROST
forward engines (sdpa_fwd_prefill_sm107, sdpa_fwd_prefill_sm107_fp8, sdpa_fwd_prefill_sm107_mxfp8) serve the
whole tail fused: the gate tile is TMA-staged by the kernel’s load warp and applied in the epilogue after the
dead-row select, so the gated O (and the quantized O on the FP8 / MXFP8 rows) is written once. Served today at
d_qk = d_v = 256 with a bf16 G, dense / unsplit / non-PackGQA / non-paged layouts; any other combination
falls back to the unfused three-node execution. Two contracts hold on the fused path: Stats (LSE) is
independent of G, and Amax_O — an output of the sdpa node, which precedes the gate on the graph — is the
amax of the un-gated normalised O (in scale_o units on FP8, unscaled on MXFP8), while the stored O is
the gated value. The per-engine claims are tracked in
python/cudnn/sdpa/frost/SUPPORT_MATRIX_TRACKER.md.
The same fusion is reachable without the graph API through the
gated attention block (fuse_gate=True).
Tensors
Input Tensors
Output Tensors
Where:
- is the batch size
- is the number of query heads
- is the number of key heads
- is the number of value heads
- is the sequence length of the query
- is the sequence length of the key and value
- is the embedding dimension per head of query and key
- is the embedding dimension per head of value
- is the (power of 2) block size of the K container
- is the (power of 2) block size of the V container
- is the number of blocks in the K container
- is the number of blocks in the V container
Samples and Tests
-
Python forward sample: samples/python/50_sdpa_forward.ipynb
-
Python backward sample: samples/python/51_sdpa_backward.ipynb
-
Python prefill sample with paged caches: samples/python/52_sdpa_with_paged_caches.ipynb
-
Python decode sample with packed paged caches: samples/python/53_sdpa_decode_with_paged_caches.ipynb
-
C++ sample: samples/cpp/sdpa
-
Python tests (v2 with randomized configurations): test/python/test_mhas_v2.py
Example Usage:
SDPA FP16/BF16 Backward
This operation computes gradient tensors for scaled dot product attention (SDPA) using the FlashAttention-2 algorithm as described in the paper FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning. You are required to pass the stats tensor from the forward operation to the backward operation as input.
C++ API
The options parameter of type SDPA_backward_attributes is used to control the attributes of backward operation, as detailed below:
Python API
Args:
q(cudnn_tensor): The query data from the forward pass.k(cudnn_tensor): The key data from the forward pass.v(cudnn_tensor): The value data from the forward pass.o(cudnn_tensor): The output data from the forward pass.dO(cudnn_tensor): The gradient of the loss with respect to the output.stats(cudnn_tensor): The softmax statistics tensor from the forward pass (generate_stats=True).attn_scale(Optional[Union[float, cudnn_tensor]]): The attention scale factor. Must match the forward pass.bias(Optional[cudnn_tensor]): The bias tensor from the forward pass.dBias(Optional[cudnn_tensor]): Output tensor to store the bias gradient.use_alibi_mask(Optional[bool]): Enable ALiBi. Must match the forward pass configuration.use_padding_mask(Optional[bool]): Enable variable sequence length masking. Must match forward pass.seq_len_q(Optional[cudnn_tensor]): Per-batch query sequence lengths.seq_len_kv(Optional[cudnn_tensor]): Per-batch key/value sequence lengths.max_total_seq_len_q(Optional[int]): Maximum total sequence tokens for Q when using ragged tensors. Used for workspace allocation. Defaults to if not provided.max_total_seq_len_kv(Optional[int]): Maximum total sequence tokens for KV when using ragged tensors. Used for workspace allocation. Defaults to if not provided.diagonal_alignment(Optional[cudnn.diagonal_alignment]): Must match the forward pass.diagonal_band_left_bound(Optional[int]): Must match the forward pass.diagonal_band_right_bound(Optional[int]): Must match the forward pass.dropout(Optional[tuple]): Dropout configuration. Must match the forward pass to ensure the same dropout mask is applied.use_deterministic_algorithm(Optional[bool]): If True, forces deterministic gradient computation. This ensures bitwise-identical results across multiple runs but may be slower. Default is False.compute_data_type(Optional[cudnn.data_type]): Data type for internal computation.name(Optional[str]): Name for the operation.
Returns:
dQ(cudnn_tensor): The gradient with respect to the query tensor.dK(cudnn_tensor): The gradient with respect to the key tensor.dV(cudnn_tensor): The gradient with respect to the value tensor.
Important Notes:
-
The backward operation does NOT support paged attention. K and V must be contiguous tensors.
-
All masking and dropout configurations must exactly match the forward pass to ensure correct gradients.
-
When using ragged tensors, set
max_total_seq_len_qandmax_total_seq_len_kvto the maximum total tokens (sum of sequence lengths) for proper workspace allocation. -
Python sample: samples/python/51_sdpa_backward.ipynb
-
C++ sample: samples/cpp/sdpa
-
Python tests (v2 with randomized configurations): test/python/test_mhas_v2.py
Tensors
Input Tensors
Output Tensors
Example Usage:
Block Sparse Attention FE OSS API
The experimental Block Sparse Attention API provides CuTe DSL forward and explicit backward kernels driven by per-query-block lists of selected key/value blocks. It is a standalone Python FE OSS API and is separate from the cuDNN Graph API described above.
HSTU Attention FE OSS API (SM100/SM103)
The experimental HSTU Attention API
provides packed-variable-length forward and backward CuTe DSL kernels for
Blackwell SM100/SM103 GPUs. HSTU applies SiLU to scaled QK scores without
softmax, supports its specialized mask modes, and exposes the sequence
normalization factor separately as scaling_seqlen. FP16 and BF16 arbitrary-mask
forward and backward automatically build private block metadata on the active
CUDA stream without adding public API parameters; D256 backward builds both
Q-to-K and K-to-Q views from one coarse classification.
Gated Attention Block FE OSS API (SM107)
The experimental Gated Attention Block API is a model-level FE OSS
API for NVIDIA Rubin (SM107): the QKV+gate projection, QK-RMSNorm (optional) with partial RoPE, GQA SDPA,
sigmoid gate and out projection of a Qwen3.5-style gated attention sub-layer behind one class, one workspace
and one execute(), every stage a FROST kernel. It runs bf16 / fp16, per-tensor FP8 and MXFP8 — the MXFP8
pipeline optionally with MXFP4 (e2m1 x E8M0) projection weights and with an NVFP4 or MXFP4 block-quantized output
feeding an fp4 x fp4 out projection — with two fusion knobs (fuse_norm_rope, fuse_gate) that take the block to
three launches (four with the fp4 output), plus a bf16 backward with a recompute policy. It is separate from the
cuDNN Graph API above; the fused epilogue gate it uses is also available as the graph pattern described under
“Fused epilogue gate”.
SDPA PyTorch Custom Ops (cudnn::sdpa_fwd / cudnn::sdpa_bwd)
PyTorch custom ops (torch.library) exposing the full cuDNN SDPA feature
surface — the features torch.nn.functional.scaled_dot_product_attention’s
aten contract cannot express:
- attention sinks — per-Q-head logits folded into the softmax denominator
- diagonal bands —
window_leftandwindow_right. The two bounds use different conventions, matchingdiagonal_band_left_bound/diagonal_band_right_bound:window_leftcounts visible tokens including self (so FA2’s(w, 0)maps towindow_left = w + 1), whilewindow_rightis the last visible column past the diagonal, with no offset (FA2’s(_, r)maps towindow_right = r).window_right=0is exactly causal;window_right > 0admits future columns and so cannot be combined withis_causal, which the op rejects rather than silently resolving. - bottom-right causal alignment — inference-style diagonals
- padded batches — per-batch actual lengths via
seq_len_q/seq_len_kv - THD / varlen packing — FlashAttention-style
(T, H, D)+cu_seqlens
The ops build cuDNN pygraph sdpa / sdpa_backward nodes; the engine Router
picks the best serving plan (FROST OSS kernels or cuDNN-backend engines) per
configuration. Graphs are cached per configuration (bounded, thread-safe;
cuDNN handles are thread-local).
Usage
Contracts and limits
- Dense tensors are BHSD
(B, H, S, D)(any strides; the graph declares the actual layout). Varlen tensors are packed(T, H, D); non-contiguous views (e.g. K/V slices of a fused(T, 2, H, D)KV projection) are declared with their true strides. On the varlen path, a non-dense innermost dim or a misaligned base pointer is repaired by one copy (warned as slow path); the dense path declares the given strides as-is. - One io dtype per call (
fp16orbf16); mixed-dtype inputs are rejected. sdpa_bwdserves the THD/varlen path. Dense backward and sink backward (dSink) are follow-ups and raiseNotImplementedError. It consumes a padded(B, H, max_seqlen_q, 1)fp32 LSE (backend restriction: bprop THD rejects ragged LSE on SM8X/SM12X).- Autograd (
register_autograd) requiresreturn_lse=Trueon the forward; the glue converts the packed TH1 stats to the padded layout device-side. - Both ops ship
register_fakemeta kernels.cudnn::sdpa_fwdpassestorch.library.opcheckon the dense and varlen paths, including dynamic-shape AOT dispatch (torch.compile-ready); the opcheck autograd case exercisescudnn::sdpa_bwdthrough the registered backward.
Requirements
nvidia-cudnn-frontend, cuDNN backend ≥ 9.6 (THD token-major stats), sm80+.
Tests: test/python/sdpa/test_torch_ops.py.
SDPA FP8 Forward
This operation computes the scaled dot product attention (SDPA) in the 8-bit floating point (FP8) datatype, using the FlashAttention-2 algorithm as described in the paper FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning. It is applicable for both training and inference phases, with an option to generate a stats tensor to be used for backwards training computation.
The FP8 datatype consists of two encodings:
FP8_E4M3(1 sign bit, 4 exponent bits, and 3 mantissa bits)FP8_E5M2(1 sign bit, 5 exponent bits, 2 mantissa bits).
Due to the limited numerical precision of FP8 data type, for practical use cases, you must scale values computed in FP32 format before storing them in FP8 format, and descale the values stored in FP8 format before performing computations on them. For more information, refer to the Transformer Engine FP8 Primer.
The suggested value for the scaling factor is computed as: (Max representable value in the fp8 format) / (Max absolute value seen in the tensor for the previous layer).
- For E4M3, the suggested scaling factor is
448.f/ prev_layer_tensor_amax(rounded to the nearest lower power of two) - For E5M2, the suggested scaling factor is
57344.f/ prev_layer_tensor_amax(rounded to the nearest lower power of two)
The suggested value for the descale factor is the reciprocal of the scale factor.
Since scaling and descaling are critical for convergence with FP8 datatype, you are required to pass scaling and descaling input tensors, as well as amax output tensors.
C++ API
The options parameter of type SDPA_fp8_attributes is used to control the attributes of the forward operation, as detailed below:
Python API
Configurable Options
The current FP8 support is a subset of the options supported in FP16 and BF16 support.
- Attention scale (
attn_scale): Applies a scaling factor to attention scores before the softmax, such as . Set to 1.0 by default. - Causal mask: Fills the upper triangular matrix of attention scores with negative infinity.
- Padding mask (
use_padding_mask): Variable sequence lengths, provided either as per-batch lengths (seq_len_q/seq_len_kv) or as cumulative sequence lengths (cu_seq_len_q/cu_seq_len_kv; cuDNN 9.25+, UNIFIED implementation only).
Limitations
- Requires Hopper (SM90) or newer architecture.
- Head dimension must be a multiple of 16.
- Limited masking options compared to FP16/BF16 (causal and padding masks only).
- Requires explicit scale/descale tensors for all FP8 inputs and outputs.
Tensors
The tensors in forward operation are defined as the following:
Input Tensors
Output Tensors
Where:
- is the batch size
- is the number of query heads
- is the number of key heads
- is the number of value heads
- is the sequence length of the query
- is the sequence length of the key and value
- is the embedding dimension per head of query and key
- is the embedding dimension per head of value
Samples and tests
- C++ sample: samples/cpp/sdpa
SDPA FP8 Backward
This operation computes the gradients for scaled dot product attention (SDPA) 8-bit floating point (FP8) datatype, using the FlashAttention-2 algorithm as described in the paper FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning. You are required to pass the stats tensor from the forward operation to the backward operation as input.
- C++ sample: samples/cpp/sdpa
C++ API
The options parameter of type SDPA_fp8_backward_attributes is used to control the attributes of the backward operation, as detailed below:
Python API
Limitations
- Requires Hopper (SM90) or newer architecture.
- Dropout is not supported in FP8 backward pass.
- Only causal masking is supported.
- Requires explicit scale/descale tensors for all FP8 inputs and outputs.
Tensors
The tensors in backward operation are defined as the following:
Input Tensors
Output Tensors
Where:
- is the batch size
- is the number of query heads
- is the number of key heads
- is the number of value heads
- is the sequence length of the query
- is the sequence length of the key and value
- is the embedding dimension per head of query and key
- is the embedding dimension per head of value
FAQs
Logical vs Physical Layout
BHSD Layout (Batch-Head-Sequence-Dim)
The default logical layout where dimensions are ordered as .
- Dimensions:
- Strides:
This is the most common layout and matches PyTorch’s default attention tensor ordering.
BSHD Layout (Batch-Sequence-Head-Dim)
A physical layout where sequence comes before heads in memory, while maintaining the logical dimension order.
- Dimensions: (logical order, unchanged)
- Strides:
Note: The dimension order remains but strides are reordered so that in memory, sequence varies faster than head.
Determinism Support
Fprop
Always deterministic on all architectures
Bprop
SM100 - Deterministic requires cuDNN backend version 9.19.0 or later. SM80 and SM120 do not support deterministic algorithm with ragged input tensor. SM90 - Determinism is supported.
cuDNN Flex Attention API
SDPA and SDPA backward operations now accept the functions set_score_mod and set_score_mod_bprop, which allows modification of the attention score matrix. These functions can be used to program a sub-graph of pointwise operations that can subsequently be used to program the score modifier. Note that this function usage is mutually exclusive to the usage of ready made options. Also, note that the graph argument in the score_mod function is not the same as the sdpa graph. So, any tensor to be passed as input to the score-mod sub-graph must first be registered with main graph and subsequently passed as argument to the score_mod function. The SDPA operation also now accepts the function set_block_mask, which applies a block mask to the score matrix. The implementation assumes a 128 x 128 block size.
cuDNN Version History for SDPA
This section documents features and fixes introduced in each cuDNN version for SDPA operations.
Version 9.21.0
set_unfuse_fma/unfuse_fmasupport for Unified SDPA forward on SM100
Version 9.19.0
- FP8 deterministic algorithm support on Blackwell
- d_qk=192 with d_v=128 support for FP8
Version 9.18.0
- THD/Ragged support on Ampere and Ada (SM80/SM89)
- Deterministic algorithm on Blackwell for FP16/BF16
Version 9.15.0
- Padding mask support for Unified SDPA
- Paged attention inputs for Unified SDPA
Version 9.14.0
- Block mask support for Unified SDPA
- Known Issue: Non-causal + s_kv > 1024 + sliding window may have issues
Version 9.13.0
- Unified SDPA implementation (requires 9.13.1)
- FP8 output in FP16/BF16 format on Blackwell
- Sink token support
Version 9.11.0
- DeepSeek configuration (d_qk=192, d_v=128) backward on Hopper
- Blackwell backward support with d_qk=192
Version 9.10.2
- Paged attention with packed page tables
Version 9.10.0/9.10.1
- Known Issues: General stability issues - recommend using 9.10.2+
Version 9.9.0
- Various head dimension expansions for decode mode
Version 9.7.0
- Bottom-right causal masking for FP8 (SM100+)
- Paged + ragged combination support
Version 9.6.0
- GQA with ragged offset support
- Bottom-right causal mask seqlen flexibility
Version 9.5.0
- Paged attention support
- dBias with variable sequence lengths
Version 9.3.0
- Bottom-right causal masking for FP16/BF16
- Minimum recommended version for new deployments
Version 9.2.0
- Sliding window attention
Version 9.1.0
- FP8 SDPA support (Hopper+)
Version 9.0.0
- Sequence length flexibility (s_q, s_kv not required to be multiples of 64)
Version 8.9.6
- Padding mask, ALiBi mask support
- Bias mask support
Version 8.9.3
- Initial SDPA support (SM80+)