Red Hat AI Factory with NVIDIA Reference Implementation#
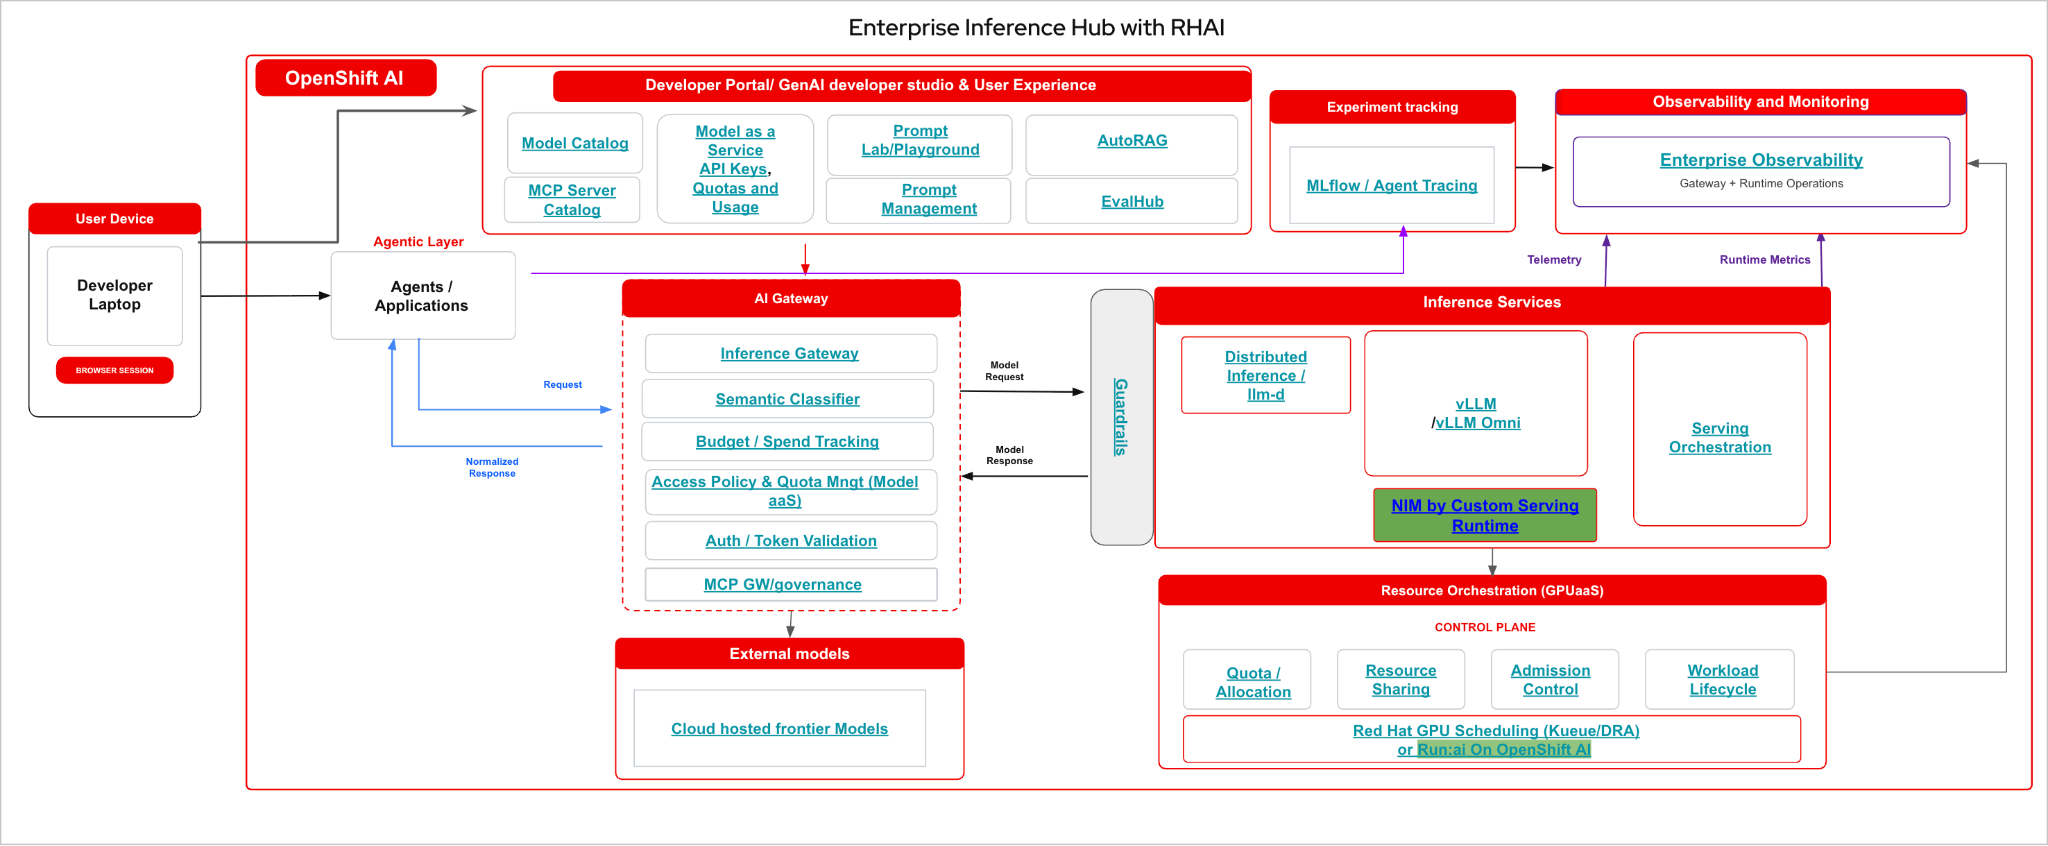
Red Hat AI Factory with NVIDIA implements the same Portal, Gateway, and Backend pattern using an open, Kubernetes-native design that already shares two foundational layers with NVIDIA’s own deployment — OpenShift and llm-d. Where the NVIDIA reference design uses NVIDIA-specific control-plane components, Red Hat AI provides open source alternatives supported by Red Hat, while NVIDIA components remain supported by NVIDIA. Both interoperate directly, so an enterprise can adopt the Red Hat pattern in place of, or alongside, the NVIDIA pattern.
The Red Hat AI Inference Platform is already adopted by multiple large enterprise customers, serving >50 billion tokens per week per customer (conservatively). NVIDIA NIM maps to the supported vLLM distribution, Dynamo to llm-d, Run:ai to the Red Hat build of Kueue, LiteLLM to the Models-as-a-Service/AI Gateway, and Datadog to OpenShift observability exported over OpenTelemetry and Prometheus. An existing LiteLLM can be connected as an external gateway. A semantic classifier for model selection by task and cost is on the roadmap.
Component |
What it does |
Status |
Docs |
|---|---|---|---|
Model Catalog |
Browse, select, and deploy pre-validated models from a curated registry |
GA |
|
AI Gateway UI |
Management console for quota, model routing, gateway policies, issue and manage API keys for model access, scoped by user or application |
GA |
AI Gateway controls access, routing, and cost attribution for all model traffic#
Component |
What it does |
Status |
Docs |
|---|---|---|---|
Inference Gateway |
Routes inference requests to model backends with load balancing and endpoint management |
GA |
|
Semantic |
Classifies incoming prompts by complexity, cost, and sensitivity to produce routing signals for intelligent model selection |
Incubating (upstream) Developer Preview in November |
|
Access Policy and Quota Mgmt (MaaS) |
Per-user and per-team access policies, rate limits, and quota allocations for model endpoints |
GA |
|
Auth / Token Validation |
Authenticate and authorize model requests via API key and token validation |
GA |
|
Budget / Spend Tracking |
Track token consumption and compute cost per user, team, or application for showback reporting. |
Token limits per user and model are GA. |
|
External Models (Cloud hosted) |
Route requests to externally hosted models through the same gateway policies. (OpenAI, Anthropic, Azure OpenAI, Vertex AI, Bedrock; others as OpenAI-compatible) |
Tech Preview |
Inference Services run model workloads across engines and orchestration layers#
Component |
What it does |
Status |
Docs |
|---|---|---|---|
llm-d (Distributed Inference)/vLLM |
CNCF Sandbox project that orchestrates vLLM and vLLM Omni across disaggregated GPU pools for prefill/decode separation and intelligent request routing |
GA |
|
llm-d/vLLM Omni |
Combines llm-d’s distributed serving orchestration with vLLM-Omni’s multimodal execution to efficiently serve models that generate text, images, audio, and video. |
Roadmap. Developer Preview in 3.7 |
|
vLLM |
High-performance inference engine for LLMs, supporting NVIDIA, AMD, Intel Gaudi, and IBM Spyre accelerators |
GA |
|
vLLM Omni |
Multimodal serving engine for text, image, audio, and video workloads, extending vLLM to non-text modalities |
Developer Preview Upstream |
|
NIM via Custom Serving Runtime |
Deploy NVIDIA NIM containers on OpenShift AI via KServe integration or the NIM Operator |
NVIDIA-provided |
|
Serving Orchestration |
Manages model deployment lifecycle, including scaling, revision management, canary rollouts, and traffic splitting |
GA |
Observability provides end-to-end visibility from prompt to token generation#
Component |
What it does |
Status |
Docs |
|---|---|---|---|
Enterprise Observability |
Infrastructure-level monitoring of inference deployments. GPU utilization, latency percentiles, throughput, and queue depth. |
GA |
Guardrails enforce safety policies on both user input and model output#
Component |
What it does |
Status |
Docs |
|---|---|---|---|
Guardrails |
Content filtering, PII detection, jailbreak/prompt injection detection, and hallucination checks on inputs and outputs. Supports NVIDIA NeMo Guardrails. |
GA |
Resource Orchestration manages GPU allocation across workloads#
Component |
What it does |
Status |
Docs |
|---|---|---|---|
Red Hat GPU Scheduling (Kueue/DRA) |
Queue-based GPU scheduling with fair sharing, preemption, and priority across inference and training workloads. Dynamic Resource Allocation (DRA) enables fine-grained GPU partitioning. |
GA (Kueue) / Tech Preview (DRA) |
|
Quota / Allocation |
Per-team and per-namespace GPU quota enforcement |
GA |
|
Resource Sharing |
Cohort-based GPU sharing across teams with fair-share scheduling |
GA |
|
Admission Control |
Fair-share admission policies for workload queuing and priority |
GA |
|
Workload Lifecycle |
Job and workload management, monitoring pending workloads |
GA |
|
Run:ai on OpenShift AI |
NVIDIA GPU orchestration and workload management platform, available as an alternative to Kueue |
NVIDIA-provided |
Platform#
Component |
What it does |
Status |
|---|---|---|
Any Kubernetes / Any Linux |
Inference hub runs on OpenShift, standalone Kubernetes, or Linux |
GA |
Extended AI Platform Services#
Component |
What it does |
Status |
Docs |
|---|---|---|---|
Prompt Lab / Playground |
Test prompts across models, compare responses, and evaluate RAG workflows interactively |
Tech Preview |
|
Prompt Management |
Store, version, and share prompt templates across teams. |
GA |
|
MLflow / Agent Tracing / Experiment Tracking |
Track experiments, log model metrics, trace agent execution chains, and compare runs |
GA |
|
EvalHub |
Evaluate and compare models, prompts, RAG configs, and agentic AI systems using standardized benchmarks |
GA |
|
AutoRAG |
Automated optimization of retrieval-augmented generation pipelines, including chunking, embedding, and retrieval strategy selection. |
Tech Preview |
|
MCP Server Catalog |
Registry of approved Model Context Protocol servers that agents and playground sessions can connect to. |
Tech Preview |
|
MCP GW / Governance |
Govern which MCP servers agents can access and enforce connection policies.. |
Tech Preview |