
Working with DLA#
Important
In TensorRT 11.4.1, DLA support depends on the platform and package:
Supported: NVIDIA Jetson AGX Orin when using NVIDIA JetPack 7.2.2 or later. This support is generally available, and GPU fallback behaves as it did in TensorRT 10.x. Install the TensorRT Linux SBSA build, which is now a single package for both DLA and non-DLA deployments; the SBSA build does not provide DLA outside NVIDIA JetPack. These builds use strongly typed networks; refer to Strongly Typed Networks for DLA.
Supported: Windows on ARM, where DLA support is in beta.
Not supported: NVIDIA Jetson Thor, which has no DLA. Install the SBSA build for GPU inference.
Not supported: NVIDIA DriveOS deployments, including NVIDIA DRIVE AGX Thor.
Not supported: Jetson Orin on NVIDIA JetPack 6.x, which must remain on a TensorRT 10.x release supported by its JetPack version. TensorRT 10.7 was the last 10.x release that supported DLA.
DLA was unavailable in TensorRT 11.0 through 11.3, including TensorRT 11.3.1 for DriveOS. TensorRT 11.4.0 supported DLA only on Windows on ARM.
DLA support on Windows on ARM is in beta and covers a restricted set of layers. Its supported-layer set and restrictions differ from Orin: notably, there is no GPU fallback, so every layer must be DLA-capable, and batch size is 1. DLA engines built for Windows on ARM must be rebuilt once DLA support on that platform reaches general availability, so keep your source models. Refer to DLA Supported Layers for Windows on ARM for that platform.
NVIDIA DLA (Deep Learning Accelerator) is a fixed-function accelerator engine targeted for deep learning operations. It is designed to fully hardware accelerate convolutional neural networks. DLA supports various layers, such as convolution, deconvolution, fully connected, activation, pooling, and batch normalization. Refer to the DLA Supported Layers and Restrictions section for Jetson DLA support.
DLA is useful for offloading CNN processing from the GPU and is significantly more power-efficient for these workloads. In addition, it can provide an independent execution pipeline in cases where redundancy is important, such as mission-critical or safety applications.
For more information, refer to the DLA Developer page and the DLA tutorial Getting Started with the Deep Learning Accelerator on NVIDIA Jetson Orin.
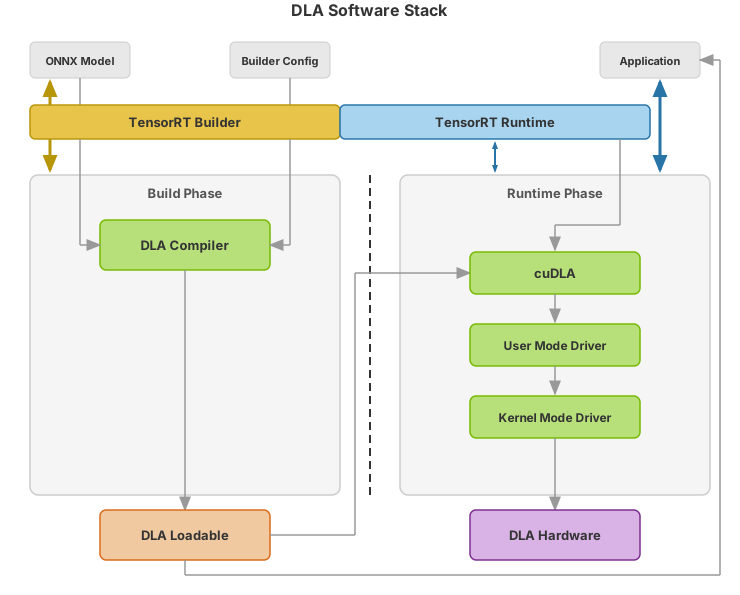
When building a model for DLA, the TensorRT builder parses the network and calls the DLA compiler to compile the network into a DLA loadable. Refer to Using trtexec to learn how to build and run networks on DLA.
In this guide
Building and Launching the Loadable: build and launch DLA loadables with
trtexec, the TensorRT API, and cuDLADLA Supported Layers and Restrictions: Jetson DLA supported layers, formats, and hardware limits
DLA Runtime Configuration: configure GPU fallback, I/O formats, workspace allocation, and tensor registration
DLA Standalone Mode: generate standalone DLA loadables outside TensorRT
Customizing DLA Memory Pools and Structured Sparsity: customize DLA SRAM/DRAM pools and structured sparsity
Strongly Typed Networks for DLA: specify FP16 and quantized DLA networks with strong typing
ONNX Parser Flags for DLA: configure DLA-specific ONNX parsing, adjustment, and capability reporting
DLA Supported Layers for Windows on ARM: Windows on ARM DLA supported layers and restrictions