

Over Quota, Fairness and Preemption
This quick start provides a step-by-step walkthrough of the core scheduling concepts - over quota, fairness, and preemption. It demonstrates the simplicity of resource provisioning and how the system eliminates bottlenecks by allowing users or teams to exceed their resource quota when free GPUs are available.
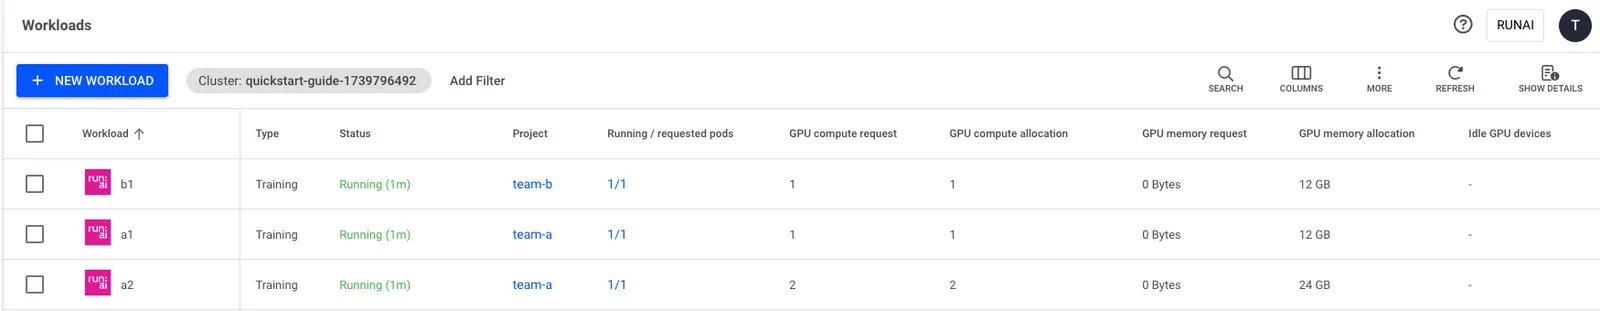
- Over quota - In this scenario, team-a runs two training workloads and team-b runs one. Team-a has a quota of 3 GPUs and is over quota by 1 GPU, while team-b has a quota of 1 GPU. The system allows this over quota usage as long as there are available GPUs in the cluster.
- Fairness and preemption - Since the cluster is already at full capacity, when team-b launches a new b2 workload requiring 1 GPU , team-a can no longer remain over quota. To maintain fairness, the NVIDIA Run:ai Scheduler preempts workload a1 (1 GPU), freeing up resources for team-b.
Prerequisites
- You have created two projects - team-a and team-b - or have them created for you.
- Each project has an assigned quota of 2 GPUs. In this example, we have 4 GPUs on 2 machines with 2 GPUs each.
Note
Flexible workload submission is enabled by default. If unavailable, contact your administrator to enable it under General settings → Workloads → Flexible workload submission.
Step 1: Logging In
UI
CLI v2
API
Browse to the provided NVIDIA Run:ai user interface and log in with your credentials.
Step 2: Submitting the First Training Workload (team-a)
UI - Flexible
UI - Original
CLI v2
API
-
Go to Workload manager → Workloads
-
Click +NEW WORKLOAD and select Training
-
Select under which cluster to create the workload
-
Select the project named team-a
-
Under Workload architecture, select Standard
-
Select Start from scratch to launch a new training quickly
-
Enter a1 as the workload name
-
Click CONTINUE
In the next step:
-
Under Environment, enter the Image URL -
kubeflow/pytorch-dist-mnist:latest -
Under Runtime settings, click +COMMAND & ARGUMENTS, then set the Arguments to
--epochs 100. -
Under Compute resources, click the load icon. A side pane appears, displaying a list of available compute resources. Select the ‘one-gpu’ compute resource for your workload.
- If ‘one-gpu’ is not displayed, follow the below steps to create a one-time compute resource configuration:
- Set GPU devices per pod - 1
- Optional: set the CPU compute per pod - 0.1 cores (default)
- Optional: set the CPU memory per pod - 100 MB (default)
- If ‘one-gpu’ is not displayed, follow the below steps to create a one-time compute resource configuration:
-
Click CREATE TRAINING
Step 3: Submitting the Second Training Workload (team-a)
UI - Flexible
UI - Original
CLI v2
API
- Go to the Workload Manager → Workloads
- Click +NEW WORKLOAD and select Training
- Select the cluster where the previous training workload was created
- Select the project named team-a
- Under Workload architecture, select Standard
- Select Start from scratch to launch a new training quickly
- Enter a2 as the workload name
- Click CONTINUE
In the next step: - Under Environment, enter the Image URL -
kubeflow/pytorch-dist-mnist:latest - Under Runtime settings, click +COMMAND & ARGUMENTS, then set the Arguments to
--epochs 100. - Under Compute resources, click the load icon. A side pane appears, displaying a list of available compute resources. Select the ‘two-gpus’ compute resource for your workload.
- If ‘two-gpus’ is not displayed, follow the below steps to create a one-time compute resource configuration:
- Set GPU devices per pod - 2
- Optional: set the CPU compute per pod - 0.1 cores (default)
- Optional: set the CPU memory per pod - 100 MB (default)
- If ‘two-gpus’ is not displayed, follow the below steps to create a one-time compute resource configuration:
- Click CREATE TRAINING
Step 4: Submitting the First Training Workload (team-b)
UI - Flexible
UI - Original
CLI v2
API
-
Go to the Workload Manager → Workloads
-
Click +NEW WORKLOAD and select Training
-
Select the cluster where the previous training was created
-
Select the project named team-b
-
Under Workload architecture, select Standard
-
Select Start from scratch to launch a new training quickly
-
Enter b1 as the workload name
-
Click CONTINUE
In the next step:
-
Under Environment, enter the Image URL -
kubeflow/pytorch-dist-mnist:latest -
Under Runtime settings, click +COMMAND & ARGUMENTS, then set the Arguments to
--epochs 100. -
Under Compute resources, click the load icon. A side pane appears, displaying a list of available compute resources. Select the ‘one-gpu’ compute resource for your workload.
- If ‘one-gpu’ is not displayed, follow the below steps to create a one-time compute resource configuration:
- Set GPU devices per pod - 1
- Optional: set the CPU compute per pod - 0.1 cores (default)
- Optional: set the CPU memory per pod - 100 MB (default)
- If ‘one-gpu’ is not displayed, follow the below steps to create a one-time compute resource configuration:
-
Click CREATE TRAINING
Over Quota Status
UI
CLI v2
API
System status after run:
Step 5: Submitting the Second Training Workload (team-b)
UI - Flexible
UI - Original
CLI v2
API
-
Go to the Workload Manager → Workloads
-
Click +NEW WORKLOAD and select Training
-
Select the cluster where the previous training was created
-
Select the project named team-b
-
Under Workload architecture, select Standard
-
Select Start from scratch to launch a new training quickly
-
Enter b2 as the workload name
-
Click CONTINUE
In the next step:
-
Under Environment, enter the Image URL -
kubeflow/pytorch-dist-mnist:latest -
Under Runtime settings, click +COMMAND & ARGUMENTS, then set the Arguments to
--epochs 100. -
Under Compute resources, click the load icon. A side pane appears, displaying a list of available compute resources. Select the ‘one-gpu’ compute resource for your workload.
- If ‘one-gpu’ is not displayed, follow the below steps to create a one-time compute resource configuration:
- Set GPU devices per pod - 1
- Optional: set the CPU compute per pod - 0.1 cores (default)
- Optional: set the CPU memory per pod - 100 MB (default)
- If ‘one-gpu’ is not displayed, follow the below steps to create a one-time compute resource configuration:
-
Click CREATE TRAINING
Basic Fairness and Preemption Status
UI
CLI v2
API
Workloads status after run:

Next Steps
Manage and monitor your newly created workload using the Workloads table.