

Spark On Kubernetes
Apache Spark is “a lightning-fast unified analytics engine for big data and machine learning”.
Since NVIDIA Base Command Manager version 9.0, the recommended way to run Spark workloads inside BCM is within Kubernetes.
Documentation for Spark is available at https://spark.apache.org/docs/.
8.1 Important Requirements
By default only the root user of the cluster can access Kubernetes. Since that is not very useful, the cluster administrator can grant access to regular users by using cm-kubernetes-setup with the --add-user flag.
The regular user should check that Kubernetes can be accessed via the user’s account (sections 7.2–7.3), or Spark workloads will fail to run. Being able to load the kubernetes module and being able to run the kubectl commands suggests that Kubernetes is properly accessible to the user:
Example
8.2 Running Spark Jobs Via The Kubernetes Spark Operator
Spark jobs can be run within Kubernetes if the cluster administrator has installed the cm-kubernetes-spark-operator package. The installation can be done
-
as part of
cm-kubernetes-setup(here) or -
as part of the Base View Kubernetes Wizard using the navigation path:
Containers>Kubernetes>Kubernetes Wizard.
The following session assumes that the cluster administrator has configured Spark to run as a Kubernetes operator (Chapter 6 of the Containerization Manual). In the session, a user alice carries out a Spark way of calculating pi. This can be regarded as a “Hello world!” type of demonstration for Spark users.
8.2.1 Example Spark Operator Run: Calculating Pi
For alice, a YAML file based on the specification at https://github.com/kubeflow/spark-operator/blob/v1beta2-1.6.2-3.5.0/examples/spark-py-pi.yaml can be used:
Example
Instead of tracking the pod with:
kubectl get pods
as in the preceding session, or with the more convenient:
watch kubectl get pods
the pod could be tracked with the -f| --follow option to stream the driver logs:
Example
To get intended output of the pi run—the calculated value of pi—it is sufficient to grep the log as follows:
Example
After the pi run has completed, the resources can be removed from the namespace:
8.3 Running Spark Jobs Directly Via spark-submit
The Spark documentation covers a pi run via spark-submit. However, using the Kubernetes operator submission method (section 8.2) is recommended instead in more recent versions.
8.4 Accessing The Spark User Interface
If a job is run via the Kubernetes Operator or spark-submit, then the Spark User Interface (Spark UI) can be used to monitor the job. The Spark UI is shut down once the job has finished, so it only makes sense to access the Spark UI for longer-running jobs.
The kubectl port-forward command can be used to allow access to the Spark UI:
The preceding example makes the dashboard available via local port 3000 on the machine where the port-forward command is executed. The Spark UI runs on port 4040 inside the pod, and displays something like in figure 8.1:
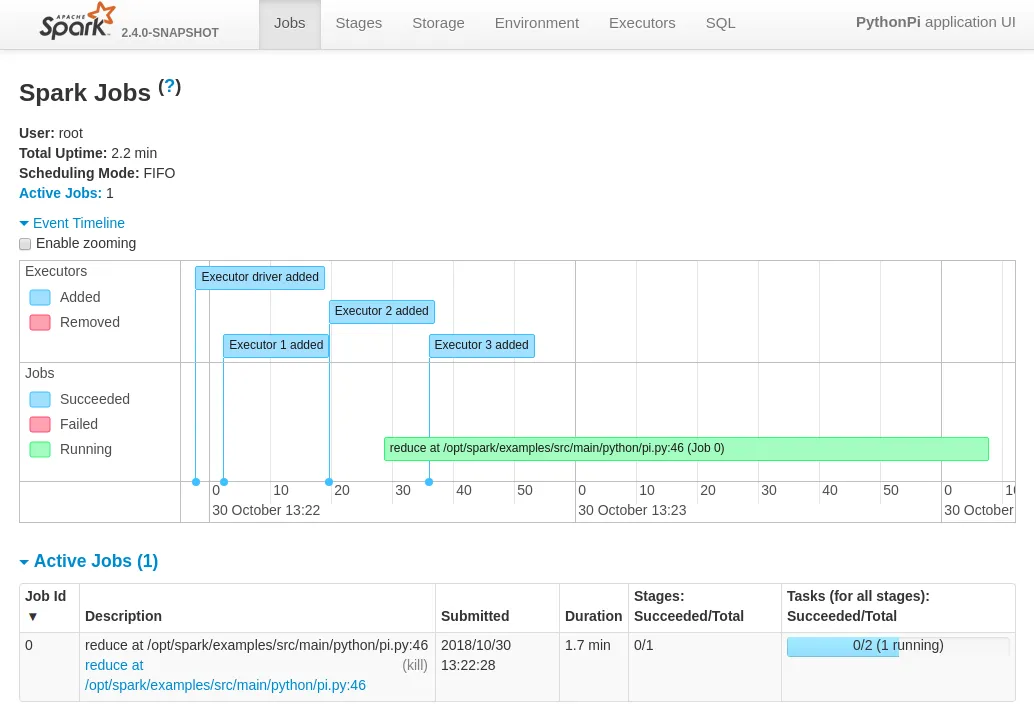
Figure 8.1: The Spark dashboard, forwarded on port 3000
8.5 Mounting Volumes Into Containers
The official documentation at https://spark.apache.org/docs/latest/running-on-kubernetes.html#using-kubernetes-volumes gives an outline of how volumes can be mounted into containers.
In summary, there are 3 ways a Kubernetes volume (https://kubernetes.io/docs/concepts/storage/volumes) can be mounted:
-
hostPath: mounts a file or directory from the host node’s filesystem into a pod. -
emptyDir: an initially empty volume, created when a pod is assigned to a node. -
persistentVolumeClaim: used to mount aPersistentVolumeinto a pod.
8.5.0.1 Mounting A hostPath
The official documentation mentions adding the following two flags to specify how the volume is mounted inside the container:
The following flag should also be added, to specify the path on the host:
The volumes can be specified for each executor as well as for the driver. For an executor, the specification should use spark.kubernetes.executor instead of spark.kubernetes.driver.
For example, the NFS share /cm/shared of a typical BCM setup could be made available on executor pods by adding the following 3 flags to the spark-submit command:
Example
This results in /cm/shared being mounted in read-write mode on the mount path /data:
8.5.0.2 Using Persistent Volume Claims
Spark in this case assumes that the Kubernetes cluster being managed by the user has persistent volumes available. A list of persistent volumes types can be found at: https://kubernetes.io/docs/concepts/storage/persistent-volumes/#types-of-persistent-volumes.
Claims to specific types of storage can be created for use with Spark. If spark-submit tries to use a persistent volume claim, then it assumes the claim already exists. It does not initiate a claim by itself.
In the following specification, for demonstration purposes, a claim my-claim is created:
This claim should bind to a persistent volume that meets the criteria. If none are configured, then the user can create a local volume for /cm/shared, for example with:
Applying the above two YAML configurations should result in the persistent volume claim object my-claim, and the persistent volume kube-pv-volume in Kubernetes:
Example
Invoking spark-submit as follows will then try to find the claim with name my-claim.
The claim that was specified can be found in the pod description:
Inside the executor pods /data is then found to be available, and presents the contents of /cm/shared from the host OS.