

Kubernetes
Kubernetes is an open-source platform for automating deployment, scaling, and operations of application containers across clusters of hosts. With Kubernetes, it is possible to:
-
scale applications on the fly
-
seamlessly update running services
-
optimize hardware usage by using only the resources that are needed
BCM provides the administrator with the required packages, allows Kubernetes to be set up on a cluster, and manages and monitors Kubernetes. More information about the design of Kubernetes, its command line interfaces, and other Kubernetes-specific details, can be found at the official online documentation at https://kubernetes.io/docs/.
To deploy most of Kubernetes, NVIDIA Base Command Manager from version 10.0 onwards uses kubeadm (https://kubernetes.io/docs/setup/production-environment/tools/kubeadm/).
BCM runs CoreDNS, the Kubelet component (https://kubernetes.io/docs/reference/command-line-tools-reference/kubelet/), and the entire control plane inside Kubernetes.
The distributed key-value store used for Kubernetes, etcd, is typically run inside of Kubernetes on control planes. However, in BCM etcd is run outside of Kubernetes.
Kubernetes integration with BCM is available for Kubernetes v1.34, v1.35, and v1.36 at the time of writing of this paragraph (July 2026). Kubernetes runs on the x86_64 and aarch64 architectures for all the BCM-supported Linux distributions. For a more up-to-date status, the feature matrix at https://service.bcm.nvidia.com/feature-matrix/ can be checked.
The version that is running on a cluster can be found with:
Example
The versions that are available with BCM integration can be found with the cm-kubernetes-setup utility (section 4.2):
Example
4.1 Reference Architecture
A reference architecture for Kubernetes in BCM comprises:
-
etcd nodes: An etcd cluster—the Kubernetes distributed key-value storage—runs on an odd number (1, 3, 5 …) of nodes.
-
control plane nodes: typically run on head nodes or on dedicated nodes. 2 or 3 are recommended.
-
worker nodes: typically run on regular nodes that are designated to run user workloads.
To avoid a single point of failure and to achieve high availability, a minimum of three nodes is recommended for etcd, and a minimum of two control plane nodes is recommended.
Kubernetes API server proxy: An NGINX server is configured on the head node(s) and on all other nodes involved in the Kubernetes cluster (control plane and worker nodes). This NGINX server takes care of exposing the Kubernetes API server on a specific port, and load balances requests to the control plane nodes. Should one of those nodes go down it can detect this and stop sending requests until the node comes back up.
Since BCM version 8.2, multiple clusters of Kubernetes can be deployed. In such a configuration, the same nodes cannot be shared across different Kubernetes clusters. Because of the NGINX server, a port is reserved on the head node(s) for every Kubernetes cluster. This is required for Kubernetes HA , and it also allows kubectl and other tools such as Helm to be used from the head node, to access each Kubernetes cluster.
Gateway Proxy: The same NGINX server is also used as the entry point on the head node(s) to forward traffic to the Kubernetes Gateways. This functionality is referred to as the “Gateway proxy” and is described in detail in section 4.17.
4.1.1 Hardware Requirements
To run properly, Kubernetes deployment requires a per-node minimum of
-
16 GB RAM
-
two CPU cores
Without these minimum requirements, deployment may succeed, but further configuration, such as starting up Jupyter kernels, may fail with problems that are hard to diagnose. For example, error reporting may not show a lack of resources because some components are automatically deleted.
4.2 Kubernetes Setup
The usual, and recommended way, to install Kubernetes with BCM is to install it interactively from a TUI session (section 4.2.8).
An alternative way, typically used for automated non-interactive setups, is to use a plain command line specification (section 4.2.7), which usually results in a long command line.
BCM deploys Kubernetes with the cm-kubernetes-setup utility, which is part of the cm-setup package. Several recent versions of Kubernetes are offered (figure 4.1):

Figure 4.1: Kubernetes setup TUI session (section 4.2.8): version selection screen
The TUI version selection offers the Kubernetes minor versions that the installed packages provide. The patch (http://semver.org) level within the chosen minor version is then asked for on the following screen (figure 4.5). At the time of writing of this section (August 2026), minor versions 1.34, 1.35, and 1.36 are the recommended and tested versions offered, providing patch levels 1.34.10, 1.35.7, and 1.36.3 respectively. The selected patch version should normally be retained. In special cases, the patch version can be changed in the saved configuration file:
-
The patch version can be removed to use the latest released patch version. However, because the latest version can change between runs, this can make the installation non-idempotent.
-
The patch version can be set to a version other than the recommended and tested version.
-
For an air-gapped deployment (Appendix B), each exact Kubernetes version expects a specific combination of system packages and container images, all of which must be present in the air-gapped deployment bundle. From BCM 11.34 onwards, the wizard validates this before installation begins, and fails early with a specific error message if the selected version does not match what was downloaded, instead of failing later during installation. Two kinds of error types can be shown, depending on which mismatch is detected:
-
A package version mismatch names each affected package and its found and expected versions, for both the head node and the default software image:
Example
-
A Helm chart version mismatch names the chart and its found and expected versions:
Example
-
-
BCM provides or uses the following Kubernetes-related packages:
-
conntrack(conntrack-toolson RHEL-based distributions) andnginx: These distribution packages are always installed on the head node(s) and on the control-plane and worker node(s). -
cm-etcd: This BCM package is installed on the nodes selected for etcd. In a similar way to the case of Harbor or Docker Registry (section 3.2), the nodes that run etcd are protected by BCM with thedatanodeoption (here). For etcd nodes, the option is added during thecm-kubernetes-setupinstallation. As in the case for the registries, the datanode option is set in order to help prevent the administrator from wiping out the existing state of etcd nodes. Wiping out the state of etcd nodes means that the Kubernetes cluster becomes incoherent and that it cannot be restored to where it was just before the etcd nodes were wiped. -
cm-containerd: This BCM package has the containerd runtime. -
cm-nvidia-container-toolkit: This BCM package has the NVIDIA container toolkit (includes NVIDIA container runtime). -
cm-kube-diagnose: This BCM package has Helper tools to diagnose malfunctioning Kubernetes clusters.
Kubernetes .rpm and .deb packages themselves are installed from the Kubernetes community-owned software repositories (https://kubernetes.io/blog/2023/08/15/pkgs-k8s-io-introduction/). These repositories host Kubernetes versions starting from v1.24.0 at the time of writing of this paragraph (March 2024).
-
4.2.1 Kubernetes Networking
Early on during the wizard session (figure 4.2), a name for the cluster is requested. The wizard pre-fills it with default, but this should not be confused with the Kubernetes default namespace. Here, the name is used instead, inside BCM, to identify the cluster, configuration files, and other resources such as module files.

Figure 4.2: Kubernetes setup TUI session: networking selection screen
This screen also allows the following important choices:
-
Kubernetes external FQDN: This is the FQDN that is placed as one of the entries in the public-facing certificates generated for this Kubernetes cluster.Configuring the public-facing certificate of the
bcm-gatewayGateway(served by Kgateway) is discussed further in section 4.17.7. -
Service network base addressandService network netmask bits: These define the CIDR for the service network. The wizard pre-fills the fields. It also tries to avoid pre-filling them with overlapping network ranges, by taking any existing network known to BCM into account. -
Pod network base addressandPod network netmask bits: These define the CIDR for the pod network. The wizard pre-fills these. It also tries to avoid pre-filling them with overlapping network ranges, by taking any existing network known to BCM into account. By default, entire /24 network ranges are assigned to individual Kubernetes nodes from the pod CIDR.
The packages are installed automatically from the repository when the administrator runs cm-kubernetes-setup from the command line.
The log file produced by the setup can be found in /var/log/cm-kubernetes-setup.log.
4.2.2 Kubernetes Core Add-ons
During setup, some critical add-on components such as the Networking Component for Kubernetes are automatically deployed. Most components are in the kube-system namespace, but others have their own namespaces. In BCM some add-ons are treated as Kubernetes applications (Chapter 5), and belong to the default app group, system. In the future Helm is expected to manage most, if not all, components instead of BCM Kubernetes applications.
The user is prompted for a Networking Component, Kubernetes operators (managed using Helm), Kubernetes add-ons (managed using Kubernetes applications), and more. They all result in either Helm charts being deployed, or in Kubernetes applications being managed from BCM.
A cmsh treeview illustrating the hierarchy to access these applications is:
Helm charts can be found using the helm command. For example using helm list -A on a cluster (after loading the correct module file).
In the past the DNS component was also provided as an add-on. However since BCM version 10.0, kubeadm is used to bundle CoreDNS as part of the default control plane.
Kubernetes apps are discussed further in Chapter 5. Kubernetes operators are discussed further in Chapter 6.
4.2.2.1 Kubeadm Components
Components deployed as part of the default Kubernetes control plane are:
-
Kubernetes API server
-
Kubernetes Scheduler
-
Kubernetes Controller Manager
-
Kubernetes Proxy
-
Core DNS
These are deployed through the “static pod” mechanism (https://kubernetes.io/docs/tasks/configure-pod-container/static-pod/). Kubernetes control plane components are described at: https://kubernetes.io/docs/concepts/overview/components/.
CoreDNS: CoreDNS is the DNS server add-on for internal service discovery. It reads the IP addresses of services and pods from etcd, and resolves domain names for them. If a domain name is not found because the domain is external to the Kubernetes cluster, then CoreDNS forwards the request to the main DNS server. BCM uses CoreDNS version 1.13.1 with Kubernetes version 1.35.
4.2.2.2 Networking Component
An important component managed through BCM’s Kubernetes Apps is the Networking component. This adheres to the Container Networking Interface, or CNI. At the time of writing the available CNIs in the setup wizard are either Calico or Flannel. However BCM does support other CNIs, for example Cilium, as described in the knowledge base article at https://enterprise-support.nvidia.com/s/article/installing-cilium-networking-for-kubernetes.
Flannel: Flannel is a simple and easy way to configure a layer 3 network fabric designed for Kubernetes.
Calico: Calico is a popular open source networking and network security solution for Kubernetes. It provides network connectivity between workloads and security policies features. It can be configured to use eBPF.
Further details on Calico can be found at https://docs.projectcalico.org/.
If the Kubernetes cluster is composed of more than 50 nodes, then the Calico component Typha is also automatically deployed for better scalability. The number of Typha replicas is calculated by allocating one Typha replica per 150 nodes, with a minimum of 3 (above 50 nodes) and a maximum of 20.
If an initial deployment of the Kubernetes cluster has fewer than 50 nodes, but nodes are then added to the Kubernetes cluster so that the 50 node threshold is exceeded, then Typha is not automatically enabled. In this case, Typha can be enabled manually using cmsh as follows:
Example
Cilium: Cilium (https://cilium.io/) is a networking, observability, and security solution with an eBPF-based dataplane.
4.2.3 Kubernetes Optional Components
The following components are installed by default unless otherwise noted. However, the user can choose to skip some or all of them during the setup.
4.2.3.1 Kgateway
Kgateway is the implementation that BCM uses to fulfill the Kubernetes Gateway API specification. It is discussed further in section 4.17.
4.2.3.2 MetalLB
MetalLB is a bare-metal load balancer that allocates external IP addresses to any LoadBalancer-type Service on the cluster. BCM deploys it alongside Kgateway to back the Kubernetes Gateways (section 4.17.4.1), but it can also be used outside the Gateway scope.
4.2.3.3 Kubernetes Metrics Server
The Kubernetes Metrics Server is an add-on that is a replacement for Heapster. It aggregates metrics, and provides container monitoring and performance analysis. It exposes metrics using an API.
4.2.3.4 Kubernetes State Metrics
kube-state-metrics is an add-on agent to generate and expose cluster-level Kubernetes metrics (section G.1.14 of the Administrator Manual) for objects. The project is not focused on the health of the individual Kubernetes components, but rather on the health of the various objects inside, such as deployments, nodes and pods.
4.2.4 Kubernetes Deprecated And Retired Components
The following components were part of BCM’s Kubernetes installation in earlier releases. They are no longer installed by default, and are documented here for reference and to point users to their replacements.
4.2.4.1 Kubernetes Dashboard (retired)
The Kubernetes Dashboard provided a web UI for cluster administration and metrics visualization in BCM versions before 11.32.0. It was retired upstream and has been removed in BCM version 11.32.0.
4.2.4.2 Ingress NGINX Controller (deprecated)
The Ingress NGINX Controller (ingress-nginx) provided ingress routing and web load balancing in BCM versions before 11.33.0 using standard Kubernetes Ingress resources, which were consumed together with ingress-nginx-specific annotations, such as nginx.ingress.kubernetes.io/*.
The Ingress NGINX Controller was deployed as a ingress-nginx Helm release. In BCM, it was exposed externally using the legacy Ingress proxy on the non-standard ports 30080 (HTTP) and 30443 (HTTPS), and the TLS certificate for externally-exposed services was served on 30443. It was deprecated upstream and in BCM starting with version 11.32.0, and is disabled by default from BCM 11.33.0, where it is replaced by Kgateway (section 4.17). For BCM clusters that were originally deployed with the Ingress NGINX Controller, the procedure to migrate to the Gateway-based stack is described in section 4.17.8.
The wizard marks the Ingress NGINX Controller as deprecated on the operator selection screen (section 4.2.8). It should not be selected for a new deployment without a good reason to do so.
The Ingress NGINX Controller should not be confused with the Ingress proxy. The controller runs inside Kubernetes. The Ingress proxy is an NGINX instance that runs outside Kubernetes, on the head node, and forwards external traffic into the cluster (section 4.9.3). The two are configured independently, so the Ingress Proxy Enable parameter being set says nothing about whether the Ingress NGINX Controller is in use.
4.2.5 Helm Kubernetes Package Manager
Helm is an add-on that manages charts, which are packages of pre-configured Kubernetes resources. The Helm component is installed and properly configured with BCM’s Kubernetes installation by default. It is initialized and ready for use by every Kubernetes user when the Kubernetes module is loaded. BCM uses Helm version 4.2.3.
When the Helm binary is installed during the Kubernetes setup, an offer is made to deploy charts during the setup process. Most operators are documented in Chapter 6.
Other parts of the wizard also determine which Helm charts are deployed as part of the setup for the following:
-
Kyverno and Kyverno Policies (section 4.10.1)
-
BCM Permissions Manager (section 4.15)
-
BCM Local Path Provisioner (section 4.20)
Example
4.2.6 Note On Run:ai Operator Dependencies
4.2.6.1 Selecting The Run:ai Operator Dependencies
When the cm-kubernetes-setup wizard is run, with the intent of running Run:ai as well, the operator selection screen must include the dependencies that Run:ai requires. For Run:ai 2.25, these are:
-
NVIDIA GPU Operator
-
Grafana Operator
-
Kgateway
-
Knative Operator
-
Kubeflow Training Operator
-
Kubernetes Metrics Server
-
Kubernetes MPI Operator
-
Kubernetes State Metrics
-
LeaderWorkerSet Operator
-
MetalLB
-
Network Operator (technically optional, but recommended)
-
NIM Operator (optional)
-
Prometheus Adapter
-
Prometheus Operator Stack
The Run:ai operator and its prerequisites are described in more detail in section 6.11.
4.2.7 Kubernetes Setup From The Command Line
The cm-kubernetes-setup command line utility has the following usage synopsis:
The preceding output does not list every argument that the utility accepts. Some valid arguments are not shown by --help. For example, --skip-headnode-check is accepted by the utility but is not listed. It is a development argument, and it is not part of any documented BCM procedure. An argument that is absent from the --help output may be valid, but is typically not intended for use by the end user.
The cm-kubernetes-setup utility should be executed on the console.
4.2.7.1 Dealing With A Pre-existing Docker Installation
Docker (Chapter 2) is no longer a requirement for Kubernetes configured by BCM. This is because Kubernetes can directly interface with containerd through its Container Runtime Interface (CRI). Docker can co-exist with Kubernetes, and can be set up as discussed in section 2.1.
4.2.8 Kubernetes Setup From A TUI Session
When the Kubernetes installation is carried out using cm-kubernetes-setup without any options, a TUI wizard starts up. The administrator can answer several questions in the wizard. Questions that are asked include questions about which of the node categories or which of the individual nodes should be configured to run the Kubernetes services. There are also questions about the service and pod networks parameters, the port numbers that will be configured for the daemons, which operators to install, and so on. After the wizard has been completed, a configuration file can be saved that can be used to set up Kubernetes, by default cm-kubernetes-setup.conf.
The configuration file can be deployed immediately from the wizard, or it can be deployed later by specifying it as an option to cm-kubernetes-setup, in the form -c <file>.
The layout of the configuration file can change between BCM releases. For example, the Flannel settings are stored under modules.kubernetes.flannel in BCM 11.33, and under modules.kubernetes.operators.flannel in BCM 11.34. A configuration file that was saved by one release should therefore not be assumed to work with another.
If no deployment has been carried out earlier, then the main operations screen of the wizard shows just two options, Deploy and Exit.
If deployment has already been carried out, then the further options that are available are also displayed (figure 4.3):
Example

Figure 4.3: Kubernetes setup TUI session: main operations screen after a deployment
One of the further options shown after a deployment is a Modify operators item, for adding operators to, or removing operators from, an existing cluster without re-running the full setup. This is described in section 6.15.
The deployment using CLI or using TUI assigns the appropriate roles, and adds the new Kubernetes cluster. The deployment adds health checks to the monitoring configuration, and it generates certificates for the Kubernetes daemons.
Operating the wizard:
The wizard is a terminal UI, where
-
the arrow keys (up, down, left, right) move between fields
-
the
<TAB>key moves between widgets such as the field area and the buttons along the bottom -
the
<SPACE>bar selects an option on screens that present a list of choices -
the
<ENTER>key, if pressed on a screen with a list of choices, advances to the next screen without changing the selection, which can take some getting used to -
the
< Help >button on the screen, if present, describes the setting in more detail than the screen itself.
The screens that follow are the ones presented when the wizard is run with the default operator selection. That is the path through the wizard, not a recommendation to accept every pre-filled value: some screens, such as the DockerHub registry mirror, need an answer that suits the site. Screens that appear only when a particular operator has been selected are not described here. Those are covered with the operator that they belong to, in chapter 6.
Kubernetes operations:
If no deployment has been carried out earlier, then this screen offers only Deploy and Exit as options (figure 4.4). The fuller set of options shown in figure 4.3 appears only after a cluster exists.
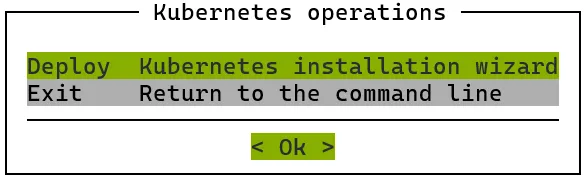
Figure 4.4: Kubernetes setup TUI session: main operations screen before any deployment
Choosing a Kubernetes version:
The wizard lists the Kubernetes minor versions available in the installed packages (figure 4.1). Versions certified for NVIDIA AI Enterprise are marked with an asterisk, and the legend on the screen explains the marking.
Choosing a Kubernetes patch level:
The version chosen on the preceding screen is a minor version. This screen selects the patch level within it (figure 4.5). Two entries are offered: latest, and the specific patch release that the installed packages provide. The specific release is pre-selected.
Choosing latest means that the patch level is resolved when the deployment runs, rather than being fixed now. For an air-gapped cluster the specific release should be chosen, because only the patch level that was mirrored into the tarball is available (section B.2).

Figure 4.5: Kubernetes setup TUI session: choosing the Kubernetes patch level
DockerHub registry mirror:
A registry mirror can be specified so that images are pulled from it rather than from DockerHub (figure 4.6). The field is pre-filled with an NVIDIA-internal host that is not reachable from customer sites. The value should therefore be replaced with the address of a mirror that the cluster can reach, or it should be cleared if no mirror is used.
For an air-gapped cluster, the mirror is the local container registry that is set up as part of the air-gapped procedure (section B.2).
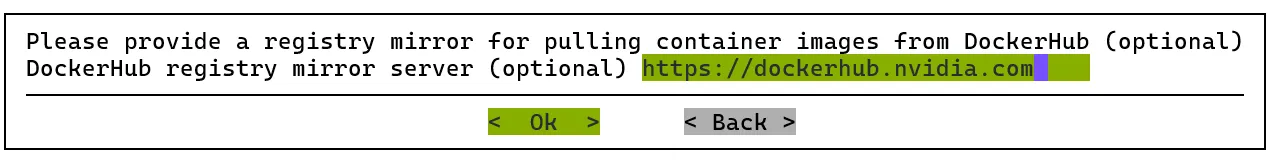
Figure 4.6: Kubernetes setup TUI session: DockerHub registry mirror
Basic cluster values:
The cluster name, domain, external FQDN, and the service and pod network CIDRs are set here (figure 4.2). The wizard pre-fills the network fields and tries to avoid ranges that overlap networks already known to BCM. These fields are described in detail in section 4.2.1.
Exposing the Kubernetes API server:
The Kubernetes API server can be exposed to the external network (figure 4.7). The wizard offers yes as the pre-selected answer, so accepting the default exposes the API server.
Leaving it unexposed means that the port is not opened to the external network, which is the safer choice. The API server is still reached through the NGINX proxy on the head node, so kubectl and Helm continue to work there. It should be exposed only if clients outside the cluster need to reach the API server directly.
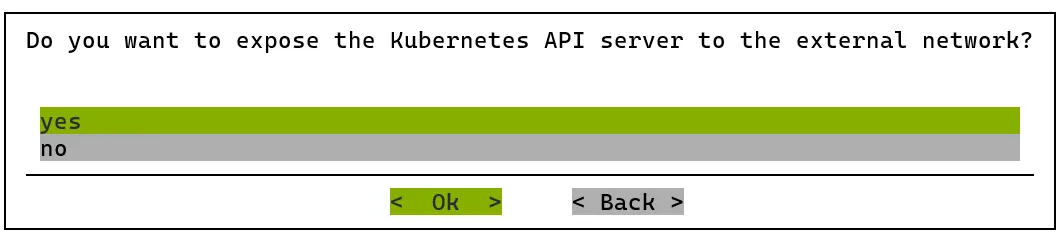
Figure 4.7: Kubernetes setup TUI session: exposing the Kubernetes API server
Selecting the internal network:
This is the network that Kubernetes nodes use to reach each other (figure 4.8). One network must be selected, using <SPACE>. On a cluster configured for high availability a third option, failovernet, is offered alongside externalnet and internalnet.
If the nodes do not share an IP address on the selected network, then their internal networks are configured as fallback networks.
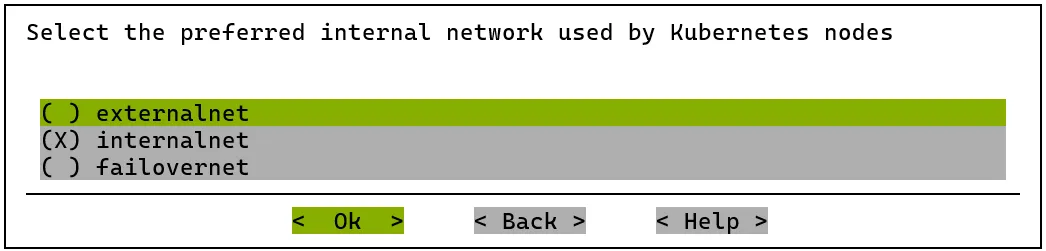
Figure 4.8: Kubernetes setup TUI session: selecting the internal network
The control-plane, worker, and etcd nodes are assigned on four consecutive screens (figures 4.9–4.12). The head node is pre-selected as a control-plane node and as an etcd node.
Worker nodes are assigned on two of those screens. The first selects whole node categories, and the second selects individual nodes. Selecting a category is sufficient on its own. If the intended worker nodes are all members of a category that has been selected, then the screen for individual nodes can be left with nothing selected, and it lists only the nodes that the category selection did not already cover.
An odd number of etcd nodes should be selected, as the screen itself states. An even-numbered cluster still establishes a quorum, but it tolerates no more failures than the odd number below it: a three-node and a four-node cluster both keep working with one node down, so the fourth node adds cost without adding fault tolerance.
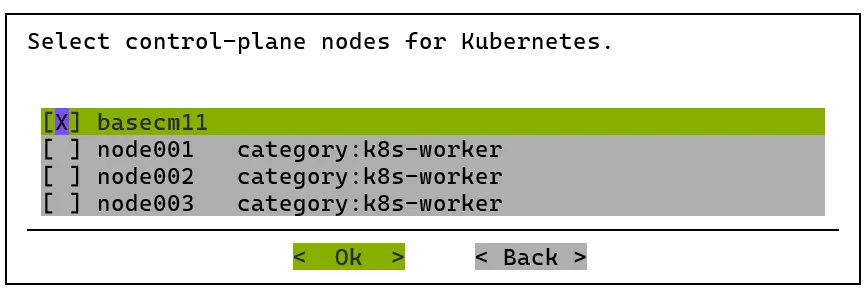
Figure 4.9: Kubernetes setup TUI session: assigning control-plane nodes

Figure 4.10: Kubernetes setup TUI session: assigning worker nodes by category

Figure 4.11: Kubernetes setup TUI session: assigning individual worker nodes
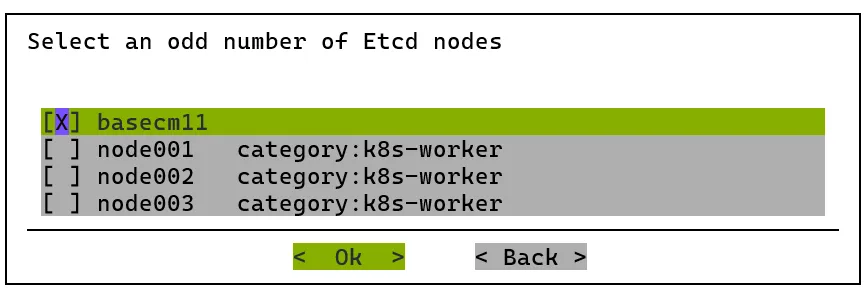
Figure 4.12: Kubernetes setup TUI session: etcd node assignment
Main Kubernetes component values:
The port numbers configured for the daemons have default assignments, but can be re-assigned as needed, and the etcd spool directory can be set (figure 4.13). The defaults are port 10443 for the API server proxy, and /var/lib/etcd for the etcd spool directory.

Figure 4.13: Kubernetes setup TUI session: main Kubernetes component values
Kubernetes network plug-in:
The CNI network plug-in is chosen here (figure 4.14). Calico, installed by way of the Tigera Operator, is pre-selected and is the recommended choice. Flannel is the alternative. These are the only two that the wizard offers. Both are described in section 4.2.1.
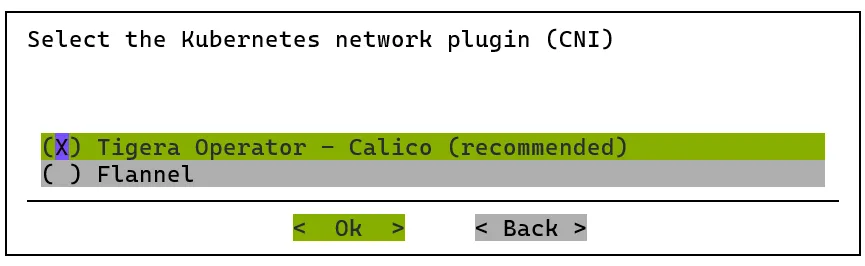
Figure 4.14: Kubernetes setup TUI session: selecting the CNI network plug-in
Kyverno policy engine:
The Kyverno policy engine is installed by default (figure 4.27). Kyverno is what BCM uses to enforce Pod Security Standards. PodSecurityPolicy provided that enforcement in older releases, and was removed in Kubernetes v1.25 (section 4.10.1).
If the policy engine is not installed, then Kubernetes Permissions Manager (section 4.15) still creates the namespace and the role bindings for each user, so users are separated from each other by RBAC. What is not created are the policies that restrict what a user may do inside their own namespace. On Kubernetes v1.25 and later there is no fallback for this, because the PodSecurityPolicy that used to provide it no longer exists.
A user in that situation can run privileged pods, and can mount arbitrary host paths. Those pods are created in the user’s own namespace, but neither capability is confined to it: a privileged pod and a host path mount reach the node filesystem and the container runtime. The exposure is therefore at node level, and through the node it extends to other workloads and to cluster data. The RBAC separation described above does not prevent this.
On a cluster with one administrator and no other users this can be acceptable. On a cluster that is shared between users it usually is not.
Kyverno policies:
The Kyverno policies are installed by default (figure 4.29). The policies are what implement the Pod Security Standards (section 4.14.2). The engine on its own enforces nothing.
On a cluster configured for high availability, a further screen asks whether Kyverno itself is to be set up for high availability (figure 4.28). That screen is not presented on a cluster with a single head node.
Namespaces excluded from the Kyverno policies:
Namespaces can be excluded from each of the cluster-wide policies (figure 4.15). Pods running in an excluded namespace are not subject to that policy. Each of the five policies takes its own comma-separated list, and each is pre-filled with the default namespace.
Further exclusions are added automatically during installation, based on the features that have been configured and the operators that have been selected. A namespace named on this screen is not created by the wizard, as the screen itself states.
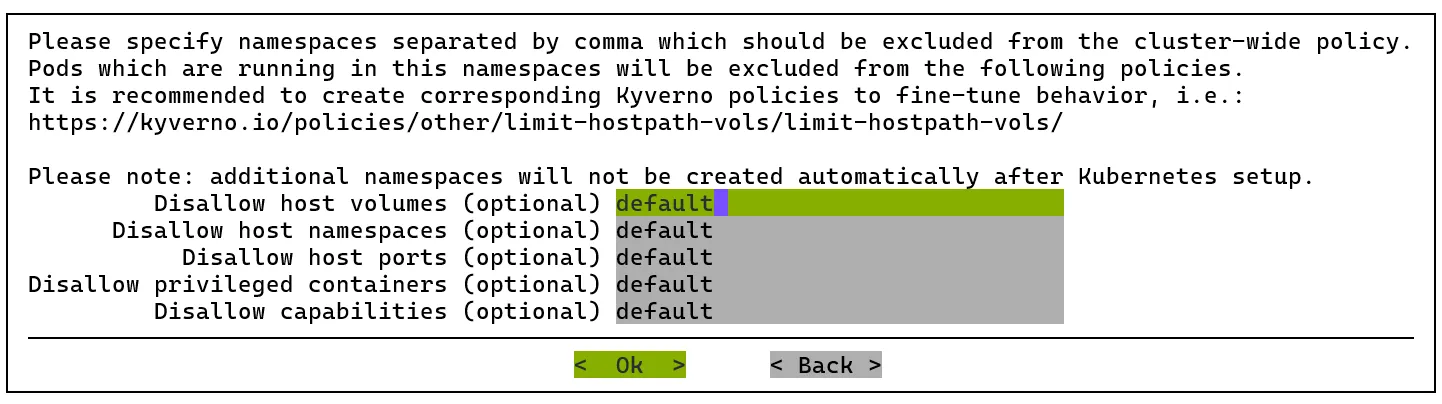
Figure 4.15: Kubernetes setup TUI session: namespaces excluded from the Kyverno policies
Selecting the operators:
Operator packages are application managers, and are described further in chapter 6. The operators that can be selected are listed below, in the order in which the wizard presents them:
-
NVIDIA GPU Operator
-
AgentGateway
-
AgentGateway CRDs
-
Argo CD
-
Grafana Alloy
-
Grafana Loki
-
Grafana Operator
-
Ingress NGINX Controller (deprecated, section 4.2.4.2)
-
Jupyter Kernel Operator (
cm-jupyter-kernel-operator) -
Kgateway
-
Knative Operator
-
KubeFlow Training Operator
-
Kubernetes Metrics Server
-
Kubernetes MPI Operator (
cm-kubernetes-mpi-operator) -
Kubernetes State Metrics
-
LeaderWorkerSet operator
-
MetalLB
-
Network Operator
-
NIM Operator
-
PostgreSQL Operator (
postgresql-operator) -
Prometheus Adapter
-
Prometheus Operator Stack
-
Spark Operator (
spark-operator)
Four of these are selected by default: Kgateway, Kubernetes Metrics Server, Kubernetes State Metrics, and MetalLB (figure 4.16). The rest are installed only if they are selected here.
The NVIDIA GPU Operator is not selected by default. It manages the Kubernetes device plugin that exposes NVIDIA GPUs as schedulable resources (section 6.7), and the wizard provides no other way to install that plugin. A cluster with NVIDIA GPUs therefore cannot run GPU workloads until the operator is installed. The wizard does not check whether the cluster has GPUs, and does not warn if the operator is left unselected. It does not have to be installed here: it can also be added to a running cluster (section 6.7.2).
The CNI network plug-in is not part of this list. It is chosen on the earlier screen shown in figure 4.14.
Each operator that is selected adds its own configuration screens later in the wizard. Those screens are described with the operator concerned, in chapter 6.

Figure 4.16: Kubernetes setup TUI session: selecting the operators to install
Prior to BCM 11.33, Run:ai was installed as part of cm-kubernetes-setup (figure 4.17). From BCM 11.33 onwards, Run:ai is deployed separately using the cm-runai-setup wizard after Kubernetes setup is complete (section 6.11.2.2).

Figure 4.17: Kubernetes setup TUI session: Run:ai operator selection (prior to BCM 11.33)
MetalLB mode:
MetalLB advertises the Gateway addresses either by ARP, in layer 2 mode, or by BGP (figure 4.32). Layer 2 mode is pre-selected and needs no external peer. BGP mode advertises through an external peer.
Gateway IP addresses:
One IP address is requested for each Gateway that is configured (figure 4.18). This is the address at which the Gateway is reached.
The field is pre-filled with the highest address on the Kubernetes node network that is not already in use. Addresses assigned to devices, addresses used by the head node for its filesystem mounts, the dynamic range of the network, and ranges already claimed by MetalLB address pools are all excluded. On a cluster with one head node this is typically the address just below the head node itself.
The pre-filled value can be replaced. An address that is already assigned to a device, or that overlaps a range already in use, is rejected with an error.

Figure 4.18: Kubernetes setup TUI session: Gateway IP address
MetalLB IP address pools:
Address pools can be defined for MetalLB to allocate from (figure 4.19). The list is empty by default. Rows are added with <ALT>-<A> and removed with <ALT>-<D>.
Leaving the list empty is correct on the default path. The Gateway does not take its address from a pool defined here. A pool holding only the Gateway address given on the previous screen is generated during the installation itself. Pools are added on this screen only for other services of type LoadBalancer.

Figure 4.19: Kubernetes setup TUI session: MetalLB IP address pools
Exposing the Kubernetes Gateways:
The Gateways can be exposed to the external network by enabling the Gateway proxy on the head nodes and edge directors (figure 4.34). This is enabled by default.
Gateway proxy configuration:
The port that the Gateway proxy listens on is set here (figure 4.35). The default is port 443.
BCM NVIDIA packages:
The cuda-dcgm package can be installed into the software images used by the Kubernetes nodes (figure 4.20). The screen lists the images that would be modified. The default is not to install it.
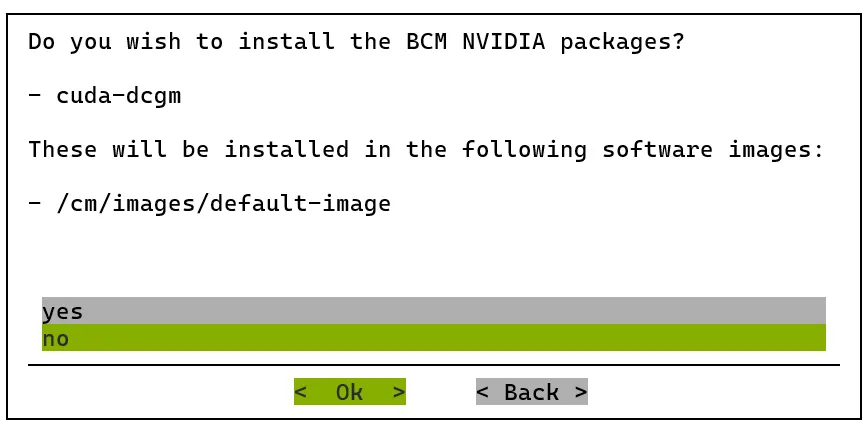
Figure 4.20: Kubernetes setup TUI session: installing the BCM NVIDIA packages
BCM NVIDIA Container Toolkit package:
The cm-nvidia-container-toolkit package can be installed on the head node and into the software images (figure 4.21). The screen lists the paths that would be modified. The default is not to install it.
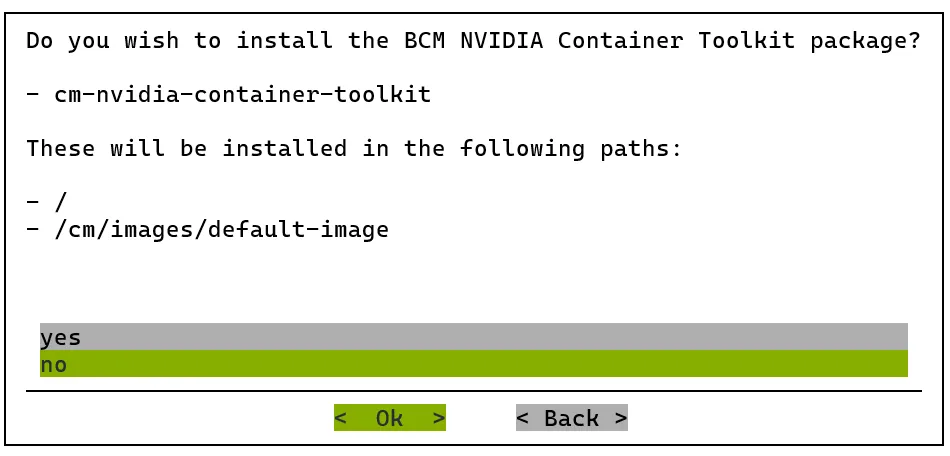
Figure 4.21: Kubernetes setup TUI session: installing the BCM NVIDIA Container Toolkit package
Both NVIDIA package screens are skipped if the GPU Operator is selected:
The two preceding screens are presented only when the NVIDIA GPU Operator has not been selected. If it has been selected, then the wizard decides both answers itself and does not ask:
-
the BCM NVIDIA packages are installed, because they are almost always wanted alongside the operator
-
the BCM NVIDIA Container Toolkit package is not installed, because the GPU Operator deploys and manages the container toolkit itself by default (chapter 6)
Running cm-kubernetes-setup with the --adv-configuration-bcm-nvidia-packages option presents both screens even when the GPU Operator has been selected, so that the answers can be set by hand.
Permission manager:
Kubernetes Permissions Manager (section 4.15) is installed by default (figure 4.22). As the screen states, it is needed only if non-root users are to use the cluster.
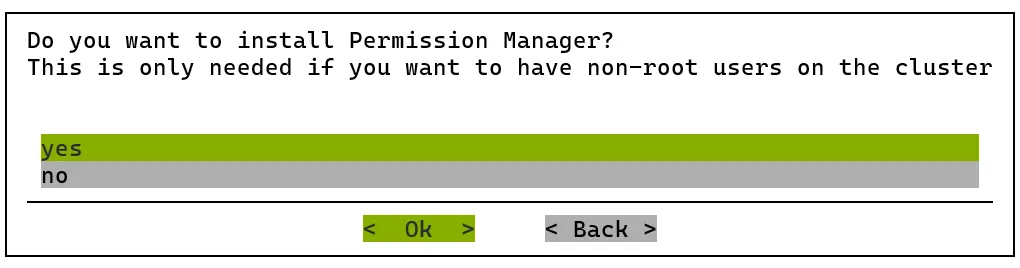
Figure 4.22: Kubernetes setup TUI session: installing Kubernetes Permissions Manager
Storage class:
The storage class for the cluster is configured here (figure 4.23). Local path storage is enabled by default, and is set as the default storage class. The alternative is to set no default storage class.
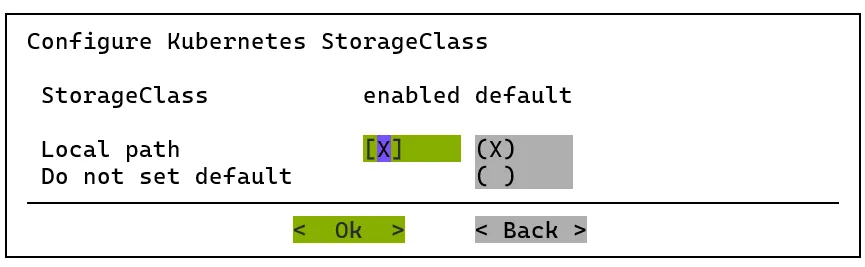
Figure 4.23: Kubernetes setup TUI session: configuring the Kubernetes storage class
Local path storage pool:
If local path storage is enabled, then the directory that backs it is set here (figure 4.24). The default is /cm/shared/apps/kubernetes/<cluster>/var/volumes, where <cluster> is the name of the Kubernetes cluster. A custom provisioner image can also be given, and is optional.
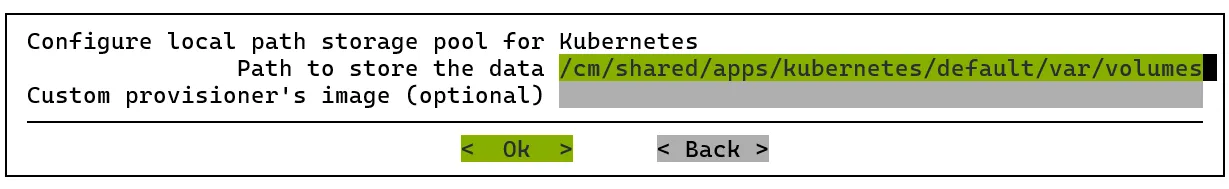
Figure 4.24: Kubernetes setup TUI session: configuring the local path storage pool
Summary:
The final screen offers the deployment and configuration file options (figure 4.25). The configuration can be deployed straight away, or written to a file to be deployed later with -c, or both. Save config & deploy is pre-selected.
The minimal config variants write a configuration file that records only the values that differ from the defaults. The full variants record every value. A minimal file is easier to read and to carry between systems. A full file is a complete record of the deployment, and does not change meaning if a default changes in a later BCM release.
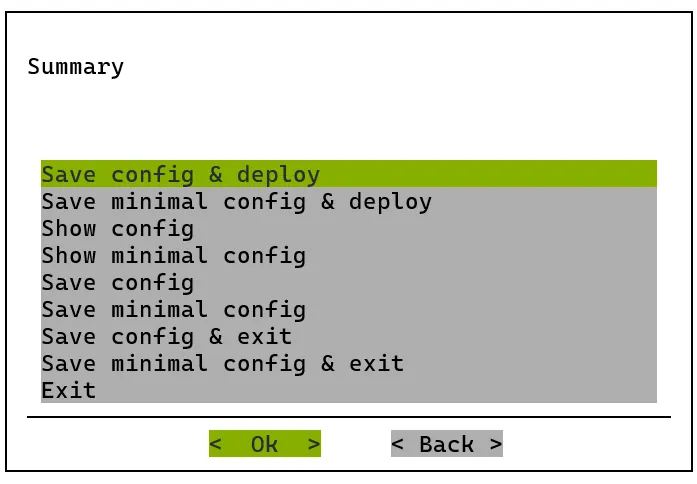
Figure 4.25: Kubernetes setup TUI session: summary screen
4.2.9 Testing Kubernetes
To test that Kubernetes works, the cluster-info command can be run. For example, on the head node, basecm11:
Example
After cm-kubernetes-setup finishes, and the regular nodes have been rebooted, the state of the nodes can be found by running the get nodes command:
Example
A six node cluster should show the following Kubernetes installed add-ons, when using kubectl with the get all -n kube-system option (some lines truncated):
Example
The administrator can now configure the cluster to suit the particular site requirements.
4.3 Using GPUs With Kubernetes: NVIDIA GPUs
4.3.1 Prerequisites
The GPUs have to be recognized by the nodes, and have the appropriate drivers (such as nvidia-driver) installed. Details on how to do this are given in Chapter 9 of the Installation Manual.
To verify the GPUs are recognized and have drivers in place, the nvidia-smi command can be run. The response displayed for a GPU should look similar to the following:
Example
If a non-BCM Containerd has already been deployed before Kubernetes is deployed, then cm-kubernetes-setup may replace an existing Containerd configuration file in order to enable NVIDIA GPU integration using a Kubernetes CNI plugin. This is because Containerd is configured by cm-kubernetes-setup, overwriting any previous configuration.
4.3.2 New Kubernetes Installation
As part of the setup, cm-kubernetes-setup assigns a new role to the Kubernetes worker nodes: generic::containerd.
The role has a Configurations submode, in which the containerd-cri object can be configured. The entry for Filename specifies the path to the cri.toml file, which contains content used by the container runtime interface on the Kubernetes worker nodes that have been assigned the role.
Example
The file with the CRI (Container Runtime Interface) configuration is created in directory:
and included into the main Containerd configuration file:
with the imports statement:
Whatever the container runtime that is selected, if NVIDIA GPU integration is required then the NVIDIA container toolkit is taken care of by the installer. The configuration for Containerd is added as a separate configuration file in the configurations submode, as nvidia-cri.
NVIDIA GPUs are integrated into Kubernetes using the NVIDIA GPU operator. This is discussed further in section 6.7.
4.3.3 Existing Kubernetes Installation
The NVIDIA GPU operator can always be deployed through Helm. The official documentation for the NVIDIA GPU operator is at
https://docs.nvidia.com/datacenter/cloud-native/gpu-operator/latest/overview.html
4.4 Using GPUs With Kubernetes: AMD GPUs
4.4.1 Prerequisites
The GPUs have to be recognized by the node. One way to check this from within BCM is to run sysinfo for the node:
Example
In order to make Kubernetes aware of nodes that have AMD GPUs, the AMD GPU device plugin has to be deployed as a DaemonSet inside Kubernetes. The official GitHub repository that hosts this plugin can be found at:
https://github.com/RadeonOpenCompute/k8s-device-plugin
The device plugin requires Kubernetes v1.16+, which has been around since BCM version 9.0. With some extra instructions, the plugin can also be made a part of BCM version 8.2.
The DaemonSet YAML file can be deployed with:
Example
4.4.2 Managing The YAML File Through CMDaemon
The plugin can be added by the user using the Kubernetes appgroups as an application. In the session that follows, it is given the arbitrary name device-plugin:
Example
The configuration of the plugin can be set to the YAML file, by setting the config parameter to take the value of the YAML file path.
Example
The YAML file can also be edited within cmsh after it has been set, by running set config without a value.
There are older releases available, starting from Kubernetes v1.10, if needed. Saving this device-plugin YAML should result in pods being scheduled on all the non-tainted nodes, as seen by listing the pods (some columns elided):
4.4.3 Including Head Nodes as part of the DaemonSet
BCM taints head nodes, so that they do not run non-critical pods. The taint can be removed with the “-” operator to allow non-critical pods to run:
Example
However, a more specific exception can be configured in the DaemonSet itself.
Within the YAML file, the following existing tolerations definition has to be modified, from:
to:
The modified toleration tolerates this taint, and therefore has the device plugin run on such tainted nodes.
4.4.3.1 Verifying That AMD GPUs Are Recognized By Kubernetes
If Kubernetes is aware of the AMD GPUs for a node then several mentions of amd.com/gpu are displayed when running the kubectl describe node command for the node. The following session shows output for a node gpu001, ellipsized for clarity:
Example
4.4.4 Running The DaemonSet Only On Specific Nodes
The AMD GPU device plugin, unlike the NVIDIA GPU device plugin Daemonset, is scheduled to run on each Kubernetes host. This means that it runs even if the host has no GPU.
This can be prevented with the following steps:
A LabelSet can be created using cmsh, and the nodes or categories that have GPUs are assigned within the labelsets mode:
Example
This assigns the labels to the nodes with GPUs. This can be verified with:
Example
The DaemonSet YAML can now be adjusted to only run the device plugin on nodes with this new label. This can be done by adding an affinity block after the tolerations block:
Example
This results in the device plugin pods being removed immediately from all nodes that do not have the label.
4.4.5 Running An Example Workload
An example workload can be run as described in the official AMD GPU Kubernetes device plugin documentation at:
https://github.com/RadeonOpenCompute/k8s-device-plugin/tree/v1.16#example-workload
Thus it should now be possible to run:
The YAML requests only one GPU at the bottom of the YAML file:
Container creation might take a while due to the image size. Once scheduled, it prints out that it found exactly one GPU, and proceeds to run a TensorFlow workload.
Example
Had more GPUs been requested, more would have been made available to the container.
For comparison, a CPU version of the container is also available. The official instructions can be referred to for these, too.
4.5 Kubernetes Configuration Overlays
A list of configuration overlays can be seen from within configurationoverlay mode:
Example
The NetQ configuration overlay is only normally displayed if NetQ is deployed.
Configuration overlays can be used to manage the Kubernetes services used with a particular configuration. For example, when managing the Kubernetes services used for a Kubernetes engine within an Auto Scale tracker (section 8.4.9 of the Administrator Manual).
4.6 Removing A Kubernetes Cluster
A Kubernetes cluster can be removed using cm-kubernetes-setup with the --remove and --yes-i-really-mean-it options. Also, if there is more than one cluster present, then the cluster name must be specified using the --cluster parameter.
A removal run looks as follows (some output ellipsized):
Example
Using the --remove option removes the Kubernetes cluster configuration from BCM, unassigns Kubernetes-related roles—including the EtcdHost role—and removes Kubernetes health checks. The command does not remove packages that were installed with a cm-kubernetes-setup command before that.
After the disabling procedure has finished, the cluster has no Kubernetes configured and running.
4.7 Kubernetes Cluster Configuration Options
Kubernetes allows many Kubernetes clusters to be configured. These are separated sets of hosts with different certificates, users and other global settings.
When carrying out the Kubernetes setup run, a Kubernetes cluster name is asked, and a new object with the cluster settings is then added into the CMDaemon configuration. The administrator can change the settings of the cluster from within the kubernetes mode of cmsh, or within the Kubernetes Clusters options window of Base View accessible using the navigation path Containers > Kubernetes Clusters.
The cmsh equivalent looks like:
Example
The preceding kubernetes mode parameters are described in table 4.1:
Table 4.1: kubernetes mode parameters
4.8 EtcdCluster
The EtcdCluster mode sets the global etcd cluster settings. It can be accessed using the top level etcd mode of cmsh.
* Boolean (takes yes or no as a value)
Table 4.2: EtcdCluster role parameters and etcd options
4.9 Kubernetes Roles
Kubernetes roles include the following roles:
-
EtcdHost(here) -
KubernetesApiServerProxy(here) -
Kubelet(here) -
generic::containerd(here) -
generic::netq(here)
When nodes are configured using Kubernetes roles, then settings in these roles may sometimes use the same values (pointer variables).
Example
and
Pointer variables such as these have definitions that are shared across the roles, as indicated by the parameter description tables for the roles, and which are described in the following pages.
In cmsh, the roles can be assigned:
-
for individual nodes using the
rolessubmode ofdevicemode -
for a category using the
rolessubmode of a category -
for a configuration overlay using the
rolessubmode ofconfigurationoverlaymode
4.9.1 EtcdHost Role
The EtcdHost role is used to configure and manage the etcd service for a node.
The etcd service manages the etcd database, which is a hierarchical distributed key-value database. The database is used by Kubernetes to store its configurations. The EtcdHost role parameters are described in table 4.3:
* Boolean (takes yes or no as a value)
Table 4.3: EtcdHost role parameters and etcd options
The etcd settings are updated by BCM in /cm/local/apps/etcd/current/etc/cm-etcd.conf.
4.9.2 The KubernetesAPIServerProxy Role
The KubernetesApiServerProxy role sets up a proxy that provides the entry point for one or more instances of the Kubernetes API server. The proxy runs on every node of a Kubernetes cluster instance, including the head node.
If multiple Kubernetes control-plane nodes are present, then it enables HA for the Kubernetes control plane components (section 4.1).
This means that local port 10443 on all these nodes load balances over all control-plane node API servers.
Port 10443 can also be opened up for external access. The cm-kubernetes-setup wizard (section 4.2) in one of its screens (figure 4.26) prompts for this.
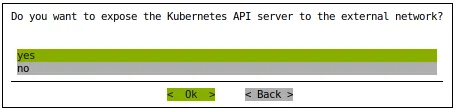
Figure 4.26: Wizard question
If the prompt is answered with no, then the firewall role on the head node can still be customized with cmsh later on:
Example
4.9.3 The KubernetesIngressServerProxy Role
This role used to provide the “Ingress Proxy” (also known as “Ingress Server Proxy”) functionality, configuring the head-node NGINX to expose the Kubernetes ingress externally. In BCM 11.33.0 and later the role is almost a placeholder, because the head-node NGINX configuration is now offloaded to the Kubernetes setup itself, which generates and applies it using the Configure Gateway proxy to route traffic from head node(s) to Gateways item of cm-kubernetes-setup (section 4.17.6.3).
The role and the related Kubernetes cluster entity parameters (for example Ingress Proxy Enable, Ingress Proxy Listen Port, Ingress Proxy Backend Port) keep their original names for backward compatibility.
4.9.4 The Kubelet Role
The Kubelet role is used to configure and manage the kubelet service. BCM takes care of joining these nodes with kubeadm join when needed.
Control plane: The Kubelet role has a parameter Control plane that is set to the value yes for control plane nodes. In that case it also runs Kubernetes control plane services, such as:
Workers: The Kubelet role has a parameter worker that is set to yes for worker nodes. In that case, the control plane pods will not be running on the node.
The Kubelet role parameters are described in table 4.4:
* Boolean (takes yes or no as a value)
Table 4.4: Kubelet role parameters and kubelet options
Further details on the Kubelet service can be found at https://kubernetes.io/docs/reference/command-line-tools-reference/kubelet/.
4.9.4.1 CPU Manager And Topology Manager Policy On GPU Nodes
From BCM 11.34 onwards, GPU worker nodes are automatically configured with a static CPU manager policy and a best-effort topology manager policy. These settings enable workloads running on GPU nodes to request exclusive CPU allocation and benefit from NUMA-aware scheduling. The default kubelet settings (cpuManagerPolicy=none and topologyManagerPolicy=none) are suboptimal for GPU workloads: without CPU pinning, containers share CPUs via time-slicing, which causes cache thrashing and inconsistent throughput in the GPU data pipeline; and without topology awareness, CPU, memory, and GPU allocations may be placed on different NUMA nodes, forcing host → device data transfers to cross the inter-socket interconnect at reduced bandwidth.
The following kubelet settings are applied automatically to nodes that have GPUs:
-
cpuManagerPolicy: staticenables the static CPU manager, which grants exclusive CPU access to guaranteed-QoS containers that request whole CPUs. -
topologyManagerPolicy: best-effortenables the topology manager, which attempts to align CPU, memory, and device (GPU) allocations to the same NUMA node. -
topologyManagerScope: podapplies topology alignment at the pod level, so that all containers in a pod share the same NUMA node affinity. -
kubeReserved: {cpu: 250m}reserves a small amount of CPU for Kubernetes system components.
Control plane nodes and non-GPU worker nodes use the default kubelet configuration and are not affected by these settings. Clusters deployed before BCM 11.34 are also not affected, since kubeadm upgrade reuses the existing in-cluster kubelet configuration.
Further details on the CPU manager and topology manager policies can be found at https://kubernetes.io/docs/tasks/administer-cluster/cpu-management-policies/ and https://kubernetes.io/docs/tasks/administer-cluster/topology-manager/.
4.9.4.2 The options Submode
The full path to the files should be specified for the options command. For example, kube-apiserver.yaml may be specified as /etc/kubernetes/manifests/kube-apiserver.yaml.
4.9.5 Containerd Role
The Containerd role is used to configure and manage the containerd daemon. This is done through a generic role in BCM. Generic roles under Kubernetes are found under the cmsh path indicated by: cmsh > configurationoverlay[kube-object] > roles[generic::role]
Example
The role has several submodes:
-
The
configurationssubmode: This contains various configuration drop-ins.Configuration drop-ins that BCM may manage in the
generic::containerdrole are:-
NVIDIA Container Toolkit configuration.
-
Docker registry certs directory configuration.
-
Docker Hub credentials configuration.
-
Harbor Registry Mirror configuration.
-
CRI cgroup configuration.
-
CNI bin dir configuration.
-
CRI registry configuration.
-
CRI custom sandbox image configuration.
The drop-ins that are actually available depend on choices made by the cluster administrator during deployment.
-
-
The
environmentsubmode: This has optional environment variables that are made available to the configuration files and that are to be used as templates. -
The
excludelistsnippetssubmode: This has files related to containerd that need to be excluded, such as the most obvious directory/var/lib/containerd.
4.10 Security Model
The Kubernetes security model allows authentication using a certificate authority (CA), with the user and daemon certificates signed by a Kubernetes CA. The Kubernetes CA should not be confused with the BCM CA.
BCM lets kubeadm create a CA specifically for issuing all Kubernetes-related certificates. The certificates are put into /etc/kubernetes/pki/<kube cluster label>/ by default.
In Kubernetes terminology a user is a unique identity accessing the Kubernetes API server. The user may be a human or an automated process. For example an admin or a developer is a human user, but kubelet represents an infrastructure user. Both types of users are authorized and authenticated in the same way against the API server.
Kubernetes uses client certificates, tokens, or HTTP basic authentication methods to authenticate users for API calls. BCM configures client certificate usage by default. The authentication is performed by the API server which validates the user certificate using the common name part of the certificate subject.
In Kubernetes, authorization happens as a separate step from authentication. Authorization applies to all HTTP accesses on the main (secure) API server port. BCM by default enables RBAC (Role-Based Access Control) combined with Node Authorization. The authorization check for any request thus takes the common name and/or organization part of the certificate subject to determine which roles the user or service has associated. Roles carry a certain set of privileges for resources within Kubernetes.
4.10.1 Kyverno
BCM has support for the Kyverno policy engine (https://kyverno.io/). If Kyverno is installed, then Kubernetes Permissions Manager (section 4.15) creates policy manifests packed as a Helm chart for every user added to Kubernetes using cm-kubernetes-setup. In addition, a kyverno-policy chart is installed in enforce mode to implement Pod Security Standards (https://kyverno.io/policies/). During installation, some exclusions are added to the policies automatically to make chosen features of the Kubernetes cluster work.
For every created user the following defaults are applied:
-
The user has an associated service account with the same name
-
A <username>-restricted namespace is created. So, for a user
johnthe namespace isjohn-restricted. -
An
editcluster role is bound to the service account in <username>-restricted namespace. The user is allowed to create pods, services, configmaps, etc. in the namespace -
The user is allowed to list nodes in the cluster
-
Kyverno policies are applied to the resources in <username>-restricted namespace or to pods created or updated by the associated user
-
If hostPath is not the home directory of the user (of the format
/home/<username>) then the creation of the resource is denied -
The UID and GID of the running process are set to the same value as the UID and GID of the PAM user
-
Modifications from the defaults are:
-
If the
Allow any UID process in podscheckbox is ticked, or if the--allow-all-uidsargument is specified, then the UID and GID of the running process becomes the user’s UID and GID only if the hostPath volume is specified. Otherwise it can be set to any UID and GID. -
Cluster roles can be set not only to
edit
but also to
-
view -
admin -
cluster-admin
More details on these roles can be found at:
https://kubernetes.io/docs/reference/access-authn-authz/rbac/#user-facing-roles. -
In addition, the user can be given access to custom CRDs, such as Postgres Operator, Jupyter Operator or Google Spark Operator
4.10.2 PodSecurityPolicy
PodSecurityPolicy (PSP) was available in older versions of BCM. However, PSP support was completely removed in Kubernetes v1.25. BCM therefore now uses Kyverno (section 4.10.1) for an equivalent functionality.
4.11 Addition Of New Kubernetes Users
BCM users can use Kubernetes by making them Kubernetes users. This means having Kubernetes configuration and access set up for them. This can be carried out using the cm-kubernetes-setup TUI utility, and choosing the Add user option (figure 4.3). The utility then prompts for
-
a Kubernetes cluster
-
a user name
-
a namespace that the privileges are to be assigned to
-
a role for the user, with choices provided from:
-
cluster-admin: cluster-wide administrator -
admin: administrator -
edit: regular user -
view: read-only user
-
-
a switch if the user is allowed to run as any user, including root, inside pods
-
a comma-separated list of paths that the user is able to mount to pods
-
the UIDs and GIDs for user processes in pods
-
a list of the Kubernetes operators that a user can use
Based on the input, a YAML for the Kubernetes Permission Manager is generated. This in turn, creates a Helm chart with all the required roles, role bindings, and Kyverno rules.
Creation of the user also triggers CMDaemon to create certificate and configuration files in the ~/.kube directory
4.11.1 Adding Users Non-Interactively With cm-kubernetes-setup
The user-management options are included in the complete cm-kubernetes-setup -h output in section 4.2.7.
The user has to be a user that exists on the cluster already and available using PAM.
If --add-to-namespace is specified, then the namespace has to exist on the Kubernetes cluster already.
Example
The preceding example creates a user john for the default john-restricted namespace. It also assigns the edit role, and gives permission to run processes in the pod with the current UID/GIDs of the user. The ability to mount ~/john as a hostPath is also provided.
A way to assign any of the default Kubernetes user-facing roles is also provided by using --role key, as documented at https://kubernetes.io/docs/reference/access-authn-authz/rbac/#user-facing-roles
The possible roles are: view, edit, admin, and cluster-admin.
Example
The preceding example creates a user john with view privileges only, for the default john-restricted namespace.
Example
The preceding example creates a user john with the following privileges:
-
editprivileges -
able to mount
/home/johnand/scratchas hostPath volume, when the process runs with UID/GIDs taken from the PAM subsystem on the moment of creation -
able to run as any user, including root (attempts to mount any hostPath volume will be rejected)
-
access to the Jupyter Kernel Operator, i.e. with access to the resource
kind: CmKubernetesOperatorPermissionsJupyterKernel
4.12 Getting Information And Modifying Existing Kubernetes Users
It is possible to edit user properties and permissions. cm-kubernetes-setup provides 2 ways of doing it: interactively or using CLI options.
Modifying users can be done interactively by choosing Modify User in the cm-kubernetes-setup main menu. Guidance is then given on choosing the cluster, users, and on modifying permissions.
Modifying users can also be done using CLI options, by specifying the --modify-user argument:
Example
The default john-restricted namespace is created as user john is added, along with the settings specified by the other options. The following example then adds permission to mount the /scratch hostPath into pods, and gives access to the Postgres Operator:
Information about existing users can be found with:
Example
Permission for user john to operate in the dev namespace can be added with:
Example
Permission for the user john to operate in the dev namespace can be revoked with:
Example
4.13 List Of Resources Defined For Users
These resources are rendered by the Permission Manager Operator, and can therefore be found inside Kubernetes.
4.13.0.1 The Role Bindings Deployed For Every User By Default
By default, the role bindings deployed for the user john created in the preceding section are:
-
ClusterRole/john-nodes(in namespacejohn-restricted) -
ClusterRoleBinding/john-nodes(in namespacejohn-restricted)
User john is given read-only rights for the Nodes resource (for kubectl get nodes).
4.13.0.2 The Secure Namespace Related Resources
The secure namespace for user john is:
Namespace/john-restricted
The service account used by john:
ServiceAccount/john(in namespacejohn-restricted)
This is found referenced, for example, in john’s $HOME/.kube/config.
The PodSecurityPolicy that defines the user can run non-privileged pods, and use only ports above 1024, and so on:
PodSecurityPolicy/john-restricted(in namespacejohn-restricted)
More details on this can be found in section 4.10, here. This policy will only do something as soon as the PodSecurityPolicy Admission Controller is enabled in the API server.
A PodSecurityPolicy that defines the user can run as root as well, but without hostPath volumes:
PodSecurityPolicy/john-restricted-root(in namespacejohn-restricted)
To give the aforementioned privileges to john’s secure namespace, so that john can run workloads, execute kubectl get all, and more:
-
Role/john-restricted(in namespacejohn-restricted) -
RoleBinding/john-restricted(in namespacejohn-restricted)
The RoleBinding assigns it to the user john and ServiceAccount account for john. The upstream documentation at https://kubernetes.io/docs/reference/access-authn-authz/service-accounts-admin has more details on this.
The user john can be given the ability to use the PodSecurityPolicy defined earlier in his secure namespace, but also in other namespaces:
-
ClusterRole/john-psp(in namespacejohn-restricted) -
ClusterRoleBinding/john-psp(in namespacejohn-restricted)
The same ability can be given for the second root but no hostPath PodSecurityPolicy:
-
ClusterRole/john-psp-root(in namespacejohn-restricted) -
ClusterRoleBinding/john-psp-root(in namespacejohn-restricted)
If the Kyverno engine is installed then several policies are added:
-
clusterpolicies.kyverno.io/john-*-drop-privs-w-hostpath*: Policy to modify pod manifests to run process with specified UID/GID -
clusterpolicies.kyverno.io/john-*-limit-hostpath-vols: Policy to deny pods if hostPath volumes do not match specified paths
The full content of all the documents created for the user can be viewed by checking the generated Helm manifest:
Example
4.14 Kyverno
Kyverno (https://kyverno.io/) is a policy engine designed for Kubernetes. With Kyverno, policies are managed as Kubernetes resources, and no new language is required to write policies. This allows the use of familiar tools such as kubectl, git, and kustomize to manage policies. Kyverno policies can validate, mutate, and generate Kubernetes resources, as well as ensure container image supply chain security.
4.14.1 Kyverno Installation
Kyverno engine and Kyverno policy Helm charts can be installed as a part of cm-kubernetes-setup:

Figure 4.27: Choosing Kyverno installation
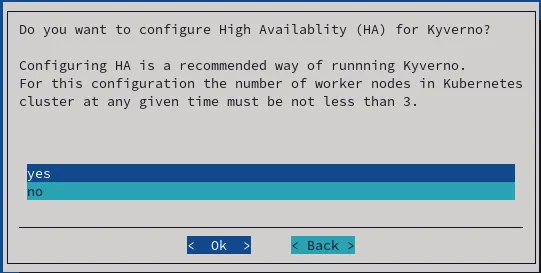
Figure 4.28: Kyverno high availability setup

Figure 4.29: Kyverno policy setup
The installation adds 2 Helm charts in the namespace ’kyverno’:
If the HA option is chosen, then the replica count value is set to 3.
This means that at any given time Kubernetes scheduler tries to run 3 pods at the same time:
4.14.2 Kyverno Policies
It is also recommended to install Kyverno policies in order to enforce Pod Security Standards https://kyverno.io/policies/. BCM configures Kyverno policies in ’enforce’ mode, adding service namespaces during cm-kubernetes-setup as exclusions (figure 4.30).

Figure 4.30: Kyverno policy: Defining the excluded namespaces
The list of namespaces to be excluded from particular policies depends on features selected during installation:
In the preceding output, all namespaces that match the wildcard *-restricted are excluded from the policy named ’disallow-host-path’ (https://kyverno.io/policies/pod-security/baseline/disallow-host-path/disallow-host-path/). This means that, without additional restrictions, all pods in the user namespaces can mount any host path from an underlying node.
To prevent that Kubernetes Permission Manager creates a Kyverno Cluster Policy for every newly-created user, and restricts the hostPath to only the home directory of the user:
4.15 Kubernetes Permission Manager
The Kubernetes permission manager is a custom operator based on Helm. It helps to manage user and system account permissions, roles, role bindings and pod security policies. The operator itself is packed and distributed as a Helm chart, so it can be installed during Kubernetes cluster creation using the cm-kubernetes-setup TUI. The Helm chart for the operator is located in /cm/shared/apps/kubernetes-permissions-manager/current/helm. The output to the following command shows if it is installed:
The Helm chart of the operator includes custom resource definitions (CRD), and makes it possible for the administrator to manage resources using the kubectl tool:
Example
At the time of writing of this section (December 2021), the permission manager handles these 6 CRDs:
-
cmkubernetespermissionusersto manage user access to generic resources of the cluster, such as pods, services, secrets, configmaps, etc. -
cmkubernetesoperatorpermissionsjupyterkernelsto manage access to the Jupyter Kernels. -
cmkubernetesoperatorpermissionspostgresqlsto manage access to the Postgres operator (https://github.com/zalando/postgres-operator). -
cmkubernetesoperatorpermissionsmpisto manage access to the MPI operator (https://github.com/kubeflow/mpi-operator). -
cmkubernetesoperatorpermissionsnimsto manage access to the NIM operator (https://docs.nvidia.com/nim-operator/). -
cmkubernetesoperatorpermissionssparksto manage access to the Google Spark operator (https://github.com/GoogleCloudPlatform/spark-on-k8s-operator).
Providing access to third party operators is necessary if pod security policy is enabled. This is because, by default, not only does the user have no access to CRDs, but also the service accounts of the third party operators have no access to the user namespace.
The following example is a YAML document that provides access to the Jupyter Kernel Operator:
Every installed CRD document triggers the Kubernetes permission operator to create a corresponding Helm chart:
It is also possible to customize the resulting Helm chart by specifying additional values to specify a section of the CRD. The 6 Helm chart CRD directories can be seen with:
Example
For example, available values for the Jupyter kernel can be checked using the following command:
Example
Similarly, tunables for the generic user permissions of the user are available using:
Example
The output should be similar to:
4.16 Providing Access To External Users
External access to a BCM Kubernetes cluster falls into two distinct paths, each using its own port on the head node(s) and described in their own subsections:
-
access to the Kubernetes control plane itself, for administrative tooling such as
kubectlandhelm, using the Kubernetes API server proxy port (10443by default), and covered in section 4.16.1. -
access to applications and services running on the cluster, using the Gateway proxy port (
443by default), and covered in section 4.16.2.
A schematic overview of the data and control paths is shown in figure 4.31:
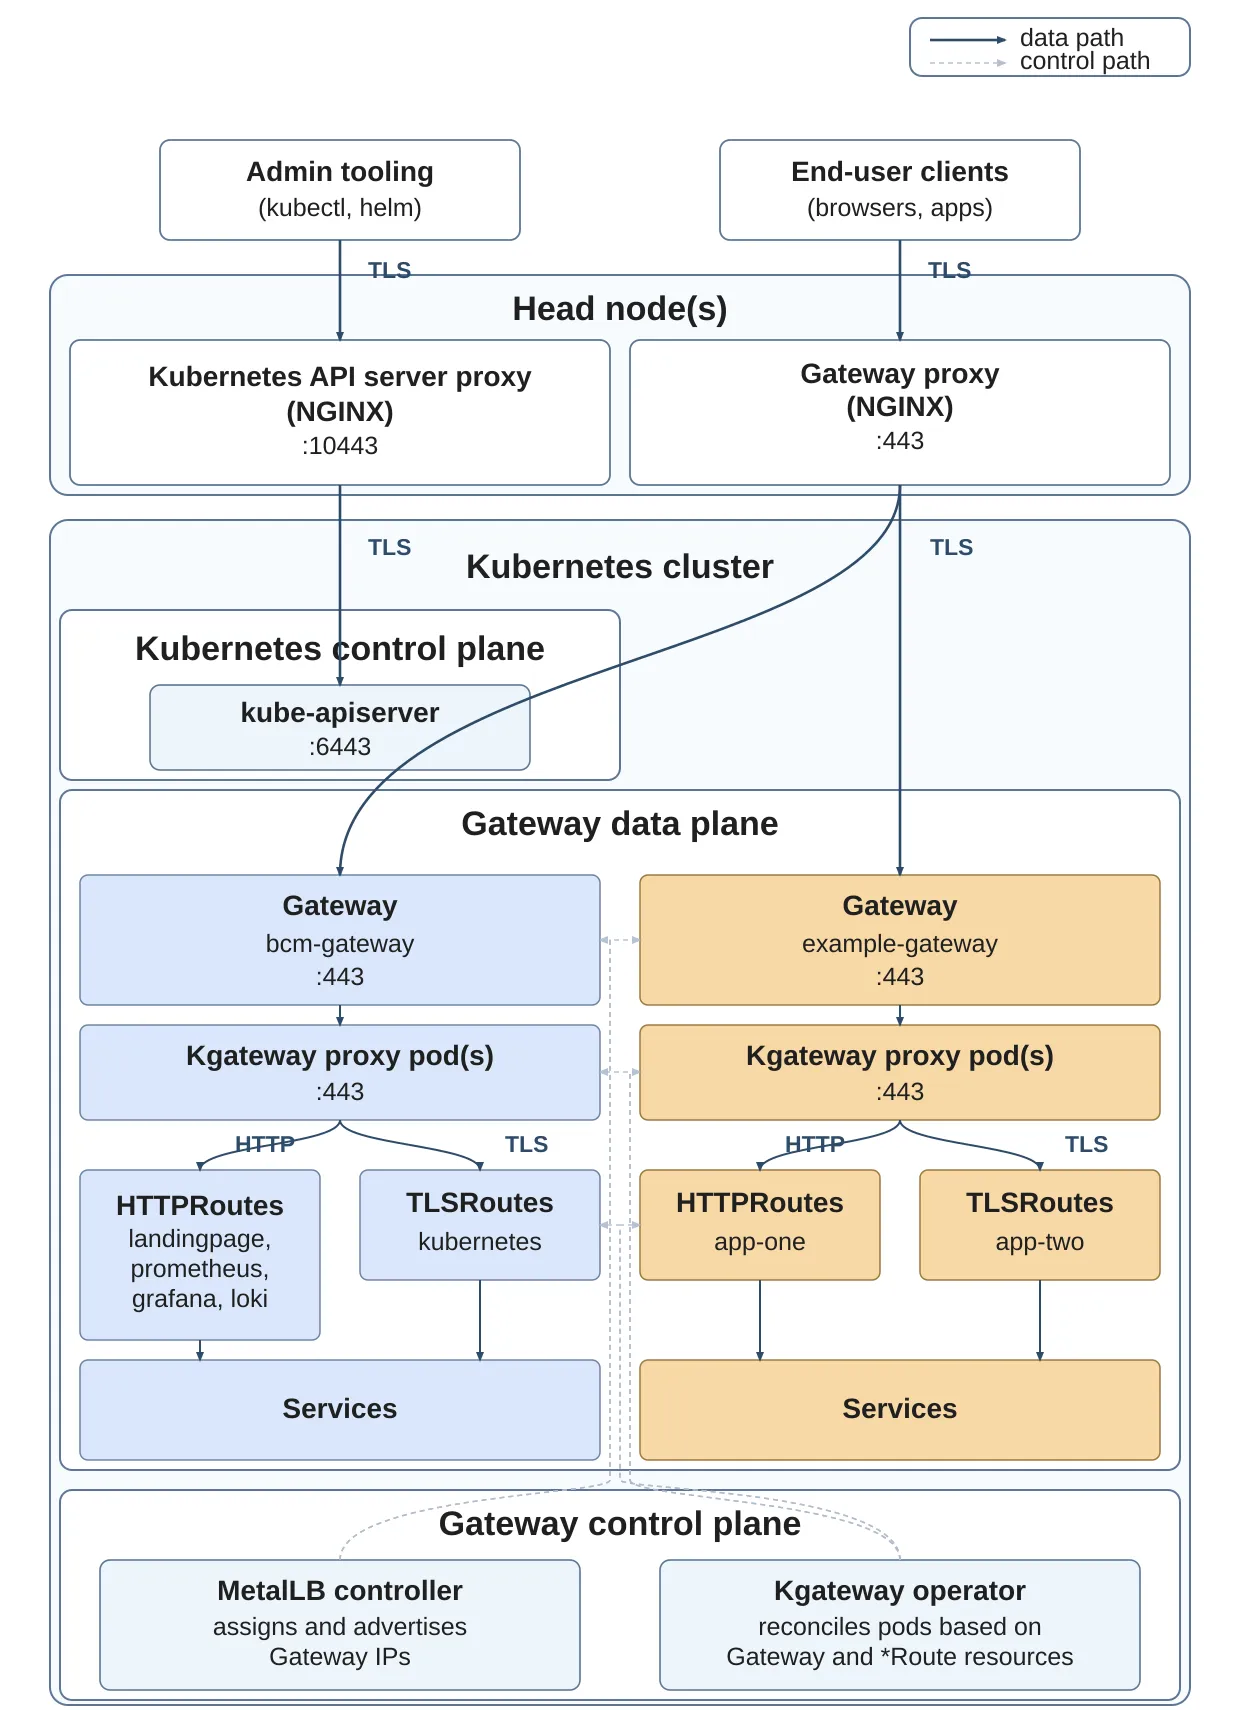
Figure 4.31: Data and control paths between the Kubernetes gateways and proxies
If exposing the Kubernetes API server to the external network is selected during setup with cm-kubernetes-setup, then both the Kubernetes API server proxy port and the Gateway proxy port are opened on the Shorewall service that runs on the head node. Exposure to the external network is enabled by default.
4.16.1 External Access To The Kubernetes Control Plane (kubectl, helm)
For administrative tooling such as kubectl and helm to reach the Kubernetes API server from outside the cluster, an entry in the company/internal DNS server should resolve the external FQDN of the cluster to the head node (or to one of the nodes where Kubernetes is running). The external FQDN is set during the Kubernetes cluster setup, and is the first item in the list of trusted domains configured on the Kubernetes cluster entity. It can be retrieved with cmsh as follows:
Example
In the preceding example, the FQDN of the cluster is basecm11.example.com. The cluster administrator managing their own cluster will have another FQDN, and not this FQDN.
The port on which the Kubernetes API server is exposed externally is the Kubernetes API server proxy port. It can be retrieved from the Kubernetes cluster entity as follows:
This port is opened automatically by Shorewall on the head node when the exposing the Kubernetes API server to the external network option is selected during cm-kubernetes-setup, as mentioned earlier.
4.16.2 External Access To Kubernetes-hosted Applications And Services
Applications and services running in Kubernetes are exposed externally through the Gateway components, which are fully covered in section 4.17. For any service that needs its own subdomain (for example, myapp.<cluster-fqdn>, used as a hostname in a Gateway API route resource—such as an HTTPRoute or TLSRoute—attached to a Kubernetes Gateway), a corresponding DNS entry under the external FQDN must be added.
4.17 Kubernetes Gateway
Starting with BCM 11.33.0, support for the Kubernetes Gateway API (currently version 1.5.x) is introduced, provided by Kgateway and MetalLB. External traffic is exposed using the Gateway proxy on its listening port (443 by default) on the head node(s), which forwards that traffic to the configured Gateways served by Kgateway (the bcm-gateway Gateway by default, and any additional Gateways that have been added).
The 4.17 BCM Kubernetes Gateway components are:
Kgateway (https://kgateway.dev/): the controller that fulfills the Kubernetes Gateway API (https://gateway-api.sigs.k8s.io/) specification on the cluster, reconciling Gateway, HTTPRoute, TLSRoute, and related resources, and spinning up Kgateway proxy pods that actually handle traffic for each Gateway.
MetalLB (https://metallb.universe.tf/): provides a LoadBalancer Service IP address for each Gateway in the same way that a cloud provider’s load balancer would do for Kubernetes running in a managed cloud, and makes that IP address routable from outside the cluster.
The Gateway proxy: an NGINX server running on the head node(s) and edge directors, provided by the KubernetesIngressServerProxy role (section 4.9.3). It serves as the single entry point on the head node(s) for external clients, and forwards incoming traffic on its listening port to the appropriate Gateway based on the TLS Server Name Indication (SNI) hostname.
4.17.1 Gateway API
The Kubernetes Gateway API is a Kubernetes-defined API specification, not a controller. The Gateway, HTTPRoute, TLSRoute, and related resources follow this specification, and are intended to be implementation-agnostic. BCM provides Gateway API 1.5.x. Kgateway is the implementation that BCM uses with the specification, and the resources that the applications and operators define according to the specification are, in most cases, portable across any conformant Gateway API implementation. The official documentation for the Kubernetes Gateway API explains the model in detail.
4.17.2 Kgateway
With Kgateway the control plane and the data plane are split:
-
The Kgateway operator itself is the control plane. It watches the Gateway API resources (
Gateway,HTTPRoute, etc.) and reconciles them. -
The data plane is created on demand, per
Gateway, in the form of one or more Kgateway proxy pods that actually handle incoming traffic.
A consequence of this split is that only installing the Kgateway operator does not, by itself, expose any traffic: a Gateway (with a corresponding GatewayClass) must also be created so that the Kgateway operator can spin up the proxy pod(s) for it.
4.17.3 The bcm-gateway Gateway
All BCM-shipped applications and operators expose their Kubernetes-hosted services through the configured Gateways. The configured gateways are the bcm-gateway Gateway by default, and any additional Gateways that have been added (section 4.17.5) using Gateway API HTTPRoute or TLSRoute resources attached to those Gateways. The configured routes and the Gateways themselves can be inspected with kubectl:
The full YAML of an individual route can be inspected with kubectl. For example, the BCM-shipped HTTPRoute landingpage attached to the default bcm-gateway Gateway can be viewed with:
The spec.parentRefs entry binds this HTTPRoute to the default bcm-gateway Gateway (named bcm-gateway in the bcm-gateway namespace), and the spec.rules entry forwards traffic matching the / path prefix to a Kgateway Backend named landingpage, which is configured as a static Backend pointing to master:80, where the BCM landing page service runs on the head node(s) and is served by apache2 or httpd. Multiple backends and path-based routing can be configured through additional HTTPRoute resources attached to the same bcm-gateway Gateway.
4.17.3.1 Attaching Application Routes To The bcm-gateway Gateway
Applications can attach their own HTTPRoute or TLSRoute resources to the bcm-gateway Gateway alongside the BCM-shipped routes shown in the preceding text. This is the simplest way to expose an application externally, as it avoids having to allocate and configure an extra IP address. For an application to be allowed to attach routes, its namespace must first be added under the relevant listener’s allowedRoutes.namespaces.selector.matchExpressions on the bcm-gateway Gateway.
4.17.4 MetalLB
4.17.4.1 Gateway IP Address Assignment And Routability
Each Gateway is exposed using a LoadBalancer Service that requires its own IP address, which is unique across all Gateways, and also unique across different Kubernetes clusters. In a bare-metal BCM deployment there is no cloud load balancer to allocate such IP addresses, so this responsibility is delegated to MetalLB (https://metallb.universe.tf/), which is installed alongside Kgateway. MetalLB allocates an IP address from a configured pool to each Gateway’s LoadBalancer Service and makes that IP address routable from outside the cluster.
MetalLB supports two modes for advertising the assigned IP addresses:
-
L2mode (Layer 2 / ARP): No special network equipment configuration is required, which makesL2mode the simplest to deploy. It provides basic failover-style HA, but not true load-balancing. The main limitation is that traffic can only reach the Gateway through nodes that are in the same L2 network as the client. When the Gateway proxy is enabled, this means that at least one Kubernetes node must be in the same L2 network as the head node(s), so incoming traffic can be forwarded through the head node(s) to reach Kubernetes services. Further details can be found at https://metallb.universe.tf/concepts/layer2/.- In
L2mode,cm-kubernetes-setupsuggests sensible default IP addresses on a best-effort basis by filtering out many known used or assigned IP addresses and IP ranges. These suggestions may still conflict with the environment into which the setup is carried out. The customer must ensure that eachGatewayuses a unique, routable, IP address.
- In
-
BGPmode: The MetalLB speakers establish BGP sessions with the network’s BGP-capable routers and advertise theServiceIP addresses as routes. This provides a higher level of HA together with true load balancing, since traffic is distributed across nodes. This requires a BGP peer to be available upfront—typically a network router, switch, or similar device.Further details can be found at https://metallb.universe.tf/concepts/bgp/.
During the initial cm-kubernetes-setup session, the wizard prompts for the MetalLB mode to use for Kubernetes Gateways (figure 4.32).

Figure 4.32: Wizard prompt: select the MetalLB mode for Kubernetes Gateways
If BGP mode is selected, the wizard then prompts for the specific BGP settings (figure 4.33).
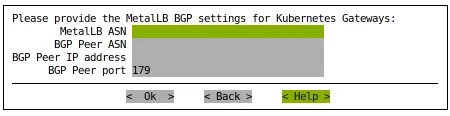
Figure 4.33: Wizard prompt: MetalLB BGP settings for Kubernetes Gateways
The MetalLB mode is configured per Kubernetes cluster and therefore applies to all Gateways in that cluster. The number of Kgateway proxy pods, by contrast, is determined per Gateway using the chosen GatewayClass (section 4.17.5.1), so different applications within the same cluster can scale their data plane independently. The same Gateways work with either MetalLB mode.
4.17.4.2 L2 Mode: Restricting Which Nodes Participate In The Gateway Data Plane
The L2-mode limitation described in the preceding text means that some care is needed in deciding which Kubernetes nodes participate in the Gateway data plane. BCM manages this automatically when the Gateway proxy is enabled, but the cluster administrator should still validate whether other BCM compute nodes need to reach the Gateway from a different L2 network.
BCM uses a dedicated labelset in cmsh, exclude-lb, backed by the standard upstream Kubernetes node label node.kubernetes.io/exclude-from-external-load-balancers (https://kubernetes.io/docs/reference/labels-annotations-taints/). When this label is present on a node:
-
MetalLB does not use that node to advertise any
LoadBalancerServiceIP address. -
Kgateway does not schedule any of its proxy pods on that node.
The label thus keeps the Gateway IP address advertisement and the corresponding proxy pods co-located on the same set of nodes, which avoids the failure mode where an IP address is announced from a node that does not actually host the proxy pod.
cm-kubernetes-setup manages the exclude-lb labelset as follows:
-
In
L2mode with the Gateway proxy enabled, the labelset is applied to Kubernetes nodes that are not on a network shared with head nodes. This ensures that MetalLB advertisement and Kgateway proxy pod scheduling occur only on the other nodes that do share networks with the head node(s). -
In
L2mode with the Gateway proxy disabled, the labelset is not applied to any node. It is then up to the cluster administrator to optionally add nodes to the labelset based on node needs. -
In
BGPmode no nodes are added to the labelset either. This means that all Kubernetes nodes can participate in the Gateway data plane, and no further action is needed from the cluster administrator.
Nodes can be added to or removed from the exclude-lb labelset in cmsh, for example:
Example
4.17.5 Creating Additional Gateways
Applications that need to be exposed externally can either attach their routes to the default bcm-gateway Gateway (section 4.17.3.1), or create an additional Gateway as described in the following subsections.
4.17.5.1 Provided Gateway Classes
A Gateway references a GatewayClass that determines how the Gateway is implemented (which controller fulfills it, and with how many proxy pods). BCM provisions three Kgateway-backed GatewayClass resources, differing only in the number of Kgateway proxy pods that back the corresponding Gateway:
-
kgateway: 1 Kgateway proxy pod (suitable for non-HA deployments) -
kgateway-ha2: 2 Kgateway proxy pods -
kgateway-ha3: 3 Kgateway proxy pods
The default bcm-gateway Gateway is provisioned against the kgateway-ha2 class, giving it two Kgateway proxy pods. Additional Gateways can reference any of the provided classes.
The available classes can be listed with:
4.17.5.2 MetalLB Resources
When an additional Gateway is created, the MetalLB resources need to be created as well, in order to assign and advertise an IP address for that Gateway. This subsection describes the manifests that are applied, mirroring what cm-kubernetes-setup creates for the default bcm-gateway Gateway (section 4.17.4.1).
For each additional Gateway, two MetalLB resources are required, both in the metallb-system namespace:
-
An
IPAddressPoolthat holds the IP address (or range of IP addresses) that MetalLB can assign to theGateway, and—optionally—restricts the pool to that oneGatewayusingserviceAllocation. -
An advertisement resource that exposes the assigned IP address to the network. The value of
kindsets the cluster’s MetalLB mode (section 4.17.4.1):-
L2Advertisementfor L2 mode -
BGPAdvertisementfor BGP mode.
-
In BGP mode the BGPPeer that BCM provisions in the metallb-system namespace is cluster-wide, and does not need to be duplicated for additional Gateways. The new BGPAdvertisement reuses it automatically.
The manifests that follow are a valid starting point, but additional Gateways can deviate from this shape. For example:
-
a wider CIDR or a range in
spec.addressescan be used, which means that the pool can serve multipleLoadBalancerServices -
omitting
serviceAllocationmakes the pool generally available, -
services can be selected on different labels or namespaces.
The upstream MetalLB documentation has the full schema of each resource.
Detecting the MetalLB mode: Whether BGP mode is available for an additional Gateway can be checked by looking for the BCM-managed BGPPeer named gateway in the metallb-system namespace:
Example
If the BGPPeer exists, then the cluster was set up with BGP mode and an additional Gateway can reuse that peer by applying a BGPAdvertisement. BGP mode is generally the better choice when it is available—the trade-offs between the two modes are described in section 4.17.4.1. L2 mode is always usable as well, regardless of whether the BGPPeer exists, by applying an L2Advertisement instead.
Naming convention: The gateway- name prefix in the metallb-system namespace is reserved for MetalLB resources that cm-kubernetes-setup creates and manages itself, so the names of MetalLB resources for an additional Gateway must not start with that prefix. A common convention is to reuse the Gateway’s own name (or <gateway-namespace>-<gateway-name>) as the MetalLB resource name.
IP address selection: The IP address, or range chosen for the additional Gateway must:
-
be unique across all
Gateways (and across other Kubernetes clusters that may share the same network), as described in section 4.17.4.1 -
not overlap with any other
IPAddressPoolin the cluster, including the ones created bycm-kubernetes-setup -
be routable from the intended clients, taking into account the L2-mode restriction on which nodes participate in the
Gatewaydata plane (section 4.17.4.2)
IPAddressPool: Apply an IPAddressPool containing the chosen IP address as a /32 entry, and use serviceAllocation to bind the pool to the specific additional Gateway using the gateway.networking.k8s.io/gateway-name label that Kgateway sets on the LoadBalancer Service:
Example
The serviceAllocation stanza restricts this pool so that it is only used for the additional Gateway. It does not restrict the additional Gateway to this pool. If another IPAddressPool on the cluster is generally available (autoAssign: true, with no serviceAllocation restricting it away from this Service), then MetalLB can still assign an address from that pool instead of this dedicated one, bypassing the intended assignment. For serviceAllocation to have its intended effect, every other IPAddressPool that could serve the same Service must either set autoAssign: false or carry its own serviceAllocation restriction. This must be in place before the Service is created: an address already assigned to a Service is not reassigned automatically.
L2Advertisement (L2 mode): In L2 mode, apply an L2Advertisement that references the IPAddressPool:
Example
BGPAdvertisement (BGP mode): In BGP mode, apply a BGPAdvertisement instead, again referencing the IPAddressPool. No additional BGPPeer is needed—the BGPPeer that cm-kubernetes-setup provisioned for the default bcm-gateway Gateway handles the BGP session with the upstream router:
Example
4.17.6 Gateway Proxy
The Gateway proxy is implemented by NGINX on the head node(s) and edge directors. Its configuration is generated and applied by cm-kubernetes-setup, which also opens the Gateway proxy port (443 by default) in the firewall. The related parameters (such as Ingress Proxy Enable and Ingress Proxy Listen Port) live on the Kubernetes cluster entity in cmsh, and the corresponding head-node role is the KubernetesIngressServerProxy role (section 4.9.3).
4.17.6.1 Architecture
The Gateway proxy listens on the head node(s) on its listening port and uses TLS Server Name Indication (SNI) to decide where to forward each incoming connection:
-
Connections that present a SNI hostname matching a hostname declared by one of the configured
Gateways’ listeners are forwarded to that specificGateway’sLoadBalancerServiceIP address. -
Connections without a SNI hostname (for example, when a client connects to the head node by IP address), and connections with a SNI hostname that does not match any of the configured
Gatewaylisteners, are forwarded to the defaultbcm-gatewayGateway.
On the Gateway side, the matching listener must be on port 443. The backend port that the Gateway proxy connects to on each Gateway’s LoadBalancer Service is exposed by the Ingress Proxy Backend Port parameter on the Kubernetes cluster entity in cmsh, which defaults to 443. This value is used internally by the Gateway proxy and is not intended to be customized.
4.17.6.2 Configuration During Setup
During the initial cm-kubernetes-setup session, two wizard screens drive the Gateway proxy configuration:
- A yes/no prompt (figure 4.34) asking whether to expose the Kubernetes
Gateways to the external network by enabling the Gateway proxy on the head node(s) and edge director(s). Selectingyes(recommended) enables it. Selectingnoskips it; the Gateway proxy can still be configured later using the menu item described in section 4.17.6.3, or by following the manual steps in section 4.17.6.4.

Figure 4.34: Wizard prompt: expose the Kubernetes Gateways by enabling the Gateway proxy?
- A follow-up
Customize Gateway proxy configurationscreen (figure 4.35) asking on which TCP port the Gateway proxy should listen. The default is443, which matches the standard HTTPS port and is what the rest of this documentation assumes.
Figure 4.35: Wizard prompt: Customize Gateway proxy configuration (Gateway proxy port)
4.17.6.3 The Configure Gateway proxy Menu Item
After the initial setup, the same head-node NGINX configuration can be regenerated and re-applied at any time using the Configure Gateway proxy to route traffic from head node(s) to Gateways item, found under the Gateway configuration menu of cm-kubernetes-setup. Selecting that item inspects the Gateways currently present on the cluster, collects their LoadBalancer Service IP addresses assigned by MetalLB and the hostnames declared on their listeners, and then refreshes the head-node NGINX Gateway proxy configuration accordingly so that the SNI-based routing described in section 4.17.6.1 reflects the current set of Gateways. This item is therefore re-run whenever a new Gateway is added or an existing one is changed.
4.17.6.4 Manual Configuration
If the wizard prompt about exposing the Kubernetes Gateways by enabling the Gateway proxy was answered with no during the initial cm-kubernetes-setup session, the Gateway proxy can still be enabled afterwards by carrying out the following steps.
Step 1: ensure the Gateway proxy port is not already in use: If the configured Gateway proxy port is already in use (for example, by the Gateway proxy of another Kubernetes cluster, or by the BCM landing page when served on that port using apache2 or httpd), then that port must be changed.
If the Gateway proxy port is the default 443, then for Ubuntu-based systems this means commenting out Listen 443 in /etc/apache2/ports.conf. For RHEL-based systems that line is located at /etc/httpd/conf.d/ssl.conf. If a different Gateway proxy port was configured, then the corresponding Listen directive for that port must be adjusted instead.
The web service should then be restarted (apache2 for Ubuntu, httpd for RHEL and Rocky).
Step 2: enable the Gateway proxy in the Kubernetes cluster entity: On the Kubernetes cluster entity in cmsh, Ingress Proxy Enable should be set to yes, and Ingress Proxy Listen Port should be set to the desired Gateway proxy port.
The parameter gateway_proxy_enabled must also be set. It is an additional entry for BCM 11 versions later than point release version 11.33.0, required as the Gateway proxy replaces the legacy Ingress.
The example below uses the default port 443.
Example
Step 3: assign the role to the head nodes: This can be done as follows in cmsh, and should be repeated for the passive head node in case of an HA BCM cluster.
Example
As the preceding session shows, assigning the role immediately affects the /etc/nginx/nginx.conf file and the nginx service, but the actual Gateway proxy routing configuration is generated and applied in Step 4.
Step 4: run the Configure Gateway proxy menu item: This is described in section 4.17.6.3.
Step 5: open the Gateway proxy port in the firewall: The port in the default firewall, Shorewall (section 7.2 of the Installation Manual), is managed using the firewall role in cmsh. Only the Gateway proxy port needs to be opened, in addition to the Kubernetes API server proxy port. The example below uses the default Gateway proxy port 443; if a different port was configured in Step 2, use that value instead.
The pre-existing 10443 entry shown above with the description Kubernetes 'default' API Server proxy is automatically opened by the KubernetesApiServerProxy role when exposing the Kubernetes API server to the external network was selected during cm-kubernetes-setup. In the example above, the newly-added port 443 entry has no description because it was added manually; it can be commented or otherwise tagged later if needed. As shown above, the change is reflected immediately in the /etc/shorewall/rules file and shorewall service.
4.17.7 Configuring The Gateway TLS Certificate
Kubernetes applications that are exposed externally on BCM use HTTPS using the Gateway proxy port, served by the configured Gateways (the bcm-gateway Gateway by default, and any additional Gateways that have been added). The TLS certificate that the bcm-gateway Gateway presents is the certificate that needs to be configured for external access.
For the bcm-gateway Gateway, it is assumed that
-
the cluster administrator has provided the cluster with a domain name, for example
my-cluster.nvidia.local -
there is a DNS entry present that makes this domain name resolve to the cluster IP address
-
a matching
bcm-gateway.keyandbcm-gateway.crtTLS certificate key pair file has been provided
4.17.7.1 Gateway Self-signed Certificate
For testing purposes it is possible to create a self-signed certificate with a private certificate authority (CA) owned by the cluster administrator, and configure the bcm-gateway Gateway to present it. That is, using that instead of a trusted (third-party) CA. However the effort needed to configure this means that the procedure is not generally recommended. Reasons to avoid using a self-signed certificate are:
-
each user needs the self-signed CA certificate pairs working on their system between the appropriate applications
-
each user also needs to override a warning about the untrusted certificate by accepting the self-signed certificate on browsers such as Chrome.
-
it is very easy to run into subtle issues later on that are hard to uncover
That said, appendix A has instructions on setting up a self-signed certificate for testing purposes. The steps that are needed to also make the certificates trusted on any given subsystem or application such as the web browser, are outside the scope of the manuals and BCM support. It is assumed that this has already been set up by the organization.
4.17.7.2 Gateway Trusted CA Certificate
In case no self-signed certificate is to be used—for example if there is already a trusted CA certificate to use for this purpose—then another Kubernetes wizard session can be run from the active head node to configure the bcm-gateway Gateway TLS certificate. The cluster administrator carries out the following procedure:
-
uses SSH to get into the active head node
-
copies certificate pair files,
bcm-gateway.crtandbcm-gateway.key, over to the head node (for example: to the/rootdirectory) -
invokes
cm-kubernetes-setup, opens theGateway configurationmenu, and then chooses (figure 4.36):Configure TLS Certificate for Gateway -
answers
yeswhen the wizard prompts:Do you want to configure an existing, properly signed certificate pair? -
sets paths to the certificate pair files; the wizard then stores the certificate pair as the Kubernetes TLS
Secretgateway-bcm-gateway-certin thebcm-gatewaynamespace, and references thatSecretfrom thebcm-gatewayGatewaylistener -
confirms that the HTTPS certificate is working correctly, using the SAN check (described shortly)

Figure 4.36: The Configure TLS Certificate for Gateway item under the Gateway configuration menu
The SAN check: The following command can be used to inspect the SAN (Subject Alternative Name) part of the certificate currently presented by the bcm-gateway Gateway using the Gateway proxy port:
Example
4.17.8 Migrating An Existing Kubernetes Cluster From Ingress To Gateway
For BCM clusters that were originally deployed with the legacy Ingress NGINX Controller (BCM versions before 11.33.0), the following procedure migrates the cluster to Kubernetes Gateway without recreating the cluster.
Prerequisites: Before starting the migration:
-
All applications and operators that currently rely on Kubernetes
Ingressresources should either already support, or be ready to be migrated to, the Kubernetes Gateway API. -
If the legacy Ingress proxy is currently used for external access, a maintenance window should be planned, since that external traffic will be interrupted during the migration.
Step 1: deploy the Gateway components: The cm-kubernetes-setup utility is started on the active head node. From its Gateway configuration menu, the Install Gateway components and replacements for legacy BCM Ingresses item is selected. The exact actions performed by this step are summarized by the wizard confirmation dialog.
This step is intentionally non-destructive in the sense that it does not uninstall the Ingress NGINX Controller, and it does not delete any existing Ingress resources. However, it does reconfigure the legacy Ingress proxy on the head node(s) to behave as the Gateway proxy, so external traffic through the legacy Ingress path no longer works after this step.
Step 2: adjust external load balancer configuration: If any external load balancer currently sends traffic to the legacy Ingress proxy ports (30080 and/or 30443, with 30443 the default HTTPS port), it should be updated to use the Gateway proxy port instead. This ensures that external traffic reaches the head-node Gateway proxy rather than the legacy Ingress proxy path while the Gateway-based path is being validated.
Step 3: validate traffic for the BCM-shipped services: With the Gateway components running, the BCM-shipped services that were previously fronted by Ingress—the landing page, the Kubernetes API at the configured external FQDN, Prometheus, Grafana, and Loki, where applicable—should be verified through the new bcm-gateway Gateway using the Gateway proxy port.
The Gateway and its HTTPRoute/TLSRoute resources can be inspected with:
-
kubectl get gateway -A -
kubectl get httproute -A -
kubectl get tlsroute -A
Step 4: migrate non-BCM Ingress resources to Gateway API: Any non-BCM-provided application that still relies on Kubernetes Ingress resources is now migrated. For each such Ingress:
-
an equivalent
HTTPRoute(orTLSRoutefor TLS pass-through) is authored, targeting the same backendService -
the new route is attached to a
Gateway—either to the defaultbcm-gatewayGateway(section 4.17.3.1), or to a dedicatedGatewaycreated in the application’s namespace (section 4.17.5) -
the original
Ingressresource is left in place for the time being, so traffic keeps flowing through the legacy path while the new path is being validated
Step 5: refresh the Gateway proxy for non-BCM Gateways: After non-BCM Gateways have been created on the cluster
-
cm-kubernetes-setupis started again -
the
Gateway configurationmenu is opened -
the
Configure Gateway proxy to route traffic from head node(s) to Gatewaysitem is selected (section 4.17.6.3).
This refreshes the head-node NGINX Gateway proxy so that traffic for the new Gateways is forwarded from the head node(s) to their respective LoadBalancer Service IP addresses assigned by MetalLB, using the SNI-based routing described in section 4.17.6.1. Connections that do not match any non-BCM Gateway listener (including connections without a SNI hostname) continue to be forwarded to the default bcm-gateway Gateway.
Step 6: validate traffic for the non-BCM services: Each migrated application is verified through its HTTPRoute or TLSRoute on the bcm-gateway Gateway (or on its dedicated Gateway). At this point, both the BCM-shipped services and the non-BCM services are reachable through the Gateway-based path, while the legacy Ingress NGINX Controller NodePorts are still in place as a fallback.
Step 7: remove the legacy Ingress NGINX controller: Once all traffic has been confirmed on the Gateway-based path, the legacy controller is removed. To carry this out, cm-kubernetes-setup is started again, the Gateway configuration menu is opened and the Remove Ingress NGINX Controller (ingress-nginx) and legacy BCM Ingresses item is selected.
The exact actions performed by the removal are summarized by the wizard confirmation dialog.
This step does not delete any Ingress resources that were not provided by BCM. Any non-BCM Ingress resources that have not been removed yet remain present on the cluster.
Step 8: complete the cleanup: Once the previous steps have all completed successfully, any non-BCM Ingress resources that are still present on the cluster can be safely deleted by the cluster administrator. For example:
After this, the cluster is fully migrated to the Kubernetes Gateway API, and the legacy Ingress NGINX Controller is no longer in use on the cluster.
4.18 Networking Model
Kubernetes expects all pods to have unique IP addresses, which are reachable from within the cluster. This can be implemented in several ways, including adding pod network interfaces to a network bridge created on each host, or by using 3rd party tools to manage pod virtual networks.
With BCM the default pod network provider is Calico (https://www.projectcalico.org/). Calico uses the Border Gateway Protocol (BGP) to distribute routes for every Kubernetes pod. This allows the Kubernetes cluster to be integrated without the need for overlays (IP-in-IP). Calico is particularly suitable for large Kubernetes deployments on bare metal, or in private clouds. This is because for larger deployments the performance and complexity costs of overlay networks can become significant.
4.19 Kubernetes Monitoring
When cm-kubernetes-setup is run, it configures the following Kubernetes-related health checks:
-
KubernetesChildNode: checks if all the expected agents and services are up and running for active nodes -
KubernetesComponentsStatus: checks if all the daemons running on a node are healthy -
KubernetesNodesStatus: checks if Kubernetes nodes have a status ofReady -
KubernetesPodsStatus: checks if all the pods are in one of these states:Running,Succeeded, orPending
4.20 Local Path Storage Class
For storage, instead of creating Kubernetes PersistentVolumes every time, a modern and practical way is to use the StorageClass feature.
Further documentation on StorageClass is available at:
-
http://blog.kubernetes.io/2016/10/dynamic-provisioning-and-storage-in-kubernetes.html
-
https://kubernetes.io/docs/concepts/storage/persistent-volumes/#storageclasses
As a part of initial installation it is possible to choose a Local Path Storage class to utilize the shared storage mounted on every node of the Kubernetes cluster. The two wizard screens that do this, the storage class screen and the local path storage pool screen, are described in the walkthrough in section 4.2.8.
Possible options include any POSIX shared filesystems, such as NFS, BeeGFS, LustreFS, etc. If a class is enabled, then the installation wizard asks for a path for where Kubernetes physical volumes (PV) will be physically located. This path should be located on a shared filesystem accessible from all nodes.
After installation, the storage class can be seen to be available with:
Users of the cluster can then freely create persistent volume claims (PVC) resources and use them in running pods.
4.21 Integration With Harbor
In order to spawn pods that use images from the Harbor registry, a secret must first be created with the credentials:
The secret must then be referenced from the pod:
Further information on this is available at https://kubernetes.io/docs/concepts/containers/images/#specifying-imagepullsecrets-on-a-pod.
4.22 Kubernetes Upgrades
This section assumes that an upgrade to a BCM Kubernetes is being considered. This means that it is assumed to have been set up with cm-kubernetes-setup.
Upgrades to Kubernetes can be done by following the principles behind the official upstream documentation at https://kubernetes.io/docs/tasks/administer-cluster/kubeadm/kubeadm-upgrade/.
The following points must be kept in mind when upgrading a BCM Kubernetes cluster:
-
Nodes that are part of the cluster may be provisioned through their software image.
-
The Kubernetes version in BCM must manually be updated to match the version of the upgrade.
-
Air-gapped upgrades follow the principles of this section, but have some extra considerations. Air-gapped upgrades are discussed in Appendix C, and the instructions there can be followed after reading this section (section 4.22) first.
-
Only some Kubernetes versions are supported. A list of supported available versions can be retrieved with:
Example
In the example that follows, a BCM cluster is upgraded from Kubernetes 1.31 to Kubernetes 1.32.
At the time of writing of this section (March 2026), the URL for the upstream documentation redirects the readers to the upgrade instructions for, among others, 1.33 to 1.34.
4.22.1 Upgrade Prerequisites
Kubernetes is not a single entity for upgrade purposes. There is a single driver, the kubeadm program, which is used to plan and execute the upgrade, but it does it only for itself and a handful of components central to Kubernetes’ functionality. Kubernetes does not have ways to manage its third-party components with kubeadm’s upgrade planning and execution. This means that multiple Kubernetes components that are essential to Kubernetes are not involved in the upgrade process. If these components are neglected during an upgrade, then they can either prevent successful completion of the upgrade, or can themselves fail as a result of the upgrade.
Some noteworthy components that are excluded by upgrades are the etcd database, CNIs, CSIs, container runtimes, as well as individual pods not managed by higher-level entities such as Deployment, ReplicaSet and so on. The Kubernetes documentation at
https://kubernetes.io/docs/concepts/workloads/pods/disruptions/#pod-disruption-budgets
describes the workings of the eviction process in greater detail.
Kubernetes upgrades assume that various entities, in particular, pods, can migrate away from the node being upgraded. This assumption may not be true because of various constraints on pod scheduling. The constraints need to be satisfied or worked around in order for migration to work. Particular care has to be taken when dealing with persistent volumes or physical resources such as GPUs that cannot migrate, but are needed for a pod to be deployed.
4.22.1.1 Hot And Cold Upgrades
-
A hot upgrade is one that allows the system to stay online at all times.
-
A cold upgrade is one that requires at least a brief service interruption.
Since Kubernetes is aimed at providing 100% system uptime, the upgrade process is designed to be hot. The cluster administrator carrying out the hot upgrade does however need to make an effort for the instances where Kubernetes cannot ensure service uptime.
Upgrading components that cannot be stopped in a regular manner: One common problem with hot upgrades is the need to migrate or to stop DaemonSet pods. These are intended to run on all Kubernetes nodes, even those being drained. Kubernetes can be told to ignore DaemonSet pods by using the --ignore-daemonsets option. The problem with doing that is that it avoids upgrading those pods, and also typically avoids upgrading the third-party component that created them. To ensure upgrade completion, the administrator has to carry out a separate upgrade action, appropriate for each component ignored in this way.
Upgrading gradually: Kubernetes upgrades come without any tools to perform upgrades at scale. The available tools can only upgrade a single node at a time. This means that, especially for larger clusters, the administrator needs to carry out the upgrade gradually, and has to plan and allocate extra capacity to accommodate pods migrated from nodes being upgraded. Special precautions need to be taken when dealing with deployments which require larger replica counts. Administrators may need to perform special procedures. Third-party components in particular may require the simultaneous presence of multiple entities across multiple nodes, in order to be able to upgrade those components without a service interruption.
Finally, it is possible that some components are simply not designed for hot upgrades. In that case, administrators have to remove those components from the system, and install the newer version, with the downtime depending on each individual case.
4.22.2 Example RHEL9 Cluster
A cluster with 3 nodes that run the control plane, and based on RHEL9, is considered as a reference example. One control plane node is the single head node, and the other two control plane nodes are two regular (compute) nodes. There are four additional worker-only nodes, and all the non-head nodes share the same category and software image.
4.22.3 Before Starting The Upgrade
The upstream instructions at https://v1-32.docs.kubernetes.io/docs/tasks/administer-cluster/kubeadm/kubeadm-upgrade/#before-you-begin, on preparing for the upgrade should be read. A node that is to be upgraded must be drained.
4.22.4 Updating The First Control Plane Node
The first control plane node is upgraded in this section.
Instead of going into much detail on upgrades—the official documentation at https://kubernetes.io/docs/tasks/administer-cluster/kubeadm/kubeadm-upgrade/ does a good job—an example covering an upgrade to a Rocky cluster running Kubernetes version 1.27 is shown that uses the official documentation for guidance. Instructions for Ubuntu differ slightly but can be carried out in a similar way.
Typically the control plane is on the head node, so that the cluster administrator starts with updating the control plane being run by the head node. However, for completeness, the two subsections that follow describe updating the control plane if starting with:
-
either the head node
-
or a compute node
4.22.4.1 Upgrading A Control Plane Node Starting With The Head Node
To upgrade the control plane when the head node is the first node to be upgraded, the repository entry for picking up packages from the Kubernetes repository should have the new version set.
Example
The grep outputs confirm there is a repository file, and that it is set to pick up Kubernetes version 1.31. The .31 indicates what is called the minor version in Kubernetes. To instead pick up version 1.32, the upstream documentation instructs changing the minor version in the repository file to the next minor version upgrade number, so here from v1.31 to v1.32. Skipping minor versions for upgrades is unsupported.
An additional check to confirm the running version is:
The minor version in kubernetes.repo is changed from v1.31 to v1.32 using a text editor. The installation for a new kubeadm can then be carried out with:
The upgrade plan can be inspected:
In this case it gives a recommended upgrade command to run on the head node:
The upgrade is now made to version 1.32.6, as suggested. The curious cluster administrator can view the list of available versions can be viewed with the --showduplicates option to yum:
Example
Most cluster administrators stick to the recommendation.
The host should now be drained, if it has not already been drained:
As suggested, the kubelets are now upgraded. Updating the kubectl version at the same time is also a good idea:
The kubelets can be restarted so that the new versions run:
This ends the procedure of upgrading the control plane by first starting on a head node. Upgrading the control plane by first starting with a regular node instead is described next.
4.22.4.2 Upgrading The Control Plane Node Starting With A Compute Node
This section describes the list of commands for upgrading the control plane when it is the first control plane node to be upgraded. For example node001, rather than a head node.
The appropriate software image and related information for the node must first be found. For node001 this can be done with:
The software image is then entered and modified using a chroot jail.
The repository file of the image, with an absolute path outside the chroot jail of /cm/images/default-image/etc/yum.repos.d/kubernetes.repo, has its minor version changed appropriately:
The package versions available for installation in the image can be checked with:
In this case versions 1.32.6 are seen to be available.
The kubeadm, kubelet and kubectl packages are upgraded in advance, and the chroot environment is then exited:
The following set of commands then carries out the update on node001:
4.22.5 Updating Subsequent Control Plane Nodes
If there is only one control plane node, then this section can be skipped.
If there is more than one control plane node, and if the first control plane node is a head node that has been updated, then the remaining control plane nodes should be updated. The kubectl command can be used to orient the cluster administrator, by displaying the state of the upgrade, roles, and Kubernetes versions per node:
Example
The remaining control plane nodes can now be updated. In the reference example case, these control plane nodes are node001 and node002 as seen in the preceding example. The commands in the section on Upgrading The Control Plane Node Starting With A Compute Node (here) should be followed, but with one small difference. Instead of running:
kubeadm upgrade apply v1.32.6
the command
kubeadm upgrade node
is run.
The software image should also be prepared with the new packages before exiting the chroot jail. After exiting the chroot jail the remaining control plane nodes can then be updated with the following set of commands:
Example
Output after this should now look similar to:
The procedure can be repeated for node002 in the reference example system. After that, the control plane nodes are all in an updated state. The worker nodes still need updating.
4.22.6 Updating The Worker Nodes
The commands for the worker nodes follow a similar pattern. They are updated one by one, and the software images must also be updated, if it has not already been done. The software image update follows the procedure described in the section on Upgrading The Control Plane Node Starting With A Compute Node (here), where a chroot jail is entered, the updates are carried out, and the chroot jail is left.
Since nodes are drained as part of their update procedure, it is best to do them one by one, or at most in limited batches to avoid doing too many at once.
The set of commands to update a single worker is:
The kubectl drain command might complain for other reasons. The administrator can decide on proceeding further by adding additional flags.
For example:
forces the drain even if some pods have stateful data in emptyDir volumes.
Multiple nodes can be updated as follows:
Example
Output after all the worker nodes are updated too should look similar to:
4.22.7 Updating The Status In BCM
For releases of BCM before BCM 11.32, setting the attribute version for the Kubernetes object in CMDaemon is not carried out automatically by BCM. Setting that attribute is however necessary in order to get the correct version of Kubernetes showing up in the available module files. A session to update the old version is as follows:
4.22.8 Notes For Upgrading To Kubernetes v1.31.x
The kubeadm-init-* files generated by BCM for Kubernetes clusters older than v1.31, contain an incompatibility with v1.31 that cannot be solved automatically by kubeadm config migrate when carrying out a migration as described in https://kubernetes.io/docs/reference/setup-tools/kubeadm/kubeadm-init/#config-file.
To prevent errors while executing the kubeadm config migrate command, any JoinConfiguration block needs to be removed from the kubeadm-init-* files.
The kubeadm-init-* files are files that, for a Kubernetes cluster name, follow the pattern:
Thus, for the default BCM Kubernetes cluster installation that creates a Kubernetes cluster called default, this would be the single YAML file:
The part to remove in such files looks like this:
4.22.9 Notes For Ubuntu
The upstream documentation covers Ubuntu upgrades when it diverges from RHEL procedures. As an aid, the following commands, discussed in the procedure for RHEL within section 4.22 are followed by the corresponding commands for Ubuntu:
4.22.10 Notes For SLES
For v1.32, for SLES, BCM can use the “tarball” approach. The installation of such non-package-manager packages is documented at https://kubernetes.io/docs/setup/production-environment/tools/kubeadm/install-kubeadm/, in the “Without a package manager” section. The commands in that section there can be used as a guide to find alternatives for the yum and apt commands used so far.
4.22.11 Other Approaches
When carrying out the steps described in this chapter, some things may in practice end up being done differently from what is suggested.
For example: control plane nodes often have different categories and software-images compared to the workers. For example, perhaps the control-plane nodes do not have GPUs, and need different packages. In that case, multiple software images have to be prepared with new packages.
Earlier on, a process to update nodes one at a time was described. However, when a software image is updated, and multiple nodes are tied to that software image, then those nodes can all be provisioned at the same time. The binaries in the updated software image can therefore also be provisioned to all the nodes using that image.
The problem with this is that it could result in nodes getting the new binaries prematurely if they happen to reboot during the update. If this is an unwanted risk, then it can be avoided in several ways, described next.
4.22.11.1 Additional Software Images
A separate software image can be introduced. Nodes can be moved to the new software image one at a time. A software image can also be overruled at the level of a node.
Example
The cluster administrator should remember to undo the preceding settings, or should move the new software image to the appropriate category, and then clear the node-level override again. This is so that, after the upgrade, the system is organized as before.
4.22.11.2 Using NOSYNC
The other option is to configure the nodes with NOSYNC for their Next install mode. This prevents them from syncing with their software image when rebooting (in the case that they still reboot):
Example
Both these approaches make updating slightly more tedious, but also more straightforward.
During testing by BCM developers, nodes getting their binaries updated prematurely due to an unexpected reboot was not seen to be a significant issue. This is presumably because as long as the first control plane node is updated successfully, and the reboot of the extra node is by accident, there is an interruption anyway. The kubelet simply comes back up with the new version. However this is not the official recommended approach.