

Gemma 4#
NeMo RL supports post-training the Gemma 4 family with the AutoModel training backend and vLLM generation. The reference configurations cover text-only DAPO for the E2B, 12B, 26B-A4B, and 31B variants and multimodal GRPO for the E4B variant.
Important
Status: Functionally Ready. The listed configurations provide short-run functional and CI coverage. They are starting points for post-training, not a claim of long-run convergence on every model and parallel layout.
Support Matrix#
Model |
Task |
Training backend |
Training parallelism |
Generation backend |
Status |
|---|---|---|---|---|---|
|
Text-only DAPO |
AutoModel (FSDP2) |
CP1 or CP2 |
vLLM |
Functionally Ready |
|
VLM GRPO |
AutoModel (FSDP2) |
CP1 |
vLLM TP4 |
Functionally Ready |
|
Text-only DAPO |
AutoModel (FSDP2) |
CP1 |
vLLM TP2 |
Functionally Ready |
|
Text-only DAPO |
AutoModel (FSDP2) |
EP32 with CP1; EP16 with CP2 |
vLLM TP4 |
Functionally Ready |
|
Text-only DAPO |
AutoModel (FSDP2) |
CP1 or CP2 |
vLLM TP4 |
Functionally Ready |
Reference Recipes#
Recipe YAML files under examples/configs/recipes/ are the source of truth.
Model |
Layout |
Nodes and GPUs |
Recipe |
|---|---|---|---|
E2B |
FSDP2, CP1 |
1n8g |
|
E2B |
FSDP2, CP2 |
1n8g |
|
E4B |
VLM FSDP2, CP1 |
1n8g |
|
12B |
FSDP2, CP1 |
2n8g |
|
26B-A4B |
FSDP2, EP32, CP1 |
4n8g |
|
26B-A4B |
FSDP2, EP16, CP2 |
4n8g |
|
31B |
FSDP2, CP1 |
4n8g |
|
31B |
FSDP2, CP2 |
4n8g |
Run a Recipe#
From an allocation matching the recipe, launch the standard GRPO entry point. For example, run the 12B configuration with:
uv run examples/run_grpo.py \
  --config examples/configs/recipes/llm/dapo-gemma4-12b-it-2n8g-fsdp2-automodel.yaml
See the GRPO guide for algorithm and launch details.
Context Parallel#
Context Parallel support uses the refactored AutoModel CP interface introduced
by PR #3498. The E2B and 31B CP2
recipes are thin overrides of their CP1 parents that change
policy.dtensor_cfg.context_parallel_size to 2. The 26B-A4B CP2 recipe also
changes expert parallelism from EP32 to EP16 so the model-parallel product fits
on the same four-node allocation. Other model, optimizer, sequence-length, and
generation settings remain identical to their CP1 parents.
Context Parallel currently applies to the text-only E2B, 26B-A4B, and 31B
recipes backed by AutoModel’s Gemma 4 model-owned attention. Do not enable it
for the E4B VLM recipe or the 12B unified checkpoint. The text-only recipes
freeze the vision and audio towers, disable sequence packing, and configure
vLLM with language_model_only: true where the checkpoint requires it.
Training and generation parallelism are independent. CP partitions training
sequences; the tensor_parallel_size under policy.generation.vllm_cfg
controls vLLM. The AutoModel model-parallel product must divide the training
world size. The 26B-A4B CP2 recipe uses EP16 × CP2 across 32 GPUs, provided by
four nodes with eight GPUs per node.
Validation Curves#
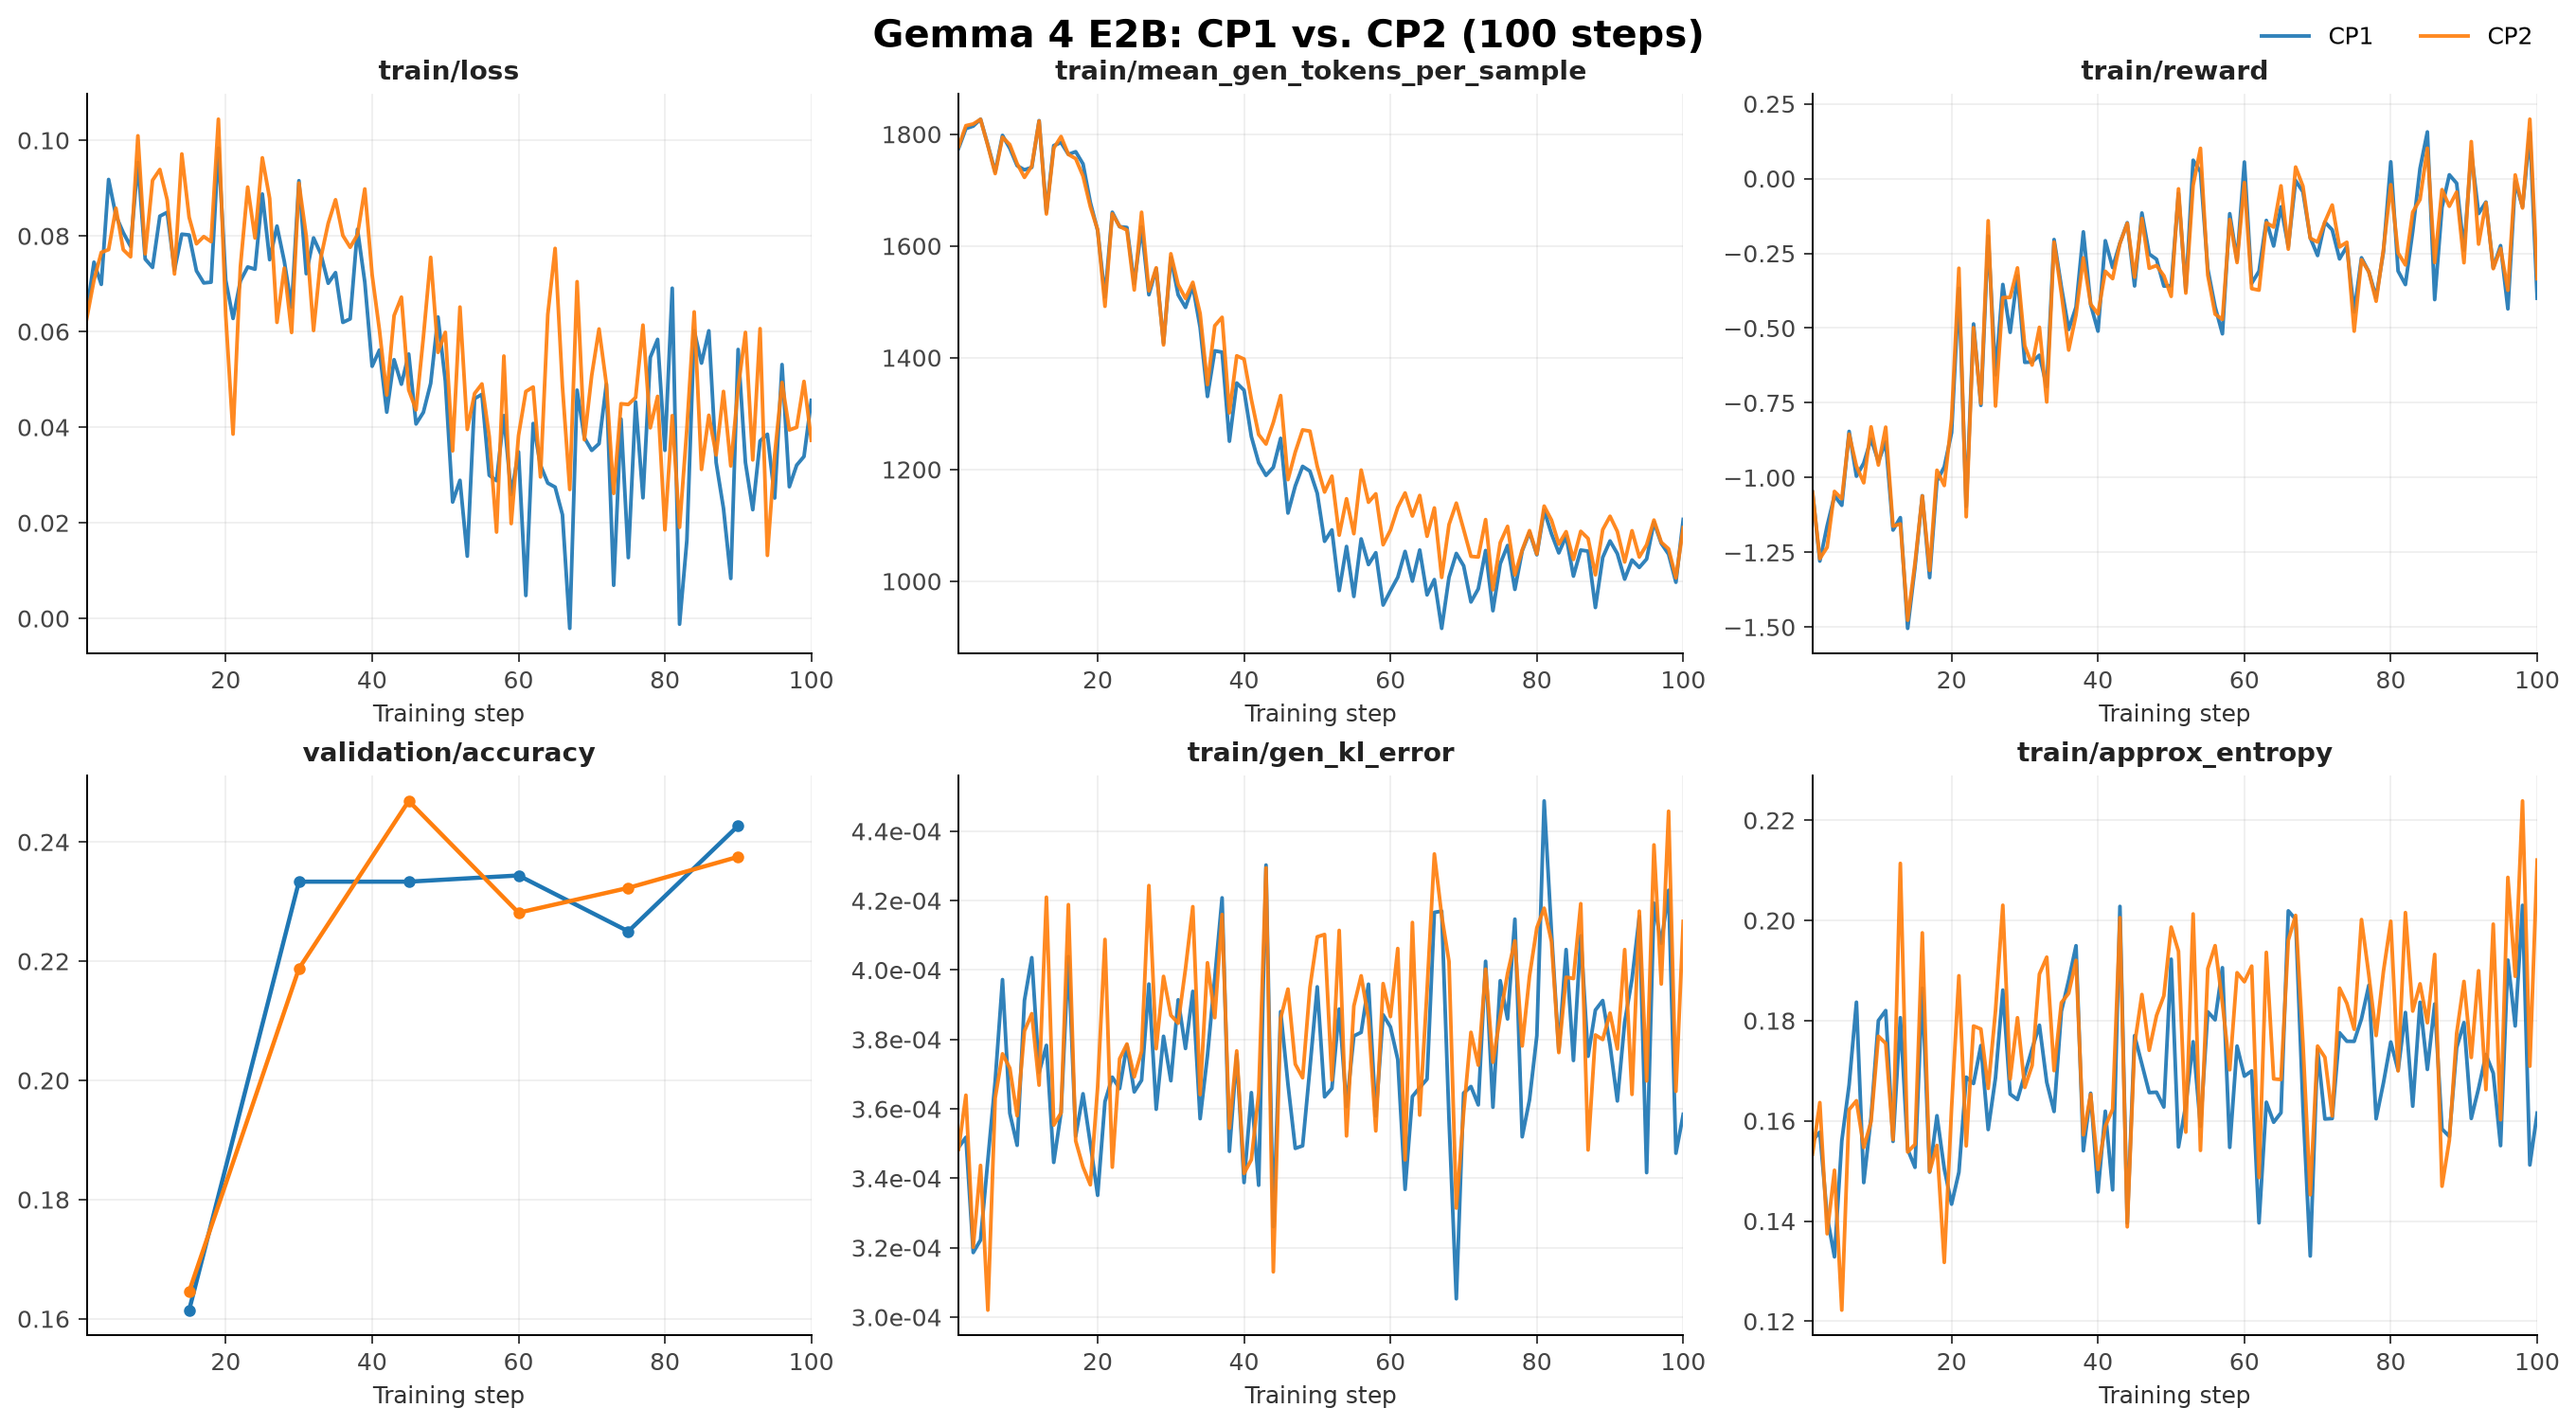
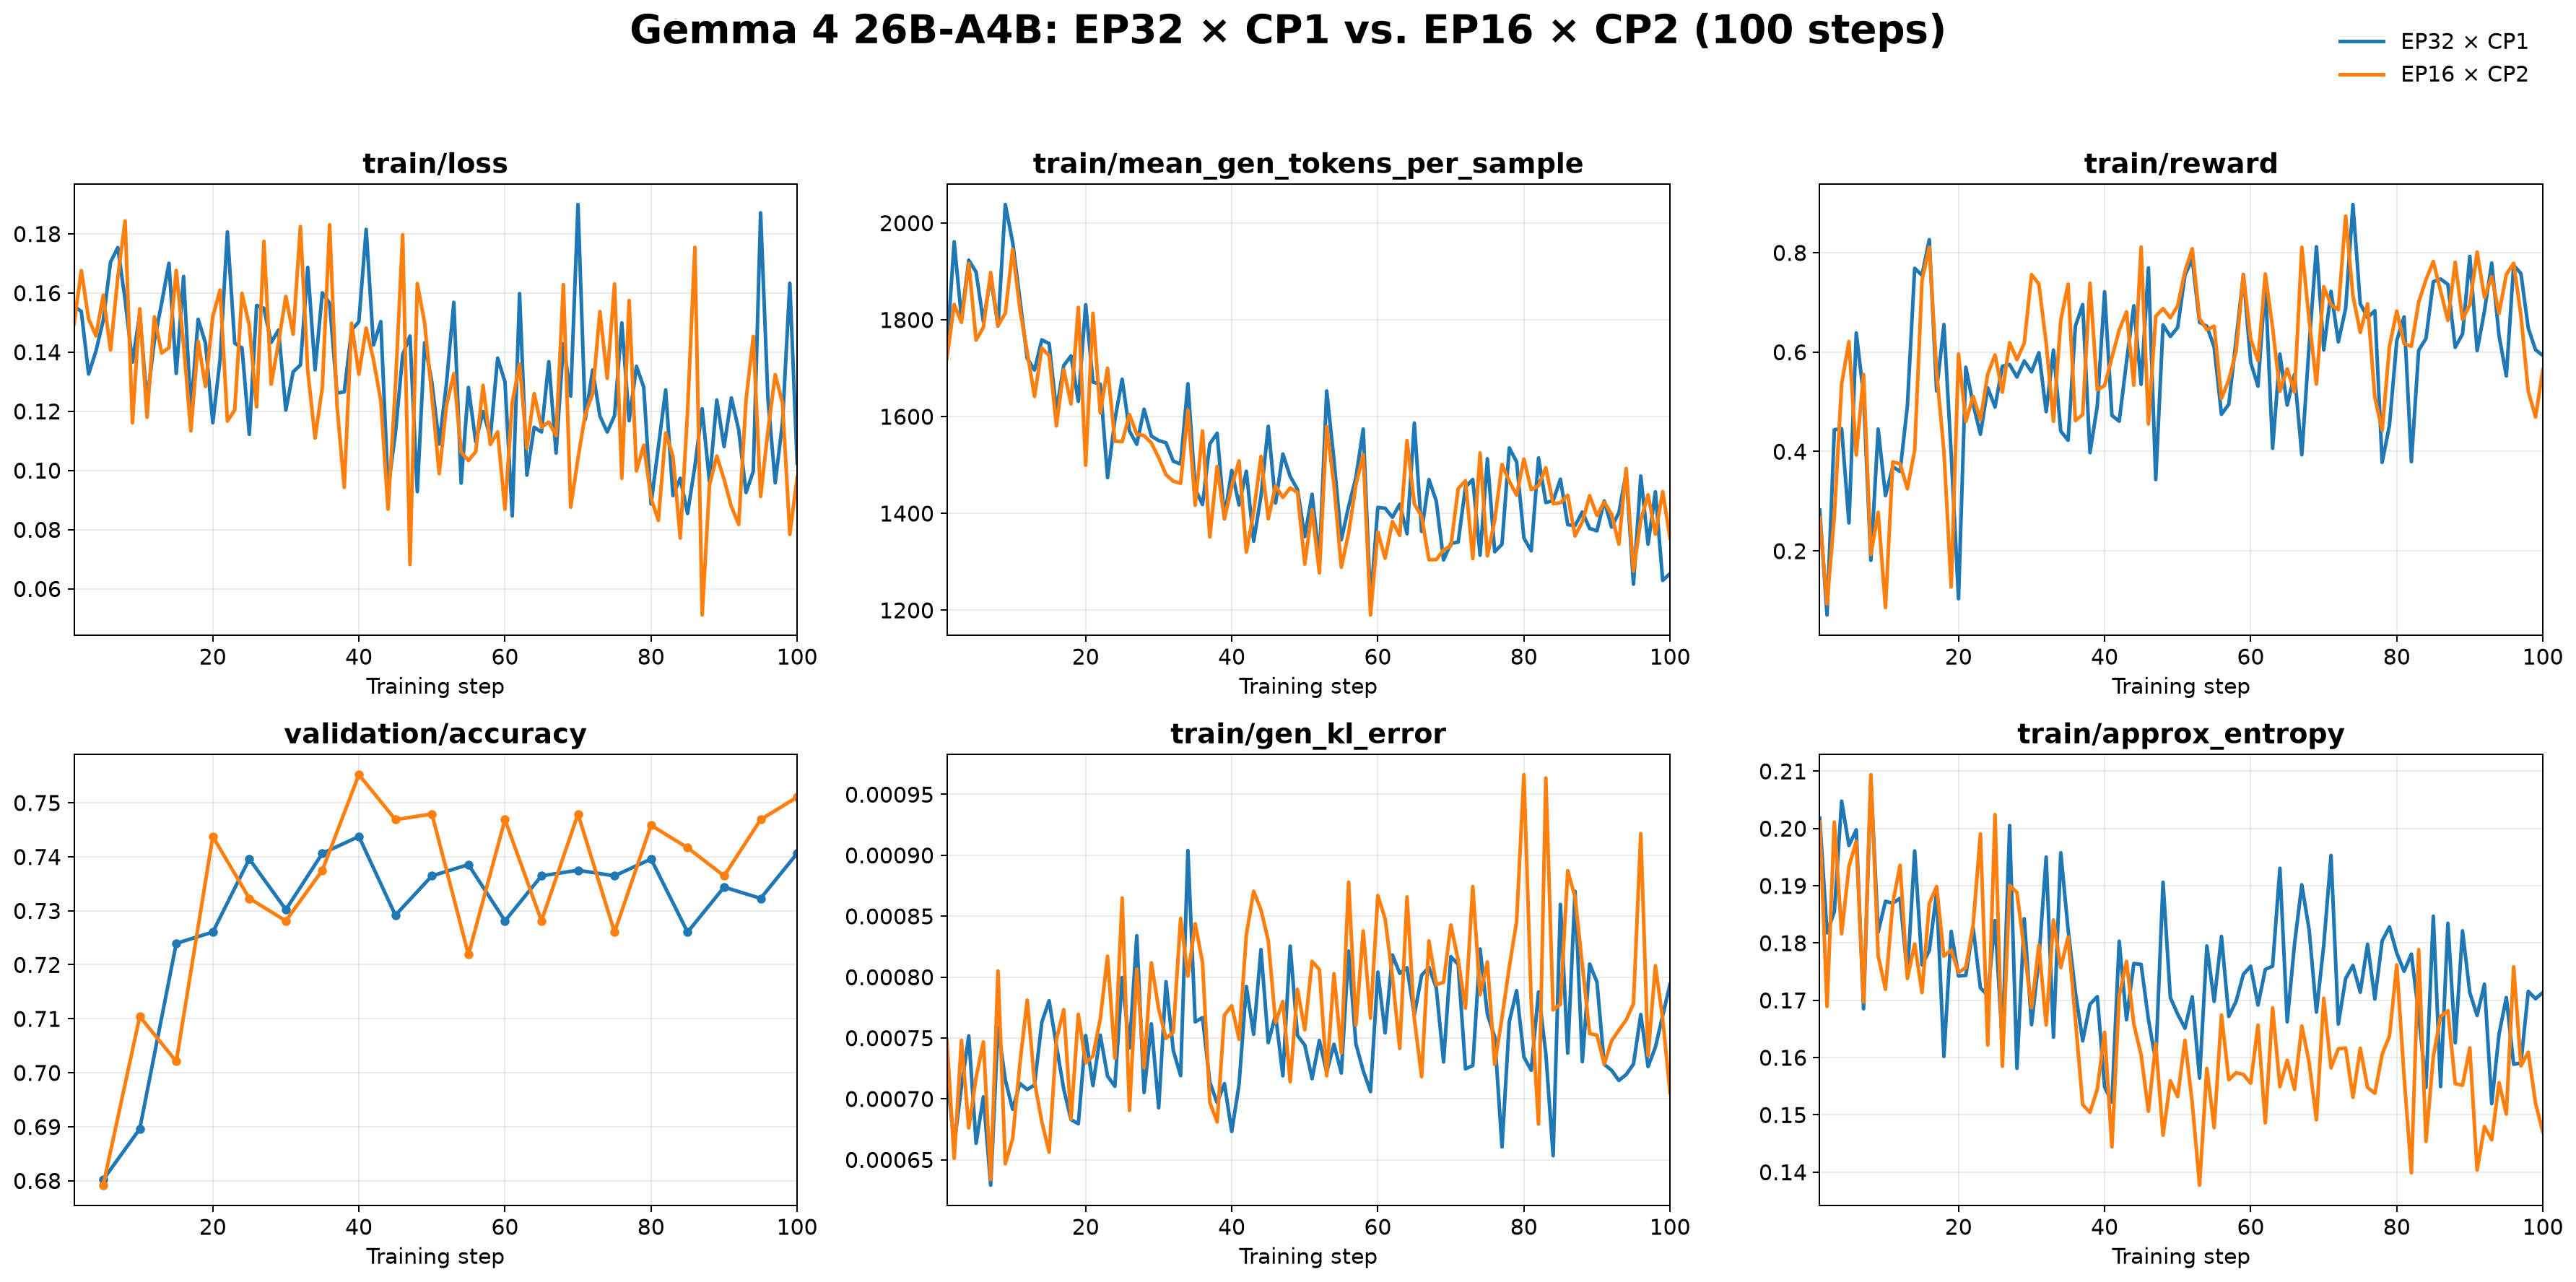
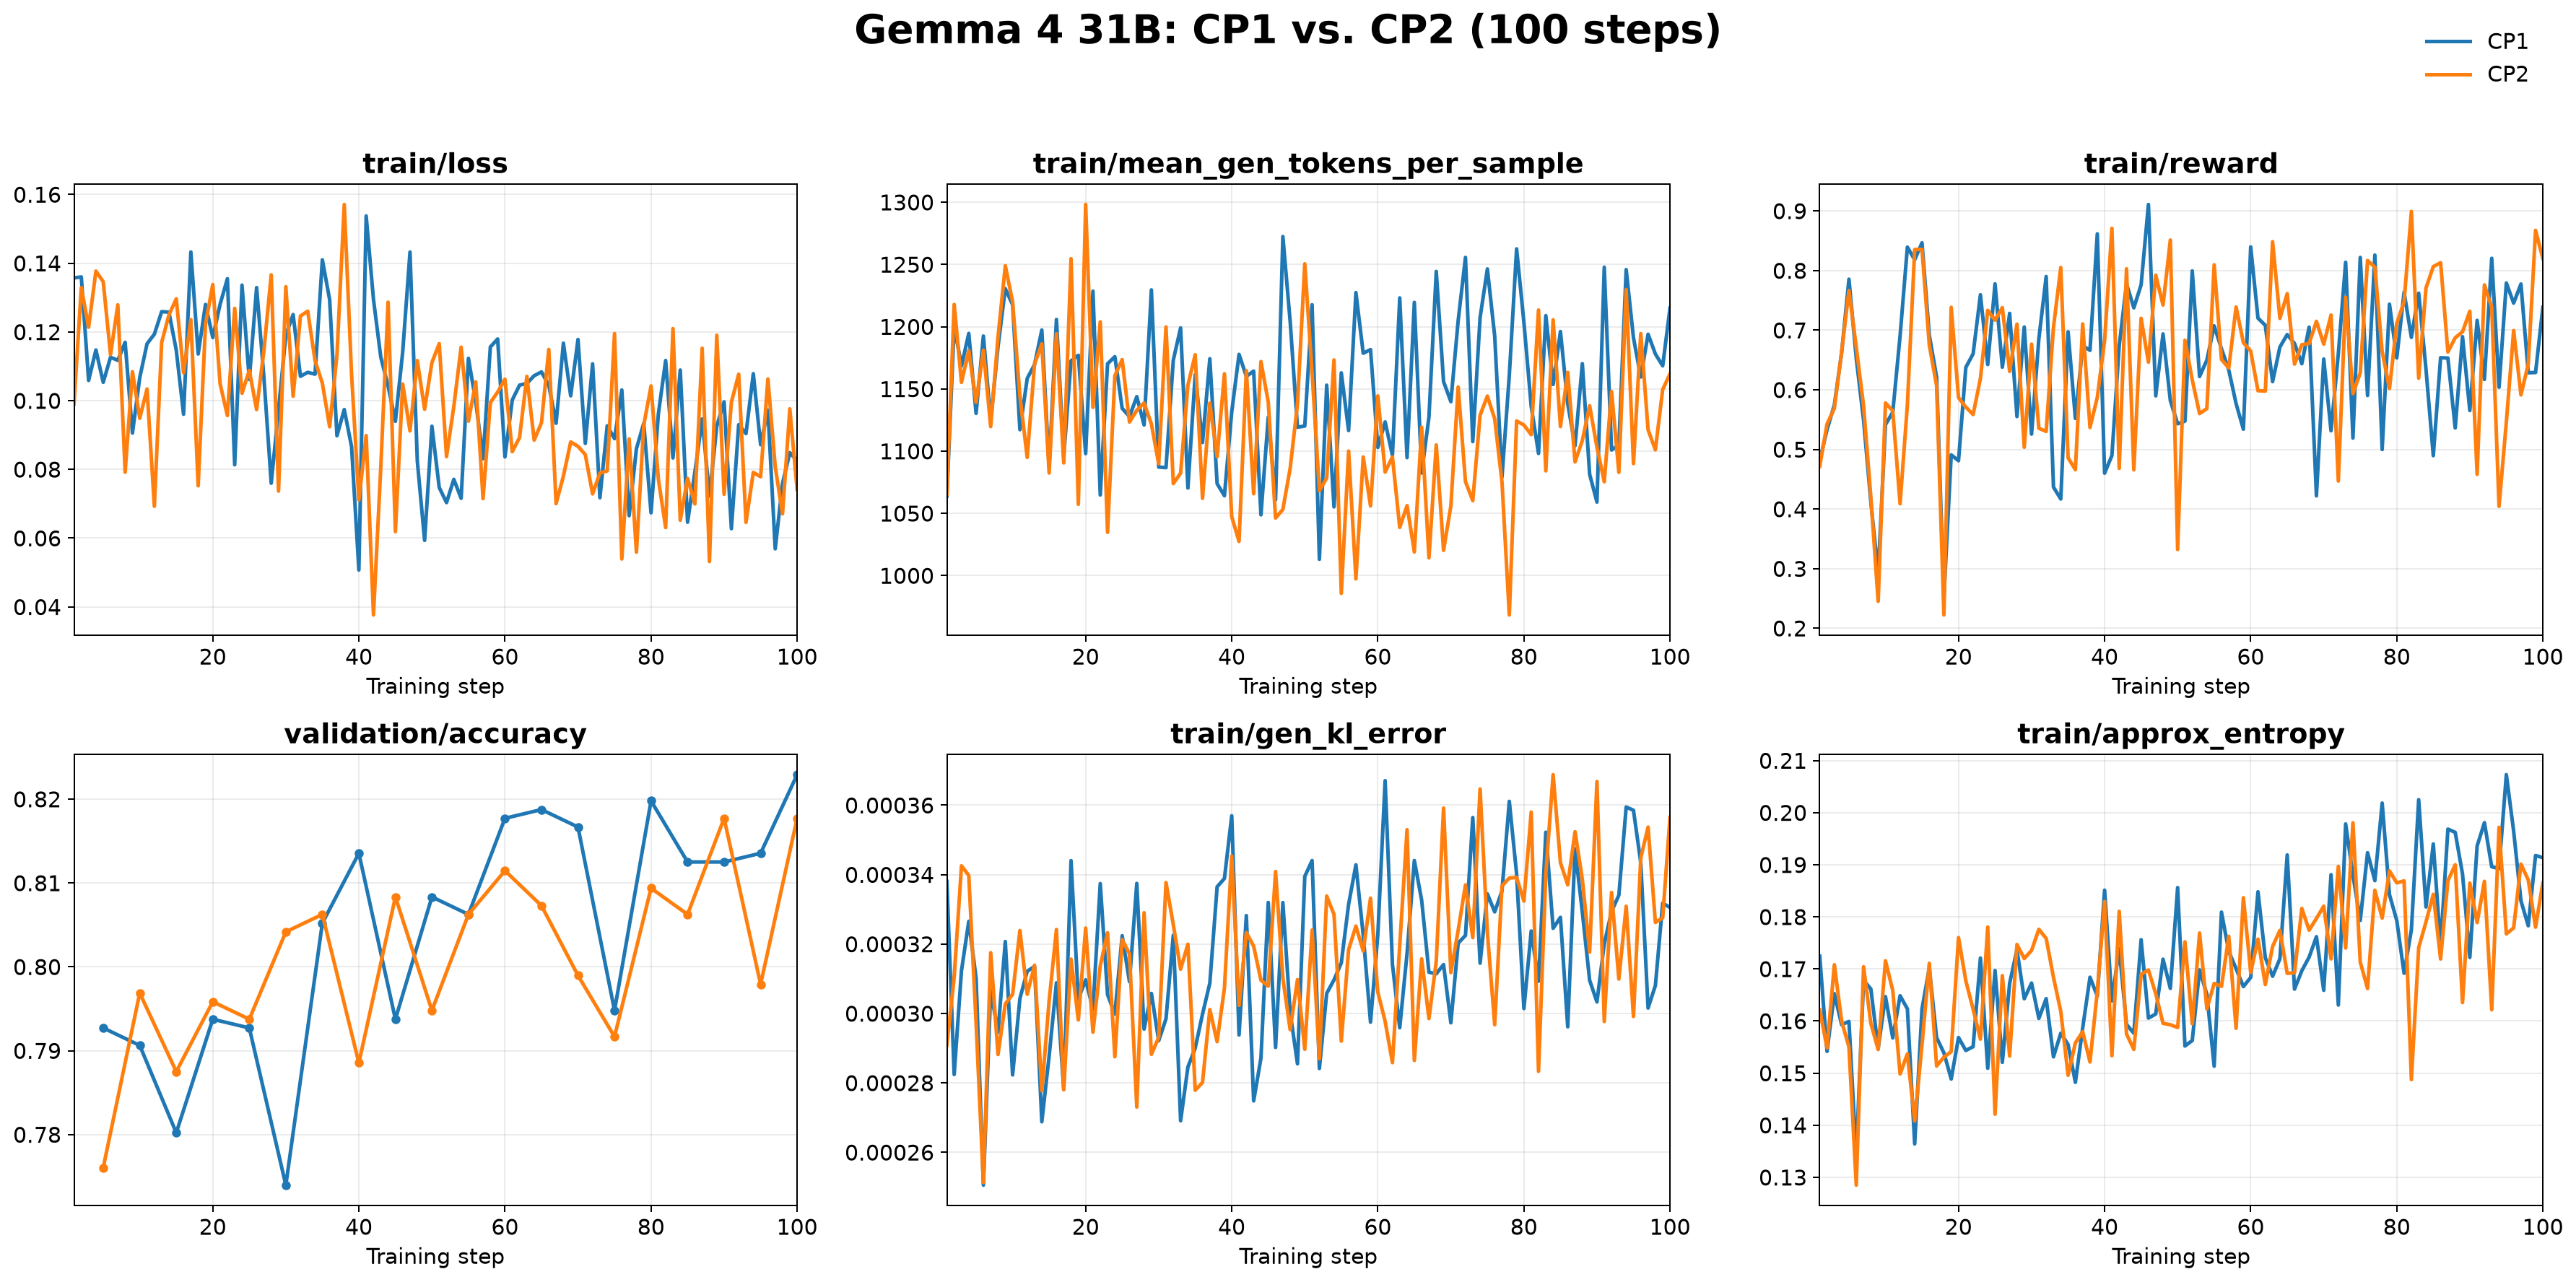
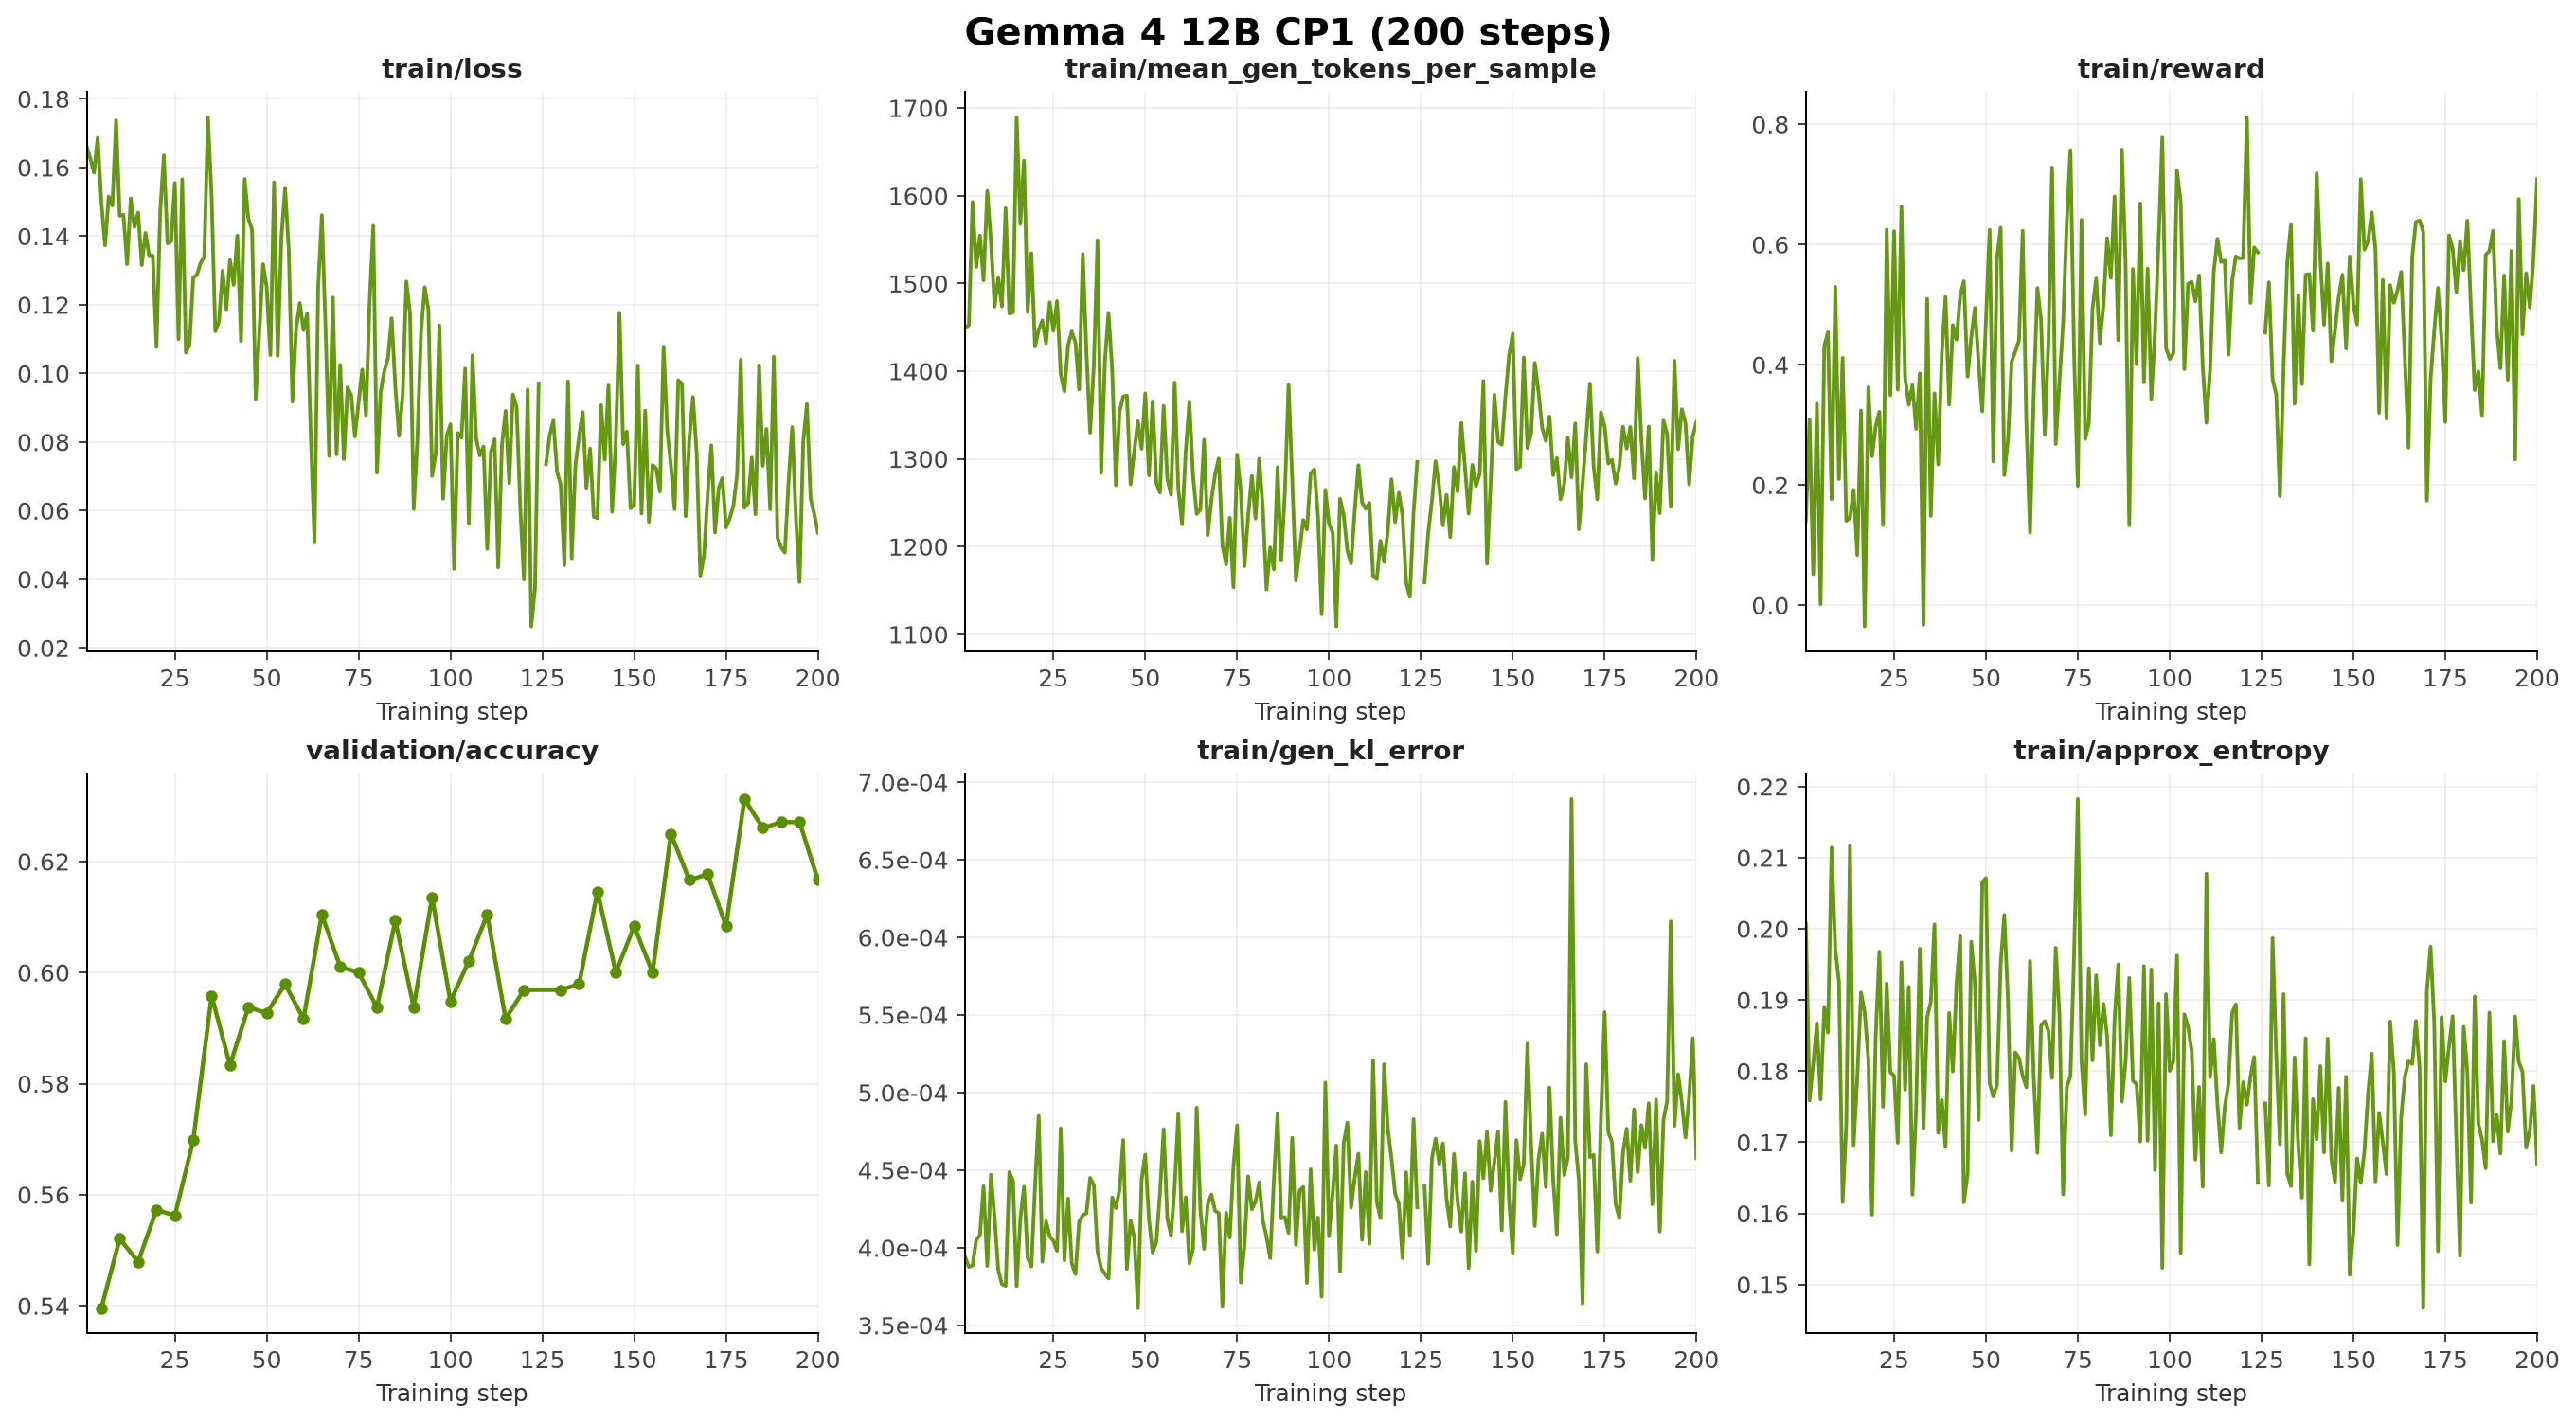
The following plots show raw step-level metrics captured from completed validation runs. Validation accuracy is plotted only at validation steps; the other metrics are plotted at every recorded training step.
E2B Context Parallel Parity#
The E2B CP1 and CP2 runs use the same 100-step training configuration except
for policy.dtensor_cfg.context_parallel_size. Their trajectories remain close
across the six metrics: the mean absolute difference in validation accuracy is
0.0083 across six aligned validation points, while the mean absolute difference
in generation KL error is 1.6e-5 across 100 aligned training points.
26B-A4B Context Parallel Parity#
The 26B-A4B pair keeps the four-node, 32-GPU training world size fixed while changing the model-parallel layout from EP32 × CP1 to EP16 × CP2. Both runs complete 100 steps. The mean absolute difference in validation accuracy is 0.0114 across 20 aligned validation points, while the mean absolute difference in generation KL error is 5.6e-5 across 100 aligned training points. The final validation accuracies are 0.741 for EP32 × CP1 and 0.751 for EP16 × CP2.
31B Context Parallel Parity#
The 31B CP1 and CP2 runs use the same four-node training configuration except
for policy.dtensor_cfg.context_parallel_size. Both runs complete 100 steps.
The mean absolute difference in validation accuracy is 0.0099 across 20 aligned
validation points, while the mean absolute difference in generation KL error is
2.2e-5 across 100 aligned training points. The final validation accuracies are
0.823 for CP1 and 0.818 for CP2.
12B Long Run#
The 12B CP1 run completed 200 steps. Validation accuracy increases from 0.540 at step 5 to 0.617 at step 200 and reaches a maximum of 0.631. Training loss decreases from 0.166 at step 1 to 0.054 at step 200, while generation KL error stays below 6.9e-4. The recorded history contains 199 training-metric rows and 39 validation rows; step 125 has no values for the requested metrics, so the plot does not interpolate that missing row.
12B Unified Checkpoint#
The 12B checkpoint reports model_type: gemma4_unified and architecture
Gemma4UnifiedForConditionalGeneration. NeMo RL routes it through the
image-text AutoModel class so the complete checkpoint can load, while the
reference recipe trains only the language path:
The vision and audio towers are frozen.
vLLM generation uses
language_model_only: trueand TP2.Weight refits omit the frozen vision/audio tensors because vLLM’s text-only unified model uses encoder-free multimodal stubs with a different layout.
vLLM tokenizer initialization is enabled for the unified architecture.
Activation checkpointing and optimizer offload during log-probability computation are enabled.
Sequence packing and Liger kernels are disabled.
The total sequence length is 4,096 tokens, with up to 3,072 generated tokens.
Limitations and Tracking#
Context Parallel is not supported by the Gemma 4 VLM recipe.
The 12B
gemma4_unifiedcheckpoint currently supports CP1 only; unlike the other text variants, it does not use AutoModel’s Gemma 4 model-owned CP attention implementation.The recipes disable sequence packing; validate any packing change separately.
The functional status does not imply long-run convergence for every variant.
Gemma 4 CP support is tracked by #2914, and 12B support by #2913.