Skip to navigation

RT-Embed Performance

View as Markdown

Overview

The Real-Time Embedding (RT-Embedding) microservice provides video and text embedding generation capabilities using the Cosmos-Embed1 model, enabling video search and similarity matching. Benchmarks cover two operating modes:

  • Streaming mode — the microservice reads live RTSP streams continuously. Every 10 seconds of video, it samples 8 frames and produces one video embedding vector. Latency is measured from when a 10-second chunk is ready until the embedding is returned.
  • Non-streaming mode — the microservice handles discrete embedding requests for video clips or text queries. Benchmarks measure throughput (requests per second) and latency across varying concurrency levels.

Each video embedding encodes 8 frames sampled from a 10-second chunk scaled to 448×448 resolution into a 768-dimensional vector. Text embeddings encode up to 128 tokens into the same 768-dimensional space, enabling cross-modal search.
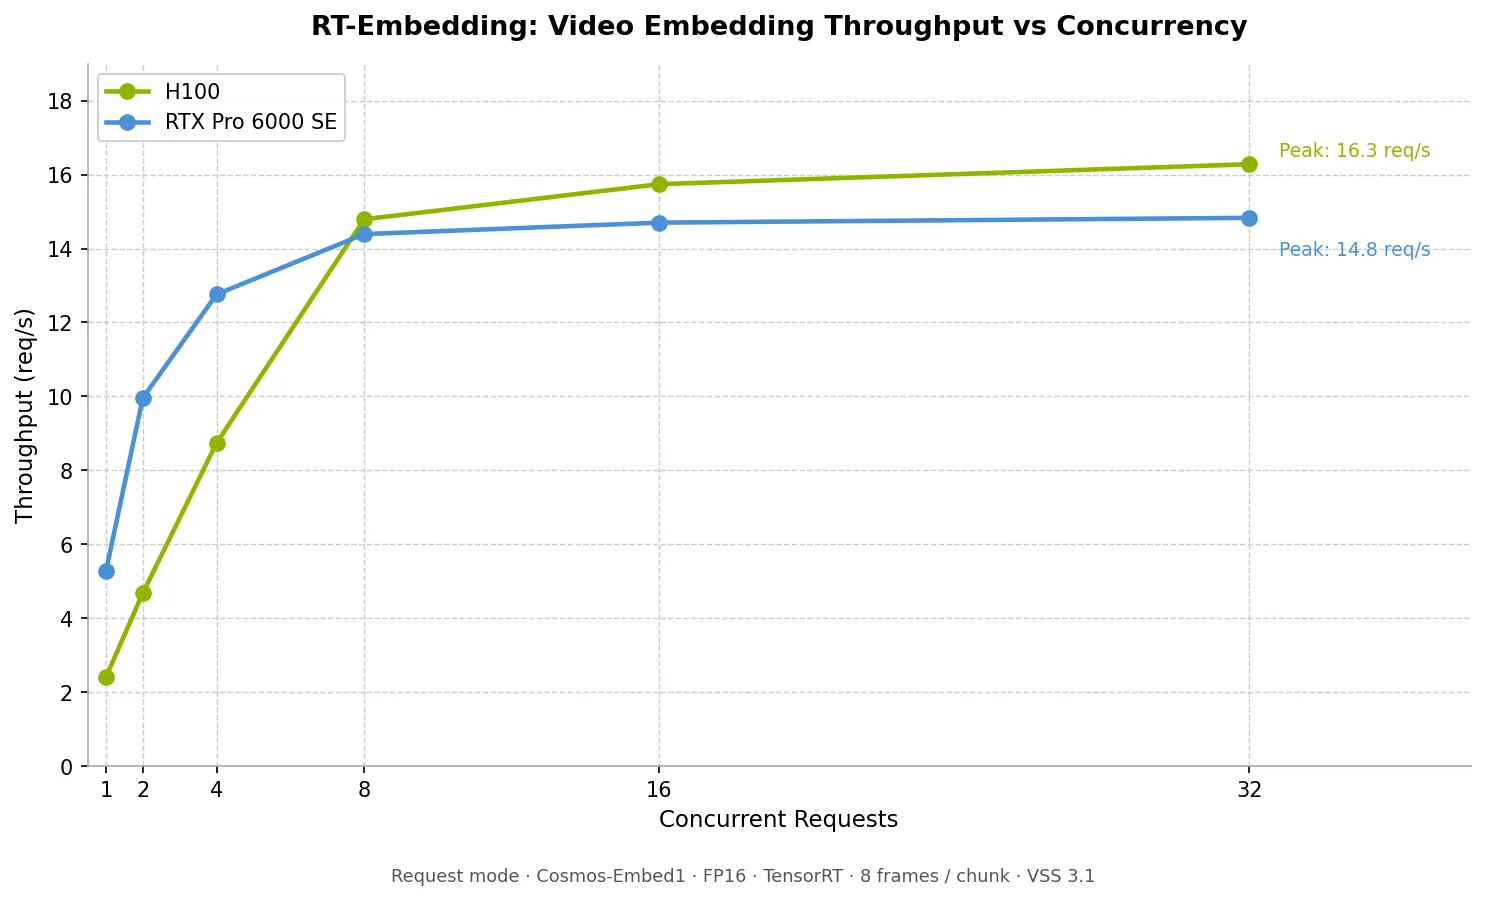
RT-Embedding video embedding throughput vs concurrency for H100 and RTX Pro 6000 SE
Video embedding throughput (req/s) vs. concurrent requests. The H100 reaches up to 16 req/s while the RTX Pro 6000 SE peaks near 15 req/s; the RTX Pro 6000 SE reaches peak throughput at lower concurrency and saturates earlier, while the H100 sustains throughput through higher concurrency levels.

Test Configuration

ParameterValue
VSS Release3.2
ModelCosmos-Embed1-448p
Model precisionFP16
Inference engineTensorRT (TRT)
Frames per chunk (video)8
Image resolution448×448
Embedding vector length768
Chunk duration10 seconds
Text ISL (text embedding)20 tokens
GPUs testedH100, RTX Pro 6000 SE

Performance by GPU

Streaming Mode

Max StreamsAvg Latency (s)p90 (s)p95 (s)Max (s)GPU Core (%)NVdec (%)
1703.006.768.6212.8966.393.9
Concurrent StreamsAvg (s)p90 (s)p95 (s)Min (s)Max (s)GPU Core (%)NVdec (%)
10.130.130.190.080.320.00.6
160.200.200.250.080.294.06.4
320.240.240.310.080.348.011.7

Request Mode

Concurrent RequestsAvg Latency (s)Throughput (req/s)
10.412.41
20.424.68
40.448.74
80.5014.79
160.9415.74
321.8116.28
Concurrent RequestsAvg Latency (s)Throughput (req/s)p90 (s)p95 (s)
10.007132.10.0070.008
20.008216.70.0090.011
40.010368.00.0100.012
80.013563.60.0150.016
160.018800.50.0230.023
320.0271044.30.0310.031
Video DurationE2E Latency (s)Avg Chunk Inference (s)Decode Latency (s)GPU Core (%)NVdec (%)
10 s0.4120.0390.3690.00.0
10 min5.2030.0390.61548.972.6
60 min28.80.0390.60154.387.6

All benchmarks use Cosmos-Embed1-448p, FP16, TensorRT, 8 frames per 10-second chunk of 1080p input resolution, scaled to 448×448 model resolution, and a 768-dimensional embedding vector. For streaming deployments, plan for 10–15% headroom below the maximum concurrent stream counts.