

Monitoring: Monitoring Cluster Devices
BCM monitoring allows a cluster administrator to monitor anything that can be monitored in the cluster. Much of the monitoring consists of pre-defined sampling configurations. If there is anything that is not configured, but the data on which it is based can be sampled, then monitoring can be configured for it too, by the administrator.
The monitoring data can be viewed historically, as well as on demand. The historical monitoring data can be stored raw, and optionally also as consolidated data—a way of summarizing data.
The data can be handled raw and processed externally, or it can be visualized within Base View in the form of customizable charts. Visualization helps the administrator spot trends and abnormal behavior, and is helpful in providing summary reports for managers.
Monitoring can be configured to set off alerts based on triggers, and pre-defined or custom actions can be carried out automatically, depending on triggers. The triggers can be customized according to user-defined conditional expressions.
Carrying out such actions automatically after having set up triggers for them means that the monitoring system can free the administrator from having to carry out these chores.
In this chapter, the monitoring system is explained with the following approach:
-
A basic example is first presented in which processes are run on a node. These processes are monitored, and trigger an action when a threshold is exceeded.
-
With this easy-to-understand example as a basic model, the various features and associated functionality of the BCM monitoring system are then described and discussed in further depth. These include visualization of data, concepts, configuration, monitoring customization and
cmshuse.
10.1 A Basic Monitoring Example And Action
10.1.1 Synopsis Of Basic Monitoring Example
In section 10.1, after an overview (section 10.1.1), a minimal basic example of monitoring a process is set up (section 10.1.2) and used (section 10.1.3). The example is contrived, with the aim being to present a basic example that covers a part of what the monitoring system is capable of handling. The basic example gives the reader a structure to keep in mind, around which further details are fitted and filled in during the coverage in the rest of this chapter.
In the basic example, a user runs a large number of pointless CPU-intensive processes on a head node which is normally very lightly loaded. An administrator who is monitoring user mode CPU load usage throughout the cluster, notices this usage spike. After getting the user to stop wasting CPU cycles, the administrator may decide that putting a stop to such processes automatically is a good idea. The administrator can set that up with an action that is triggered when a high load is detected. The action that is taken after triggering, is to stop the processes (figure 10.1).
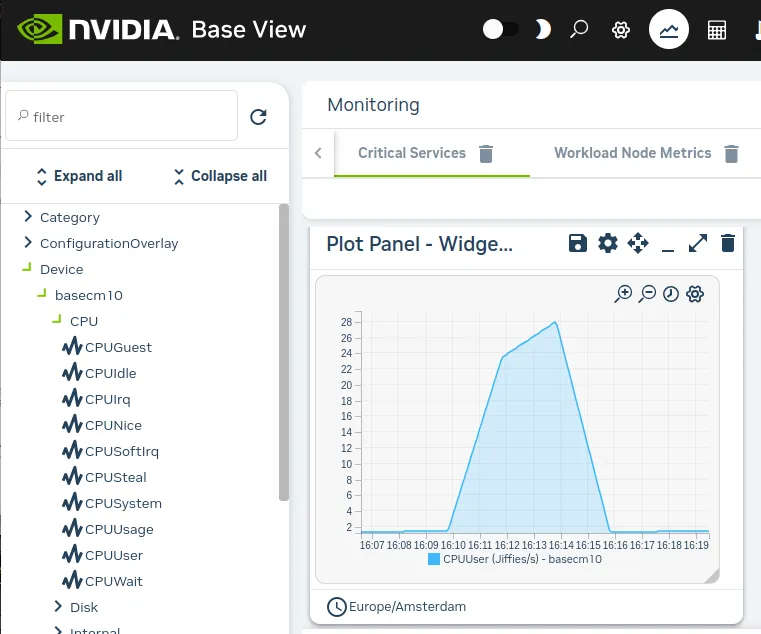
Figure 10.1: Monitoring Basic Example: CPU-intensive Processes Started, Detected And Stopped
The basic example thus illustrates how BCM monitoring can be used to detect something on the cluster and how an action can be set up and triggered based on that detection.
10.1.2 Before Using The Basic Monitoring Example—Setting Up The Pieces
10.1.2.1 Running A Large Number Of Pointless CPU-Intensive Processes
One way to simulate a user running pointless CPU-intensive processes is to run several instances of the standard unix utility, yes. The yes command sends out an endless number of lines of “y” texts. It is typically used in scripts to answer dialog prompts for confirmation.
The administrator can run 8 subshell processes in the background from the command line on the head node, with yes output sent to /dev/null, as follows:
Running “mpstat 2” shows usage statistics for each processor, updating every 2 seconds. It shows that %usr, which is user mode CPU usage percentage, is close to 90% on an 8-core or less head node when the 8 subshell processes are running.
10.1.2.2 Setting Up The Kill Action
To stop the pointless CPU-intensive yes processes, the command killall yes can be used. The administrator can make it a part of a script killallyes:
and make the script executable with a chmod 700 killallyes. For convenience, it may be placed in the /cm/local/apps/cmd/scripts/actions directory where some other action scripts also reside.
10.1.3 Using The Basic Monitoring Example
Now that the pieces are in place, the administrator can use Base View to add the killallyesaction action to its action list, and then set up a trigger for the action:
10.1.3.1 Adding The Action To The Actions List
In Base View:
-
The navigation path
Monitoring > Actions > Monitoring Actions > killprocess⋮ > Cloneis used to clone the object structure of an existing action. The
killprocessaction is a convenient choice of existing action to clone because it is expected to function in a similar way tokillallyes, which means that the values in the cloned object should not have to be modified much. However, any action could be cloned and the clone modified in appropriate places. -
The name of the cloned action is changed. That is, the administrator sets
Nametokillallyesaction. This is just a sensible label—the name can be arbitrary. -
Scriptis set to the path/cm/local/apps/cmd/scripts/actions/killallyes, which is where the script was placed earlier (here).
After saving, the killallyesaction action becomes part of the list of monitoring actions (figure 10.2):
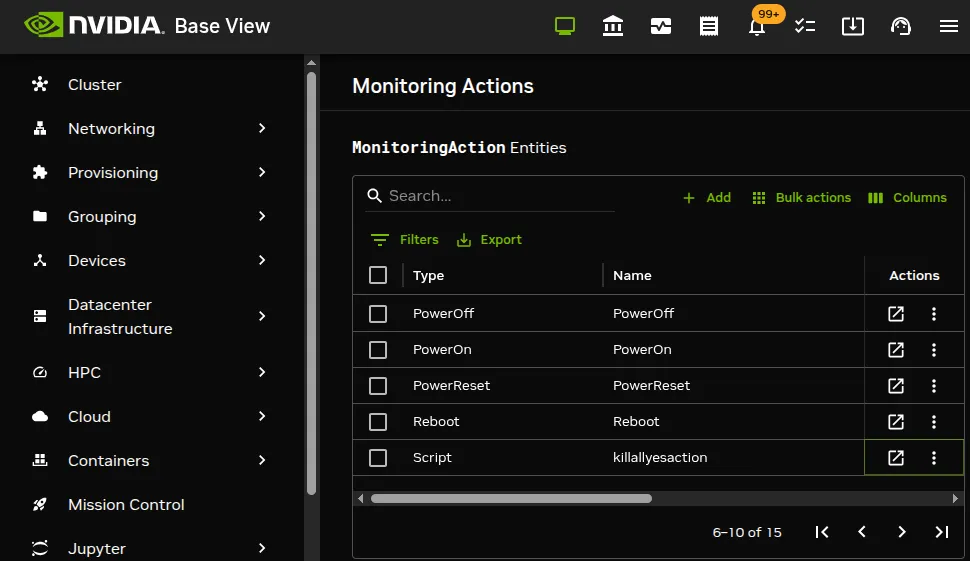
Figure 10.2: Base View Monitoring Configuration: Adding An Action
10.1.3.2 Setting Up A Trigger Using CPUUser On The Head Node(s)
The navigation path
Monitoring > Triggers > Failing health checks > Clone
can be used to configure a monitoring trigger, by cloning an existing trigger. A trigger is a condition that is set on the state of sample, which runs an action when that condition is met. In this case, the sample state condition may be that the metric (section 10.2.3) CPUUser must not exceed 50. If it does, then an action (killallyesaction) is run, which should kill the yes processes.
-
CPUUseris a measure of the time spent in user mode CPU usage per second, and is measured in jiffy intervals per second. -
A jiffy interval is a somewhat arbitrary time interval that is predefined for kernel developers per platform. It is the minimum amount of time that a process has access to the CPU before the kernel can switch to another task.
The jiffy interval per second of
CPUUseris a quantity rather than a percentage. It should not be confused with the closely related measurableCPUUsage, which is a percentage.CPUUsageis used for%usermonitoring, where%useris the user time as defined and measured for thetopcommand.
To configure triggering for CPUUser, the trigger attributes can be modified as follows (figure 10.3):
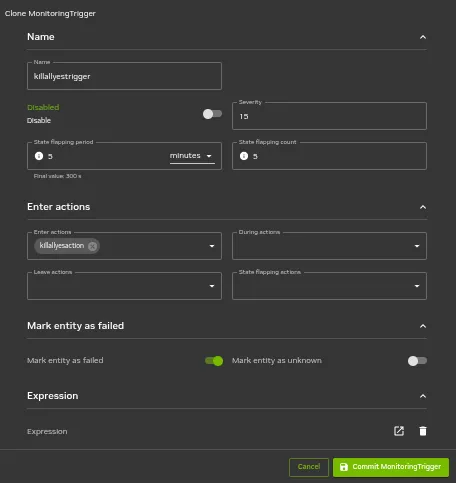
Figure 10.3: Base View Monitoring Configuration: Setting A Trigger
-
A name is set for the trigger. The name can be arbitrary, and
killallyestriggeris used in this example. -
The trigger is enabled (that is: the
Disabledtoggle is not enabled). -
The
Enter actionsfield is filled with thekillallyesaction, which is the action defined earlier. -
The trigger is saved by clicking on the
Commit MonitoringTriggerbutton. -
the trigger can be set to run an action script if the sample state crosses over into a state that meets the trigger condition. That is,
Enter actionsis configured for a particular condition.The condition under which the
Enter actionsaction script is run in the example, can simply be whenCPUUseron the head node is above 50. Such a condition can be set by setting an expression in a subwindow. The subwindow to do this is opened with theExpressionbox ↗ icon seen at the bottom of the screen in figure 10.3.Clicking on the icon brings up the
MonitoringCompareExpressionsubwindow (figure 10.4):
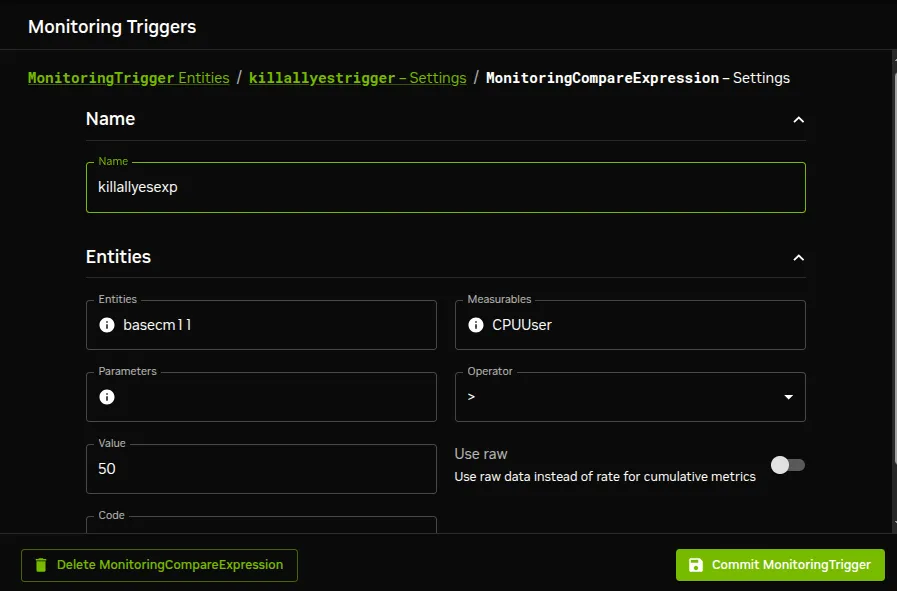
Figure 10.4: Base View Monitoring Configuration: Setting An Expression
Within the subwindow:
-
A name is set for the expression. The name can be arbitrary, and
killallyesexpis used forNamein this example. -
An entity is set. In this case, the entity being monitored is the head node. If the head node is called
basecm11in this example, thenbasecm11is the value set forEntities. An entity is often simply a device, but it can be any object that CMDaemon stores. -
A measurable is set. In this case,
Measurablesis set toCPUUser. -
An operator and threshold value are set. In this case
>, which is the greater than operator, and50which is a significant amount of CPUUser time in jiffies/s, are set forOperatorandValue.
After saving the configuration, the killallyesexp expression evaluates the data being sampled for the killallyestrigger trigger. If the expression is TRUE, then the trigger launches the killallyesaction action.
10.1.3.3 The Result
In the preceding section, an action was added, and a trigger was set up with a monitoring expression.
With a default installation on a newly installed cluster, the measurement of CPUUser is done every 120s (the period can be modified in the Data Producer window of Base View, as seen in figure 10.11). The basic example configured with the defaults thus monitors if CPUUser on the head node has crossed the bound of 50 jiffies/s every 120s.
If CPUUser is found to have entered—that is: crossed over from below the value and gone into the zone beyond 50 jiffies/s—then the killallyesexp expression notices that. Then, the trigger it is configured for, killallyestrigger trigger, runs the killallyesaction action, which runs the killallyes script. The killallyes script kills all the running yes processes. Assuming the system is trivially loaded apart from these yes processes, the CPUUser metric value then drops to below 50 jiffies/s.
To clarify what “found to have entered” means in the previous paragraph:
After an Enter trigger condition has been met for a sample, the first sample immediately after that does not ever meet the Enter trigger condition, because an Enter threshold crossing condition requires the previous sample to be below the threshold.
The second sample can only launch an action if the Enter trigger condition is met and if the preceding sample is below the threshold.
Other non-yes CPU-intensive processes running on the head node can also trigger the killallyes script. Since the script only kills yes processes, leaving any non-yes processes alone, it would in such a case run unnecessarily. This is a deficiency due to the contrived and simple nature of the basic example which is being illustrated here. In a production case the action script is expected to have a more sophisticated design.
At this point, having gone through section 10.1, the reader is expected to have a rough idea of how monitoring, triggers, trigger conditional expressions, and actions work. The following sections in this chapter cover the concepts and features for BCM monitoring in greater detail.
10.2 Monitoring Concepts And Definitions
A discussion of the concepts of monitoring, along with definitions of terms used, is appropriate at this point. The features of the monitoring system in BCM covered later on in this chapter will then be understood more clearly.
10.2.1 Measurables
Measurables are measurements (sample values) that are obtained via data producers (section 10.2.10) in CMDaemon’s monitoring system. The measurements can be made for nodes, head nodes, other devices, or other entities.
10.2.1.1 Types Of Measurables
Measurables can be:
-
enummetrics: measurements with a small number of states. The states can be pre-defined, or user-defined. Further details on enummetrics are given in section 10.2.2.
-
metrics: measurements with number values, and
no data, as possible values. For example, values such as:-13113143234.5,24,9234131299. Further details on metrics are given in section 10.2.3. -
health checks: measurements with the states
PASS,FAIL, andUNKNOWNas possible states, andno dataas another possible state, when none of the other states are set. Further details on health checks are given in section 10.2.4.
10.2.1.2 no data And Measurables
If no measurements are carried out, but a sample value needs to be saved, then the sample value is set to no data for a measurable. This is a defined value, not a null data value. metrics and enummetrics can therefore also take the no data value.
10.2.1.3 Entities And Measurables
An entity is a concept introduced in BCM version 8.0.
Normally, a device, or a category or some similar grouping is a convenient idea to keep in mind as an entity, for concreteness.
The default entities in a new installation of BCM are the following:
device category partition[base] softwareimages
However, more generally, an entity can be an object from the following modes of cmsh:
category cloud configurationoverlay device edgesite etcd fspart group jobqueue jobs kubernetes network nodegroup partition profile rack softwareimage user
For example, a software image object that is to be provisioned to a node is an entity, with some of the possible attributes of the entity being the name, kernelversion, creationtime, or locked attributes of the image:
Because measurements can be carried out on such a variety of entities, it means that the monitoring and conditional actions that can be carried out on a BCM cluster can be very diverse. This makes entities a powerful and versatile concept in BCM’s monitoring system for managing clusters.
10.2.1.4 Listing Measurables Used By An Entity
In cmsh, for an entity, such as a device within device mode, a list of the measurables used by that device can be viewed with the measurables command.
Example
The subsets of these measurables—enummetrics, metrics, and health checks—can be listed with the enummetrics (section 10.2.2), metrics (section 10.2.3), or healthchecks (section 10.2.4) command.
In Base View, all the entities that are using health checks can be viewed via the navigation path:
Monitoring > All Health Checks (figure 10.25 section 10.4.7)
10.2.1.5 Listing Entities That Use A Measurable
The entities using a specific measurable can be listed with the usage command:
Example
If the number of measurables is too large to view on the screen:
Example
then the -v option can be used to list the entities over multiple lines:
Example
10.2.1.6 Listing Measurables From monitoring Mode
Similarly, under monitoring mode, within the measurable submode, the list of measurable objects that can be used can be viewed with a list command:
Example
The subsets of these measurables—enummetrics, metrics, and health checks—can be listed with: list enum (section 10.2.2), list metric (section 10.2.3), or list healthcheck (section 10.2.4).
In Base View, the equivalent to listing the measurables can be carried out via the navigation path:
Monitoring > Measurables (figure 10.12, section 10.4.2)
10.2.1.7 Viewing Parameters For A Particular Measurable From monitoring Mode
Within the measurable submode, parameters for a particular measurable can be viewed with the show command for that particular measurable:
Example
10.2.2 Enummetrics
An enummetric is a measurable for an entity that can only take a limited set of values. At the time of writing of this section (February 2026), the enummetrics, and their possible values, are:
The values possible for the enummetrics are as follows:
-
DeviceStatus:up,down,closed,installing,installer_failed,installer_rebooting,installer_calling_init,installer_unreachable,installer_burning,burning,unknown,opening,going_down,pending, andno data -
wlm_slurm_state:allocated,completing,down,drain,draining,fail,failing,idle,maint, andmixed -
sys_class_net_name_assign_type:unpredictable,predictable,userspace, andrenamed
The list of possible values for an enummetric can be seen with the enumvalues command, used within the enummetric object:
Example
The enummetrics available for use can be listed from within the measurable submode of the monitoring mode:
Example
The list of enummetrics that is configured to be used by an entity, such as a device, can be viewed with the enummetrics command for that entity:
Example
The states that the entity has been through can be viewed with a dumpmonitoringdata command (section 10.6.4):
Example
The parameters of an enummetric such as devicestatus can be viewed and set from monitoring mode, from within the measurable submode (here).
10.2.3 Metrics
A metric for an entity is typically a numeric value for an entity. The value can have units associated with it.
In the basic example of section 10.1, the metric value considered was CPUUser, measured at the default regular time intervals of 120s.
The value can also be defined as no data. no data is substituted for a null value when there is no response for a sample. no data is not a null value once it has been set. This means that there are no null values stored for monitored data.
Other examples for metrics are:
-
LoadOne(value is a number, for example: 1.23) -
WriteTime(value in ms/s, for example: 5 ms/s) -
MemoryFree(value in readable units, for example: 930 MiB, or 10.0 GiB)
A metric can be a built-in, which means it comes with BCM as integrated code within CMDaemon. This is based on c++ and is therefore much faster than the alternative. The alternative is that a metric can be a standalone script, which means that it typically can be modified more easily by an administrator with scripting skills.
The word metric is often used to mean the script or object associated with a metric as well as a metric value. The context makes it clear which is meant.
A list of metrics in use can be viewed in cmsh using the list command from monitoring mode:
Example
In Base View, the metrics can be viewed with the navigation path:
Monitoring > Measurables (figure 10.12, section 10.4.2)
A list of metrics in use by an entity can be viewed in cmsh using the metrics command for that entity. For example, for the entity node001 in mode devices:
Example
The parameters of a metric such as AlertLevel:count can be viewed and set from monitoring mode, from within the measurable submode, just as for the other measurables:
Example
The equivalent Base View navigation path to edit the parameters is:
Monitoring > Measurables >Edit
10.2.4 Health Check
A health check value is a response to a check carried out on an entity. The response indicates the health of the entity for the check that is being carried out.
For example, the ssh2node health check, which runs on the head node to check if the SSH port 22 passwordless access to regular nodes is reachable.
A health check is run at a regular time interval, and can have the following possible values:
-
PASS: The health check succeeded. For example, ifssh2nodeis successful, which suggests that ansshconnection to the node is fine. -
FAIL: The health check failed. For example, ifssh2nodewas rejected. This suggests that thesshconnection to the node is failing. -
UNKNOWN: The health check did not succeed, did not fail, but had an unknown response. For example, ifssh2nodehas a timeout, for example due to routing or other issues. It means that it is unknown whether the connection is fine or failing, because the response that came in is unknown. Typically the administrator should investigate this further. -
no data: The health check did not run, so no data was obtained. For example, ifssh2nodeis disabled for some time, then no data values were obtained during this time. Since the health check is disabled, it means thatno datacannot be recorded during this time byssh2node. However, because having ano datavalue in the monitoring data for this situation is a good idea—explicitly knowing about having no data is helpful for various reasons—thenno datavalues can be set, by CMDaemon, for samples that have no data.
Other examples of health checks are:
-
diskspace: check if the hard drive still has enough space left on it -
mounts: check mounts are accessible -
mysql: check status and configuration of MySQL is correct -
hpraid: check RAID and health status for certain HP RAID hardware
These and others can be seen in the directory: /cm/local/apps/cmd/scripts/healthchecks.
10.2.4.1 Health Checks
In Base View, the health checks that can be configured for all entities can be seen with the navigation path:
Monitoring > Measurables (figure 10.12, section 10.4.2)
Options can be set for each health check by clicking through via the Edit button.
10.2.4.2 All Configured Health Checks
In Base View, health checks that have been configured for all entities can be seen with the navigation path:
Monitoring > All Health Checks (section 10.4.7)
The view can be filtered per column.
10.2.4.3 Configured Health Checks For An Entity
An overview can be seen for a particular entity <entity> via the navigation path:
Monitoring > Health status><entity>>Show
10.2.4.4 Severity Levels For Health Checks, And Overriding Them
A health check has a settable severity (section 10.2.7) associated with its response defined in the trigger options.
For standalone healthchecks, the severity level defined by the script overrides the value in the trigger. For example, FAIL 40 or UNKNOWN 10, as is set in the hpraid health check (/cm/local/apps/cmd/scripts/healthchecks/hpraid).
Severity values are processed for the AlertLevel metric (section 10.2.8) when the health check runs.
10.2.4.5 Default Templates For Health Checks And Triggers
A health check can also launch an action based on any of the response values.
Monitoring triggers have the following default templates:
-
Failing health checks: With a default severity of15 -
Passing health checks: With a default severity of0 -
Unknown health checks: With a default severity of10
The severity level is one of the default parameters for the corresponding health checks. These defaults can also be modified to allow an action to be launched when the trigger runs, for example, sending an e-mail notification whenever any health check fails.
With the default templates, the actions are by default set for all health checks. However, specific actions that are launched for a particular measurable instead of for all health checks can be configured. To do this , one of the templates can be cloned, the trigger can be renamed, and an action can be set to launch from a trigger. The reader should be able to recognize that in the basic example of section 10.1 this is how, when the metric measurable CPUUser crosses 50 jiffies/s, the killallyestrigger is activated, and the killallyes action script is run.
10.2.5 Trigger
A trigger is a threshold condition set for a sampled measurable. When a sample crosses the threshold condition, it enters or leaves a zone that is demarcated by the threshold.
A trigger zone also has a settable severity (section 10.2.7) associated with it. This value is processed for the AlertLevel metric (section 10.2.8) when an action is triggered by a threshold event.
Triggers are discussed further in section 10.4.5.
10.2.6 Action
In the basic example of section 10.1, the action script is the script added to the monitoring system to kill all yes processes. The script runs when the condition is met that CPUUser crosses 50 jiffies/s.
An action is a standalone script or a built-in command that is executed when a condition is met, and has exit code 0 on success. The condition that is met can be:
-
A
FAIL,PASS,UNKNOWN, orno datafrom a health check -
A trigger condition. This can be a
FAILorPASSfor conditional expressions. -
State flapping (section 10.2.9).
The actions that can be run are listed from within the action submode of the monitoring mode.
Example
The Base View equivalent is accessible via the navigation path:
Monitoring > Actions (figure 10.19, section 10.4.4)
Configuration of monitoring actions is discussed further in section 10.4.4.
10.2.7 Severity
Severity is a positive integer value that the administrator assigns for a trigger. It takes one of these 6 suggested values:
| Value | Name in cmsh | Base View Icon | Description |
|---|---|---|---|
0 | debug |  | debug message |
0 | info | | informational message |
10 | notice | | normal, but significant, condition |
20 | warning |  | warning conditions |
30 | error |  | error conditions |
40 | alert | | action must be taken immediately |
Severity levels are used in the AlertLevel metric (section 10.2.8). They can also be set by the administrator in the return values of health check scripts (section 10.2.4).
By default the severity value is 15 for a health check FAIL response, 10 for a health check UNKNOWN response, and 0 for a health check PASS response (section 10.2.4.4).
10.2.8 AlertLevel
AlertLevel is a special metric. It is sampled and re-calculated when an event with an associated Severity (section 10.2.7) occurs. There are three types of AlertLevel metrics:
-
AlertLevel (count): the number of events that are atnoticelevel andhigher. The aim of this metric is to alert the administrator to the number of issues. -
AlertLevel (max): simply the maximum severity of the latest value of all the events. The aim of this metric is to alert the administrator to the severity of the most important issue. -
AlertLevel (sum): the sum of the latest severity values of all the events. The aim of this metric is to alert the administrator to the overall severity of issues.
10.2.9 Flapping
Flapping, or State Flapping, is when a measurable trigger is detecting changes (section 10.4.5.1) that are too frequent. That is, the measurable goes in and out of the zone too many times over a number of samples. In the basic example of section 10.1, if the CPUUser metric crossed the threshold zone 5 times within 5 minutes (the default values for flap detection), then it would by default be detected as flapping. A flapping alert would then be recorded in the event viewer, and a flapping action could also be launched if configured to do so.
10.2.10 Data Producer
A data producer produces measurables. Sometimes it can be a group of measurables, as in the measurables provided by a data producer that is being used:
Example
Sometimes it may just be one measurable, as provided by a used data producer:
Example
It can even have no measurables, and just be an empty container for measurables that are not in use yet.
In cmsh all possible data producers (used and unused) can be listed as follows:
Example
The equivalent in Base View is via the navigation path:
Monitoring > Data Producers
The data producers configured for an entity, such as a head node basecm11, can be listed with the monitoringproducers command:
Example
The displayed data producers are the ones configured for the entity, even if there are no measurables used by the entity.
Data producer configuration in Base View is discussed further in section 10.4.1.
10.2.10.1 Access Control For Monitoring Data
Access control to data producers: An access control setting for a data producer determines who can plot (via the measurables monitoring interface used by Base View and the User Portal), or view data (using the text-based interface of cmsh or pythoncm) from the measurables generated by a data producer. Thus, for example, the charts in the user portal (section 10.8) can be restricted according to the data producer that generates them.
There are three possible settings for access control for data producers. If the data producer is set to:
-
Public: then it means any user can, by default, plot/view data derived from that data producer. This is because by default a user has the tokenPLOT_TOKENin their profile. -
Private: then it means that a non-root user cannot, by default, plot/view data derived from that data producer. This is because, by default, non-root users do not have the tokenPRIVATE_MONITORING_TOKENin their profile. If that token is in the profile, then the user has an elevated privilege, and can plot/view data, just like root. -
Individual: then it means that a non-root user, by default, can plot/view the data only if the job associated with that data was run by that same non-root user. More verbosely, with the default user settings: the user who ran a job for which job measurables are produced by a data producer, must be the same as the user who wants to plot/view the data, or else the data cannot be plotted/viewed. The exception to this is, as already suggested, if the user that wants to plot/view the data is root, or has a user profile with the tokenPRIVATE_MONITORING_TOKEN. In that case the data can be plotted/viewed.NOTE: In more detail, individual access control is meant for job-based measurables, and works like this:
All monitoring data is stored per (entity, measurable) pair.
If the measurable has an access control value of
individual, then a user check is performed. If the login name is the same as the user that owns the entity, then data can be plotted/viewed. If the user check does not match, then no data is returned.Jobs—which are entities—are owned by the user that ran the job. Similarly Prometheus (entities) can have a
user="Alice"label set, to define ownership. No other entity managed by BCM is owned by a user.For all unowned entities, individual access is equivalent to private access.
On a regular BCM cluster, only a few low level data producers are set to private. An administrator can decide to set a data producer access control value to one of the three possible values, by using the setup submode of monitoring mode:
Example
If a data producer is newly added, then by default its access control value is set to public. Changing this to private at a later time means that access to past and future data values from that data producer are affected by the private setting. If access is changed once more back to public, then it means that access to past and future data values are once again viewable and plottable by all users.
The current settings for access control for the data producers can be seen with:
Example
Access control to measurables: Measurables can also have access controls.
Access control for measurables is by default inherited from the data producer that generates it. It can be overwritten:
Example
A measurable can thus take an access control value of Public, Private, or Individual. It can also explicitly be set to a value of inherit, which sets it to the value of its data producer. The inheritance is indicated in cmsh by enclosing the parent data producer in parentheses, as shown in the preceding example.
The current settings for access control for the measurables can be seen with:
Example
10.2.11 Conceptual Overview: The Main Monitoring Interfaces Of Base View
Base View, besides having the default settings mode, has some other display modes and logging view modes that can be selected via the 8 icons in the top right corner of the Base View standard display (figure 10.5):

Figure 10.5: Base View: Top Right Corner Icons
The 8 icons are described from left to right next:
-
Cluster Overviewicon has the browser display the main cluster overview page (figure 2.3). -
The
Accountingicon brings up a window that allows visualization of job resources used by users, although it can be used to visualize job resources used by other entities that are used as a classifier. Job accounting (Chapter 12) is helpful in tracking resources consumed by users. -
The
Monitoringmode allows visualization of the data values collected according to the specifications of the Base ViewMonitoringresource. The visualization allows graphs to be configured, and is discussed further in section 10.3. -
The
Chargebackmode allows the monitoring of resources requested over a period for jobs run by selected groups (Chapter 13). -
The
Eventsicon allows logs of events (section 10.10) to be viewed. -
The
Background tasksicon allows background tasks to be viewed. -
The
Package Updatesicon lists packages that can be updated. This is the Base View equivalent of thepackages --outdatedcommand incmsh(section 9.1.1). -
The ≡ icon (hamburger icon, collapsed menu icon) expands to show, among other options, a dark mode toggle, and a logout option (figure 10.6):
Figure 10.6: Base View Top Right Hand Corner Menu items
The monitoring aspects of the second and third icons of figure 10.5 are discussed in greater detail in the sections indicated.
10.3 Monitoring Visualization With Base View
The Monitoring icon in the menu bar of Base View (item 3 in figure 10.5) launches an intuitive visualization tool that is the main GUI tool for getting a feel of the system’s behavior over periods of time. With this tool the measurements and states of the system can be viewed as resizable and overlayable graphs. The graphs can be zoomed in and out on over a particular time period, the graphs can be laid out on top of each other or the graphs can be laid out as a giant grid. The graph scale settings can also be adjusted, stored and recalled for use the next time a session is started.
An alternative to Base View’s visualization tool is the command-line cmsh. This has the same functionality in the sense that data values can be selected and studied according to configurable parameters with it (section 10.6). The data values can even be plotted and displayed on graphs with cmsh with the help of unix pipes and graphing utilities. However, the strengths of monitoring with cmsh lie elsewhere: cmsh is more useful for scripting or for examining pre-decided metrics and health checks rather than a quick visual check over the system. This is because cmsh needs more familiarity with options, and is designed for text output instead of interactive graphs. Monitoring with cmsh is discussed in sections 10.5 and 10.6.
Visualization of monitoring graphs with Base View is now described.
10.3.1 The Monitoring Window
If the Monitoring icon is clicked on from the menu bar of Base View (figure 10.5), then a monitoring window for visualizing data opens up. By default, this displays a dashboard called Critical Services which has two plot panels. The plot panels have graph axes with a time scale going back some time on the x-axis, and with a y-axis that allows measurable data values plotted against time (figure 10.7).
By default, the data values that are plotted are for the ManagedServicesOK health check. The first panel displays the plots for the head node, the second panel displays the plots for all the regular nodes in the default category.
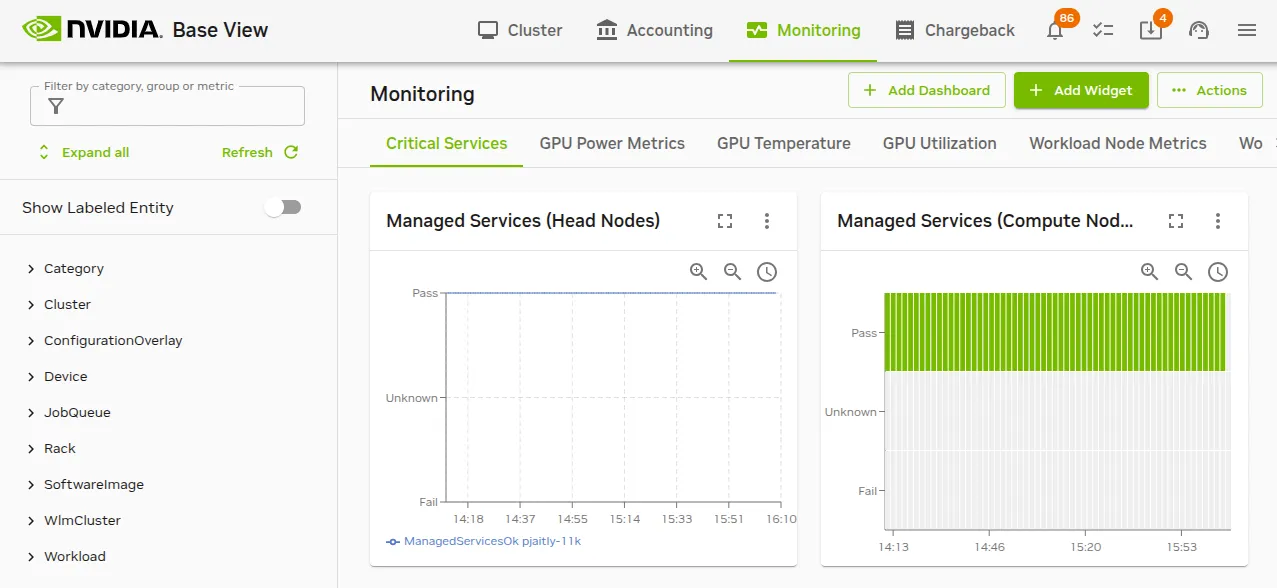
Figure 10.7: Base View Monitoring Window: Default Plot Panels
10.3.1.1 Finding And Selecting The Measurable To Be Plotted
To plot measurables, the entity which it belongs to should be selected from the navigation menu on the left-hand side. Once that has been selected, a class for that measurable can be chosen, and then the measurable itself can be selected. For example, to plot the measurable CPUUser for a head node basecm11, it can be selected from the navigation path:
Monitoring icon > Device > head node > CPU > CPUUser
Sometimes, finding a measurable is easier if the Expand all widget is used, together with the filter box. Typing in CPUUser in the filter box then shows all the measurables with that text (figure 10.8). The search is case-insensitive.
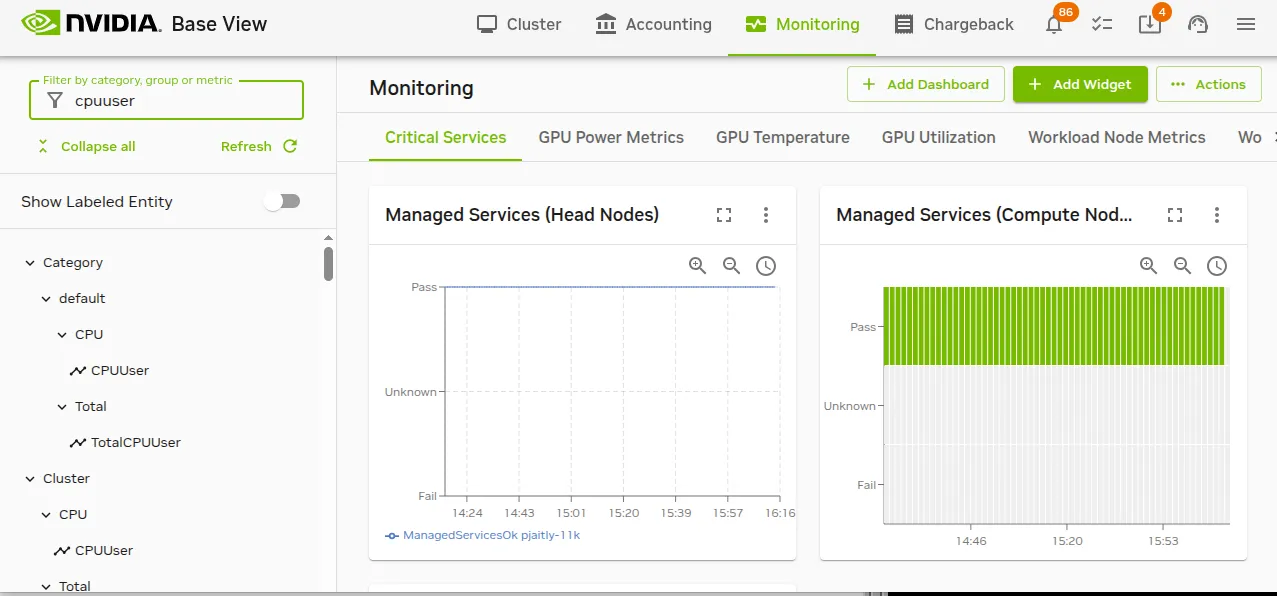
Figure 10.8: Base View Monitoring Window: Search Box In Navigation
The search box can handle some simple regexes too, with .* and | taking their usual meaning:
Example
-
node001.*cpuuser: select a measurable with a data path that starts withnode001and ends withcpuuser, with 0 or more characters of any kind in between. -
(node001|node002).*cpuuser: as for preceding example, but includingnode002as an alternative tonode001.
The / (forward slash) allows filtering according to the data path. It corresponds to the navigation depth in the tree hierarchy:
Example
node001/cpu/cpuuser: search for a measurable with a data path that matchesnode001/cpu/cpuuser
10.3.1.2 Plotting The Measurable
Once the measurable is selected, it can be drag-and-dropped into a plot panel. This causes the data values to be plotted.
When a measurable is plotted into a panel, two graph plots are displayed. The smaller, bottom plot, represents the polled value as a bar chart. The larger, upper plot, represents an interpolated line graph. Different kinds of interpolations can be set. To get a quick idea of the effect of different kinds of interpolations, https://bl.ocks.org/mbostock/4342190 is an interactive overview that shows how they work on a small set of values.
The time axes can be expanded or shrunk using the mouse wheel in the graphing area of the plot panel. The resizing is carried out centered around the position of the mouse pointer.
10.4 Monitoring Configuration With Base View
This section is about the configuration of monitoring for measurables, and about setting up trigger actions.
If Base View is running in the standard Cluster Overview mode selecting Monitoring from the navigation menu resources makes the following menu items available for managing or viewing:
-
Data Producers(section 10.4.1) -
Measurables(section 10.4.2) -
Consolidators(section 10.4.3) -
Actions(section 10.4.4) -
Triggers(section 10.4.5) -
Health status(section 10.4.6) -
All Health checks(section 10.4.7) -
Standalone Monitored Entities(section 10.4.8) -
Queries(section 10.4.9)
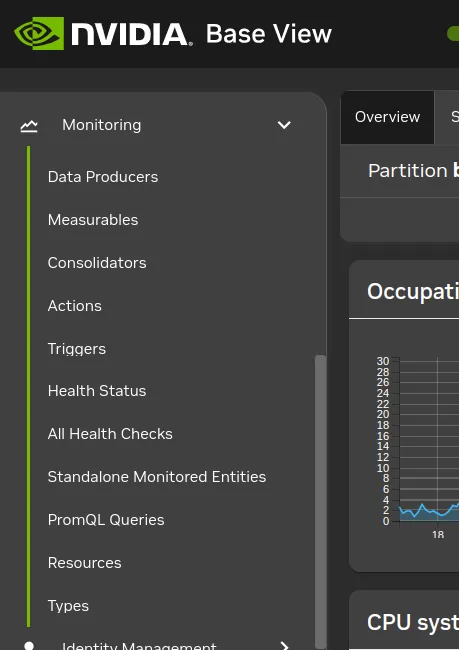
Figure 10.9: Base View Monitoring Configuration Settings
These settings (figure 10.9) are now discussed in detail.
10.4.1 Monitoring Configuration: Data Producers
The navigation path:
Monitoring > Dataproducers
opens up the Monitoring Data Producer list screen, which lists all the data producers (figure 10.10).
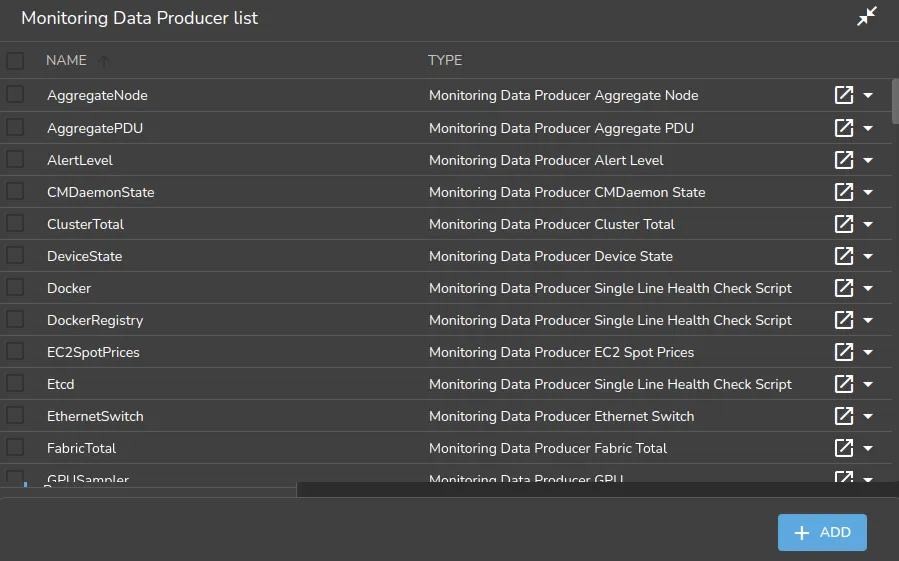
Figure 10.10: Base View Monitoring Configuration Data Producers
Data producers are introduced in section 10.2.10.
Each data producer can have its settings edited within a subwindow. For example, the ProcStat data producer, which produces data for several measurables, including CPUUser, has the settings shown in figure 10.11:
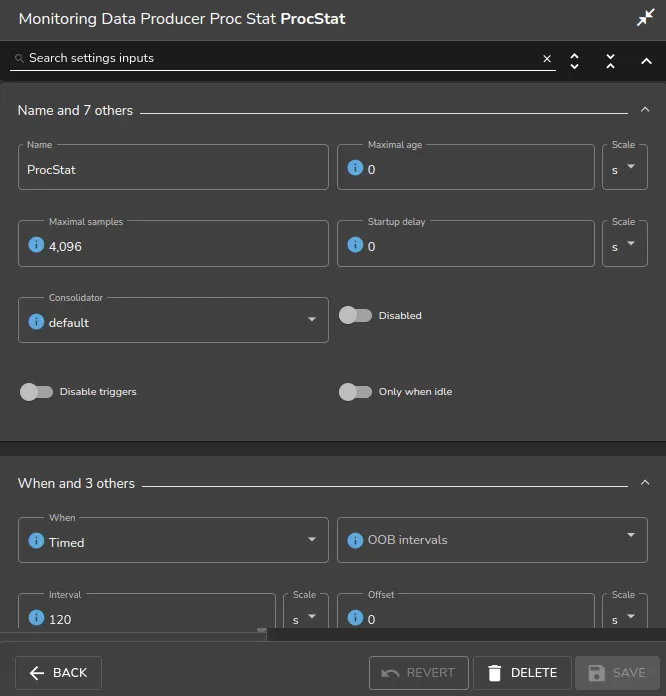
Figure 10.11: Base View Monitoring Configuration Data Producer: ProcStat
When the data producer takes samples to produce data, run length encoding (RLE) is used to compress the number of samples that are stored as data. Consolidation is carried out on the RLE samples. Consolidation in BCM means gathering several data values, and making one value from them over time periods. Consolidation is done as data values are gathered. The point at which data values are discarded, if ever, is thus not dependent on consolidation.
The data producer settings that are seen in the subwindow of figure 10.11 include the following:
-
Maximal samples: the maximum number of RLE samples that are kept. If set to0, then the number of samples is not considered. -
Maximal Age: the maximum age of RLE samples that are kept. IfMaximal Ageis set to0then the sample age is not considered.With
Maximal samplesandMaximal Age, the first of the rules that is reached is the one that causes the exceeding RLE samples to be dropped.Samples are kept forever if
Maximal samplesandMaximal Ageare both set to0. This is discouraged due to the risk of exceeding the available data storage space.If the number of samples is reduced, then previously consolidated data values are automatically discarded after about 30 minutes. Changing parameters should therefore be done with some care.
-
Interval: the interval between sampling, in seconds. -
Offset: A time offset from start of sampling. Some sampling depends on other sampling to be carried out first. This is used, for example, by data producers that rely on sampling from other data producers. For example, theAggregateNodedata producer, which has measurables such asTotalCPUIdleandTotalMemoryFree. The samples forAggregateNodedepend upon theProcStatdata producer, which produces theCPUIdlemeasurable; and theProcMemInfodata producer, which produces theMemoryFreemeasurable. -
Fuzzy offset: a multiplier in the range from 0 to 1. It is multiplied against the sampling time interval to fix a maximum value for the time offset for when the sampling takes place. The actual offset used per node is spread out reasonably evenly within the range up to that maximum time offset.For example, for a sampling time interval of 120s:
If the offset is
0, then there is no offset, and the sampling is attempted for all nodes at time instant when the interval restarts. This can lead to an overload at the time of sampling.If, on the other hand, the offset is
0.25, then the sampling is done within a range offset from the time of sampling by a maximum of 0.25 × 120s = 30s. So, each node is sampled at a time that is offset by up to 30s from when the 120s interval restarts. From the time the change in value of the fuzzy offset starts working, the offset is set for each node. The instant at which sampling is carried out on a node then differs from the other nodes, even though each node still has an interval of 120s between sampling. An algorithm is used that tends to even out the spread of the instants at which sampling is carried out within the 30s range. The spreading of sampling has the effect of reducing the chance of overload at the time of sampling. -
Consolidator: By default, set to thedefaultgroup. Thedefaultgroup consolidates (summarizes) the RLE samples over periods of an hour. Consolidators are explained further in section 10.4.3. -
Node execution filters(here): A way to filter execution (restrict execution) of the data producer. It tells BCM where the data producer runs. If not set, then the data producer runs on all nodes managed by CMDaemon. -
Execution multiplexer(here): A way to multiplex execution (have execution work elsewhere) for a data producer. The object tells BCM about the entities that the data producer is executing sampling at. Thus a data producer gathers data at the nodes defined by the node execution filter, and the data producer executes sampling at other entities, which are defined into groups called execution multiplexers. -
When: This has four possible values:-
Timed: Data producer is run at a periodicInterval. This is the default. -
On demand: Data producer is only run on demand, and not at a periodicInterval. -
Out of band: Data producer is only run on out of band connections. -
On start: Data producer is only run on start and not at a periodicInterval.
-
-
Only when idle: By default a data producer runs regardless of how busy the nodes are. However, if theOnly when idlesetting is enabled, then the data producer runs only when the node is idle. Idle is a condition that is defined by the metric conditionLoadOne>1(here).
10.4.2 Monitoring Configuration: Measurables
The Base View navigation path Monitoring > Measurables lists the available measurables (figure 10.12):
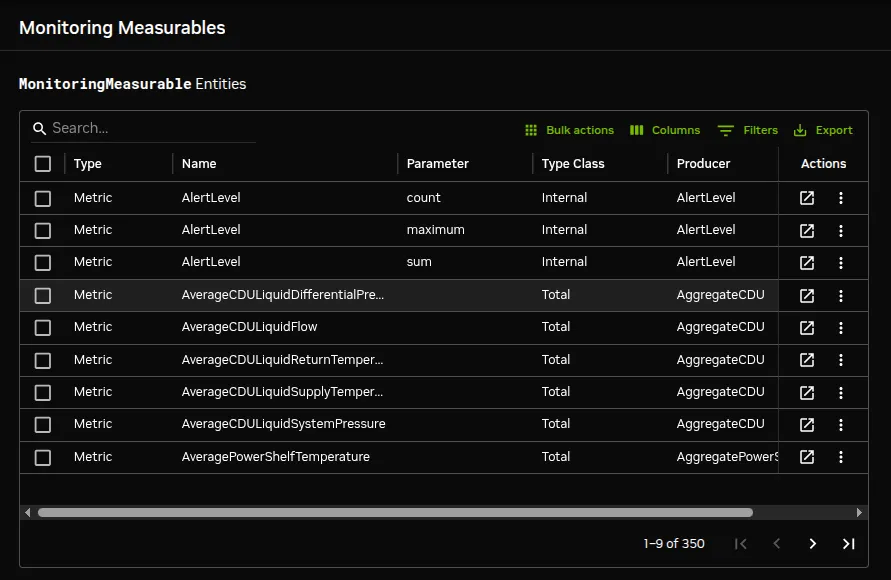
Figure 10.12: Base View Monitoring Configuration Measurables
There are many measurables, so using the search box can be handy.
The ↗ icon opens a window for settings to a particular measurable. In figure 10.13 metric settings are seen for the AlertLevel metric:
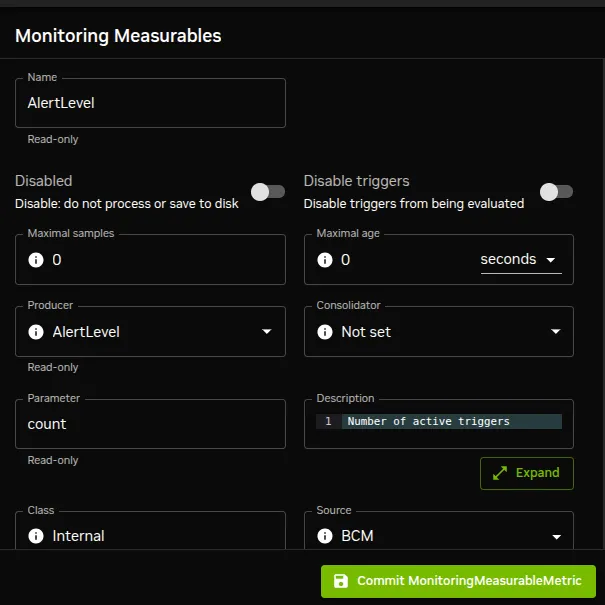
Figure 10.13: Base View Monitoring Configuration Measurables Settings Window
The sampling options include: Maximal age, Maximal samples, and Consolidator. The sampling options work as described for data producers (section 10.4.1).
Other options for a metric are setting the Maximum and Minimum values, the Unit used, and whether the metric is Cumulative.
If a metric is cumulative, then it is monotonic. Monotonic means that the metric only increments (is cumulative), as time passes. In other words, if the metric is plotted as a graph against time, with time on the x-axis, then the metric never descends. Normally the increments are from the time of boot onward, and the metric resets at boot. For example, the number of bytes received at an interface is cumulative, and resets at boot time.
Usually the cluster administrator is only interested in the differential value of the metric per sample interval. That is, the change in the value of the current sample, from its value in the preceding sample. For example, bytes/second, rather than total number of bytes up to that time from boot.
10.4.3 Monitoring Configuration: Consolidators
10.4.3.1 Introduction To Consolidators
The concept of consolidators is explained using simple ascii graphics in Appendix K, while the cmsh interface to the consolidators submode is discussed in section 10.5.2.
In this current section, the Base View interface to consolidators is discussed.
In Base View, the navigation path Monitoring > Consolidator lists all consolidator groups (figure 10.14). There are two pre-existing consolidator groups: default and none.
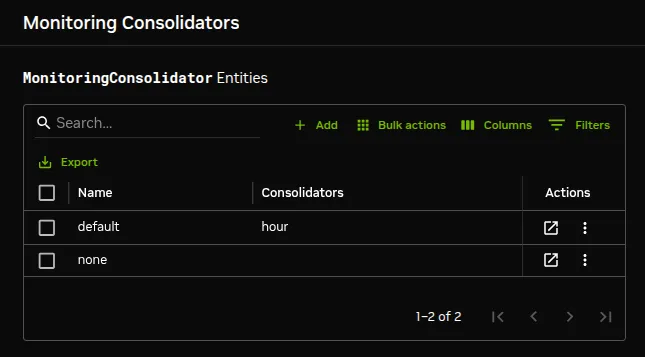
Figure 10.14: Base View Monitoring Consolidator list
Subwindows allow the consolidator components (consolidator items) to be created or modified (figure 10.15).
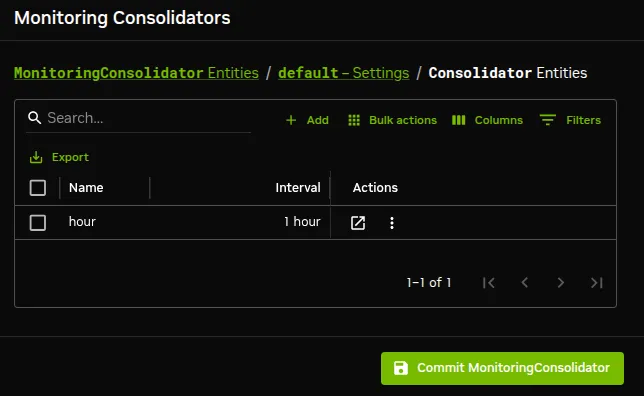
Figure 10.15: Base View Monitoring Configuration Consolidator Items
10.4.3.2 The none Consolidator Group
The none consolidator group has no consolidators. Using a consolidator group of none for a measurable or data producer means that samples are not consolidated. This can be dangerous if the cluster is more likely to run out of space due to unrestrained sampling. Unrestrained sampling can occur, for example, if Maximal Age and Maximal samples (section 10.4.1) for data producers are both set to 0.
10.4.3.3 The default Consolidator Group
In BCM 11, the default consolidator group consists of the consolidator hour only. If the cluster was upgraded to BCM 11 from BCM 10, then legacy day and week consolidators are also present. The consolidators are, unsurprisingly, defined to consolidate the samples in intervals of an hour, day, or week.
A consolidated value is generated on-the-fly. So, for example, during the hour that samples of a measurable come in, the hour consolidator uses the samples to readjust the consolidated value for that hour. When the hour is over, the consolidated value is stored for that hour as the data value for that hour, and a new consolidation for the next hour begins.
Consolidator values are kept, as for sample values, until the Maximal Age and Maximal sample settings prevent data values being kept.
In BCM 11 and later, the maximal samples for hours is set by default to 2[16] hours, which is about 7.5 years.
10.4.3.4 Other Consolidator Group Possibilities
Other sets of custom intervals can also be defined. For example, instead of the default consolidator group, which could consist of consolidators of an hour, a day, and a week; a similar group called the decimalminutes consolidator group can be added (figure 10.16), consisting of consolidators of 1min, 10min, 100min, 1000min, 10000min:
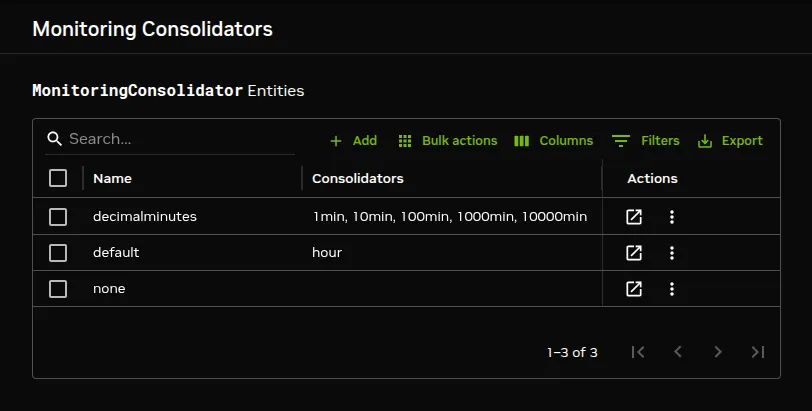
Figure 10.16: Base View Monitoring Configuration Consolidators: decimalminutes Consolidator Group
Each consolidator can be created and given appropriate definitions for the intervals and other properties (figure 10.17):
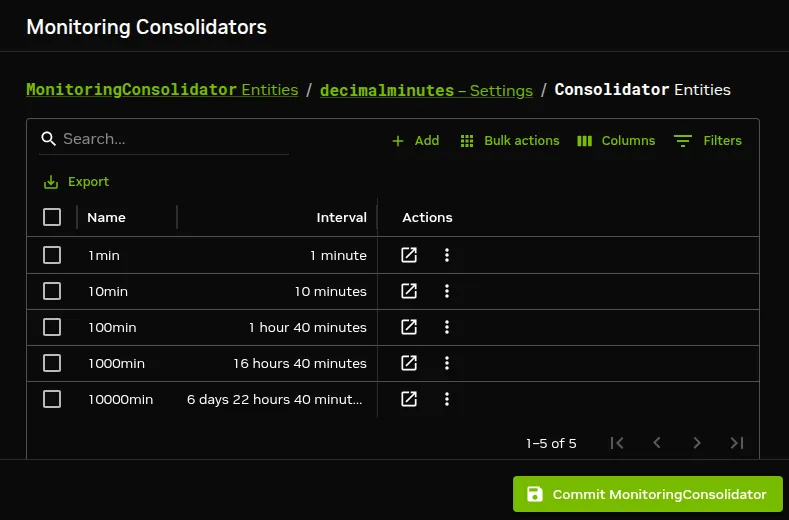
Figure 10.17: Base View Monitoring Configuration Consolidators: decimalminutes Consolidator Definitions
For the record, values for the decimalminutes consolidators that make sense could be as follows:
The values in the table are examples of settings of consolidator items. The settings of consolidator items are discussed next.
10.4.3.5 Consolidator Item Settings
Consolidator items (consolidator components) are the component members of the consolidator groups. The items have settings as properties, which can be managed (figure 10.18).
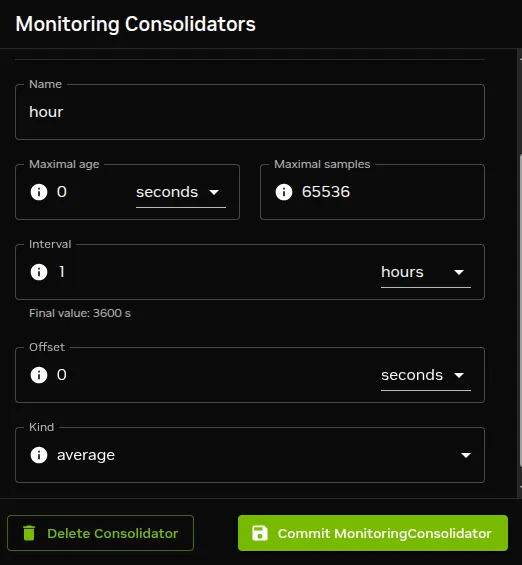
Figure 10.18: Base View Monitoring Configuration Consolidators: Consolidator Item Settings
The consolidator item hour, which is within the default consolidators group, can have its properties edited using the navigation path:
Monitoring > Consolidators[default] > Consolidators > hour
The properties that can be set for a consolidator item are:
-
Name: The name of the consolidator item. By default, for the consolidator groupdefault, the consolidator itemhouris already set up, with an interval of 1 hour, and no limit on the maximum number of samples. -
Maximal samples: The maximum number of samples that are stored for that consolidator item. This should not be confused with theMaximal samplesof the measurable being consolidated. -
Interval: The time period (in seconds) covered by the consolidator sample. For example, the consolidator with the namehourhas a value of 1 hour (3600s). The property should not be confused with the time period between samples of the measurable being consolidated. -
Offset: The time offset from the default consolidation time, explained in more detail shortly. -
Kind: The kind of consolidation that is done on the raw data samples. The value ofkindis set toaverageby default. The output result for a processed set of raw data—the consolidated data point—is an average, a maximum or a minimum of the input raw data values.Kindcan thus have the valueaverage,maximum, orminimum. The value ofkindis set toaverageby default.For a given consolidator, when one
Kindis changed to another, the historically processed data values become inconsistent with the newer data values being consolidated. Previous consolidated data values for that consolidator are therefore discarded during such a change.
To understand what Offset means, the Maximal samples of the measurable being consolidated can be considered. This is the maximum number of raw data points that the measurable stores. When this maximum is reached, the oldest data point is removed from the measurable data when a new data point is added. Each removed data point is gathered and used for data consolidation purposes.
For a measurable that adds a new data point every Interval seconds, the time t_rawgone, which is how many seconds into the past the raw data point is removed, is given by:
t_rawgone=(Maximalsamples)_measurable× (Interval)_measurable
This value is also the default consolidation time, because the consolidated data values are normally presented from t_rawgone seconds ago, to further into the past. The default consolidation time occurs when the Offset has its default, zero value.
If however the Offset period is non-zero, then the consolidation time is offset, because the time into the past from which consolidation is presented to the user, t_consolidation, is then given by:
t_consolidation=t_rawgone + Offset
The monitoring visualization graphs then show consolidated data from t_consolidation seconds into the past, to further into the past.
NOTE: For completeness: the time t_consolidationgone, which is how many seconds into the past the consolidated data goes and is viewable, is given by an analogous equation to that of the equation defining t_rawgone:
t_consolidationgone=(Maximal samples)_consolidation× (Interval)_consolidation
10.4.4 Monitoring Configuration: Actions
Actions are introduced in section 10.2.6, and are available in Base View with the navigation path Monitoring > Actions. The Actions window (figure 10.19) displays actions that BCM provides by default, and also displays any custom actions that have been created:
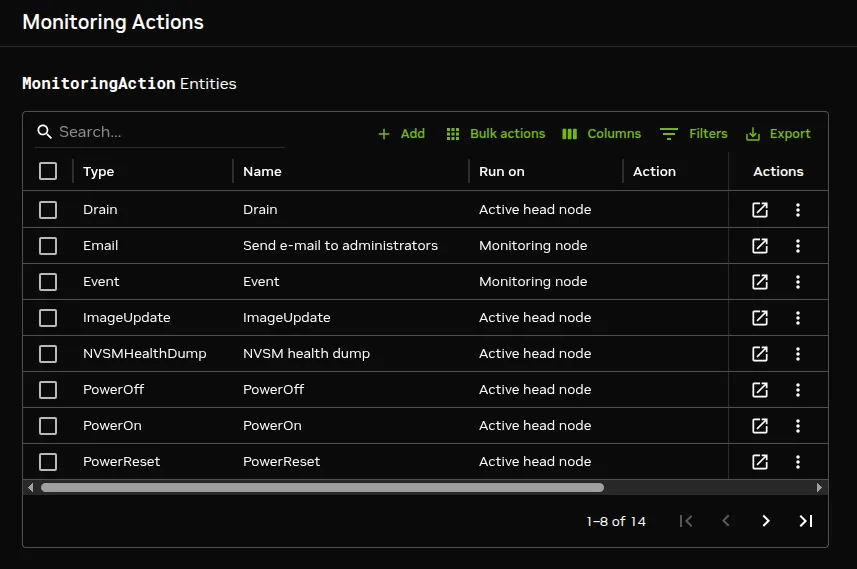
Figure 10.19: Base View Monitoring Configuration: Actions
The custom killallyes script from the basic example of section 10.1 would show up here if it has been implemented.
Actions are triggered, by triggers (section 10.4.5).
By default, the following actions exist:
-
PowerOn: Powers on the node -
PowerOff: Powers off the node -
PowerReset: Hard resets the node -
Drain: Drains the node (does not allow new jobs on that node) -
Undrain: Undrains the node (allows new jobs on that node) -
Reboot: Reboots node via the operating system -
Shutdown: Shuts the node down via the operating system -
ImageUpdate: Updates the node from the software image -
NVSMHealthDump: NVSM (section 10.13) health dump (for DGX hardware only) -
Event: Sends an event to users connected withcmshor Base View -
killprocess: A script to kill a process -
remount: A script to remount all devices -
testaction: A test script -
Send e-mail to administrators: Sends an e-mail out
The preceding actions show their options when the associated ↗ icon is clicked. A new window with the options opens up. The following options are among those then displayed:
-
Run on: What nodes the action should run on. Choices are:-
Active head node: the action runs on the active node only -
Node: the action runs on the triggering node -
Monitoring node: the action runs on the monitoring node
-
-
Allowed time: The time interval in the 24 hour clock cycle that the action is allowed to start running. The interval can be restricted further to run within certain days of the week, months of the year, or dates of the month. Days and months must be specified in lower case.The Base View interface for setting the time can be used to set the allowed times.
The allowed times have a format that is also used in
cmsh. Rather than defining a formal syntax, somecmshexamples are given of possible formats, with explanations:-
november-march: November to March. The months April to October are forbidden. -
november-march{monday-saturday}: As in the preceding, but all Sundays are also forbidden. -
november-march{monday-saturday{13:00-17:00}}: Restricted to the period defined in the preceding example, and with the additional restriction that the action can start running only during the time 13:00-17:00. -
09:00-17:00: All year long, but during 09:00-17:00 only. -
monday-friday{9:00-17:00}: All year long, but during 9:00-17:00 only, and not on Saturdays or Sundays. -
november-march{monday-saturday{13:00-17:00}}: Not in April to October. In the other months, only on Mondays to Saturdays, from 13:00-17:00. -
may-september{monday-friday{09:00-18:00};saturday-sunday{13:00-17:00}}: May to September, with: Monday to Friday 09:00-18:00, and Saturday to Sunday 13:00-17:00. -
may{1-31}: All of May. -
may,september{1-15}: All of May, and only September 1-15. -
may,september{1-15{monday-friday}}: All of May. And only September 1-15 Monday to Friday.
An EBNF grammar for allowed times is given in section 3.2.1 of the Developer Manual.
-
The following action scripts have some additional options:
-
Send e-mail to administrators: Additional options here are:-
Info: body of text inserted into the default e-mail message text. This is the text that replaces the{infomessage}placeholders in the email template formats seen in the file/cm/local/apps/cmd/scripts/actions/sendemail.py -
Recipients: a list of recipients -
All administrators: uses the list of users in theAdministrator e-mailsetting inpartition[base]mode
-
-
killprocess, andtestaction: Additional options for these are:-
Arguments: text that can be used by the script. -
Script: The location of the script on the file system.
-
10.4.5 Monitoring Configuration: Triggers
Triggers are introduced in section 10.2.5. The Triggers window (figure 10.20) allows actions (section 10.2.6) to be triggered based on conditions defined by the cluster administrator.
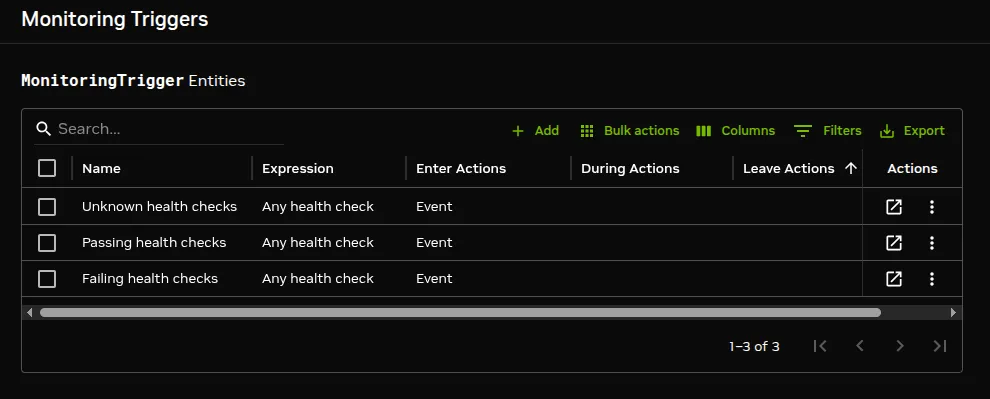
Figure 10.20: Base View Monitoring Configuration: Triggers
10.4.5.1 Change Detection For Triggers
Triggers launch actions by detecting changes in the data of configured measurables. The detection of these changes can happen:
-
When a threshold is crossed. That is:
-
either the preceding sample value was not in the zone, and the sample value now has entered the zone,
-
or the preceding sample value was in the zone, and the sample value now has left the zone
-
-
When the zone remains crossed. That is: the sample value now as well as the preceding sample value are both within the zone of a crossed threshold.
-
When state flapping is detected. This is when the threshold is crossed repeatedly (5 times by default) within a certain time period (5 minutes by default).
The monitoring configuration dialog triggers have four possible action launch configuration options to cover these cases:
-
Enter actions: if the sample has entered into the zone and the previous sample was not in the zone. This is a threshold-crossing change. -
Leave actions: if the sample has left the zone and the previous sample was in the zone. This is also a threshold-crossing change. -
During actions: if the sample is in the zone, and the previous sample was also in the zone. -
State flapping actions: if the sample is entering and leaving the zone within a particular period (State flapping period, 5 minutes by default) a set number of times (State flapping count, 5 by default).
10.4.5.2 Pre-defined Triggers: Passing, Failing, And Unknown Health Checks
By default, the only triggers that are pre-defined are the following three health check triggers, which use the Enter actions launch configuration option, and which have the following default behavior:
-
Failing health checks: If a health check fails, then on entering the state of the health check failing, an event is triggered as the action, and a severity of15is set for that health check. -
Passing health checks: If a health check passes, then on entering the state of the health check passing, an event is triggered as the action, and a severity of0is set for that health check. -
Unknown health checks: If a health check has an unknown response, then on entering the state of the health check returning an unknown response, an event is triggered as the action, and a severity of10is set for that health check.
Example: carry out a triggered action:
cmsh or Base View can be used for the configuration of carrying out an e-mail alert action (that is: sending out an e-mail) that is triggered by failing health checks.
-
A
cmshway to configure it is:The e-mail action (
send e-mail to administrators) is first configured so that the right recipients get a useful e-mail.Here, email alerts would go to
user1@example.com, as well as to anyone already configured inadministratore-mail. Additional text can be set in the body of the e-mail by setting a value forinfo.The trigger can be configured to run the action when the health check enters a state where its value is
true:The settings can be viewed with the
showcommand. TAB-completion prompting can be used to suggest possible values for the settings. -
A Base View way to carry out the configuration is using the navigation path:
Monitoring > Actions > Send e-mail to administratorsThis can be used to set the recipients and other items, and the configuration can then be saved.
The email action can then be configured in Base View using the navigation path:
Monitoring > Triggers > Failing Health Checks > ↗ > Enter Actions > Send E-mail to AdministratorsThe
Send E-mail to Administratorsaction should be added to the items in theEnter actionsbox (figure 10.21):
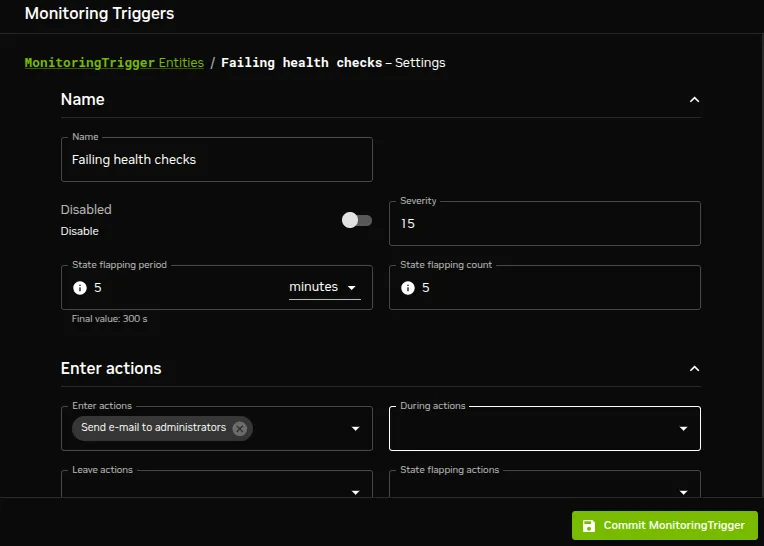
Figure 10.21: Base View Monitoring Configuration: Triggers
and this monitoring trigger configuration should then be committed.
10.4.5.3 Carrying Out Post-Drain Actions
A special, and hidden, setting for a triggered drain is post-drain-actions. This allows one or more actions to be triggered after a node has reached a fully-drained state after a drain action.
Example
In the preceding example, nodes that enter a drained state, after they are fully-drained, send an e-mail to the administrator and are powered off (here and section G.4.1).
The syntax of the post-drain action is:
set -e -v post-drain-actions <action name> [<action name> …]
10.4.5.4 Adding Custom Triggers: Any Measurable, Any Action
More triggers can be added. The killallyestrigger example from the basic example of section 10.1, seen in figures 10.3 and 10.4, is one such example.
The idea is that actions are launched from triggers, and the action for the trigger can be set to a predefined action, or to a custom action.
10.4.5.5 The Expression Subwindow For A Trigger
When editing a trigger as in figure 10.21 an Expression subwindow can be opened. For example, for the Failing health checks trigger, the Base View navigation path is:
The Expression subwindow allows parameters such as entity, measurable, parameters, (comparison) operator, and measurable value be set for a trigger (figure 10.22):
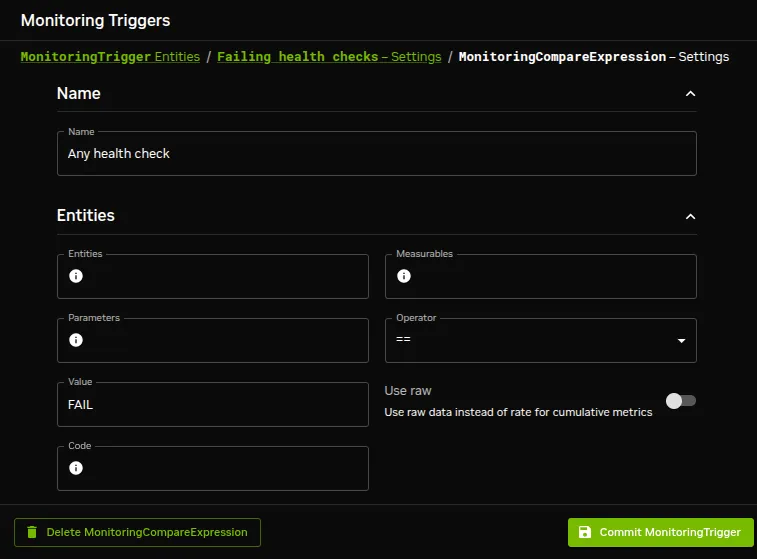
Figure 10.22: Base View Monitoring Configuration: Triggers Expression
The trigger launch is carried out when, during sampling, CMDaemon evaluates the expression as being true.
An example cmsh session to set up an expression for a custom trigger might be as follows, where the administrator is setting up the configuration so that an e-mail is sent by the monitoring system when a node is detected as having gone down:
Example
To add a touch of realism, a deliberate mistake is set here—the use of devicestate (the data producer) instead of devicestatus (the measurable). The validate command (here) gives a helpful warning here, so that the cluster administrator can fix the setting:
10.4.6 Monitoring Configuration: Health status
The Health status window (figure 10.23) displays all the nodes, and summarizes the results of all the health checks that have been run against them over time, by presenting a table of the associated severity levels (section 10.2.7):
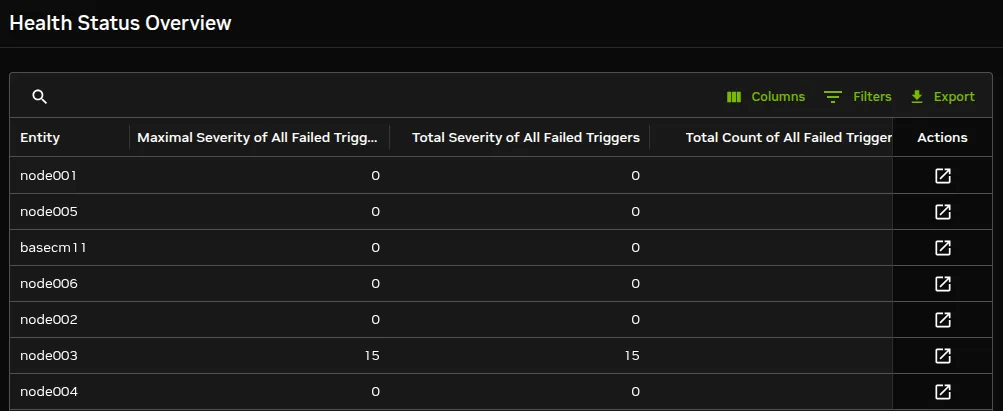
Figure 10.23: Base View Monitoring Configuration: Health Status
In the example shown in figure 10.23 the entity node003 shows a severity issue, while the other devices are fine. Details of the individual health checks per entity can be viewed by clicking on its associated ↗ icon, which opens up a subwindow (figure 10.24). For this example the issue turns out to be due to a Fail status in the ldap measurable.
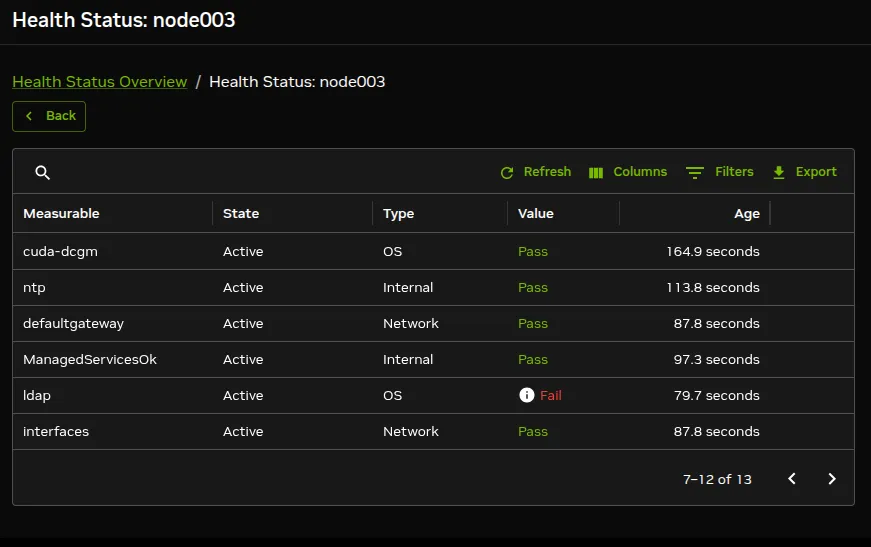
Figure 10.24: Base View Monitoring Configuration: Health Status For An Entity
10.4.7 Monitoring Configuration: All Health Checks
The All Health checks window (figure 10.25) shows all the running health checks for all entities.
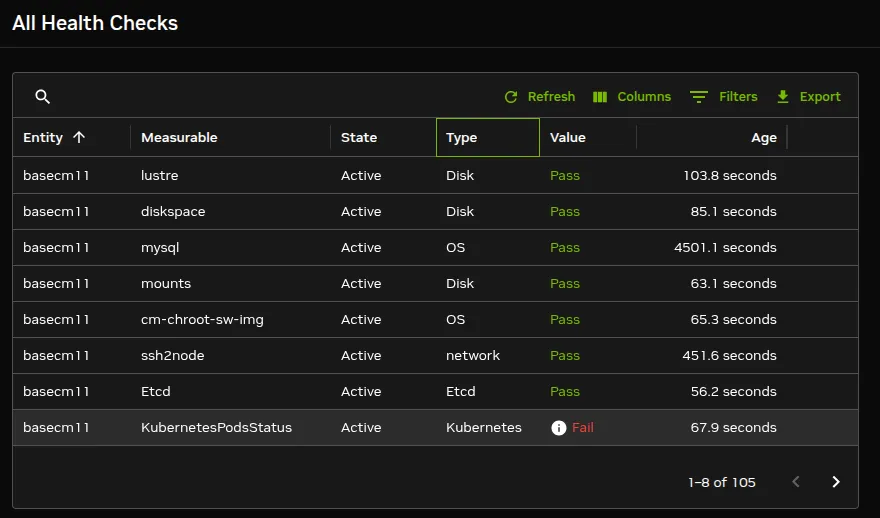
Figure 10.25: Base View Monitoring Configuration: All Health Checks For All Entities
The Filters option at the top of the table can be used to show the results per entity, measurable, state, or type only. If the entity filter is set to node003, which is as set in section 10.4.6, figure 10.24, then the results table looks similar to the table there.
10.4.8 Monitoring Configuration: Standalone Monitored Entities
The Standalone Monitored Entities window allows the cluster administrator to define a standalone entity. A standalone entity is one that is not managed by BCM—which means that no CMDaemon is running on it to gather data and for managing it—but the entity can still be monitored. For example, a workstation that is running the Base View browser could be the standalone entity. This could have its connectivity monitored by pinging it from the head node with a custom script.
10.4.9 Monitoring Configuration: PromQL Queries
The Prometheus Query list window displays the list of PromQL job-related queries, and allows query properties to be edited.
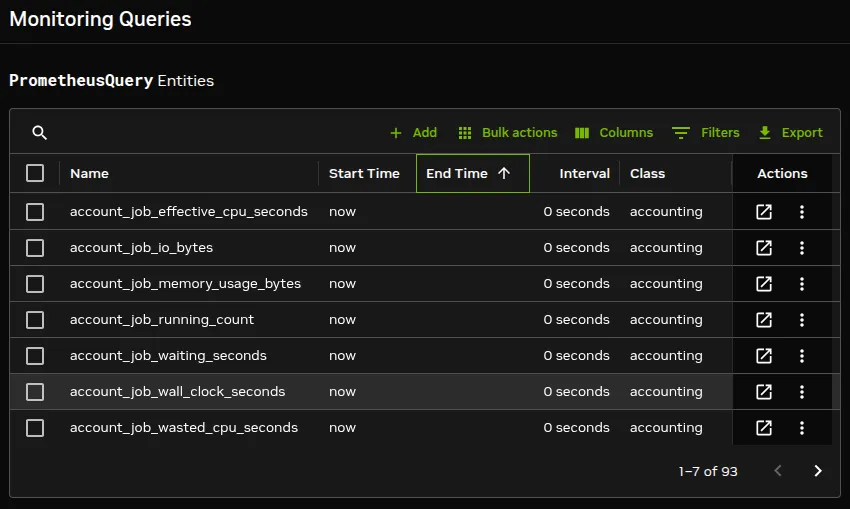
Figure 10.26: Base View Monitoring Configuration: PromQL Queries
Drilldowns can also be viewed using the Base View navigation path:
Monitoring > Queries > specific Prometheus query > Manage the drilldown queries
PromQL job queries are discussed further in section 12.3.
10.5 The monitoring Mode Of cmsh
This section covers how to use cmsh to configure monitoring. The monitoring mode in cmsh corresponds generally to the Monitoring resource of Base View in section 10.4. Similarly to how monitoring subwindows are accessed in Base View, the monitoring mode of cmsh is itself is not used directly, except as a way to access the monitoring configuration submodes of cmsh.
For this section some familiarity is assumed with handling of objects as described in the introduction to working with objects (section 2.5.3). When using cmsh’s monitoring mode, the properties of objects in the submodes are how monitoring settings are carried out.
The monitoring mode of cmsh gives access to 9 modes under it:
Example
For convenience, a tree of modes for monitoring submodes is shown in figure 10.27.
monitoring
├── action (section 10.5.1)
├── consolidator (section 10.5.2)
│ └── consolidators (here)
├── labeledentity (section 12.2)
├── measurable (section 10.5.3)
├── query (section 12.3)
│ └── drilldown
├── report
├── setup (section 10.5.4)
│ ├── executionmultiplexers (here)
│ ├── jobmetricsettings (here)
│ ├── nodeexecutionfilters (here)
│ └── dpusettings
├── standalone (section 10.5.5)
└── trigger (section 10.5.6)
└── expression (here)
Figure 10.27: Submodes Under monitoring Mode
Sections 10.5.1–10.5.6 give examples of how objects are handled under these monitoring modes. To avoid repeating similar descriptions, section 10.5.1 is relatively detailed, and is often referred to by the other sections.
10.5.1 The action Submode
The action submode under the monitoring mode of cmsh allows monitoring actions to be configured. This mode in cmsh corresponds to the Base View navigation path:
Monitoring > Actions
described earlier in section 10.4.4:
The action mode handles action objects in the way described in the introduction to working with objects (section 2.5.3). A typical reason to handle action objects—the properties associated with an action script or action built-in—might be to view the actions available, or to add a custom action for use by, for example, a metric or health check.
Some examples of how the action mode is used are now given.
10.5.1.1 The action Submode: list, show, And get
The list command by default lists the names and properties of actions available from action mode in a table:
Example
The preceding shows the actions available on a newly-installed system.
Instead of using list, a convenient way to view the possible actions is to use the show command with tab-completion suggestions:
Example
The show command of cmsh when used with a specific action displays the individual parameters and values of that action:
Example
The get command returns the value of an individual parameter of the action object:
Example
10.5.1.2 The action Submode: add, use, remove, commit, refresh, modified, set, clear, And validate
In the basic example of section 10.1, in section 10.1.2, the killallyes action was cloned from a similar script using a clone option in Base View.
The equivalent can be done with a clone command in cmsh. However, using the add command instead, while it requires more steps, makes it clearer what is going on. This section therefore covers adding the killallyes script of section 10.1.2 using the add command.
When add is used: an object is added, the object is made the current object, and the name of the object is set, all at the same time. After that, set can be used to set values for the parameters within the object, such as a path for the value of the parameter command.
Adding an action requires that the type of action be defined. Just as tab-completion with show comes up with action suggestions, in the same way, using tab-completion with add comes up with type suggestions.
Running the command help add in the action mode also lists the possible types. These types are drain, e-mail, event, imageupdate, nvsmhealthdump, poweroff, poweron, powerreset, reboot, script, servicerestart, servicestart, servicestop, shutdown, undrain.
The syntax for the add command takes the form:
add <type> <action>
If there is no killallyes action already, then the name is added in the action mode with the add command, and the script type, as follows:
Example
Using the add command drops the administrator into the killallyes object level, where its properties can be set. A successful commit means that the action is stored in CMDaemon.
The converse to the add command is the remove command, which removes an action that has had the commit command successfully run on it.
The refresh command can be run from outside the object level, and it removes the action if it has not yet been committed.
The use command is the usual way of “using” an object, where “using” means that the object being used is referred to by default by any command run. So if the killallyes object already exists, then use killallyes drops into the context of an already existing object (i.e. it “uses” the object).
The set command sets the value of each individual parameter displayed by a show command for that action. The individual parameter script can thus be set to the path of the killallyes script:
Example
The clear command can be used to clear the value that has been set for script.
The validate command checks if the object has all required values set to sensible values. So, for example, commit only succeeds if the killallyes object passes validation.
Validation does not check if the script itself exists. It only does a sanity check on the values of the parameters of the object, which is another matter. If the killallyes script does not yet exist in the location given by the parameter, it can be created as suggested in the basic example of section 10.1, in section 10.1.2. In the basic example used in this chapter, the script is run only on the head node. If it were to run on regular nodes, then the script should be copied into the disk image.
The modified command lists changes that have not yet been committed.
10.5.2 The consolidator Submode
Consolidators are introduced in section 10.4.3. Consolidators can be managed in cmsh via the consolidator mode, which is the equivalent of the consolidators window (section 10.4.3) in Base View.
The consolidator mode deals with groups of consolidators. One such pre-defined group is default, while the other is none, as discussed earlier in section 10.4.3:
Each consolidators entry can have its parameters accessed and adjusted.
For example, the parameters can be viewed with:
Example
For the hour consolidator shown in the preceding example, the number of samples saved per hour can be doubled with:
Example
The value of Period is the time for which the samples are kept. Samples older than this are dropped. The rules that are applied to decide how samples are kept are described starting here.
Previously consolidated data is discarded with this type of change, if the number of samples is reduced. Changing parameters should therefore be done with some care.
A new consolidators group can be created if needed.
A Base View way, where a decimalminutes group is created, is discussed in the example in section 10.4.3, here.
A cmsh way, where a max-per-day group is created, is discussed in the following section:
10.5.2.1 Creation Of A Consolidator In cmsh
A new consolidator group, max-per-day, can be added to the default consolidator groups of default and none, with:
Example
Within this new group, a new consolidator item, max-per-day can also be defined. The item can be defined so that it only calculates the maximum value per day. The maximum value option is set using the kind setting, and the per day option is set using the interval setting, since that is the interval with which the old data is consolidated:
Example
The max-per-day consolidator data values are kept for about 180 years.
10.5.3 The measurable Submode
The measurable submode under the monitoring mode of cmsh handles measurable objects, that is: metrics, health checks, and enummetrics. This mode corresponds to the Base View navigation path:
Monitoring > Measurables
covered earlier in section 10.4.2.
Measurable objects represent the configuration of scripts or built-ins. The properties of the objects are handled in cmsh in the way described in the introduction to working with objects (section 2.5.3).
A typical reason to handle measurable objects might be to view the measurables already available, or to remove a measurable that is in use by an entity.
Measurables cannot be added from this mode. To add a measurable, its associated data producer must be added from monitoring setup mode (section 10.5.4).
This section goes through a cmsh session giving some examples of how this mode is used.
10.5.3.1 The measurable Submode: list, show, And get
In measurable mode, the list command by default lists the names of all measurable objects along with parameters, their class, and data producer.
Example
The preceding example shows excerpts from a list of the measurables that can be set for sampling on a newly-installed system. A full list typically contains over 300 items.
The list command in measurable submode can be run as:
-
list metric: to display only metrics -
list healthcheck: to display only health checks -
list enum: to display only enummetrics
The show command of the measurable submode of monitoring mode displays the parameters and values of a specified measurable, such as, for example CPUUser, DeviceStatus, or diskspace:
Example
The Gap setting here is a number. It sets how many samples are allowed to be missed before a value of NaN is set for the value of the metric.
As detailed in section 10.5.1, tab-completion suggestions for the show command suggest the names of objects that can be used, with the use command in this mode. For show in measurable mode, tab-completion suggests over 300 possible objects:
Example
The single colon (“:”) indicates an extra parameter for that measurable.
Grepping a metrics list: is sometimes handy because there are a large number of metrics. When listing and grepping, it is usually a good idea to allow for case, and be aware of the existence of the parameter column. For example, the AlertLevel metric is displayed as AlertLevel in the tab-completion suggestions of the show command of the previous example, and in the output of the list command. The has command (explained shortly) tab-completion suggests alertlevel in lowercase. There are also several parameters associated with the AlertLevel command. So using the case-insensitive -i option of grep, and using the head command to display the headers is handy:
Example
The get command returns the value of an individual parameter of a particular health check object:
Example
10.5.3.2 The measurable Submode: The has Command
The has command is used with a measurable to list the entities that use the measurable. Typically these are nodes, but it can also be other entities, such as the base partition, or a rack.
Example
The remaining commands in measurable mode, such as use, remove, commit, refresh, modified, set, clear, and validate; all work as outlined in the introduction to working with objects (section 2.5.3). More detailed usage examples of these commands within a monitoring mode are given in the earlier section covering the action submode (section 10.5.1).
10.5.3.3 The measurable Submode: An Example Session On Viewing And Configuring A Measurable
A typical reason to look at metrics and health check objects—the properties associated with the script or built-in—might be, for example, to view the operating sampling configuration for an entity.
This section goes through a cmsh example session under monitoring mode, where the setup submode (here) is used to set up a health check. The healthcheck can then be viewed from the measurable submode.
In the basic example of section 10.1, a trigger was set up from Base View to check if the CPUUser metric was above 50 jiffies/s, and if so, to launch an action.
A functionally equivalent task can be set up by creating and configuring a health check, because metrics and health checks are so similar in concept. This is done here to illustrate how cmsh can be used to do something similar to what was done with Base View in the basic example. A start is made on the task by creating a health check data producer, and configuring its measurable properties. using the setup mode under the monitoring mode of cmsh. The task is completed in the section on the setup mode in section 10.5.4.
To start the task, cmsh’s add command is used, and the type is specified, to create the new object:
Example
The show command shows the parameters.
The values for description, runinbash, script, and class should be set:
Example
On running commit, the data producer cpucheck is created:
Example
The measurable cpucheck, is also created:
Example
Since the cpucheck script does not yet exist in the location given by the parameter script, it needs to be created. One ugly bash script that can do a health check is:
The script should be placed in the location suggested by the object, /cm/local/apps/cmd/scripts/healthchecks/cpucheck, and made executable with a chmod 700.
The cpucheck object is handled further within the cmsh monitoring setup mode in section 10.5.4 to produce a fully-configured health check.
10.5.4 The setup Submode
10.5.4.1 The setup Submode: Introduction
The setup submode under the monitoring mode of cmsh allows access to all the data producers. This mode in cmsh corresponds to the Base View navigation path:
Monitoring > Data Producers
covered earlier in section 10.4.1.
10.5.4.2 The setup Submode: Data Producers And Their Associated Measurables
The list of data producers in setup mode should not be confused with the list of measurables in measurable mode. Data producers are not the same as measurables. Data producers produce measurables, although it is true that the measurables are often named the same as, or similar to, their data producer.
In cmsh, data producers are in the Name (key) column when the list command is run from the setup submode:
Example
In the preceding example, the AlertLevel data producer has 3 showing at the start of the measurables column. This means that this AlertLevel data producer provides 3 measurables.
If the data producer is disabled, then the measurables are disabled and no sampling is carried out for those measurables.
Measurables must exist in the data producer object—that is, the value in the the Measurables column must be more than 0—and the measurable must also be enabled to allow data sampling and collection to take place. If a measurable exists, then rules—set by node execution filters (here) and execution multiplexers (here)—determine where the data sampling is carried out and where collection happens.
To clarify this point: if the list command is run from setup mode to list data producers, then the producers that have configured measurables are the ones that have 1 or more as a value in the Measurables column. Conversely, the data producers with 0 in the Measurables column have no configured measurables, whether enabled or disabled, which means that the measurables are effectively just placeholders until the software for the measurables data producers is installed.
The list of measurables can be viewed in setup mode and measurable mode. For example, the three AlertLevel measurables produced by the AlertLevel producer can be seen in the modes with:
Example
Similarly, the non-existence of the CPUSampler measurable can be viewed in setup mode and measurable modes with:
Example
10.5.4.3 The setup Submode: Listing Nodes That Use A Data Producer
The nodes command can be used to list the nodes on which a data producer <data producer> runs. It is run in the setup submode level of the monitoring mode as:
nodes <data producer>
Example
10.5.4.4 The setup Submode: Data Producers Properties
Any data producer from the full list in setup mode can, if suitable, be used to provide a measurable for any entity.
An example is the data producer AlertLevel. Its properties can be seen using the show command:
Example
These properties are described in section 10.4.1. Most of these properties are inherited by the measurables associated with the data producer, which in the AlertLevel data producer case are alertlevel:count, alertlevel:maximum, and alertlevel:sum.
10.5.4.5 The setup Submode: Deeper Submodes
One level under the setup submode of monitoring mode are 4 further submodes (modes deeper than submodes are normally also just called submodes for convenience, rather than sub-submodes):
-
nodeexecutionfilters -
executionmultiplexers -
jobmetricsettings -
dpusettings
Node execution filters: A way to filter execution (restrict execution) of the data producer.
If no node execution filter is set for that data producer, then the data producer runs on all nodes of the cluster. Filters can be of the type:
-
category -
lua -
node -
overlay -
resource -
type
The type is set when the filter is created.
-
The
nodescommand for listing the execution nodesRunning the
nodescommand for a data producer lists which nodes the execution of the data producer is run on.Example
Most of the default data producers that are used by the cluster run on an active head node, and often on the regular nodes.
-
nodexecutionfiltersto restrict data producer executionThe
rogueprocess(here) data producer is one of the few that by default runs on a regular node. Restricting a data producer to run on a particular list of nodes can be carried out as follows on a cluster that is originally in its default state:Example
This way, the
rogueprocesshealth check runs on just those nodes (node001,node002), and none of the others. -
Restricting a data producer execution to the head node—monitoring a process on the head node
Another example of data producer restriction is as follows: an administrator may wish to monitor the
slapdprocess on the head nodes. Incmsh, this can be achieved by creating a new data producer,slapdof typeprocpidstat.and other properties as parameters to the measurables of the
procpidstatdata producer, as in the following session:Example
Defining
slapdas the process name for the data producer means that the followingprocpidstatmeasurables become defined:Example
The
nodeexecutionfilterssettings can be set for theslapddata producer as follows:-
One way to set it might be:
Example
-
Alternatively, in
nodeexecutionfiltersmode, the type that can be added is one of the names reserved for a node type (Head node,Cloud nodeLite node,DPU node) which automatically sets thetypeparameter to the value oftype, and sets node type to the reserved name.:
Example
The filter now works on all head nodes. To have it work on only the active head node, the
activecommand can be used instead, atnodeexecutionfiltermode level:Example
The newly-defined
slapdparameter metrics can now have its output displayed or plotted just like any other metric:Example
-
-
Filtering a data producer by resource
A data producer can also be set up so that it is run on a particular list of nodes filtered by resource. The resources that are available to a node can be viewed using the command
monitoringresourcesfor that device:Example
An example of where running a node execution filter by resource is useful, is for data producers that are intended to run on the active head node. Most data producers that are used by the cluster run on an active head node (besides often running on the regular nodes too).
Thus, for example, the
cpucheckhealth check from here can be set to run on the active head node, by creating an arbitrary resource calledmyactive:Example
and then setting the
Resourcesparameter toActive:The
cpucheckhealth check then runs on the active head node, whichever head node it is.
When node execution filtering is carried out, the filtered data is not dropped by default. Filtered data can be dropped for a measurable or an entity with the monitoringdrop command (section 10.6.8).
Execution multiplexer: A way to multiplex execution (have execution work elsewhere) for a data producer. The object tells BCM about the entities that the data producer is executing sampling at. Thus:
-
For a node execution filter, as explained earlier here, a data producer runs and gathers data at the entity which is defined by the node execution filter. The entity can be of type:
-
category -
lua -
node -
overlay -
resource -
type
-
-
For an execution multiplexer, a data producer gathers samples from other entities. The entities are defined into groups called execution multiplexers, and can be of type:
-
category -
dynamic(an extra type not innodeexecutionfilters) -
lua -
node -
overlay -
resource -
type
Execution multiplexers can thus be
categorymultiplexers,dynamicmultiplexers, and so on. -
The executionmultiplexers mode can be entered for a data producer dmesg with:
Example
Running the commands: help add, or help set, can be used to show the valid syntax in this submode.
Most data producers run on a head node, but sample from the regular nodes. So, for example, the dmesg health check from Appendix G.2.1 can be set to sample from the regular nodes by setting it to carry out execution multiplexing to specified node entities using a node multiplexer with the arbitrary name of nodes as follows:
Example
If the type is not set to a particular type, then the type parameter is set to type and a types field becomes available. In that case, if the name is then also set to a value that is a type from the reserved list of monitoring types, then the types parameter is automatically populated by that value.
Example
The reserved list of monitoring types that can be used in the name field to automatically populate the types can be found by running the device monitoringtypes -a command:
Example
or by viewing the error message when setting a value for types incorrectly:
Example
The concepts and expected behavior of node execution filters and execution multiplexers are covered in more explicit detail in Appendix L.
Job metrics settings: Job metrics settings are a submode for setting job metric collection options for the JobSampler data producer (section 11.4).
10.5.5 The standalone Submode
The standalone submode under the monitoring mode of cmsh allows entities that are not managed by BCM to be configured for monitoring. This mode in cmsh corresponds to the Base View navigation path:
Monitoring > Standalone Monitored Entities
covered earlier in section 10.4.8.
The monitoring for such entities has to avoid relying on a CMDaemon that is running on the entity. An example might be a chassis that is monitored via a ping script running on the BCM head node.
10.5.6 The trigger Submode
The trigger submode under the monitoring mode of cmsh allows actions to be configured according to the result of a measurable.
This mode in cmsh corresponds to the Base View navigation path:
Monitoring > Triggers
covered earlier in section 10.4.5.
By default, there are 3 triggers:
Example
Thus, for a passing, failing, or unknown health check, an event action takes place if entering a state change. The default severity level of a passing health check does not affect the AlertLevel value. However, if the failing or unknown health checks are triggered on entering a state change, then these will affect the AlertLevel value.
10.5.6.1 The trigger Submode: Setting An Expression
In the basic example of section 10.1, a trigger to run the killallyes script was configured using Base View.
The expression that was set for the killallyes script in the basic example using Base View can also be set in cmsh. For example:
Example
The expression format is shown in cmsh as:
(<entity>, <measurable>, <parameter>) <comparison operator> <value>
Here:
-
an entity, as described in section 10.2.1.3, can be, for example, a node, category, device, or software image. To include more than one entity for the comparison, the alternation (pipe, |) symbol can be used, with double quotes to enclose the expression.
Example
In the preceding example, the entity
computecould be a category, and the entitygpuimagecould be a software image. -
a measurable (section 10.2.1) can be a health check, a metric, or an enummetric. For example:
CPUUsage. Alternation works for <measurable> in a similar way to that for <entity>. -
a parameter is a further option to a measurable. For example, the
FreeSpacemetric can take a mount point as a parameter. Alternation works for <parameter> in a similar way to that for <entity>. -
the comparison operator can be:
-
EQ: equivalent to, displayed as== -
NE: not equivalent to, displayed as!= -
GT: greater than, displayed as> -
LT: less than, displayed as<
If the user uses an arithmetic symbol such as
>incmshas an unescaped entry, then the entry may unintentionally be interpreted by the shell. That is why the two-letter entries are recommended instead for entry, even though when displayed they display as the arithmetic symbols for easier recognition. -
-
the value can be a string, or a number.
The regex evaluates to TRUE or FALSE. The trigger runs its associated action in the case of TRUE.
The wildcard * implies any entity, measurable, or parameter when used with the appropriate position according to the syntax of the expression format.
Using .* is also possible to match zero or more of any characters.
Some further expression matching examples:
Example
True for any failing health check:
Example
True for any nearly full local disk (less than 10MB left):
Example
True for any cloud node that is too expensive (price more than more than 10$):
Example
Excluding node agw001:
Example
True for any node in the data, gpu, or hpc categories, that has a nearly full local disk (less than 10MB left):
The unusual syntax in the preceding example is liable to change in future versions.
At the end of section 10.5.3 a script called cpucheck was built. This script was part of a task to use health checks instead of metrics to set up the functional equivalent of the behavior of the basic example of section 10.1. In this section the task is continued and completed as follows:
10.6 Obtaining Monitoring Data Values
The monitoring data values that are logged by devices can be used to generate graphs using the methods in section 10.3. However, sometimes an administrator would like to have the data values that generate the graphs instead, perhaps to import them into a spreadsheet for further direct manipulation, or to pipe them into a utility such as gnuplot.
10.6.1 Getting The List Of Measurables For An Entity: The measurables, metrics, healthchecks And enummetrics Commands
The measurables for a specified entity can be seen with the measurables command, and the measurable subtypes can be seen with the corresponding measurable subset commands: metrics, healthchecks and enummetrics. The results look quite similar to the results of the measurable submode of the monitoring mode (section 10.5.3). However, for entities, the measurables are a sublist of the full number of measurables listed in the measurable submode, which in turn are only the list of measurables for the data producers that have been enabled.
For example, within device mode where the entities are typically the head node and regular nodes, running metrics with a specified entity shows only the metrics that are configured for that entity. Thus if the entity is a head node, then only head node metrics are shown; and if the entity is a regular node, only regular node metrics are shown:
Example
Typically the number of metrics listed on the head node will differ from those listed on a regular node. Whatever each number is, it cannot be more than the number of metrics seen in the number of metrics listed in the measurable submode of section 10.5.3.
The preceding example shows the measurables listing commands being carried out on head nodes and regular nodes. These commands can be used on other entities too. For example, the base partition in partition mode, where the measurables can be listed with:
Example
The values for metric samples and health checks can be obtained from within device mode in various ways, and are explained next.
10.6.2 On-demand Metric Sampling And Health Checks
10.6.2.1 The samplenow Command For On-Demand Measurable Samples
An administrator can do live sampling, or sampling on-demand, for specified entities by using the samplenow command. The command has the following syntax:
The command can be run without options when an entity object, such as a node is used (output truncated):
Example
The entity used can also be in other modes that have measurables, such as the base partition (output truncated):
Example
10.6.2.2 The -n|--nodes Option
The -n option in device mode allows specified nodes or node ranges:
Example
10.6.2.3 The --metrics And --checks Option
For a particular entity:
-
All metrics can be sampled on demand with the
--metricsoption -
All health checks can be sampled on demand with the
--checksoption
Example
10.6.2.4 The --debug Option
The --debug option passes CMD_DEBUG=1 to the script environment. This can be used to provide extra information on what is happening during sampling.
Example
Many scripts under /cm/local/apps/cmd/scripts/ can have their debug output inspected with samplenow --debug.
A recursive grep on the head node, similar to the following, should show which scripts have a settable debug environment:
10.6.2.5 The -s|--status Option
Nodes in device mode which have a status of UP, as seen by the status command, can be sampled with the -s|--status option:
Example
The preceding example is truncated because it is quite lengthy. However, on the screen, for the device mode, it shows all the sample values for the measurables for all the entities—head node and regular nodes—that are up.
To restrict the results to node001 only, it can be run as:
Example
Sampling according to a device status value other than UP is also possible.
The help text for the samplenow command gives further details on its possible options.
The latestmetricdata and latesthealthdata commands (section 10.6.3.1) display the results from the latest metric and health samples that have been gathered by the cluster, rather than sampling on demand.
The dumpmonitoringdata command (section 10.6.4) displays monitoring data gathered over a period of time in a variety of formats.
10.6.3 The Latest Data And Counter Values—The latest*data And latestmetriccounters Commands
Within device mode, the values obtained by the latest measurable sampling run can be displayed for a specified entity with the latestmonitoringdata, latestmetricdata and latesthealthdata commands:
-
latestmetricdata: Thelatestmetricdatacommand for a specified entity displays the most recent metric value that has been obtained by the monitoring system for each metric used by the entity. For displaying metrics on-demand incmsh, thesamplenow --metricscommand (here) can be used for a specified entity. -
latesthealthdata: Thelatesthealthdatacommand for a specified entity displays the most recent value that has been obtained by the monitoring system for each health check used by the entity. For displaying health check responses on demand incmsh, thesamplenow --checkscommand (here) can be used for a specified entity. -
latestmonitoringdata: Thelatestmonitoringdatacommand for a specified entity combines the output of thelatesthealthdataandlatestmetricdatacommands, i.e. it displays the latest samples of the measurables for that entity. For displaying measurables on-demand incmsh, thesamplenowcommand (here) can be run without options, for a specified entity.
The latestmetriccounters command, on the other hand, displays the latest cumulative counter values of the cumulative metrics in use by the entity.
10.6.3.1 Using The latest*data Commands
When using the latest*data commands, the entity must be specified (some output elided):
Example
Valid entity grouping options and other options can be seen in the help text for the latestmetricdata and latesthealthdata commands.
Example
The commands are mode-sensitive. That means, for example for a nodegroup consisting of, for example, node001 and node002, that there is a difference in the entities that are displayed from device mode:
Example
and the entities that are displayed, for example, in nodegroup mode:
Example
The metrics displayed in device mode are individual device metrics, while the metrics displayed in nodegroup mode are totalling metrics.
By default the data values are shown with human-friendly units. The --raw option displays the data values as raw units.
10.6.3.2 Using The latestmetriccounter Command
The latestmetriccounter is quite similar to the latestmetricdata command, except that it displays only cumulative metrics, and displays their accumulated counts since boot. The latestmonitoringcounter command is an alias for this command.
Example
The reader can compare the preceding example output against the example output of the latestmetricdata command (here) to become familiar with the meaning of cumulative output.
10.6.4 Data Values Over A Period—The dumpmonitoringdata Command
The dumpmonitoringdata command displays monitoring data values over a specified period. This is for an entity, such as:
-
a node in
devicemode -
the
basepartition inpartitionmode -
an image in
softwareimagemode -
a job in the
jobssubmode. Thejobssubmode is under the pathcmsh>wlm[<workload manager>]>jobs, and usingdumpmonitoringdatawith it is covered here.
10.6.4.1 Using The dumpmonitoringdata Command
A concise overview of the dumpmonitoringdata command can be displayed by typing in “help dumpmonitoringdata” in a cmsh mode that has entities.
The usage of the dumpmonitoringdata command consists of the following options and mandatory arguments:
dumpmonitoringdata [OPTIONS] <start-time> <end-time> <measurable> [entity]
The mandatory arguments: The mandatory arguments for the times, the measurables being dumped, and the entities being sampled, have values that are specified as follows:
-
The measurable <measurable> for which the data values are being gathered must always be given. Measurables currently in use can conveniently be listed by running the
measurablescommand (section 10.6.1). -
If
[entity]is not specified when running thedumpmonitoringdatacommand, then it must be set by specifying the entity object from its parent mode ofcmsh(for example, withuse node001indevicemode). If the mode isdevicemode, then the entity can also be specified via the options as a list, a group, an overlay, or a category of nodes.
The time pair <start-time> or <end-time> can be specified as follows:
-
Fixed time format: The format for the times that make up the time pair can be:
-
[YY/MM/DD] HH:MM[:SS]
(If YY/MM/DD is used, then each time must be enclosed in double quotes) -
The unix epoch time (seconds since 00:00:00 1 January 1970)
-
-
now: For the <end-time>, a value ofnowcan be set. The time at which thedumpmonitoringdatacommand is run is then used. -
Relative time format: One item in the time pair can be set to a fixed time format. The other item in the time pair can then have its time set relative to the fixed time item. The format for the non-fixed time item (the relative time item) can then be specified as follows:
-
For the <start-time>, a number prefixed with “-” is used. It indicates a time that much earlier than the fixed end time.
-
For the <end-time>, a number prefixed with “+” is used. It indicates a time that much later than the fixed start time.
-
The number values also have suffix values indicating the units of time, as seconds (
s), minutes (m), hours (h), or days (d).
The relative time format is summarized in the following table:
-
-
Both <start-time> and <end-time> can have their values prefixed with a “-”. In this case, the range over which the monitored values are seen is in the past, relative to the current time. If the end time for the range is specified as further in the past than the starting time, then the time values are swapped over so that the end time becomes more recent than the starting time.
The options: The options applied to the samples are specified as follows:
10.6.4.2 Notes And Examples Of dumpmonitoringdata Command Use
Notes and examples of how the dumpmonitoringdata command can be used now follow:
Fixed time formats:
Time pairs can be specified for fixed times:
Example
Double quotes are needed for times with a YY/MM/DD specification:
Example
Unix epoch time can also be set:
Example
If the start time is accidentally swapped with the end time, the time is intelligently swapped around by CMDaemon, with a warning. Intervals and interpolation:
The -i|--intervals option interpolates the data values that are to be displayed. The option needs <number> samples to be specified. This then becomes the number of interpolated samples across the given time range. Using “-i 0” outputs only the non-interpolated stored samples—the raw data—and is the default.
Example
If the number of intervals is set to a non-zero value, then the last value is always no data, since it cannot be interpolated.
Example
A set of nodes can be specified for the dump:
Summing values: The --sum option sums a specified metric for specified devices, for a set of specified times. For 2 nodes, over a period from 2 hours ago until now, with values interpolated over 3 time intervals, the option can be used as follows:
Example
Each entry in the value column in the preceding table is the sum of loadone displayed by node001, and by node002, at that time, as can be seen from the following corresponding table:
Example
Each loadone value shown by a node at a time shown in the preceding table, is in turn an average interpolated value, based on actual data values sampled for that node around that time.
Maximum and minimum values: The --max option takes the maximum of a specified metric for specified devices, for a set of specified times. For 2 nodes, over a period from 2 hours ago until now, with values interpolated over 3 time intervals, the option can be run as follows:
Example
Each entry in the values column in the preceding table is the maximum of loadone displayed by node001, and by node002, at that time, as can be seen from the following corresponding table:
Example
Similarly, for the preceding table, if the --min option is used instead, then the result would be:
Example
Displaying values during a specified time period, with --clip:
The --clip option is used with a specified time period. If there are raw values within the period, these are displayed.
A value is displayed for the start of the period, either by selection of a raw value if it exists at the exact starting time, or via interpolation if there is no raw value at the exact starting time. Similarly, at the end of the period a raw value is shown if it exists, or an interpolated value is shown if it does not.
Example
In the preceding example, the first sample is an interpolated value, interpolated over the raw samples at 00:12:07 and 00:14:07. The remaining 3 are raw samples. The epoch times for this period, and corresponding human-readable values, are shown before the heading to the output table.
Displaying according to status: The -s|--status option selects only for nodes with the specified state. A state is one of the values output by the cmsh command ds or device status. It is also one of the values returned by the enummetric DeviceStatus (section 10.2.2).
Example
The argument to -s|--status can be specified with simple regexes, which are case insensitive. For example, inst.* covers the states installing, installer_failed, installer_rebooting installer_calling_init, installer_unreachable, installer_burning.
Displaying deltas: The --delta option lists the difference between successive monitoring data values. It subtracts the previous data value from the current data value, and divides the result by the time interval between the two values.
Example
Deltas are useful for seeing patterns in rates of change. For example, to check an experimental version of CMDaemon for a memory leak, an administrator may run:
Example
The roughly 0B/s increase over 8 hours in the preceding output is a good sign.
Displaying union and intersection sets: The --union option displays the union of a set of specified devices. The devices can be specified by the device grouping options (the options that are used to group <lists>, such as -c, -r and so on).
For example:
if the overlay galeranodes has the node mon001
and
the overlay openstackhypervisors has the nodes node001, and node002
then an example of a union of the set of these two overlays is:
Example
A union of sets in the same grouping option can be carried out using comma-separation for the list of sets. In the preceding example, the same grouping option is -e|--overlay.
For a union of different grouping options however, the syntax is different. For example, for a union of the galeranodes overlay, and a node001 node, a similar example is:
Example
For an intersection of sets, the only syntax allowed is one that uses different grouping options:
Example
For intersection, comma-separation within one grouping option is pointless, and is not supported.
Displaying percentages of a particular value across a time interval (the --timegroup option): The --timegroup option for a measurable displays the percentage of appearances of each sampled value of the measurable during the interval. The percentage is displayed in the row alongside the start time of the interval. The end time of the interval is displayed in the row that follows:
An example with devicestatus showing the percentages of times in the various provisioning states (section 5.5.3):
Example
Another example is with wlm_slurm_state, an enum that shows the state of nodes that can be allocated to the Slurm workload manager:
The percentage total is 100% in the output. The --timegroup option tends to be useful and meaningful for health checks and enummetrics, rather than for metrics.
Some non-interpolating RLE quirks: When a sample measurement is carried out, if the sample has the same value as the two preceding it in the records, then the “middle” sample is discarded from storage.
Thus, when viewing the sequence of output of non-interpolated samples, identical values do not exceed two entries one after the other. This is a common compression technique known as Run Length Encoding (RLE). It can have some implications in the output of the dumpmonitoringdata command.
Example
In the preceding example, data values for the number of threads used by CMDaemon are dumped for the last 10 minutes.
Because of RLE, the value entry around 01:15:30 in the preceding example is skipped. It also means that at most only 2 of the same values are seen sequentially in the Value column. This means that 42 is not the answer to everything.
For a non-interpolated value, the nearest value in the past, relative to the time of sampling, is used as the sample value for the time of sampling. This means that for non-interpolated values, some care may need to be taken due to another aspect of the RLE behavior: The time over which the samples are presented may not be what a naive administrator may expect when specifying the time range. For example, if the administrator specifies a 10 minute time range as follows:
Example
then here, because the dump is for non-interpolated values, it means that the nearest value in the past, relative to the time of sampling, is used as the sample value. For values that are unlikely to change much, it means that rather than 10 minutes as the time period within which the samples are taken, the time period can be much longer. Here it turns out to be almost 3 days because the nodes happened to be booted then.
10.6.5 Monitoring Data Health Overview—The healthoverview Command
In figure 10.24, section 10.4.6, the Base View navigation path
Monitoring > Health Status
showed an overview of the health status of all nodes.
The cmsh equivalent is the healthoverview command, which is run from within device mode. If run without using a device, then it provides a summary of the alert levels for all nodes.
The help text in cmsh explains the options for the healthoverview command. The command can be run with options to restrict the display to specified nodes, and also to display according to the sort order of the alert level values.
Example
10.6.6 Monitoring Data About The Monitoring Action History—The monitoringactionhistory Command
The monitoringactionhistory command displays a history of monitoring actions that have been triggered on an entity. This lets the cluster administrator examine which triggers fired on a node, and what actions were taken in response.
Example
Each row shows the entity (the node here) that was triggered and executed the action, the measurable that was evaluated, the trigger that fired, the action that was executed, the monitoring node that processed it, and the timestamp.
The command is available in any entity mode (for example: device, partition, wlm), and can be used with the standard node selection options to filter by specific entities.
The recording of action history can be disabled by setting the AdvancedConfig directive MonitoringEntityActionHistoryDisabled=1 (here). A restart of CMDaemon is required for this change to take effect.
10.6.7 Monitoring Data About The Monitoring System—The monitoringinfo Command
The monitoringinfo command provides information for specified head nodes or regular nodes about the monitoring subsystem. The help text shows the options for the command. Besides options to specify the nodes, there are options to specify what monitoring information aspect is shown, such as storage, cache, or services.
Example
10.6.8 Dropping Monitoring Data With The monitoringdrop Command
Monitoring data gathering can be restricted to certain nodes using node execution filtering and execution multiplexers. Entire data producers can also be disabled with the disable option in monitoring mode. However, restricting or disabling leaves historical samples in storage—the existing monitoring data values do not automatically get removed. So, in cmsh and Base View the latest known monitoring data values then still show up, with a forever-increasing age.
If a data producer is removed, then the associated data values for its measurable or measurables are removed.
Alternatively, if adding execution filters to a monitoring data producer is intended to be a permanent change, then all previously collected data can be dropped for filtered nodes.
For example, if the ssh connectivity to only cloud nodes is to be checked:
Example
After this is set, the monitoring data values for a non-cloud node can be checked. The ssh2node health check data values are then seen to be getting older, without any more updates being added. These health check data values can then be dropped using the monitoringdrop command from within the device mode of cmsh command.
It is wise to run a dry-run operation first, in order to make sure that no data values are unintentionally removed:
Example
The --force option can be used to remove non-filtered old data, such as data from a disabled measurable. This is also useful when correcting a bad metric script. After fixing the script, the old (incorrect) data can be dropped.
Example
A reboot or CMDaemon restart is required for the node to start collecting data again on a non-filtered metric which has been dropped with the --force option.
10.6.9 Monitoring Suspension And Resumption—The monitoringsuspend And monitoringresume Commands
The monitoringsuspend command suspends monitoring. The monitoringresume command resumes monitoring.
When suspension is applied to a head node, the regular nodes simply continue sampling data up to a maximum of 1 million samples per node. The available backlog is fetched upon resumption.
Suspension can be used during benchmarking to measure the results of benchmarking runs without having monitoring get in the way.
Suspension can also be used as a quick sanity check during regular cluster operation, as a way for an administrator to see if it is monitoring that is consuming excessive resources, in comparison with the other processes on the system. For example, running it on a head node (some output omitted or elided):
Example
In the preceding example monitoring is seen to be consuming significant resources.
After running monitoringsuspend, resuming monitoring should not be forgotten, and it should be done soon enough after suspension. If that is not done, then backlogged samples that exceed the limit of 1 million samples per node on the regular nodes would be lost. Resumption is carried out with:
Example
10.6.9.1 CMDaemon Directive Settings To Reduce Monitoring Resource Consumption
The following CMDaemon directive changes may reduce the resource consumption due to monitoring:
Increasing the job account collection interval:
by increasing the value of the JobsSamplingMetricsInterval directive (here).
Disabling job information collection completely:
by setting the value of the JobInformationDisabled directive to 1 (here).
Reducing the duration for which job data is stored:
by reducing the value of the JobInformationKeepDuration (here).
10.6.10 Monitoring Pickup Intervals
All nodes cache their monitoring data. This cached data gets picked up by the active head node at a regular pickup interval.
It is possible to alter the pickup interval using the monitoringpickup command covered in this section. The command is run from device mode.
The current pickup intervals can be listed with:
Example
An interval can be set for one or more nodes. For example, a 1-minute pickup interval can be set as follows:
Example
The pickup interval is carried out only once by default, unless otherwise specified.
The --times option allows the number of times to be specified:
Example
The --forever option lets the pickup be carried out forever.
Example
The --priority option applies the priority to equal or lower priority settings:
Example
In the preceding example, parameters for node002 only were changed, as the priority setting for node001 was higher than the applied priority option that was requested. Thus, the Interval value became 5s, as specified, the Times value defaulted to 1, and the specified Priority value of 50 was applied to node002 only.
The further behavior of the pickup from node002 is as follows:
After picking up data once from node002, five seconds from the change, the interval becomes the default of 2 minutes once again:
The yet further behavior of the pickup, during the next pickup event, is then as follows:
The Times value of 0 becomes unset. The unset value is represented by -, and is equivalent to --forever.
In other words, if a monitoring interval is changed, and the change is not specified as “forever”, then after the Times value has decremented to zero, the monitoring interval reverts to the default value of 2 minutes. The Times value then becomes a value of -, which implies forever, when the next pickup occurs.
The job metric sampler can also automatically modify the pickup interval for nodes. Every time a new job is started, all the nodes that are used by the job are assigned a modified pickup interval. The new values for the pickup can be managed in the jobmetricsettings mode of cmsh.
10.7 Offloaded Monitoring
Traditional BCM monitoring uses a single (active) head node to manage monitoring. That is, to carry out sampling and to store results for measurables. Traditional monitoring can be used for clusters of thousands of nodes, assuming the default number of measurables are running.
Offloaded monitoring in BCM is designed to share the more resource-intensive parts of monitoring across nodes so that the head node is not overloaded by monitoring. In practice, offloaded monitoring needs only to be considered for a clusters that are greater than about 1000 nodes in size, assuming the clusters have the default number of measurables running.
There are some mandatory requirements, and some recommended settings, which are discussed later on in section 10.7.3.
10.7.1 Why Offloaded Monitoring?
Traditional monitoring is highly optimized, and with some care is typically able to deal with clusters of around 10,000 nodes with the default metrics. While it has the virtue of simplicity, it also has the following possible issues:
-
there is a single point of failure, since monitoring runs on the active head node
-
the head node performance as the number of nodes increases may not be sufficient. To get around this, monitoring may rely on increasingly expensive hardware, or on reducing the sampling that is carried out. With the default monitoring in place, with typical server hardware available at the time of writing of this section (2020), a limit is reached at around 20000 nodes.
These issues may not be acceptable, in which case it makes sense to consider offloaded monitoring.
The advantages of offloaded monitoring are:
-
no single point of failure
-
the ability to scale with the size of the cluster
A disadvantage is that offloaded monitoring is more complicated than single head monitoring. However, BCM simply implements it as a role that is assigned to nodes. The BCM backend then manages the details of offloaded monitoring.
10.7.2 Implementing Offloaded Monitoring
In cmsh offloaded monitoring is implemented via role assignment. The assignment can be carried out at the level of device, category, or configuration overlay:
Example
If offloaded monitoring is to run in a highly-available way, so that a failure of one monitoring node does not halt the monitoring system, then offloaded monitoring must be assigned to two or more nodes.
10.7.3 Background Details
A description of how offloaded monitoring works in the backend follows, because it should help the cluster administrator in understanding how and when to implement it.
Offloaded monitoring uses nodes that are assigned a monitoring role.
If there are N regular (non-head) nodes in a cluster that are being monitored, and if there are M monitoring nodes, then the idea of offloading is that each monitoring node covers N/M of the total monitoring storage, and N/M of the sampling scripts.
In other words, the cluster manager aims to evenly spread the total storage and sampling needed for all the regular nodes, over the nodes with a monitoring role.
BCM in the default state with no high availability does not run offloaded monitoring.
10.7.3.1 High Availability And Offloaded Monitoring With Just The Head Nodes Running As Monitoring Nodes
The simplest offloaded monitoring configuration is when high availability is configured. That is, when BCM is configured with two head nodes as described in Chapter 15. By default, a monitoring role is then assigned to both the head nodes.
This has the effect of doubling the monitoring capacity of the head node pair in NVIDIA Base Command Manager 9.1, in comparison with a head node pair in NVIDIA Base Command Manager version 9.0 and earlier.
The head nodes then carry out storage and sampling for the regular nodes as well as for themselves.
10.7.3.2 Offloaded Monitoring With Regular Compute Nodes Running As Monitoring Nodes
It is possible to run a compute node with a monitoring role assigned to them. This means that the compute node carries out storage and sampling as part of its monitoring role.
During a SYNC install—the default node provisioning for a healthy node—monitoring data persists.
Monitoring data would be wiped out during a FULL install (section 5.4.4). To provide a check on this, the node can be set up with the datanode setting (here), which requires a confirmation from the cluster administrator before carrying out a FULL install. However, if the monitoring data values are that important, then the cluster administrator should consider backup solutions for it anyway.
10.7.3.3 Offloaded Monitoring With Dedicated Nodes Running As Monitoring Nodes
For large clusters of around 10,000 or more nodes, a recommended practice is to have dedicated monitoring nodes. These are then regular nodes that are typically set up with the datanode setting, and are not used for other purposes such as HPC use. The dedicated monitoring nodes then carry out monitoring sampling and monitoring data storage for the regular nodes. Each of the M dedicated monitoring nodes takes on N/M of the regular nodes for itself, and records monitoring data from those N/M nodes.
This is illustrated by the following schematic, with arrows indicating the monitoring sampling flow for the head nodes (H1, H2), dedicated monitoring nodes (M1 to M3), and regular nodes (N1 to N6):
Figure 10.28: Monitoring Sampling Flow For Offloaded Monitoring With Dedicated Monitoring Nodes
A monitoring node in this configuration also copies backups of its monitoring data to other monitoring nodes. Number of backups for the monitoring role (section 10.7.2) is used to configure the number of backups. In the following schematic, two neighboring monitoring nodes are used as backup:
Figure 10.29: A Simple Backup Flow For Offloaded Monitoring With Dedicated Monitoring Nodes
The backups need not be on the same local network. For example, edge directors can be backed up to the head node.
If a monitoring node fails, then its monitoring data can be extracted from its backup nodes, and a new distribution of nodes to be monitored is allocated to the remaining monitoring nodes.
A backup is carried out using what the BCM developers call a provisioning grab. This is similar to grabimage (section 5.6), but this time designed for grabbing monitoring data. Like grabimage, provisioning grab also works on the basis of an rsync. This means that the first copy can take a while, but that subsequent copies are much faster.
Provisioning grabs are staggered to reduce bandwidth consumption and to reduce the likely amount of monitoring data that goes out of date during an outage.
Dedicated monitoring nodes can cope with short outages of monitoring nodes, such as are caused by a CMDaemon restart on that monitoring node, or by a reboot of that monitoring node. These outages are not expected to take longer than a few minutes, and the monitoring nodes just continue on as normal, with some missing data samples. However, if an outage is greater than about 15 minutes, such as may happen if a monitoring node crashes, then a fully automated rebalancing of the loads on the monitoring nodes can only take place with the aid of backups.
The head nodes in this configuration are configured as HA, and without the monitoring role, and thus do not carry out monitoring data storage for the regular nodes. They do however still sample and store data for themselves, and carry out backups to each other.
Backup nodes: In addition, for larger clusters, another recommended practice is to have backup nodes (B1, B2 in the following schematic) for the dedicated monitoring nodes:
Figure 10.30: A More Sophisticated Backup Flow For Offloaded Monitoring With Dedicated Monitoring Nodes And Dedicated Backup Nodes
Backup nodes for the monitoring nodes take away the monitoring data backup task from the monitoring nodes. This frees up the monitoring nodes so that they can take on even more monitoring.
Provisioning role on monitoring nodes: If there is enough capacity on the dedicated monitoring nodes, and the cluster spends most of its time in a relatively steady state where its nodes do not reboot frequently, then adding a provisioning role to the monitoring nodes can be an efficient use of resources. In this case the monitoring nodes are obviously not so dedicated, but the advantage is that rebooting the entire cluster is then faster, at the cost of perhaps some extra load on the monitoring nodes during such a reboot.
10.7.3.4 Offloaded Monitoring Sampling And Backup Flows For Edge Computing
For a cluster with edge configured, the edge director flows in the edge network are analogous to head node flows in the local network. Thus, monitoring is carried out by the directors on the edge nodes, and the directors also sample themselves.
Thus, edge directors, not in a high-availability configuration, have the monitoring sampling data flow shown by the following schematic (figure 10.31):
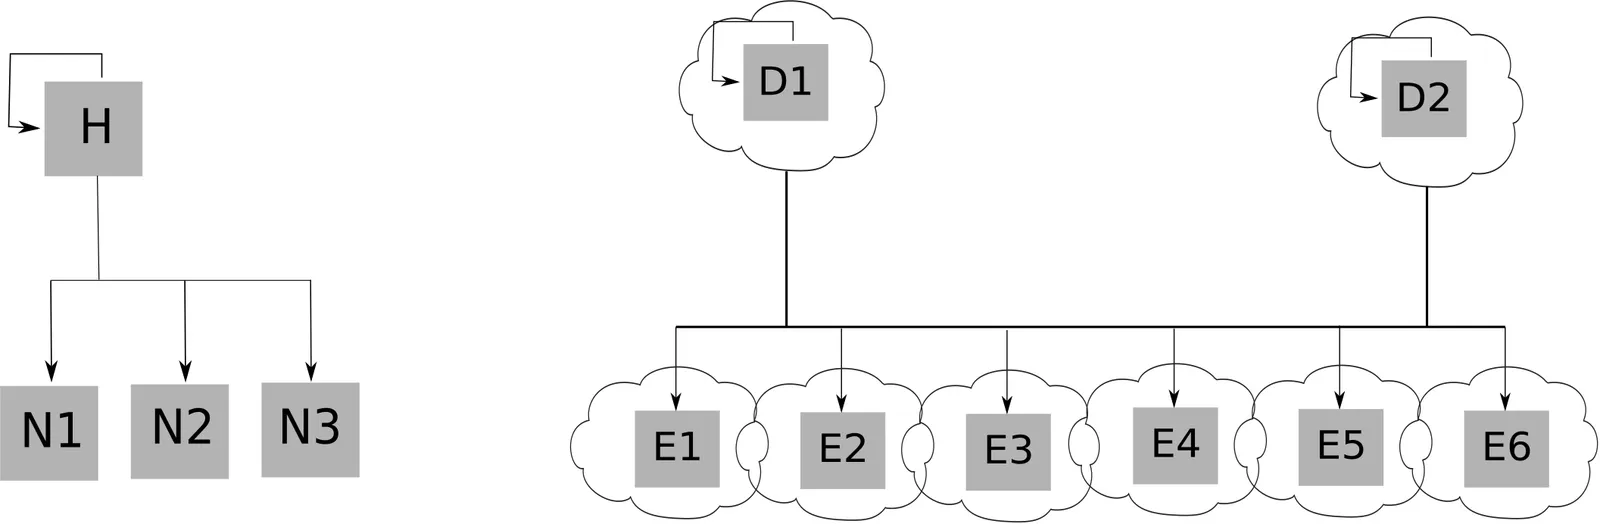
Figure 10.31: Sampling Flow For Offloaded Monitoring With Non-HA Edge Director Nodes
For edge directors that have been set up in an HA configuration (section 2.1.1.1 of the Edge Manual) the monitoring sampling data flow in the edge network is split up between directors, so that each director takes half of the edge nodes. This is analogous to how head nodes in an HA configuration take half of the regular nodes each (figure 10.32):
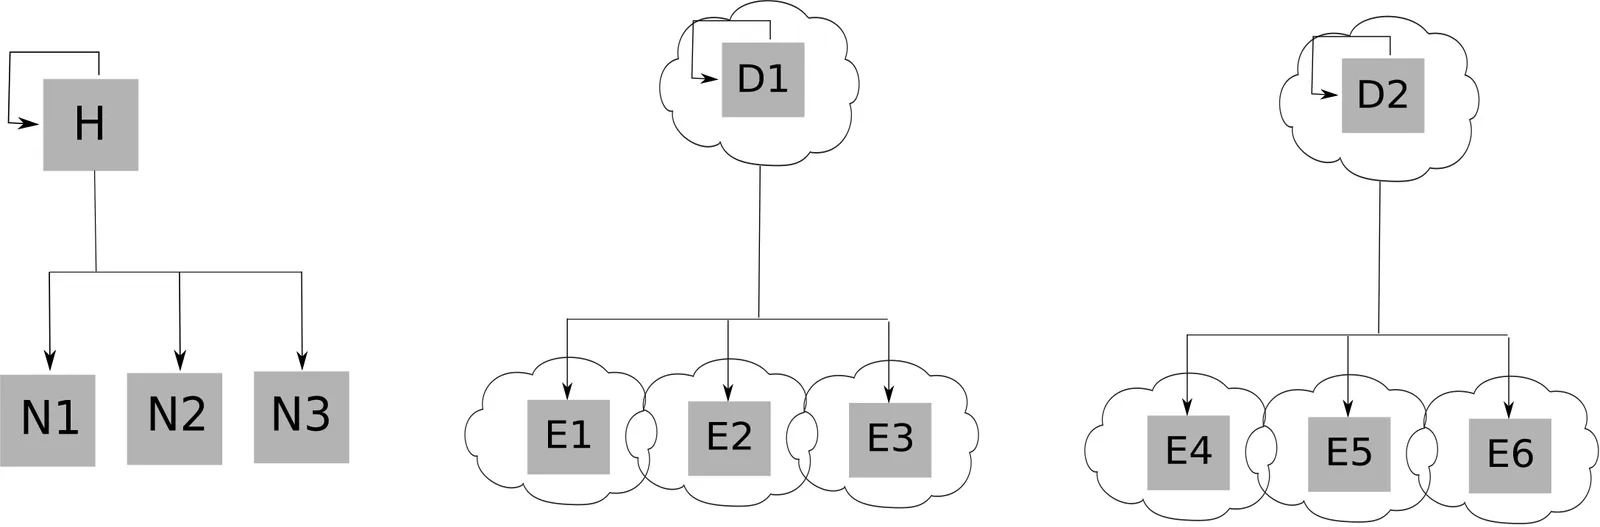
Figure 10.32: Sampling Flow For Offloaded Monitoring With HA Edge Director Nodes
The backup data flow for a non-HA configuration would then be as follows for an edge director (figure 10.33):
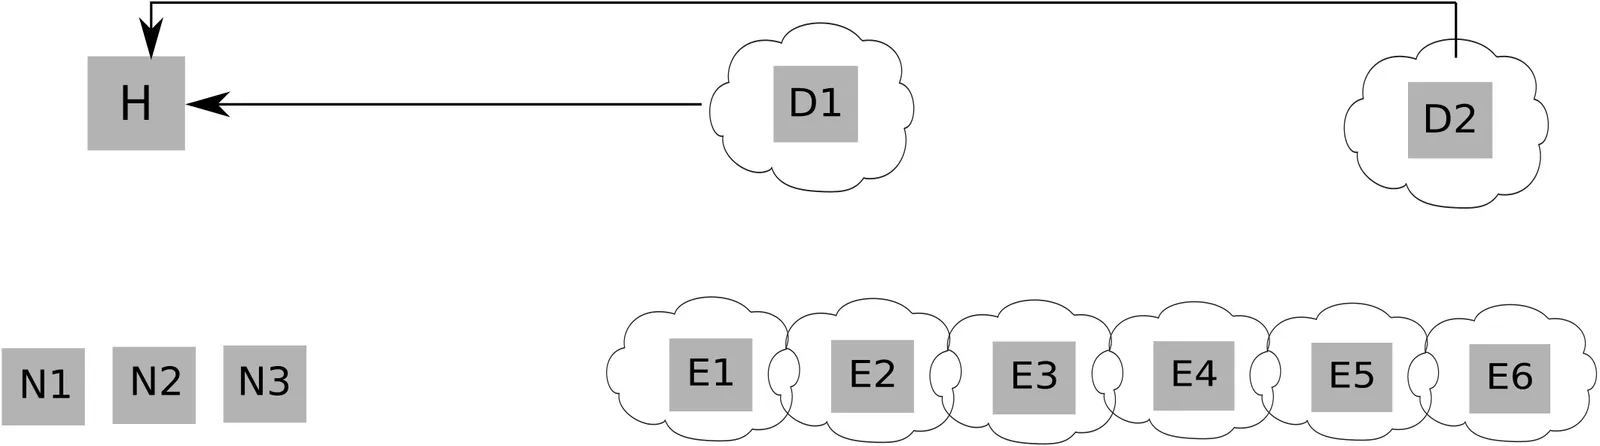
Figure 10.33: Backup Flow For Offloaded Monitoring With Non-HA Edge Director Nodes
Backing up to the head node is possible for an edge director. But it is usually unwise because one of the usual reasons to have a segregation of local and edge networks is to reduce data flow between the local and edge network.
With edge directors in an HA configuration, a big advantage is that backing up to the other edge director is possible and configured by default, rather than backing up to the head node (figure 10.34):
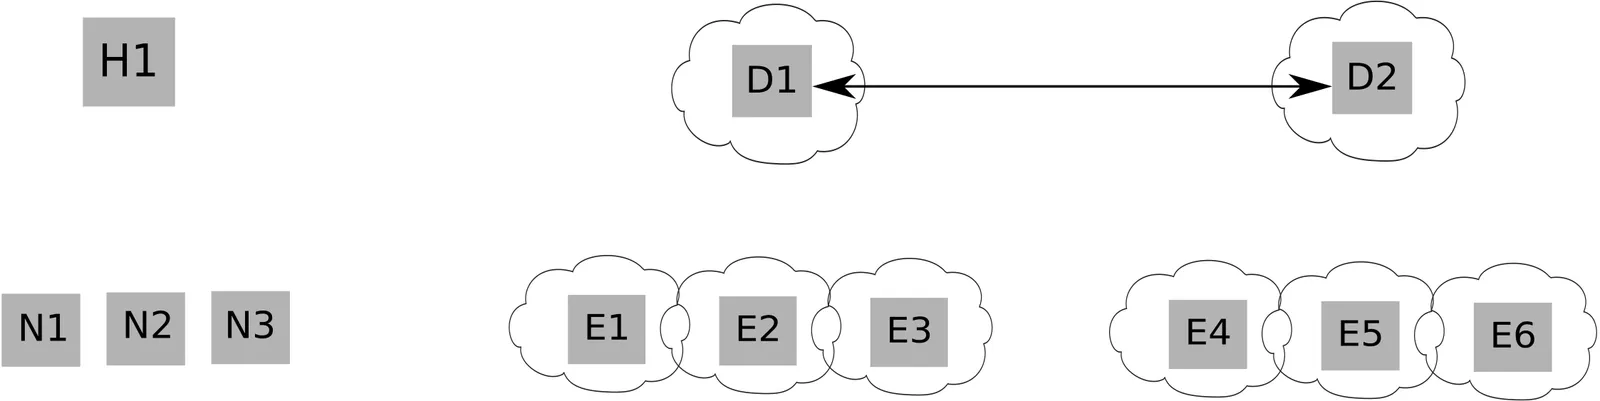
Figure 10.34: Backup Flow For Offloaded Monitoring With HA Edge Director Nodes
10.7.3.5 Default Backups Configurations
The default backup configurations for monitoring data are:
-
Head node HA : head nodes back up each other
-
Edge node HA : directors back up each other
-
edge directors: directors back up to (both) head nodes
-
cloud directors: directors back up to (both) head nodes
10.7.4 Examining Offloaded Monitoring With monitoringoffloadinformation
The monitoringoffloadinformation displays the monitoring relations between nodes. In a small HA cluster with a default configuration, with only two HA head nodes basecm11-ha-a and basecm11-ha-b in a monitoring role, the output of the command for node001 is:
Here, node001 is seen as having its monitoring data going to one selected head node.
Viable in this context means a node that is capable of being used for monitoring, even if it may not be available now, for example due to a temporary outage such as a reboot. Both head nodes are thus capable of doing monitoring.
For one of the head nodes in the cluster, the output is:
10.8 The User Portal
The user portal is a restricted version of Base View that allows non-root users to view some cluster manager data.
With a browser:
-
If the head node landing page (figure 2.1) shows a greytoned user portal block with a ⊕ within it, then it means that the user portal is not installed.
-
If the head node landing page shows a colored user portal block with a chain link icon within it, then the user portal can be accessed via the icon.
The user portal can be added or removed from the cluster manager by adding or removing the cm-webportal package.
Example
10.8.1 Accessing The User Portal
The user portal is compatible with most browsers using reasonable settings, and is supported for the same browsers that Base View supports (section 2.4).
The user portal is located by default on the head node, and can then be accessed in two ways:
-
From the chain link icon within the colored user portal block of the head node landing page, mentioned earlier.
-
More directly using a URL of the form:
https://<host name or IP address>:8081/userportal
Both of these access routes lead to a user login page. The state of the cluster can then be viewed by the users via an interactive interface.
The first time a browser is used to log in to the portal, a prominent warning about the site certificate being untrusted appears.
This is because certificate is a self-signed certificate (the X509v3 certificate of Chapter 4 of the Installation Manual), generated and signed by BCM, and the attributes of the cluster owner are part of the certificate. However, the CA for BCM (NVIDIA Bright CA) is not a recognized Certificate Authority (CA) like the CAs that are recognized by a browser, which is why the warning appears.
For a portal that is not accessible from the outside world, such as the internet, the warning about Bright Computing not being a recognized Certificate Authority is not an issue, and the user can simply accept the “untrusted” certificate, and the browser used then no longer displays such a prominent warning about the issue.
For a portal that is accessible via the internet, some administrators may regard it as more secure to ask users to trust the self-signed certificate rather than external certificate authorities. Alternatively the administrator can replace the self-signed certificate with one obtained by a trusted recognized CA, for example the one at https://letsencrypt.org, if that is preferred.
The user portal certificate discussed here is a webserver certificate, similar to that of the landing page, but served by CMDaemon rather than Apache.
10.8.2 Setting A Common Username/Password For The User Portal
By default, each user has their own username/password login to the portal. Removing the login is not possible, because the portal is provided by CMDaemon, and users must connect to CMDaemon.
A shared (common) username/password for all users can be set in the configuration file, common-credentials.json. The default username/password settings are blank, which means that common access is not enabled:
Example
To enable common access:
-
the common username and password must be added via
cmshor Base ViewExample
-
the common username and password should be set in the appropriate place in the configuration file,
common-credentials.json:Example
A minor stumbling block for the unwary administrator is:
If using Base View, then if the password for the username has already been saved in the browser’s password manager before changing it in the configuration file, then the password saved in the browser’s password manager may need to be changed to the new one explicitly.
10.8.3 User Portal Access
By default, the user profile (section 6.5) is set to readonly, which allows viewing of the information presented in the user portal, without allowing it to be altered.
10.8.4 User Portal Home Page
10.8.4.1 User Portal Overview Page
The default user portal home page is the Overview page. This allows a quick glance to convey the most important cluster-related information for users (figure 10.35):
Figure 10.35: User Portal: Overview Page
The following items are displayed on the overview page:
-
a Message Of The Day. This can be edited in
/cm/local/apps/cmd/etc/htdocs/userportal/assets/config/message-of-the-day.html -
links to the documentation for the cluster
-
an overview of the cluster state, displaying some cluster parameters. By default, it is refreshed every 10s.
The user portal is designed to serve files only, and will not run executables such as PHP or similar CGI scripts.
10.8.4.2 User Portal Job Accounting Page
Job accounting charts can be viewed on clicking upon the associated icon,  , at the top right corner of the user portal page. The user portal’s
Accounting and reporting page for Base View is then displayed.
The accounting and reporting page allows job accounting to be viewed in an accounting panel in a very similar manner to how it is done in section 12.5.
10.9 Cloud Job Tagging
Cloud job tagging is about the ability for cloud job instances to have their associated cloud resources tagged. This is only possible for AWS at the time of writing (February 2020). Enabling cloud job tagging via NVIDIA Base Command Manager was introduced in version 9.0.
Tags are key=value pairs for AWS resources, and can be applied to resources. Typically, tags that are applied are set by the user via the Tag Editor of the Amazon Management Console, and up to 50 tags can be applied per resource.
Cloud job tagging should not be confused with the tagging of job metrics for job accounting (section 12.2). AWS cloud resource tagging is only active and handled within AWS.
Cloud job tags allow the time span between tag creation and removal to be associated with a particular workload on the node.
In cmsh, for a cloud node, cloud job tagging can be enabled within cloud mode by setting the cloudjobtagging parameter for the EC2Provider entity to yes
Example
If it is set to yes, then every job running on a cloud node using that specific provider is tagged according to the applied tags.
A subset of the tags for cloud jobs are cost allocation tags. Cloud job cost allocation tags allow AWS costs to be tracked for jobs. A cost allocation tag can be:
-
an AWS generated tag: defined, created, and applied by AWS
-
a user-defined tag: defined, created, and applied by the user
By default, BCM provides the following tag names when the cloud job tagging feature is enabled:
-
BCM_JOB_ID -
BCM_JOB_ACCOUNT -
BCM_JOB_USER -
BCM_JOB_NAME
When CMDaemon sees that a job has started, the resources of that job are then tagged with the job ID, the job account, the job user, and the job name. When CMDaemon detects that the job has stopped, it removes the tags.
The AWS Cost Explorer can be used to view the AWS costs for a billing period according to tags.
Further information on tagging can be found at:
https://docs.aws.amazon.com/AWSEC2/latest/UserGuide/Using_Tags.html.
Further information on using the Cost Explorer with cost allocation tags can be found at:
https://docs.aws.amazon.com/awsaccountbilling/latest/aboutv2/cost-alloc-tags.html
10.10 Event Viewer
Monitoring in BCM is normally taken by developers to mean how sampling with data producers is handled. However, cluster administrators using this manual typically consider watching and handling events in BCM to also be a part of a more general concept of monitoring. This manual is aimed at cluster administrators, and therefore this section on event viewing and handling is also placed in the current monitoring chapter.
BCM events can be handled and viewed in several ways. Event logging is enabled by default by the EventLogger directive (here).
10.10.1 Viewing Events In Base View
In Base View, events can be viewed by clicking on the Events icon of figure 10.5. This opens up a window with a sortable set of columns listing the events in the events log, and by default with the most recent events showing up first.
10.10.2 Viewing Events In cmsh
The events command is a global cmsh command. It allows events to be viewed at several severity levels (section 10.2.7), and allows old events to be displayed. The usage and synopsis of the events command is:
Running the command without any option shows event settings:
Example
Running the command with options allows the viewing and setting of events as follows:
-
on [broadcast|private]: event messages are displayed as they happen in a session, withcmshprompts showing in between messages:-
If only
onis set, then all event messages are displayed as they happen:-
either to all open
cmshsessions, and also in Base View event viewer panes, if the event or its trigger has the “broadcast” property. -
or only in the
cmshsession that is running the command, if the event or its trigger has the “private” property.
-
-
If the further option
broadcastis set, then the event message is displayed as it happens in all opencmshsessions, and also in all Base View event viewer panes, if the event or its trigger has the “broadcast” property. -
If the further option
privateis set, then the event message is displayed as it happens only in thecmshsession that ran the command, if the event or its trigger has the “private” property.
-
-
off [broadcast|private]: disallows viewing of event messages as they happen in a session. Event messages that have not been displayed due to being forbidden with these options, are displayed when theeventscommand is run without any options in the same session.-
If only
offis set, then no event message is displayed as it happens in the session. This is regardless of the “broadcast” or “private” property of the event or its trigger. -
If the further option
broadcastis set, then the event message is not displayed as it happens, if the event or its trigger has the “broadcast” property. -
If the further option
privateis set, then the event message is not displayed as it happens, if the event or its trigger has the “private” property.
-
-
show-acknowledged: if set toyes, theneventsshows the events that have been acknowledged -
show-detailed: if set toyes, theneventsshows the events in greater detail, if possible -
level <info|notice|warning|error|alert>: sets a level. Messages are then displayed for this and higher levels. -
clear: clears the localcmshevent message cache. The cache indexes some of the events. -
details<id>: shows details for the event with the index value of <id>, which is a number that refers to an event. -
acknowledge<id>: acknowledges the event with the index value of <id> -
unacknowledge<id>: unacknowledges the event -
<number>
[info|notice|warning|error|alert]: shows a specified <number> of past lines of events. If an optional level (info,notice,…) is also specified, then only that level and higher (more urgent) levels are displayed. -
follow: follows event messages in acmshsession, similar totail -f /var/log/messages. This is useful, for example, in tracking a series of events in a session without having thecmshprompt showing. The output can also be filtered with the standard unix text utilities, for example:events follow | grep node001
A common example of events that send private messages as they happen are events triggered by the updateprovisioners command, which has the “private” property. The following example illustrates how setting the event viewing option to private controls what is sent to the cmsh session. Some of the output has been elided or truncated for clarity:
Example
10.10.3 Using The Event Bucket From The Shell For Events And For Tagging Device States
10.10.3.1 Event Bucket Default Behavior
The BCM event bucket accepts input piped to it, somewhat like the traditional unix “bit bucket”, /dev/null. However, while the bit bucket simply accepts any input and discards it, the event bucket accepts a line of text and makes an event of it. Since the event bucket is essentially an event processing tool, the volumes that are processed by it are obviously less than that which /dev/null can handle.
By default, the location of the event bucket is at /var/spool/cmd/eventbucket. Directing a message to the event bucket makes an event, which can be viewed in cmsh or Base View.
Example
This adds an event with, by default, the info severity level. It can be seen within cmsh with the events command:
Example
or it can be viewed in the Base View event pane that is accessible with the event icon in the top right corner of the Base View standard display (figure 10.5).
10.10.4 InfoMessages
InfoMessages are optional messages that inform the administrator of the reason for the status change of a measurable, or an event in the cluster.
Measurable scripts can use file descriptor 3 within their scripts to write an InfoMessage:
Example
10.10.4.1 Event Bucket Severity Levels
To write events at specific severity levels (section 10.2.7), and not just at the info level, the appropriate text can be prepended from the following to the text that is to be displayed:
Example
The preceding example displays an output notification in the Base View event viewer as shown in figure 10.36:
Figure 10.36: Base View Monitoring: Event Bucket Message Example
10.10.4.2 Event Bucket Filter
Regex expressions can be used to conveniently filter out the user-defined messages that are about to go into the event bucket from the shell. The filters used are placed in the event bucket filter, located by default at /cm/local/apps/cmd/etc/eventbucket.filter.
10.10.4.3 Event Bucket CMDaemon Directives
The name and location of the event bucket file and the event bucket filter file can be set using the EventBucket and EventBucketFilter directives from the CMDaemon configuration file directives (Appendix C.22).
10.10.4.4 Adding A User-Defined Message To A Device State With The Event Bucket
While the event bucket is normally used to send a message to the event viewer, it can instead be used to add a message to the state of a device. The line passed to the echo command then has the message and device specified in the following format:
STATE.USERMESSAGE[.device]:[message].
The device can be anything with a status property, such as, for example, a node, a switch, or a chassis.
Example
The state then shows as:
If the device is not specified, then the current host of the shell that is executing the echo command is used. For example, running these commands from the head node, basecm11, as follows:
Example
yields these states:
The added text can be cleared with echoing a blank message to that device. For example, for node001 that could be:
10.10.4.5 Reloading CMDaemon Logging Configuration With Event Bucket
CMDemon logging configuration is reloaded when CMDaemon is restarted (systemctl restart cmd). The logging configuration can also be reloaded without restarting CMDaemon by triggering the event bucket:
Example
10.10.4.6 Using An Event Bucket During The Node-installer Stage
The node-installer runs before systemd is up on the node that is being provisioned. This means that CMDaemon is also not yet running on that node, so that the regular event bucket features are not available during that time. However, a simplified event bucket—the node-installer event bucket—is available during this stage.
The node-installer event bucket can be particularly useful if debugging larger initialize and finalize scripts (Appendix E).
To use it, text is echoed to /tmp/eventbucket within the node or category scripts. The text will show up (if permitted) within the sessions of cmsh, and within the events viewer of Base View.
There are two different modes for the node-installer event bucket:
-
Device status
info-messageupdater mode:Example
-
Warning event mode:
Example
10.10.4.7 An Alternative To InfoMessages With The REST API
A cleaner alternative to InfoMessages for status messages is the Status REST API call (section 4.2.1.2 of the Developer Manual).
10.11 Monitoring Location With GNSS
GNSS (Global Navigation Satellite System) is the term given to GPS and similar systems. GNSS can be used to allow devices with the appropriate GNSS hardware to work out their location. The hardware is commonly implemented as a PCI-X card. A use case for this is to allow an engineer to walk to a node with a mobile phone, or to determine a sensible provisioning host.
The hardware requires the ability to receive satellite signals via an antenna. From the signals, the time of receipt and location can be worked out. BCM makes the results available in the locations submode of the base partition of cmsh:
Example
In practice, due to environmental interference, a minimum resolution of 5m is common for longitude and lattitude. The height determination is typically 1.5x more inaccurate. Vendor specifications should be referred to for details on obtaining greater accuracy, since there are technology enhancements that can improve the accuracy.
The location is determined at start up and on demand.
10.12 Monitoring Report Queries
10.12.1 Monitoring Report Queries In cmsh
There are usually several hundred sources of data in BCM, and they are often of different types. An administrator would sometimes like to see the output of the data sources grouped by particular nodes. The variety of types means that examining the data output according to grouping choices would normally be awkward.
The data output can be viewed in BCM with the help of a simple query language from within the monitoring report submode. The query language can be used to filter by grouping choices and data values.
10.12.1.1 Data Sources For Monitoring Reports
The sources of data can be listed in report mode with the fields command:
Example
10.12.1.2 Filtering And Grouping For Monitoring Reports
A field filtered by a grouping can be executed using the execute command on a specified field, and applying a filter grouping to it using an operator.
For example, the field ssh2node can have the filter grouping category applied to it using the operator == for all nodes that are up. This can then be executed.
If the ssh2node field output is a PASS for nodes that are in a category gpu, and the ssh2node output is also a PASS for node001 and node002, but a FAIL for node003 and node004, then a report from a query executed for this, showing the non-empty groupings of hostnames could be run with:
Example
Alternatively, the query can be saved and run as follows:
Example
A previously saved query can be run from outside the object with the -q|--query option.
The help execute text has some more detail on using the execute command.
Saving the list of nodes that the filter is applied to: The --save option takes a file base name as its argument, and saves the list of nodes that the filter applies to. Suffixes appended to the file base name are taken from the filter that is used and from the grouping values.
Example
The file name thus takes the form: <basename>-<grouping value>-<filter value>.lst
The file can be read within cmsh by using the operator ^
Example
10.13 Monitoring With nvsm
The nvsm command in the device mode of cmsh is a BCM wrapper for the NVIDIA System Management (NVSM) software stack.
-
The NVSM stack provides a CLI and API for the end user to monitor NVIDIA DGX hardware. These are documented in detail at https://docs.nvidia.com/datacenter/nvsm/latest/pdf/nvsm-user-guide.pdf.
-
The
nvsmwrapper command ofcmshis a front-end to some parts of the NVSM stack.
The nvsm CLI can be run directly on a node with an NVSM software stack. That CLI should not be confused with the nvsm wrapper command that is run from within the device mode of cmsh, and which is what is described in the rest of this section (section 10.13).
Running nvsm without any arguments displays the nvsm help text:
Tab-completion prompts to nvsm suggest nvsm-specific options:
Example
The nvsm-specific parts for this command are indicated by the following cmsh tree:
The preceding tree is discussed further next:
-
alerts: Presents a list of the alerts that NVSM detects.Example
It has the options:
-
--start <start>: Sets the first index of the alert to list.Example
This skips the first 4 alerts received, and displays the rest. The alerts are not necessarily received in same order as displayed by the
nvsm alertscommand. -
--limit <limit>: Sets a limit of<limit>alerts to be displayed.
-
-
health: carries out a dump to a.tar.xzfile for the specified node. The dump for a node namednode001is stored in/cm/shared/nvsm/node001by default. It can take about 15 minutes to complete.-
--quick: does a quick dump. This completes faster, but uses more memory and CPU. -
--tags <tags>: a comma-separated list of tags for the dump.
-
-
info: Lists the most recent health dump information.Example
The file name for a node named
node001takes a timestamped format of:node001_YYYY-MM-DD-HH-MM-SS.tar.xz-
--history: Lists historical dumps.Example
-
-
status: Shows the dump status of the node.Example
-
stop: Aborts the dump creation for the specified nodes. Withstop, the dump that has been created until then remains available as a directory rather than a.tar.xzfile -
versions: Lists the versions of various components used by NVSM.--details: May provide some more details on the component.
Example
The nvsm alert command can inform the cluster administrator about hardware issues more conveniently than diving into the NVSM CLI. Viewing the output of the alert may be enough to get on with solving the issue.
If that is not enough, then examining the dump file produced by nvsm health allows for further troubleshooting by experienced administrators and developers.
The dump file can be extracted with:
Example
The extracted directories and files have the following layout if viewed at a two-level depth with tree -L2:
10.14 Monitoring With nvdebug
The NVDebug package, nvdebug, can be installed with the package manager.
The nvdebug command in the device mode of cmsh is a BCM wrapper for the NVIDIA NVDebug log collection tool. NVDebug collects diagnostic logs from NVIDIA hardware, including host logs, BMC/Redfish data, IPMI data, and health checks.
The collected logs are stored on shared storage under /cm/shared/nvdebug/ <hostname>.
Running nvdebug without any arguments displays the nvdebug help text:
The nvdebug subcommands are:
-
start: Starts NVDebug log collection on the specified nodes. The logs are collected using a systemd service and stored in/cm/shared/nvdebug/<hostname>.Example
The
startsubcommand has the options:-
-t, --platform <type>: Platform override. Values:DGX,arm64,x86_64,NVSwitch,HGX-HMC. If not specified, the platform is derived from the node’s baseboard type. -
-j, --vendor_file <path>: Vendor JSON file for specific log collection. -
-S, --cids <id> [id ...]: Run specific collector IDs. Mutually exclusive with-g. -
-g, --loggroup <group>: Run collectors in a group:HealthCheck,Host,IPMI,Redfish,SSH. -
--debug: Runnvdebugin verbose mode.
-
-
stop: Stopsnvdebuglog collection on the specified nodes. The output includes the path to the (possibly incomplete) log file.Example
-
status: Shows the status ofnvdebuginstances. When run without-n, it lists all instances. While a collection is running,statusshows additional details such as CPU usage, memory, duration, and PID.Example
The
--jsonoption shows the raw JSON output. While active, additional fields are included:Example
-
history: Lists collectednvdebuglog files. When run without-n, it lists logs for all nodes. When a node is specified, it lists logs for that node only. For each collection run, only the archive file (.zip,.tar, and so on) is shown.Example
The
--jsonoption shows the raw JSON output:Example
-
version: Shows the installednvdebugversion.Example
-
list: Lists available collectors for a given platform. Requires the option:-t|--platform.Example
It has the options:
-
-t, --platform <type>: Required. Platform type:DGX,arm64,x86_64,NVSwitch,HGX-HMC. -
-g, --loggroup <group>: Filter by log group:HealthCheck,Host,IPMI,Redfish,SSH.
-