

Configuring The Cluster
After the NVIDIA Base Command Manager software has been installed on the head node, the cluster must be configured. For convenience, the regular nodes on the cluster use a default software image stored on the head node. The image is supplied to the regular nodes during a process called provisioning (Chapter 5), and both the head node and the regular nodes can have their software modified to suit exact requirements (Chapter 9). This chapter however goes through a number of basic cluster configuration aspects that are required to get all the hardware up and running on the head and regular nodes.
Section 3.1 explains how some of the main cluster configuration settings can be changed.
Section 3.2 details how the internal and external network parameters of the cluster can be changed.
Section 3.3 describes the setting up of network bridge interfaces.
Section 3.4 describes VLAN configuration.
Section 3.5 describes the setting up of network bond interfaces.
Section 3.6 covers how InfiniBand is set up.
Section 3.7 describes how Baseboard Management Controllers such as IPMI, iLO, DRAC, CIMC, and Redfish are set up.
Section 3.8 describes how switches are set up.
Section 3.9 describes how Cumulus switches are configured.
Section 3.11 describes how NetQ can be integrated with BCM.
Section 3.12 describes how UFM can be integrated with BCM.
Section 3.13 explains how disk layouts are configured, as well as how diskless nodes are set up.
Section 3.14 describes how NFS volumes are exported from an NFS server and mounted to nodes using the integrated approach of BCM.
Section 3.15 describes how services can be run from BCM.
Section 3.16 describes how a rack can be configured and managed with BCM.
Section 3.17 describes how GPUs can be configured with BCM.
Section 3.18 describes how sampling from a Prometheus exporter can be configured with BCM.
Section 3.19 describes how custom scripts can replace some of the default scripts in use.
Section 3.20 discusses configuration alternatives that are not based on CMDaemon.
Section 3.21 describes how the configuration files prior to a configuration change can be saved.
More elaborate aspects of cluster configuration such as power management, user management, package management, and workload management are covered in later chapters.
3.1 Main Cluster Configuration Settings
While both front ends—cmsh and Base View—can be used to carry out cluster management (Chapter 2), the BCM manuals often describe configuration with an arbitrary front end rather than for both front ends.
This is because the front ends are usually analogous enough to each other when carrying out a configuration procedure, so that describing the procedure for the other front end in detail as well is mostly wasteful. If the procedures differ significantly, then guidance is typically given on the differences.
Thus, for example, both cmsh and Base View can be used for the global configuration of cluster settings. For the cmsh front end, the configuration is done using partition mode. The analog to global configuration in the Base View front end relies on the navigation path: Cluster > Settings.
This section now continues with the Base View description.
The navigation path: Cluster > Settings brings up Base View’s cluster settings window (figure 3.1):
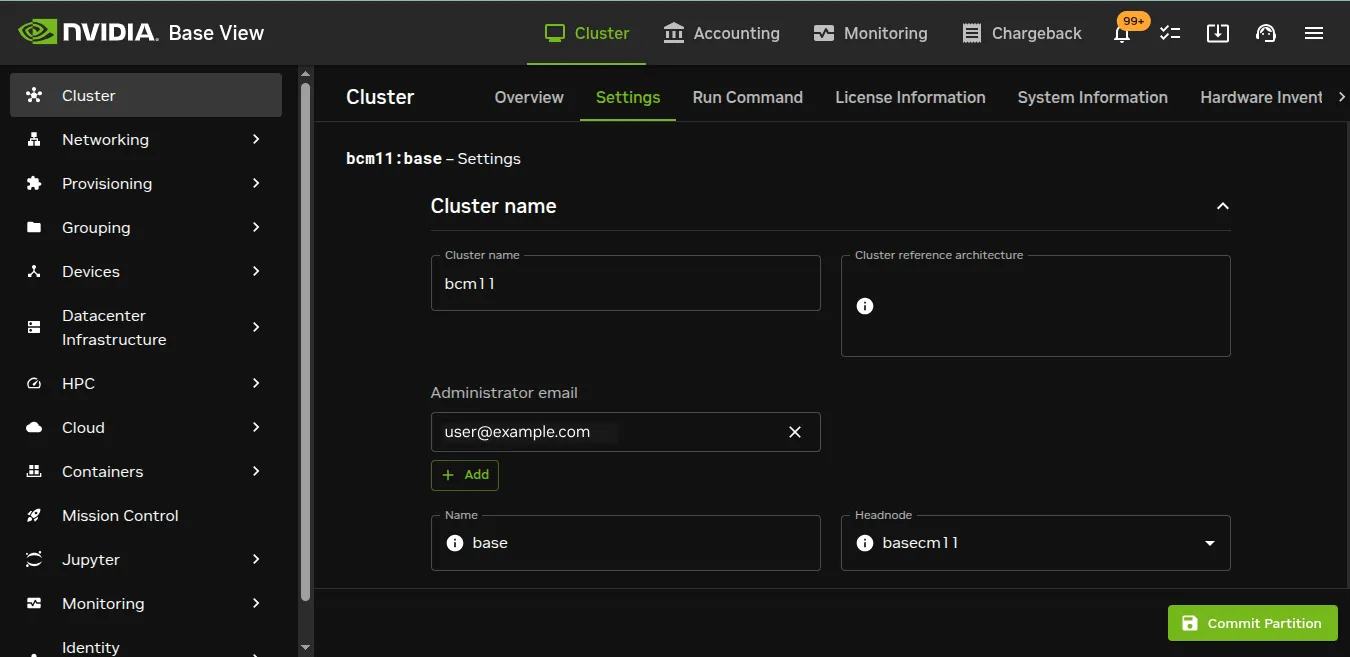
Figure 3.1: Cluster Settings
The navigational overview (here) indicates how the main cluster Settings window fits into the organizational layout of BCM.
The cluster Settings tab window allows changes to be made to many of the global cluster settings, typically using a grouping configuration that corresponds to the partition-level configuration in cmsh. The values that can be set for these global settings can in some cases be overridden by more specific configuration levels, such as (configuration-)overlay-level, category-level, or node-level configuration. The main cluster settings in figure 3.1 are about name-related settings, cluster networking settings, and some other miscellaneous global cluster settings.
3.1.1 Cluster Configuration: Various Cluster-wide Settings
In the Base View cluster Settings tab window of figure 3.1, the following cluster-wide settings can be viewed and modified:
-
Cluster name: Default value:BCM 11 Cluster. -
Administrator email: Default value: Specified during installation (figure 3.8 in Chapter 3 of the Installation Manual). -
Name servers: No default value, or picked up using DHCP. -
Time servers: Default values:0.pool.ntp.org,1.pool.ntp.org,2.pool.ntp.org. -
Search domains: No default value. -
Externally visible IP: Default value:0.0.0.0. -
Time zone: Default value: Specified during installation (figure 3.8 in Chapter 3 of the Installation Manual). -
BMC settings: This allows BMC and related settings to be managed.The following objects already exist by default on a new cluster, and can have their settings modified:
The following objects do not already exist by default on a new cluster, which means that clicking on them to configure them begins the process of creating the object, prompting the administrator to enter values for the object:
-
SELinux (Chapter 12 of the Installation Manual)
-
Access (section 3.9.1)
-
ZTP (section 3.9)
-
ZTP new switch
-
NetQ (section 3.11)
-
UFM (section 3.12)
-
NMX Manager (section 2.3 of the NVIDIA Mission Control Manual)
The BMC and related settings are described in their associated sections.
-
-
External network: Default value: as defined during selection of network topology during installation. TheManagement networkcan also be configured in this section.Management network: Default value: as defined during selection of network topology during installation.
Network topology selection during installation is covered in section 3.3.9 of the Installation Manual.
-
Default category: Default value:default. This value is inherited as the default object name forcategorymode. -
ArchOS: No default value. This specifies an architecture and OS. -
Sign installer certificates: Default value:AUTO. Described in section 5.4.1. -
Failover: No default value. -
Failover groups: No default value. -
Default burn configuration: Default value:default-destructive. -
Wlm job power usage settings: No default value. -
Leak action policies: Default value:Default building policy. -
Building Management System: Default value:NVIDIA-conforming BMS. -
Prometheus metric forwarders: No default value.
3.1.2 Cluster Configuration: Some Network-Related Settings
The following network-related settings are also described in the context of external network settings for the cluster object, in section 3.2.3, as well as in the quickstart in Chapter 1 of the Installation Manual.
3.1.2.1 Nameserver And Search Domains Used By Cluster
-
If Base View is used, then the settings window can be used to set the IP address of the nameserver and the names of the search domains for the cluster.
By default, the nameserver is the internal (regular-nodes-facing) IP address of the head node. Multiple nameservers can be added. If the value is set to
0.0.0.0, then the address supplied via DHCP to the head node is used. Alternatively, a static value can be set. Static IP addresses must be used for external addresses in the case of the cluster being configured with high availability. -
If
cmshis used instead of Base View, then the changes to thenameserverandsearchdomainvalues can instead be carried out viapartitionmode (here).
Limit to the number of search domains: In older versions of glibc (before 2.26), the number of names that can be set as search domains used by the cluster has a hardcoded maximum limit of 6, with a total of 256 characters.
From glibc 2.26 onward, this operating system limit no longer applies to normal lookups. BCM applies its own limit instead, using the MaximalSearchDomains GlobalConfig directive (Appendix C, here), which defaults to 64 search domains, and which can be set to any value from 1 to 1024.
Raising MaximalSearchDomains above 6 only has an effect on a cluster running glibc 2.26 or later. On an older glibc, only the first 6 configured search domains are used, regardless of the directive’s setting.
3.1.2.2 Changing The Order In resolv.conf
For clusters, CMDaemon by default automatically writes the /etc/resolv.conf by using the following sources, and in the following order:
-
Global network
-
Other networks
-
Category search domains
-
Partition search domains
Because older glibc versions only support 6 entries in /etc/resolv.conf, it is sometimes useful to exclude or reorder the preceding sources.
For a network object, there are two fields that control the position of the domain name in the file /etc/resolv.conf:
Example
If the Exclude from search domain field is set to yes, then the domain name for the network is not used.
The Search domain index field specifies the position of the domain name. A value of 0 means CMDaemon automatically determines its location.
The index of the category and partition search domains can also be changed by appending a number, in the suffix format : <index>, to the domain name:
Example
If an index is set for one search domain, then setting indices for all search domains is recommended. Search domains without indices are handled automatically by CMDaemon.
CMDaemon sorts all search domains according to index, and writes /etc/resolv.conf with the 6 that have the lowest index, with the lowest index first.
3.1.2.3 Setting The Stub Resolver For Ubuntu Hosts
For Ubuntu, CMDaemon generates a /etc/resolv.conf file (Appendix A), and symlinks it to the resolv.conf managed by systemd at /etc/run/systemd/resolve/resolve.conf.
However, a default Ubuntu without BCM uses a systemd stub resolver service (man systemd-resolved.8) that listens on the IP address 127.0.0.53. Sometimes a stub resolver is also useful in BCM for containers such as enroot containers (section 7.3.3) that mount and use /etc/resolv.conf.
To enable resolution for such containers on a node via the stub resolver instead of the uplink resolver, the resolver can be set using the extra resolve parameter, using the -e|--extra setting:
Example
3.1.2.4 Externally Visible IP Address
The externally visible IP address are public (non-RFC 1918) IP addresses to the cluster. These can be set to be visible on the external network.
-
If using Base View, the navigation path is:
Cluster>Settings>Externally visible IP. -
For
cmsh, the parameterexternallyvisibleipcan be set viapartitionmode.
3.1.2.5 Time server(s)
Time server hostnames can be specified for the NTP client on the head node.
-
If using Base View, the navigation path is via
Cluster>Settings>NAME SERVERS. -
For
cmsh, the parametertimeserverscan be set viapartitionmode.
3.1.2.6 Time Zone
The time zone setting can be set at various grouping levels:
If applied to the entire cluster, and if it is applied in partition mode, then:
-
In Base View, the time zone parameters can be jumped to via the navigation path:
Cluster>Settings>Time zone -
In
cmsh, the time zone can be selected inpartitionmode, using thebaseobject. Tab-completion prompting after entering “set timezone” displays a list of several hundred possible time zones, from which one can be chosen:Example
A time zone setting can also be applied at the level of a node, category, edge site, and cloud region. As is usual in the BCM hierarchy, the value set for the larger grouping is the default value used by the members of that group, while a value set specifically for the individual members of that group overrides such a default.
3.1.3 Miscellaneous Settings
3.1.3.1 BMC (IPMI/iLO, DRAC, CIMC, Redfish) Settings
Cluster > Settings > BMC Settings > This opens up a window so that the BMC settings can be managed:
-
User name: (default:bright) -
Password: (default: random string generated during head node installation) -
User ID: (default:4) -
Power reset delay: During a reset, this is the time, in seconds, that the machine is off, before it starts powering up again (default:0) -
Extra arguments: (default: none) -
privilege: (default:administrator)
The defaults in the preceding are set when the BMC interfaces are configured during head node installation. If the BMC interfaces are not set then, then the defaults are also unset.
BMC configuration is discussed in more detail in section 3.7.
3.1.3.2 Administrator E-mail Setting
By default, the distribution which BCM runs on sends e-mails for the administrator to the root e-mail address. The administrator e-mail address can be changed within BCM so that these e-mails are received elsewhere.
-
In Base View, an e-mail address (or space-separated addresses) can be set in the
Administrator e-mailfield via the navigation pathCluster>Settings>Administrator e-mail -
In
cmsh, the e-mail address (or space-separated addresses) can be set inpartitionmode, using thebaseobject as follows:Example
The following critical states or errors cause e-mails to be sent to the e-mail address:
-
By default, a month before the cluster license expires, a reminder e-mail is sent to the administrator account by CMDaemon. A daily reminder is sent if the expiry is due within a week.
-
A service on the head node that fails on its first ever boot.
-
When an automatic failover fails on the head or regular node.
3.1.3.3 SMTP Relay Host Mailserver Setting
The head node uses Postfix as its SMTP server. The default base distribution configuration is a minimal Postfix installation, and so has no value set for the SMTP relay host. To set its value:
-
in Base View: the
Relay Hostfield, with the navigation path:Cluster > Settings > Search domains > Relay Hostsets the SMTP relay host for the cluster resource.
-
in
cmsh: therelayhostproperty can be set for thebaseobject withinpartitionmode:Example
Postfix on the regular nodes is configured to use the head node as a relay host and is normally left untouched by the administrator.
If the regular node configuration for Postfix is changed due to a partition mode change, then a node reboot deploys the change for the node. Setting the AdvancedConfig (here) SmtpPartitionRelayHostInImages to 0 disables the changing of the relay host on the regular node.
Further Postfix changes can be done directly to the configuration files as is done in the standard distribution. The changes must be done after the marked auto-generated sections, and should not conflict with the auto-generated sections.
A convenient way to check mail is functioning is to run BCM’s testemail command. The command is run from within the main mode of cmsh. It sends a test e-mail out using CMDaemon:
The test e-mail destination is the administrator e-mail address discussed in the preceding section.
3.1.3.4 Failover Settings
To access options to the high availability (HA) feature of the cluster for head nodes, the administrator can click on the Failover option in Base View. This opens up a subwindow that can be used to configure HA-related parameters (section 15.4.6).
3.1.3.5 Failover Groups Settings
To access options to the high availability feature of the cluster for groups of regular nodes, the administrator can click on the Failover groups option in Base View. This opens up a subwindow that can be used to configure failover-groups-related parameters (section 15.5).
3.1.3.6 Burn Configs
Burning nodes is covered in Chapter 11 of the Installation Manual. Burn configuration settings for the cluster can be accessed in Base View via the following navigation paths:
-
Cluster > Settings > Default burn configurationThis allows the
Default burn configurationfor a node burn run to be modified. -
Cluster > Settings > Burn configsThis lists the possible burn configuration settings in a subwindow, and allows changes to some of their properties of each item of the list.
3.1.3.7 FIPS Mode
To be compliant with the Federal Information Processing Standards of the USA, Linux-based systems are required to follow some security standards. This is known as FIPS compliance.
FIPS compliance on regular nodes can be set per node or per category.
The existing FIPS status can be checked with the sysinfo command at node level:
Example
Or even just with a get:
Example
FIPS can be enabled per node:
Example
FIPS can be enabled per category:
Example
As is usual in BCM, the node-level setting overwrites the category-level setting.
Setting FIPS compliance on the head node itself via CMDaemon is not allowed. This is because FIPS GRUB configuration could, in some unusual cases, result in an unbootable head node. The cluster administrator must consider the existing state of the head node with due care before manually re-configuring it for FIPS.
3.1.4 Limiting The Maximum Number Of Open Files
3.1.4.1 Configuring The System Limit On Open Files: The /proc/sys/fs/file-max Setting
The maximum number of open files allowed on a running Linux operating system is determined by /proc/sys/fs/file-max. To configure this setting so that it is persistent, the Linux operating system uses a /etc/sysctl.conf file and *.conf files under /etc/sysctl.d/. Further information on these files can be found via the man page, man sysctl.conf.5. BCM adheres to this standard method, and places a settings file 90-cm-sysctl.conf in the directory /etc/sysctl.d.
By default, the value set for file-max by NVIDIA Base Command Manager is 131072. An on-premises head node typically is not used to run applications that exceed this value, and the settings file 90-cm-sysctl.conf is therefore not available for modification by the CMDaemon front ends (cmsh and Base View). For edge and cloud director installations, the installation scripts take care of modifying file-max since such installations can have many more open files. Cluster administrators are thus not expected to have a need to modify the value of file-max in most use cases.
However, if there is a need to modify the value of file-max, then a subsequent, extra, configuration file, such as /etc/sysctl.d/91-site-sysctl-file-max-tweak.conf can be added under /etc/sysctl.d/, so that the BCM version is not intefered with directly.
3.1.4.2 Configuring The User Limit On Open Files: The nofile Setting
The maximum number of open files allowed for a user can be seen on running ulimit -n. The value is defined by the nofile parameter of ulimit.
By default the value set by BCM is 131072.
Ulimit limits are limits to restrict the resources used by users. If the pam_limits.so module is used to apply ulimit limits, then the resource limits can be set via the /etc/security/limits.conf file and *.conf files in the /etc/security/limits.d directory. Further information on these files can be found via the man page, man limits.conf.5.
Resource limits that can be set for user login sessions include the number of simultaneous login sessions, the number of open files, and memory limits.
The maximum number of open files for a user is unlimited by default for an operating system that is not managed by BCM. However, it is set to 131072 by default for a system managed by BCM. The nofile value is defined by BCM in:
-
in
/etc/security/limits.d/91-cm-limits.confon the head node -
in
/cm/images/<software image name>/etc/security/limits.d/91-cm-limits.confin the software image that the regular node picks up.
The values set in 91-cm-limits.conf are typically sufficient for a user session, unless the user runs applications that are resource hungry and consume a lot of open files.
3.1.4.3 Deciding On Appropriate Ulimit, Limit, And System Limit Values
Decreasing the nofile value in /etc/security/limits.d/91-cm-limits.conf (but leaving the /proc/sys/fs/file-max untouched), or increasing /proc/sys/fs/file-max (but leaving the nofile value of 131072 per session as is), may help the system stay under the maximum number of open files allowed.
In general, users should not be allowed to use the head node as a compilation server, or as a test bed, before running their applications. This is because user errors can unintentionally cause the head node to run out of resources and crash it.
Depending what is running on the server, and the load on it, the administrator may wish to increase the resource limit values.
A very rough rule-of-thumb that may be useful as a first approximation to set file-max optimally is suggested in the kernel source code. The suggestion is to simply multiply the system memory (in MB) by 10 per MB, and make the resulting number the file-max value. For example, if the node has 128 GB of memory, then 1280000 can be set as the file-max value.
Fine-tuning to try and ensure that the operating system no longer runs out of file handles, and to try and ensure the memory limits for handling the load are not exceeded, is best achieved via an empirical trial-and-error approach.
3.2 Network Settings
A simplified quickstart guide to setting up the external head node network configuration on a vendor-prepared cluster is given in Chapter 6 of the Installation Manual. This section (3.2) covers network configuration more thoroughly.
After the cluster is set up with the correct license as explained in Chapter 4 of the Installation Manual, the next configuration step is to define the networks that are present (sections 3.2.1 and 3.2.2).
During BCM installation at least three default network objects were created:
internalnet: the primary internal cluster network, and the default management network. This is used for booting non-head nodes and for all cluster management communication. In the absence of other internal networks, internalnet is also used for storage and communication between compute jobs. Changing the configuration of this network is described here under the subheading “Changing Internal Network Parameters For The Cluster”.
externalnet: the network connecting the cluster to the outside world (typically a corporate or campus network). Changing the configuration of this network is described here under the subheading “Changing External Network Parameters For The Cluster”. This is the only network for which BCM also supports IPv6.
globalnet: the special network used to set the domain name for nodes so that they can be resolved whether they are cloud nodes or not. This network is described further here under the subheading “Changing The Global Network Parameters For The Cluster”.
For a Type 1 cluster (section 3.3.9 of the Installation Manual) the internal and external networks are illustrated conceptually by figure 3.2.
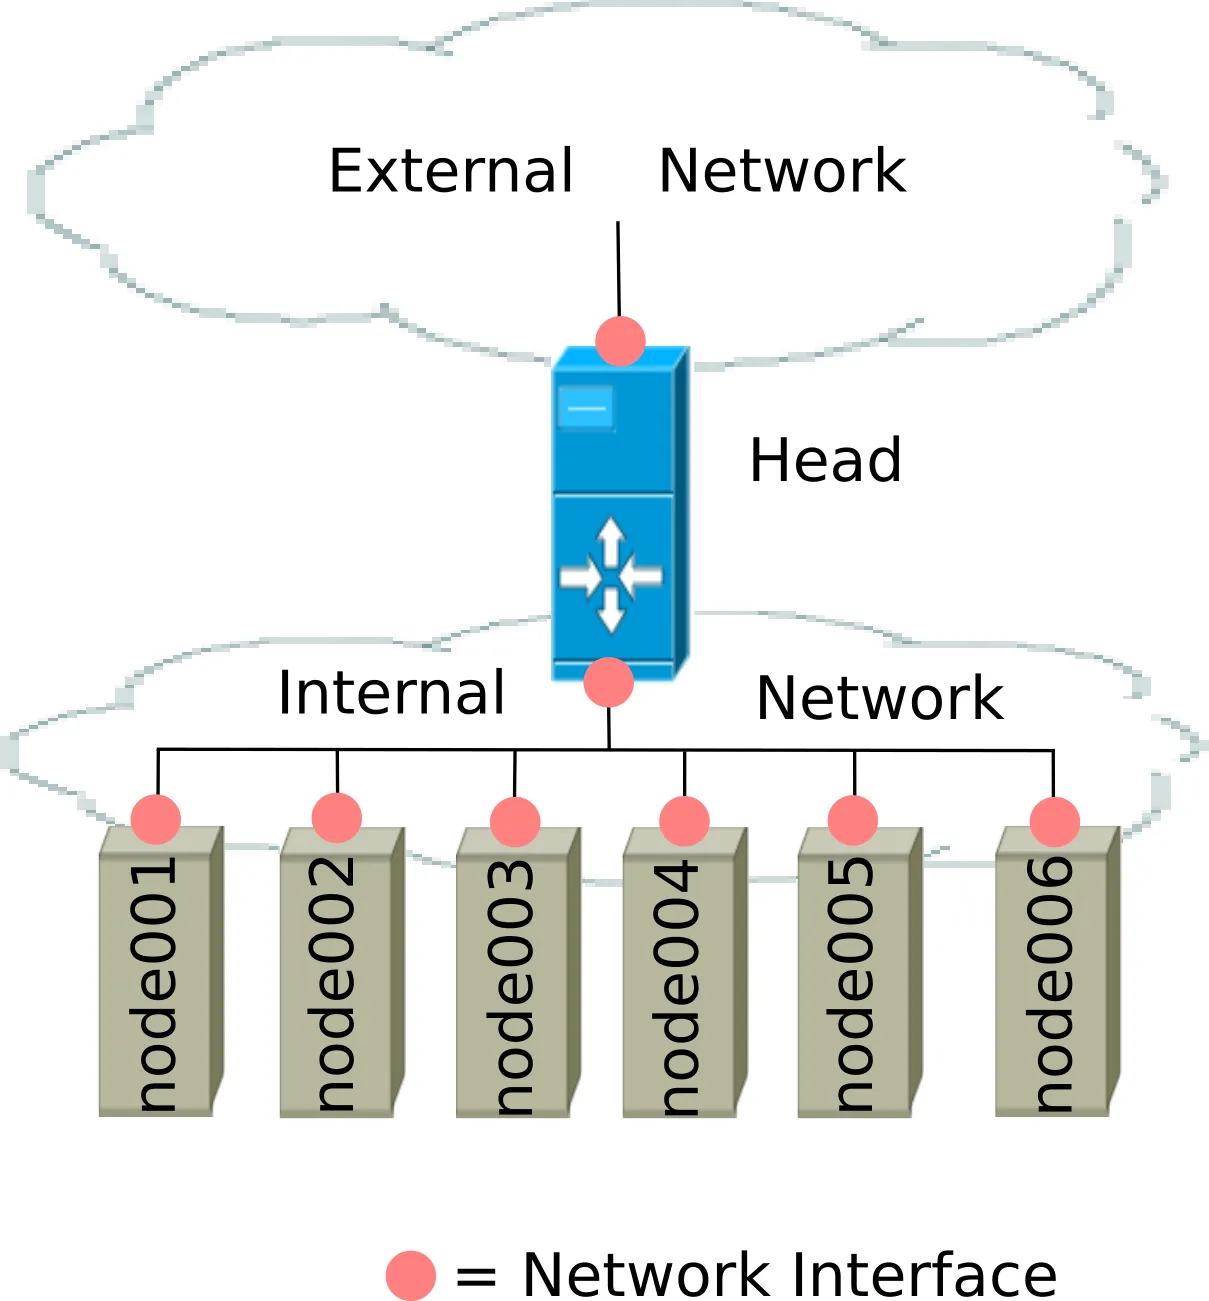
Figure 3.2: Network Settings Concepts
The configuration of network settings is completed when, after having configured the general network settings, specific IP addresses are then also assigned to the interfaces of devices connected to the networks.
-
Changing the configuration of the head node external interface is described here under the subheading “The IP address of the cluster”.
-
Changing the configuration of the internal network interfaces is described here under the subheading “The IP addresses and other interface values of the internal network”.
-
Changing the configuration of
globalnetis described here under the subheading “Changing The Global Network Parameters For The Cluster”. IP addresses are not configured at theglobalnetnetwork level itself.
3.2.1 Configuring Networks
The network mode in cmsh gives access to all network-related operations using the standard object commands. Section 2.5.3 introduces cmsh modes and working with objects.
In Base View, a network can be configured via the navigation path Networking > Networks, which opens up the Network list subwindow (figure 3.3):
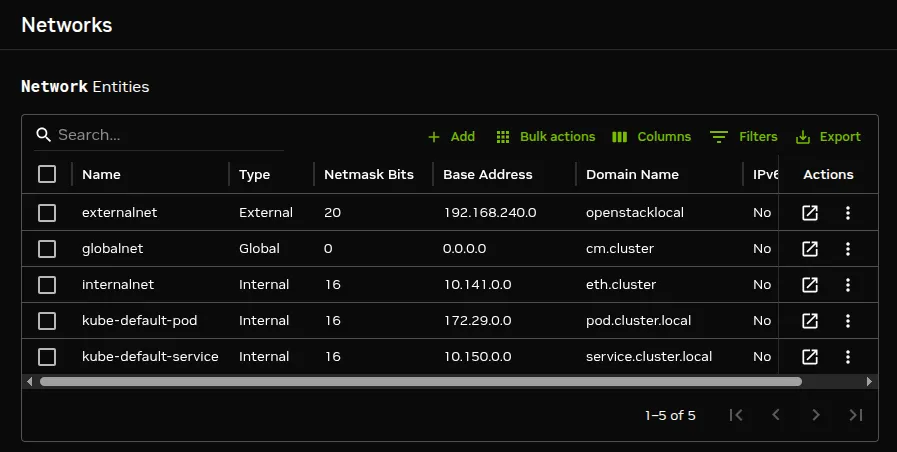
Figure 3.3: Networks
In the context of the OSI Reference Model, each network object represents a layer 3 (i.e. Network Layer) IP network, and several layer 3 networks can be layered on a single layer 2 network (e.g. routes on an Ethernet segment).
Opening up the subwindow for a network such as internalnet or externalnet brings up the Devices Overview tab window, which lists the devices on the network and associated properties. For example, the internal network typically has some nodes and other devices attached to it, each with their IP addresses and statuses (figure 3.4).
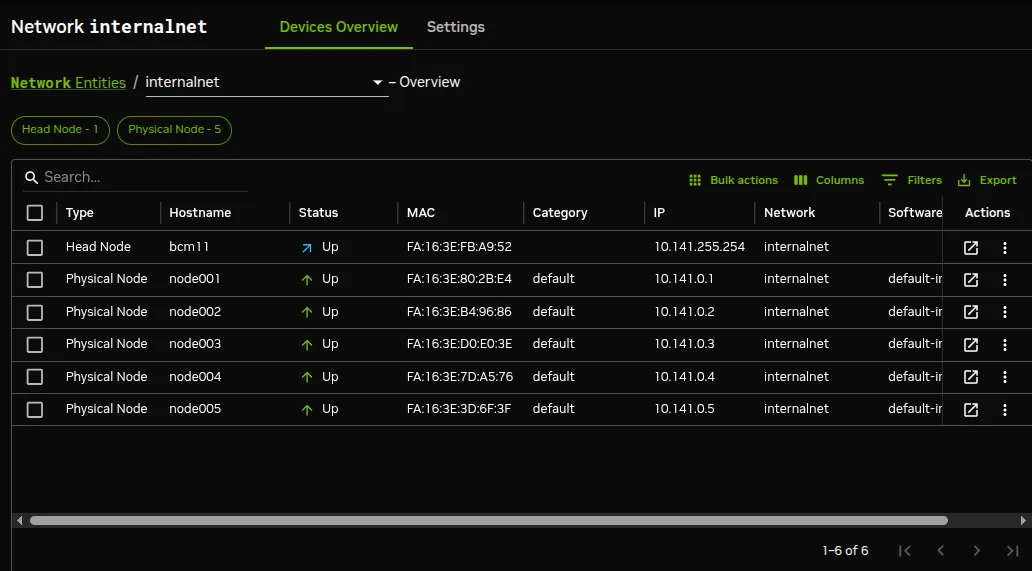
Figure 3.4: Network Overview
Selecting the Settings tab window opens a scrollable pane that allows a number of network properties to be changed (figure 3.5).
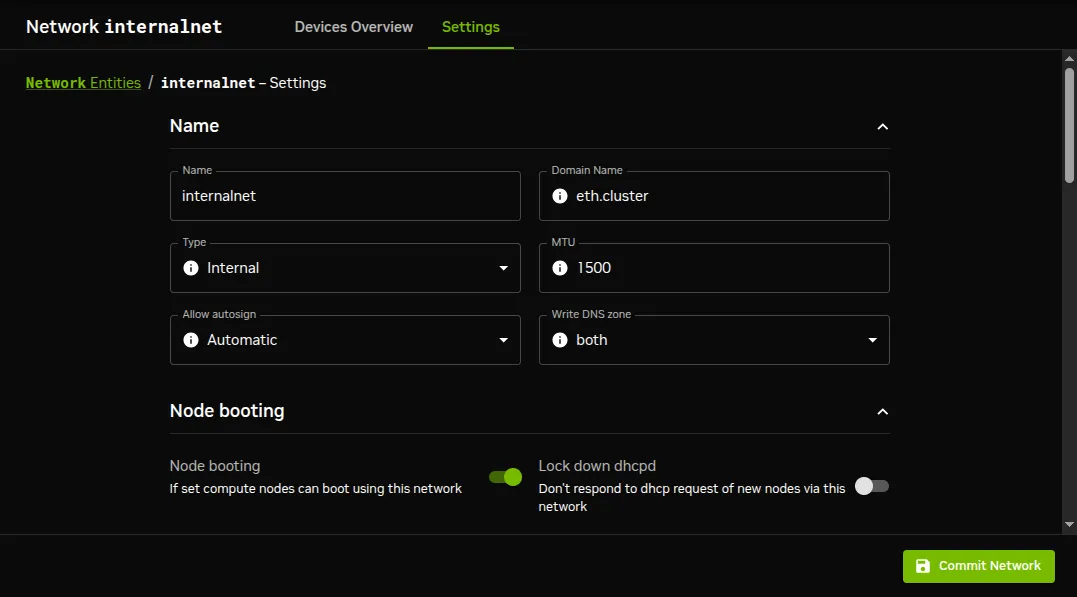
Figure 3.5: Network Settings
The properties of figure 3.5 are introduced in table 3.1:
Table 3.1: Network Configuration Settings
3.2.1.1 Basic Networking Concepts And The sipcalc Utility
In basic networking concepts, a network is a range of IP addresses. The first address in the range is the base address. The length of the range, i.e. the subnet, is determined by the netmask, which uses CIDR notation. CIDR notation is the so-called / (“slash”) representation, in which, for example, a CIDR notation of 192.168.0.1/28 implies an IP address of 192.168.0.1 with a traditional netmask of 255.255.255.240 applied to the 192.168.0.0 network. The netmask 255.255.255.240 implies that bits 28–32 of the 32-bit dotted-quad number 255.255.255.255 are unmasked, thereby implying a 4-bit-sized host range of 16 (i.e. 2[4]) addresses.
The sipcalc utility can be installed on the head node, and is a useful tool for calculating or checking such IP subnet values (man sipcalc.1 or sipcalc -h for help on this utility):
Example
3.2.1.2 DNS Domains And Zones
Every network has an associated DNS domain which can be used to access a device through a particular network. For internalnet, the default DNS domain is set to eth.cluster, which means that the hostname node001.eth.cluster can be used to access device node001 through the primary internal network. If a dedicated storage network has been added with DNS domain storage.cluster, then node001.storage.cluster can be used to reach node001 through the storage network. Internal DNS zones are generated automatically based on the network definitions and the defined nodes on these networks. For networks marked as external, no DNS zones are generated.
3.2.1.3 Layer 3 Properties
Setting the layer 3 properties of table 3.1 with set layer3 yes configures the nodes in the (main) network range to be routed by a switch with layer 3 features. The default netmask when layer3 is set to yes is /31 (255.255.255.254) for each device and switch port pair in the subnets that are created by this setting, while routing stays defined by the netmask of the (main) network, and the routing is handled by the layer 3 features of the switch.
The netmask for layer 3 networking can be set to /30 with set -e layer3bits 30. This is needed for some DataDirect Networks switches.
3.2.2 Adding Networks
Once a network has been added, it can be used in the configuration of network interfaces for devices.
In Base View the Add button in the Networks subwindow (figure 3.3) can be used to add a new network. After the new network has been added, the Settings pane (figure 3.5) can be used to further configure the newly-added network.
In cmsh, a new network can be added from within network mode using the add or clone commands.
The default assignment of networks (internalnet to Management network and externalnet to External network) can be changed using Base View, via the Settings window of the cluster object, which uses the navigation path:
Cluster > Settings > External network > {External network|Management network}
In cmsh the assignment to Management network and External network can be set or modified from the base object in partition mode:
Example
3.2.3 Changing Network Parameters
After both internal and external networks are defined, it may be necessary to change network-related parameters from their original or default installation settings.
3.2.3.1 Changing The Head Or Regular Node Hostname
To reach the head node from inside the cluster, the alias master may be used at all times. Setting the hostname of the head node itself to master is not recommended.
The name of a cluster is sometimes used as the hostname of the head node. The cluster name, the head node hostname, and the regular node hostnames, all have their own separate names as a property of their corresponding objects. The name can be changed in a similar manner for each.
For example, to change the hostname of the head node, the device object corresponding to the head node must be modified.
-
In Base View, the navigation path for modifying the host name is
Devices > All Devices > Head Node > > Settings > Hostname > Commit HeadNode. That is, under theDevicesresource, theAll Devicesoption is selected. The head node is selected from the devices displayed, and its subwindow-opening box in theActionscolumn is then clicked. This opens the device overview pane. TheSettingsoption can then be selected. TheHostnamerecord can then be modified (figure 3.6), and saved by clicking on theCommit HeadNodeicon. When setting a hostname, a domain is not included.After the change, as suggested by Base View, the head node must be rebooted.
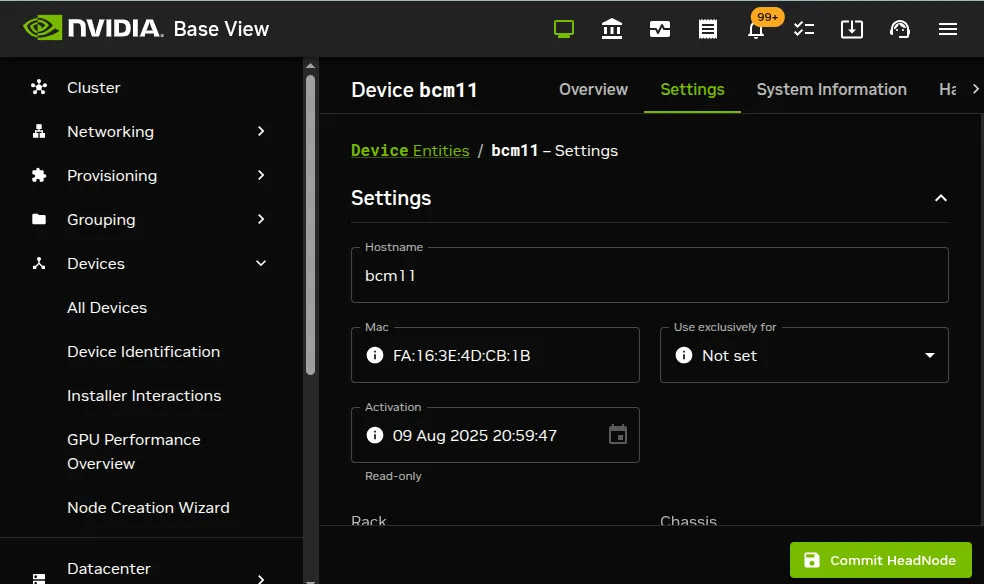
Figure 3.6: Head Node Settings
-
In
cmsh, the hostname of the head node can also be changed, via device mode:Example
The prompt string shows the new hostname after a short time, when a new shell is started.
After the hostname has been set, as suggested by
cmsh, the head node must be rebooted.
3.2.3.2 Adding Hostnames To The Internal Network
Additional hostnames, whether they belong to the cluster nodes or not, can be added as name/value pairs to the /etc/hosts file(s) within the cluster. This should be done only outside the specially-marked CMDaemon-managed section. It can be done to the file on the head node, or to the file on the software image for the regular nodes, or to both, depending on where the resolution is required.
However, for hosts that are on the internal network of the cluster, such as regular nodes, it is easier and wiser to avoid adding additional hostnames via /etc/hosts.
Instead, it is recommended to let BCM manage host name resolution for devices on the internalnet through its DNS server on the internalnet interface. The host names can be added to the additionalhostnames object, from within interfaces submode for the head node. The interfaces submode is accessible from the device mode. Thus, for the head node, with eth1 as the interface for internalnet:
Example
Multiple hostnames can be added as space-separated entries.
The named service automatically restarts within about 20 seconds after committal, implementing the configuration changes. This kind of restart is a feature (section 3.15.1) of changes made to service configurations by Base View or cmsh.
3.2.3.3 Changing External Network Parameters For The Cluster
The external network parameters of the cluster: When a cluster interacts with an external network, such as a company or a university network, its connection behavior is determined by the settings of two objects: firstly, the external network settings of the Networks resource, and secondly, by the cluster network settings.
-
The external network object contains the network settings for all objects configured to connect to the external network, for example, a head node. Network settings are configured in Base View under the
Networkingresource, then under theNetworkssubwindow, then within theSettingsoption for a selected network. Figure 3.5 shows a settings window for when theinternalnetitem has been selected, but in the current case theexternalnetitem must be selected instead. The following parameters can then be configured:-
the IP network parameters of the cluster (but not the IP address of the cluster):
-
Base address: the network address of the external network (the “IP address of the external network”). This is not to be confused with the IP address of the cluster, which is described shortly after this. -
Broadcast address: the broadcast address of the external network. This should not be confused with the broadcast IP address of the internal network. -
Dynamic range startandDynamic range end: Not used by the external network configuration. -
Netmask bits: the netmask size, or prefix-length, of the external network, in bits. -
Gateway: the default route for the external network.
-
-
the
network name(what the external network itself is called), by default this is defined asexternalnetin the base partition on a newly installed Type 1 cluster, -
the
Domain Name: the network domain (LAN domain, i.e. what domain machines on the external network use as their domain), -
the
External networkcheckbox: this is checked for a Type 1 cluster, -
and MTU size (the maximum value for a TCP/IP packet before it fragments on the external network—the default value is 1500).
-
-
The cluster object contains other network settings used to connect to the outside. These are configured in Base View using the navigation path:
Cluster > Settingsand are described in section 3.1.1:
-
e-mail address(es) for the cluster administrator,
-
any additional external name servers used by the cluster to resolve external host names. As an aside: by default, only the head node name server is configured, and by default it only serves hosts on the internal network via the internal interface. Enabling the
PublicDNSdirective (Appendix C.54) allows the head node name server to resolve queries about internal hosts from external hosts via any interface, including the external interface. -
the DNS search domain (what the cluster uses as its domain),
-
and NTP time servers (used to synchronize the time on the cluster with standard time) and time zone settings.
These settings can also be adjusted in
cmshin thebaseobject underpartitionmode. -
Changing the networking parameters of a cluster (apart from the IP address of the cluster) therefore requires making changes in the settings of the two preceding objects.
Adding custom DNS zones: BCM appends a BIND DNS include directive to the bottom of the head node name server’s generated configuration file, so that administrator-defined DNS zones are preserved across regeneration. The path of both files depends on the distribution:
-
on Ubuntu:
-
configuration file
/etc/bind/named.conf -
include file
/etc/bind/named.conf.include
-
-
on RHEL 9/10 and SLES 15:
-
configuration file
/etc/named.conf -
include file
/etc/named.conf.include
-
Custom zone definitions placed in the include file are not touched by BCM. The zone file itself can be placed in any directory the administrator chooses; it is not tied to the distribution-specific named.conf/include file paths in the preceding. For example:
Example
These and other related BIND DNS files that are managed by CMDaemon on the head node are listed in Appendix A.1.
By default, the head node name server only resolves such zones for queries from the internal network. To resolve them from other networks, the PublicDNS directive (Appendix C.54) must also be set to true.
The IP address of the cluster: The cluster object itself does not contain an IP address value. This is because it is the cluster network topology type that determines whether a direct interface exists from the cluster to the outside world. Thus, the IP address of the cluster in the Type 1, Type 2, and Type 3 configurations (section 3.3.9 of the Installation Manual) is defined by the cluster interface that faces the outside world. For Type 1, this is the interface of the head node to the external network (figure 3.2). For Type 2 and Type 3 interfaces the cluster IP address is effectively that of an upstream router, and thus not a part of BCM configuration. Thus, logically, the IP address of the cluster is not a part of the cluster object or external network object configuration.
For a Type 1 cluster, the head node IP address can be set in BCM, separately from the cluster object settings. This is then the IP address of the cluster according to the outside world.
Setting the network parameters of the cluster and the head node IP address: These values can be set using Base View or cmsh:
-
With Base View:
The cluster network object and associated settings are accessed as follows:
The external network object:
The external network object is accessed via the navigation path:
Networking > Networks > externalnet > > Settingswhich reaches the window shown in figure 3.7:
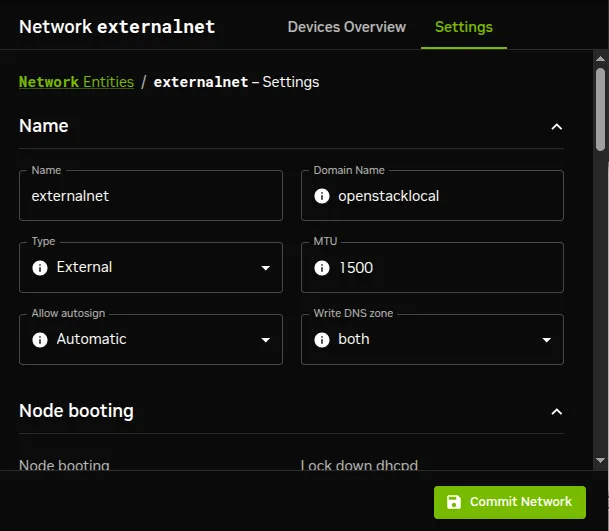
Figure 3.7: Network Settings For External Network
The cluster object:
The cluster object and associated settings are accessed using the navigation path:
Cluster > Settings
The head node IP address: For a head node basecm11, where the IP address is used by the interface eth0, the static IP address can be set via the navigation path:
Devices > All Devices > Head Node > > Settings > Interfaces > > eth0 > > IP
as seen in figure 3.8.
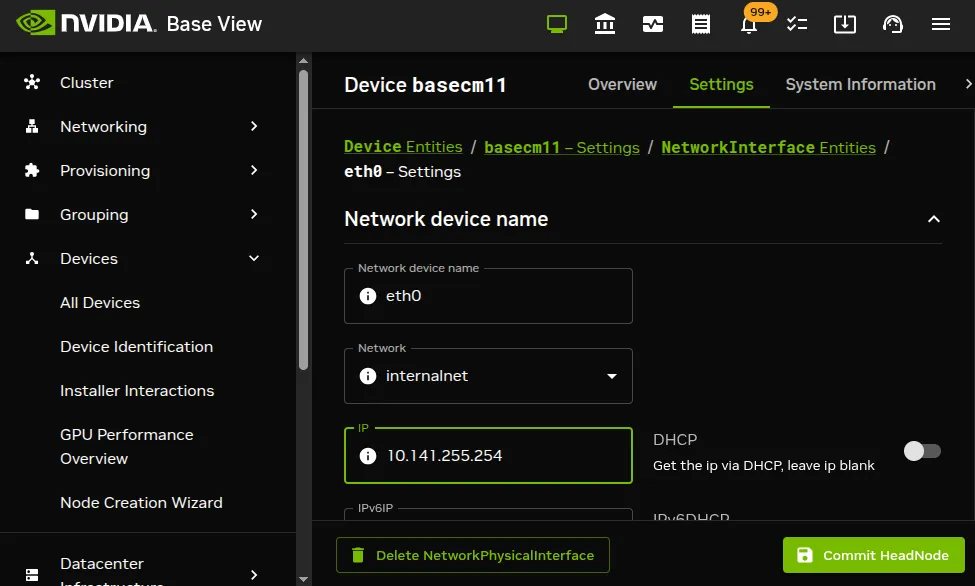
Figure 3.8: Setting The IP Address On A Head Node In Base View
-
With
cmsh:The preceding Base View configuration can also be done in
cmsh, using thenetwork,partitionanddevicemodes, as in the following example:Example
After changing the external network configurations, a reboot of the head node is necessary to activate the changes.
Using DHCP to supply network values for the external interface:
Connecting the cluster via DHCP on the external network is not generally recommended for production clusters. This is because DHCP-related issues can complicate networking troubleshooting compared with using static assignments.
For a Type 1 network, the cluster and head node can be made to use some of the DHCP-supplied external network values as follows:
-
In Base View, the DHCP setting of figure 3.8 can be set to
Enabled -
Alternatively, in
cmsh, within interfaces mode for the head node interface, the value of the parameter DHCP can be set:
The gateway address, the name server(s), and the external IP address of the head node are then obtained via a DHCP lease. Time server configuration for externalnet is not picked up from the DHCP server, having been set during installation (figure 3.8 in Chapter 3 of the Installation Manual). The time servers can be changed using Base View using the navigation path:
Cluster > Settings > Time servers
(figure 3.1), or using cmsh in partition mode as in the preceding example. The time zone can be changed similarly.
It is usually sensible to reboot after implementing these changes in order to test the changes are working as expected.
3.2.3.4 Changing Internal Network Parameters For The Cluster
When a cluster interacts with the internal network that the regular nodes and other devices are on, its connection behavior with the devices on that network is determined by settings in:
-
the internal network of the
Networksresource (here) -
the cluster network for the internal network (here)
-
the individual device network interface (here)
-
the node categories network-related items for the device (here), in the case of the device being a regular node.
In more detail:
1. The internal network object: has the network settings for all devices connecting to the internal network, for example, a login node, a head node via its internalnet interface, or a managed switch on the internal network. In Base View, the settings can be configured under the Networking resource, then under the Networks subwindow, then within the Settings option for the internalnet item (figure 3.5). In cmsh the settings can be configured by changing the values in the internalnet object within cmsh’s network mode. Parameters that can be changed include:
-
the IP network parameters of the internal network (but not the internal IP address):
-
the “
domain name” of the network. This is the LAN domain, which is the domain machines on this network use as their domain. By default, set to a name based on the network interface type used on the internal network, for exampleeth.cluster. In any case, the FQDN must be unique for every node in the cluster. -
the network name, or what the internal network is called. By default, set to
internalnet. -
The
MTUsize, or the maximum value for a TCP/IP packet before it fragments on this network. By default, set to 1500.
2. The cluster object: has other network settings that the internal network in the cluster uses. These particulars are configured in the Settings option of the cluster object resource in Base View (figure 3.1). The cmsh equivalents can be configured from the base object in partition mode. Values that can be set include:
-
the “
Management network”. This is the network over which CMDaemon manages the nodes. Management means that CMDaemon on the head node communicates with CMDaemons on the other nodes. The communication includes CMDaemon calls and monitoring data. By default, the management network is set tointernalnetfor Type 1 and Type 2 networks, andmanagementnetin Type 3 networks. It is a partition-level cluster-wide setting by default. Partition-level settings can be overridden by the category level setting, and node-level settings can override category level or partition level settings. -
the “
Node name” can be set to decide the prefix part of the node name. By default, set tonode. -
the “
Node digits” can be set to decide the possible size of numbers used for suffix part of the node name. By default, set to3. -
the “
Default category”. This sets the category the nodes are in by default. By default, it is set todefault. -
the “
Default software image”. This sets the image the nodes use by default, for new nodes that are not in a category yet. By default, it is set todefault-image. -
the “
Name server”. This sets the name server used by the cluster. By default, it is set to the head node. The default configuration uses the internal network interface and serves only internal hosts. Internal hosts can override using this value at category level (here). By default external hosts cannot use this service. To allow external hosts to use the service for resolving internal hosts, thePublicDNSdirective (Appendix C.54) must be set toTrue.
3. The internal IP addresses and other internal interface values: In Base View, the network for a node, such as a physical node node001, can be configured via a navigation path
Devices > All Devices > Physical Node > > Settings > Interfaces > BOOTIF >
The subwindow that opens up then allows network configuration to be done for such nodes in a similar way to figure 3.8. In cmsh the configuration can be done by changing properties from the interfaces submode that is within the device mode for the node.
The items that can be set include:
-
the
Network device name: By default, this is set toBOOTIFfor a node that boots from the same interface as the one from which it is provisioned. -
the
Network: By default, this is set to a value ofinternalnet. -
the
IPaddress: By default, this is automatically assigned a static value, in the range10.141.0.1to10.141.255.255, with the first node being given the first address. Using a static IP address is recommended for reliability, since it allows nodes that lose connectivity to the head node to continue operating. The static address can be changed manually, in case there is an IP address or node ID conflict due to an earlier inappropriate manual intervention.Administrators who want DHCP addressing on the internal network, despite the consequences, can set it via a checkbox.
-
onnetworkpriority: This sets the priority of DNS resolution queries for the interface on the network. The range of values that it can take is from 0 to 4294967295. Resolution takes place via the interface with the higher value.The default priority value for a network interface is set according to its type. These defaults are:
-
Additional Hostname: In the case of nodes this is in addition to the default node name set during provisioning. The node name set during provisioning takes a default form ofnode<3 digit number>, as explained earlier here in the section describing the cluster object settings.
For, example, a regular node that has an extra interface, eth1, can have its values set as follows:
Example
4. Node category network values: are settings for the internal network that can be configured for node categories. For example, for the default category called default this can be carried out:
-
via Base View, using the
Settingsoption for the category. This is in the navigation pathGrouping > Categories > > Settings -
or via the
categorymode incmsh, for thedefaultnode category.
If there are individual node settings that have been configured in Base View or cmsh, then the node settings override the corresponding category settings for those particular nodes.
The category properties involved in internal networking that can be set include:
-
Default gateway: The default gateway route for nodes in the node category. If unset, or 0.0.0.0 (the default), then the node default gateway route is decided by the internal network objectGatewayvalue. If the default gateway is set as a node category value, then nodes use the node category value as their default gateway route instead. -
Management network: The management network is the network used by CMDaemon to manage devices. The default setting is a property of the node object. It can be set as a category property. -
Name server,Time server,Search domain: The default setting for these on all nodes is set by the node-installer to refer to the head node, and is not configurable at the node level using Base View orcmsh. The setting can however be set as a category property, either as a space-separated list of entries or as a single entry, to override the default value.
Application to generic network devices: The preceding details for the internal network parameters of the cluster, starting from here, are applicable to regular nodes, but they are often also applicable to generic network devices (section 2.1.1). Benefits of adding a generic device to be managed by BCM include that:
-
the name given to the device during addition is automatically placed in the internal DNS zone, so that the device is accessible by name
-
the device status is automatically monitored via an ICMP ping (Appendix G.2.1).
-
the device can be made to work with the health check and metric framework. The scripts used in the framework will however almost certainly have to be customized to work with the device
After changing network configurations, a reboot of the device is necessary to activate the changes.
3.2.3.5 Changing The Global Network Parameters For The Cluster
The global network globalnet is a unique network used to set up a common name space for all nodes in a cluster in BCM. It is required in BCM because of the added cloud extension functionality, described in the Cloudbursting Manual. Regular nodes and regular cloud nodes are thus both named under the globalnet domain name, which is cm.cluster by default. So, for example, if default host names for regular nodes (node001, node002, …) and regular cloud nodes (cnode001, cnode002, …) are used, node addresses with the domain are:
-
node001.cm.cluster for node001
-
cnode001.cm.cluster for cnode001
The only parameter that can be sensibly changed on globalnet is the domain name, which is cm.cluster by default.
Removing globalnet should not be done because it will cause various networking failures, even for clusters deploying no cloud nodes.
Details on how resolution is carried out with the help of globalnet are given in section 6.6.1 of the Cloudbursting Manual.
3.2.3.6 Setting Static Routes In The staticroutes Submode Of cmsh
To route via a specific gateway, the staticroutes submode can be used. This can be set for regular nodes and head nodes via the device mode, and for node categories via the category mode.
On a newly-installed cluster with a type 1 network (section 3.3.9 of the Installation Manual), a node by default routes packets using the head node as the default gateway.
If the administrator would like to configure a regular node to use another gateway to reach a printer on another subnet, as illustrated by figure 3.9:
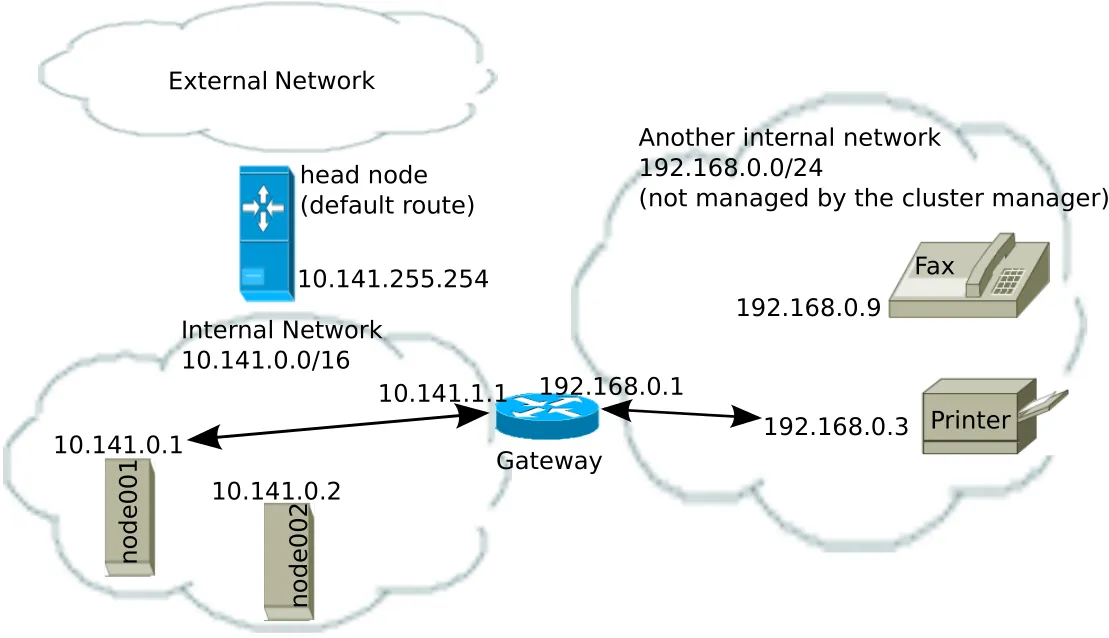
Figure 3.9: Example Of A Static Route To A Printer On Another Subnet
then an example session for setting the static route is as follows:
Example
In the preceding example, the regular node node001, with IP address 10.141.0.1 can connect to a host 192.168.0.3 outside the regular node subnet using a gateway with the IP addresses 10.141.1.1 and 192.168.0.1. The route is given the arbitrary name printerroute for administrator and CMDaemon convenience, because the host to be reached in this case is a print server. The networkdevicename is given the interface name bootif. If another device interface name is defined in CMDaemon, then that can be used instead. If there is only one interface, then networkdevicename need not be set.
After a reboot of the node, the route that packets from the node follow can be seen with a traceroute or similar. The ping utility with the -R option can often track up to 9 hops, and can be used to track the route:
Example
The routing is achieved by CMDaemon making sure that whenever the network interface is brought up, the OS of the regular node runs a routing command to configure the routing tables. The command executed for the given example is either:
or its modern iproute2 equivalent:
If the device bootif is eth0—which is often the case—then the command is run from the network interface configuration file: /etc/sysconfig/network-scripts/ifcfg-eth0 (or /etc/sysconfig/network/ifcfg-eth0 in SUSE).
If the device is a head node: then rebooting it to have the new route become active is a clean way to implement the change. However doing this may not be acceptable to cluster users due to the downtime, and the associated interruption of jobs. A quicker update to the interface that should work is using operating system networking scripts. For example, if the interface with the route is eth0, then the interface can be brought down and up again with ifdown eth0 && ifup eth0. If the various networking configurations have been applied in a way that persists over reboots, then they should be applied automatically to the interface as it starts up.
3.2.3.7 Port Forwarding With portforward
Why port forwarding is useful: In a typical type 1 network setup (section 3.3.9 of the Installation Manual), only the head nodes are accessible from the external network. So, the compute nodes cannot be accessed directly from the external network.
Accessing a compute node port may however be needed for some workflows. For example, a user on a laptop on the external network may wish to access a compute node port directly.
To allow this direct access to a compute node port, port forwarding rules can be set up from within the device mode of cmsh. Configuring port forwarding with BCM is designed to be easier than doing port forwarding directly in the operating system.
The port forwarding help text: The help text for the portforward command summarizes how to use it:
An illustration of port forwarding working: The following example indicates how BCM port forwarding works. A laptop user on the external network may wish to connect to port 1234 on compute node node001 by connecting to the head node port 4321. There is no port 4321 open on the head node to start with, until a portforward command is run:
Example
The connections command is described here.
In the background on the active head there is a new socat process that is created for each port forward:
The socat process forwards any packets from external network interface of the head node to the internal network interface of the compute node, as illustrated by the following ASCII diagram:
The forwarding can be tested by setting up a netcat listening process on port 1234 of node001:
and then typing something to port 4321 on the head node:
The Ctrl-C interrupts the session on the head node.
The Hello, World! text entered on the head node shows up on the netcat listener on node001. The session on the compute node ends with the Ctrl-C interrupt on the head node:
A successful session as just illustrated means that port forwarding is working as expected.
If the session is unsuccessful, then it may be because the port is blocked by a firewall. By default, the head node runs a firewall, Shorewall, (here), which may need to have its rules adjusted.
Listing active port forwarding rules: All are listed with the list command:
Example
Sessions denotes the number of cmsh instances that started the exact same rule. This is normally 1. Each request is tracked via a cmsh session unique identifier to prevent killing a port forward rule placed by someone else.
Destroying (removing) every rule: A specific rule can be removed by specifying its compute node IP address and compute node port. All rules are removed with the destroy option used on its own:
Example
BMC port forwarding: For BMC port forwarding 2 rules are created.
-
A rule for the BMC management interface on 443
-
A rule for the BMC console port (5900 or 17900 depending on the type of interface)
3.2.4 Tools For Viewing Cluster Connections And Connectivity
3.2.4.1 Viewing Node Routes With routes In cmsh
The cmsh routes command is a wrapper around the Linux route command, and is designed to run in parallel over nodes. It is intended to get a fast route overview for one or more nodes, and display it for easy comparison.
To get a full overview of the routes for all nodes, the command is run without any options:
Example
To select or filter the output, the grouping options of routes, or the text processing utility awk can be used. Grouping options are options to select nodes, groups, categories, and so on, and are described in the cluster management chapter, here, while a handy link for awk one-liners is http://tuxgraphics.org/~guido/scripts/awk-one-liner.html.
Selection or filtering makes it very easy to detect badly-configured nodes. For example, when the expected gateway is <expected-gateway>, the following command may be used to display only the unexpected gateways:
Example
3.2.4.2 Viewing IP Addresses With ipaddresses In cmsh
The ipaddresses command, in device mode, lists the configured and detected IP addresses for one or more devices. By default, link-local addresses (169.254.0.0/16 and fe80::/10) are excluded from the listing, since they are rarely of interest to an administrator. The --all option includes them in this default listing; it has no effect on the following --check output, which always excludes link-local and BMC interfaces.
Example
The output lists one row per configured or detected address. The preceding example omits the Netmask, MTU, Speed, and Duplex columns to fit the page; the full set of columns is:
-
Hostname: the node the interface belongs to. -
Name: the interface name. -
IP: the IP address on that interface. -
Netmask: the netmask for the address. -
MAC: the interface’s MAC address. -
PCI Bus ID: the PCI bus address of the NIC that the IP address is assigned to, for example0000:03:00.0. This identifies which physical network interface corresponds to a given IP address on a node, which is useful on hosts with several NICs. It is blank for interfaces with no discoverable PCI device, such as virtual NICs, as in the preceding example. The REST API exposes the same value as thepciBusIdfield on theIPAddressentity. -
MTU: the interface’s maximum transmission unit. -
Speed: the negotiated link speed, or-if not available. -
Duplex: the negotiated duplex mode, orunknownif not detected. -
State: whether the interface isupordown.
The --check option compares the IP address configured in BCM for each interface against the address actually detected on the device, and reports any mismatch:
Example
If any interface is not OK, the command exits with a non-zero status, though the table is still printed in full:
Example
The State column values are:
-
OK: the configured and detected addresses match, or the interface uses DHCP and an address was detected. -
Mismatch: both a configured and a detected address are present, but they differ. -
Not detected: an address is configured, but nothing was detected on the interface. -
Not configured: an address was detected, but nothing is configured in BCM for that interface.
The standard node selection options (-n, -c, -g, -r) can be used with --check to target a set of devices, for example ipaddresses -r rack01 --check. The --check option cannot be combined with --import, and --json is ignored when --check is used.
3.2.4.3 Viewing Connections In cmsh
The connections command can be run from within the device mode of cmsh. It is a parallel wrapper to view active TCP and UDP connections. That is, it runs as a simple command over multiple devices at the same time.
Running connections without options displays a full overview of the currently active TCP and UDP ports on all devices (output truncated):
Example
Filtering with grep can then show which nodes are listening on which ports. For example, nodes listening for DNS queries (port 53) can be found with:
Example
and shows that only the head node is listening on that port, providing DNS.
Some third party tools require a free port on all nodes for a service to listen on. Filtering and sorting the output of the connections command allows the administrator to find all the existing used ports across all nodes:
Example
Options to the connections command can be seen by running help connections. Options include node grouping options (such as -n|--nodes, -c|--category, and -t|--type), and filtering out TCP6 and UDP6 connections (--no-tcp6, --no-udp6).
3.2.4.4 Viewing Connections In Base View
The preceding connections command in device mode of cmsh has a Base View version. This is the Network Connections pane display, which is accessible using:
All devices > Bulk actions > Connectivity > Network Connections
3.2.4.5 Viewing Connectivity in cmsh
The connectivity command can be run from within the device mode of cmsh. It runs ICMP pings along each node route on a network of the cluster. By default the network is the management network.
By default the output displays if the connection is OK, the ping sequence ID (counting starts from zero), and the latency between the source and destination:
Example
Pings where the source and destination have identical names are carried out via identical interfaces.
Further options to the connectivity command can be seen by running help connectivity. Options include the ability to set ping timeouts and the cluster network on which to ping, as well as node grouping options.
For larger clusters, the following type of connectivity check may be a helpful diagnostic:
Example
The preceding shows how uniform nodes are in ping timings. A significant spread in uniformity can indicate network problems.
3.2.4.6 Viewing Connectivity in Base View
The preceding connectivity command in device mode of cmsh has a Base View version. This is the Ping All pane display, which is accessible using:
All devices > Bulk actions > Connectivity > Ping All
3.2.4.7 Viewing Network Performance With cm-iperf.py
A handy tool for checking the network performance of the nodes on a cluster is cm-iperf.py.
The nodes to be checked must be specified with the -n|--node option:
Example
For a Type 1 cluster (section 3.3.9 of the Installation Manual) with n nodes, the total number of connection pairs that can be evaluated is:
For a 4-node cluster this means 6 network connection pairs are displayed, as is seen in the preceding example.
Each pair is checked for about 10s. This means that for a 1000-node cluster, the time for a default run would take about 2 months. The following options are therefore useful:
-
--count: specify the number of pairs that are checked -
-r|--random: have the connection pairs chosen in a random sequence -
-p|--parallel: specify the number of parallel threads to runs the process
Example
Further options can be viewed with the -h|--help option.
3.3 Configuring Bridge Interfaces
Bridge interfaces can be used to divide one physical network into two separate network segments at layer 2 without creating separate IP subnets. A bridge thus connects the two networks together at layer 3 in a protocol-independent way.
The network device name given to the bridge interface is of the form br<number>. The following example demonstrates how to set up a bridge interface in cmsh, where the name br0 is stored by the parameter networkdevicename.
Example
A bridge interface is composed of one or more physical interfaces. The IP and network fields of the member interfaces must be empty:
Example
The BOOTIF interface is also a valid interface option.
Currently, the following bridge properties can be set:
-
SpanningTreeProtocol: sets the spanning tree protocol to be on or off. The default is off. -
Forward Delay: sets the delay for forwarding Ethernet frames, in seconds. The default is 0.
Additional properties, if required, can be set manually using the brctl command in the OS shell.
When listing interfaces in cmsh, if an interface is a member of a bond (or bridge) interface, then the corresponding bond or bridge interface name is shown in parentheses after the member interface name:
Example
It is possible to create a bridge interface with no IP address configured, that is, with an IP address of 0.0.0.0. This can be done for security reasons, or when the number of available IP addresses on the network is scarce. As long as such a bridge interface has a network assigned to it, it is properly configured on the nodes and functions as a bridge on the network.
3.4 Configuring VLAN interfaces
A VLAN (Virtual Local Area Network) is an independent logical LAN within a physical LAN network. VLAN tagging is used to segregate VLANs from each other. VLAN tagging is the practice of inserting a VLAN ID tag into a packet frame header, so that each packet can be associated with a VLAN.
The physical network then typically has sections that are VLAN-aware or VLAN-unaware. The nodes and switches of the VLAN-aware section are configured by the administrator to decide which traffic belongs to which VLAN.
A VLAN interface can be configured for an interface within BCM using cmsh or Base View.
3.4.1 Configuring A VLAN Interface Using cmsh
In the following cmsh session, a regular node interface that faces a VLAN-aware switch is made VLAN-aware, and assigned a new interface—an alias interface. It is also assigned a network, and an IP address within that network:
Example
The Reorder HDR setting in a VLAN, if enabled, moves the ethernet header around to make it look exactly like a real ethernet device. This setting controls the REORDER_HDR setting in the file at /etc/sysconfig/network-scripts/ifcfg- <interface> on the node.
3.4.2 Configuring A VLAN Interface Using Base View
Within Base View a VLAN interface can be added for a node such as node001 using the navigation path:
Devices > All Devices > node001 > Settings > Interfaces > + Add > vlan
(figure 3.10).
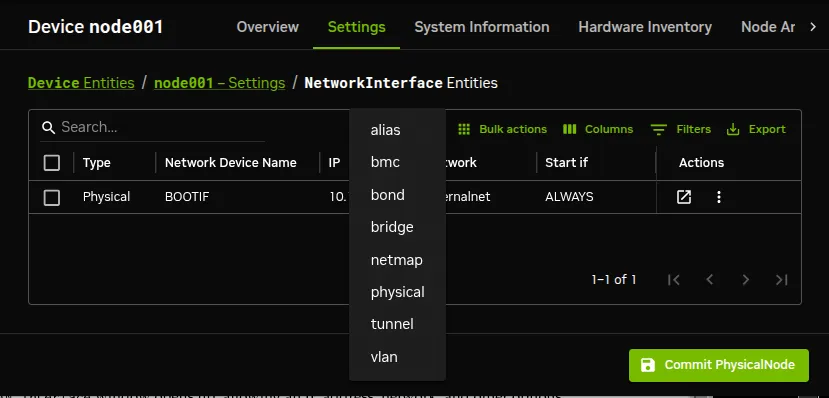
Figure 3.10: Configuring a VLAN via Base View
A Network VLAN Interface window opens up, allowing an IP address, network, and other options to be configured for the VLAN interface.
3.5 Configuring Bonded Interfaces
3.5.1 Adding A Bonded Interface
The Linux bonding driver allows multiple physical network interfaces that have been configured previously (for example, as here) to be bonded as a single logical bond interface. The behavior of such interfaces is determined by their bonding mode. The modes provide facilities such as hot standby or load balancing.
The driver is included by default on head nodes. To configure a non-head node to use a bonded interface, a Linux kernel module called the bonding module must be included in the kernel modules list of the software image of the node. A bonding interface can then be created, and its properties set as follows:
Example
Each bonded interface has a unique set of object properties, called bonding options, that specify how the bonding device operates. The bonding options are a string containing one or more options formatted as option=value pairs, with pairs separated from each other by a space character.
A bonded interface also always has a mode associated with it. By default it is set to 0, corresponding to a balanced round-robin packet transmission.
The 7 bonding modes are:
-
0 – balance-rr
-
1 – active-backup
-
2 – balance-xor
-
3 – broadcast
-
4 – 802.3ad
-
5 – balance-tlb
-
6 – balance-alb
Technically, outside of Base View or cmsh, the bonding mode is just another bonding option specified as part of the options string. However in BCM the bonding mode value is set up using the dedicated mode property of the bonded interface, for the sake of clarity. To avoid conflict with the value of the mode property, trying to commit a bonding mode value as an option=value pair will fail validation.
3.5.2 Single Bonded Interface On A Regular Node
A single bonded interface on a node can be configured and coexist in several ways on nodes with multiple network interfaces. Possibilities and restrictions are illustrated by the following:
-
The bonded interface may be made up of two member interfaces, and a third interface outside of the bond could be the boot interface. (The boot interface is the node interface used to PXE boot the node before the kernel loads (section 5.1)).
-
The boot interface could itself be a member of the bonded interface. If the boot interface is a member of a bonded interface, then this is the first bonded interface when interfaces are listed as in the example here.
-
The bonded interface could be set up as the provisioning interface. However, the provisioning interface cannot itself be a member of a bonded interface. (The provisioning interface is the node’s interface that picks up the image for the node after the initial ramdisk is running. Chapter 5 covers this in more detail).
-
A bonded interface can be set up as the provisioning interface, while having a member interface which is used for PXE booting.
3.5.3 Multiple Bonded Interface On A Regular Node
A node can also have multiple bonded interfaces configured. Possibilities and restrictions are illustrated by the following:
-
Any one of the configured bonded interfaces can be configured as the provisioning interface. However, as already mentioned in the case of single bond interfaces (section 3.5.2), a particular member of a bonded interface cannot be made the provisioning interface.
-
When a bonded interface is set as the provisioning interface, then during the node-installer phase of boot, the node-installer brings up the necessary bonded interface along with all its member interfaces so that node provisioning is done over the bonded interface.
3.5.4 Bonded Interfaces On Head Nodes And HA Head Nodes
It is also possible to configure bonded interfaces on head nodes.
For a single head node setup, this is analogous to setting up bonding on regular nodes.
For a high availability (HA) setup (Chapter 15), bonding is possible for internalnet as well as for externalnet, but it needs the following extra changes:
-
For the bonded interface on
internalnet, the shared internal IP alias interface name (the value ofnetworkdevicename, for example,eth0:0in figure 15.1) for that IP address should be renamed to the bonded alias interface name oninternalnet(for example,bond0:0). -
For the bonded interface on
externalnet, the shared external IP alias interface name (the value ofnetworkdevicename, for example,eth1:0in figure 15.1) for that IP address should be renamed to the bonded alias interface name onexternalnet(for example,bond1:0). -
Additionally, when using a bonded interface name for the internal network, the value of the provisioning network interface name (the value of
provisioninginterface, for example,eth0) for the head nodes, must be changed to the name of the bonded interface (for example,bond0 [prov]) on the internal network. Theprovisioninginterfacevalue setting is described further here.Example
3.5.5 Tagged VLAN On Top Of a Bonded Interface
It is possible to set up a tagged VLAN interface on top of a bonded interface. There is no requirement for the bonded interface to have an IP address configured in this case. The IP address can be set to 0.0.0.0, however a network must be set.
Example
3.5.6 Association Of MAC Address With A Bonded Interface
BCM has MAC settings for interfaces as well as for nodes.
When a node is provisioned via PXE booting (Chapter 5), the MAC on the NIC that is being booted from is matched with the MAC property of the node. This is how the node is identified.
If a bonded interface is used, then any interface may be used for PXE booting. Each interface has its own MAC address, which means that the interface MAC address may not match the assigned node MAC address. In BCM 11 and later versions, the node-installer recognizes any MAC address in a bonded interface.
3.5.7 Further Notes On Bonding
If using bonding to provide failover services, then the kernel module option setting for media independent interface monitoring, miimon, which is set to be off by default (set to 0), should be given a non-zero value.
The miimon setting is the time period in milliseconds between checks of the interface carrier state. A common value is miimon=100.
Its value is set in the bonding device configuration file.
-
For RHEL and derivatives, and for SLES distributions, the file is in a network script along a file path such as
/etc/sysconfig/network-scripts/ifcfg-bond0.The line within the stanza for the
ifcfg-bond0file might look like:Example
and can be set manually.
-
For RHEL and derivatives, it can alternatively be configured with front-end tools such as the
nmclitool,nmtui, or others.Example
-
For SLES, YaST can be used as a front-end tool (
YaST>System>Network Settings).
-
-
For Ubuntu, the interface definitions are in a file, either
/etc/network/interfaces, or a file under/etc/network/interfaces.d/.The line to set the value of
miimonfollows a form such as:bond-miimon 100
instead of
miimon=100
and can be set manually.
Alternatively, Canonical’s
netplan(https://netplan.io) utility can be used to set the network configuration files. ThenetplanYAML configuration key to setbond-miimonismii-monitor-interval.
When listing interfaces in cmsh, if an interface is a member of a bond or bridge interface, then the corresponding bonded or bridge interface name is shown in parentheses after the member interface name. Section 3.3, on configuring bridge interfaces, shows an example of such a listing from within cmsh here.
More on bonded interfaces (including a detailed description of bonding options and modes) can be found at http://www.kernel.org/doc/Documentation/networking/bonding.txt.
3.6 Configuring InfiniBand Interfaces
On clusters with an InfiniBand interconnect, the InfiniBand Host Channel Adapter (HCA) in each node must be configured before it can be used.
This section describes how to set up the InfiniBand service on the nodes for regular use. Setting up InfiniBand for booting and provisioning purposes is described in Chapter 5, while setting up InfiniBand for NFS is described in section 3.14.4.
3.6.1 Installing Software Packages
On a standard NVIDIA Base Command Manager cluster, the OFED (OpenFabrics Enterprise Distribution) packages that are part of the Linux base distribution are used. These packages provide RDMA implementations allowing high bandwidth/low latency interconnects on OFED hardware. The implementations can be used by InfiniBand hardware.
By default, all relevant OFED packages are installed on the head node and software images. It is possible to replace the distribution OFED with a non-distribution OFED. The replacement can be for the entire cluster, or only for certain software images. Administrators may choose to switch to a different OFED version if the HCAs used are not supported by the distribution OFED version, or to increase performance by using an OFED version that has been optimized for a particular HCA. Installing a DOCA Mellanox OFED stack onto BCM is covered in Chapter 10 of the Installation Manual.
If the InfiniBand network is enabled during cluster installation, then the infiniband.conf and rdma.conf modules in the subdirectory etc/rdma/modules/ are automatically configured for the detected hardware.
The relevant InfiniBand HCA kernel modules are then automatically loaded during the init stage by systemd. Verifying that InfiniBand is active can be done after the cluster is up and running by running ibstat:
3.6.2 Mellanox Adapter Settings With mlxconfig
The device mode mlxconfig command displays and sets Mellanox adapter configuration on nodes. It is useful for checking the runtime state that the NVIDIA mlxconfig utility reports, and for applying selected supported settings from BCM.
Example
Without --adapters, the command expands each matching adapter into the known mlxconfig fields. The output shows the BCM field name, the current value, the pending value, and whether a reboot is required for pending changes to take effect. The output can be limited to an interface, PCI address, port, or detail level:
Example
To set a value immediately on a node, use --set. A per-port field can be selected either from the interface context or by using a port suffix in the field name:
Example
Some mlxconfig changes are pending until the node is rebooted. When this is the case, the set result indicates that a reboot is required.
3.6.2.1 Persistent mlxconfig Policy With Extra Values
Persistent Mellanox adapter settings can be declared through extra_values entries whose keys start with MLX_. The desired settings can be defined on a category, on a node, or on a network interface. When the same field is defined at more than one level, the precedence is:
Category and node settings apply to all discovered Mellanox adapters on the node. Interface settings apply to the selected interface. For VLAN and bond interfaces, BCM resolves the setting to the underlying physical interface or interfaces before applying it.
The key name after MLX_ can use a BCM field name, such as link_type_p1, or a native mlxconfig field name, such as KEEP_ETH_LINK_UP_P1. Values may be strings, booleans, or numbers. Boolean values are applied to mlxconfig as 1 or 0.
Example
The settings are reconciled by the node after it connects to the head node and again during the periodic node update. The apply step is idempotent: BCM does not set a field again if the current or pending mlxconfig value already matches the desired value. If the local mlxconfig binary is missing, no Mellanox adapter is discovered, or mlxconfig rejects a value, BCM raises a warning event.
The --desired option shows the declared policy from the cluster configuration. It does not query the node or run mlxconfig, so it can be used to inspect the intended policy even before the node has applied it.
Example
3.6.3 Subnet Managers
Every InfiniBand subnet requires at least one subnet manager to be running. The subnet manager takes care of routing, addressing and initialization on the InfiniBand fabric. Some InfiniBand switches include subnet managers. However, on large InfiniBand networks or in the absence of a switch-hosted subnet manager, a subnet manager needs to be started on at least one node inside of the cluster. When multiple subnet managers are started on the same InfiniBand subnet, one instance will become the active subnet manager whereas the other instances will remain in passive mode. It is recommended to run 2 subnet managers on all InfiniBand subnets to provide redundancy in case of failure.
On a Linux machine that is not running BCM, an administrator sets a subnet manager service (usually opensm, but opensmd in SLES) to start at boot-time with a command such as:
systemctl enable opensm.service
However, for clusters managed by BCM, a subnet manager is best set up using CMDaemon. There are two ways of setting CMDaemon to start up the subnet manager on a node at boot time:
-
by assigning a role.
In
cmshthis can be done with:where
<node>is the name of a node on which it will run, for example:basecm11,node001,node002…In Base View, the subnet manager role is assigned by selecting a head node or regular node from the
Devicesresource, and assigning it the “Subnet manager role”. The navigation path for this, for a nodenode002for example, is:Devices > All Devices > node002 > Settings > Roles > + Add > [SubnetManagerRole] -
by setting the service up. Services are covered more generally in section 3.15.
In
cmshthis is done with:Example
In Base View the subnet manager service is configured by selecting a head node or regular node from the resources tree, and adding the service to it. The navigation path for this, for a node
node002for example, is:Devices > All Devices > node002 > Settings > Services > + Add
When the head node in a cluster is equipped with an InfiniBand HCA, it is a good candidate to run as a subnet manager for smaller clusters.
On large clusters a dedicated node is recommended to run the subnet manager.
3.6.4 InfiniBand Network Settings
Although not strictly necessary, it is recommended that InfiniBand interfaces are assigned an IP address (i.e. IP over IB). First, a network object in the cluster management infrastructure should be created. The procedure for adding a network is described in section 3.2.2. The following settings are recommended as defaults:
By default, an InfiniBand interface is set to datagram mode, because it scales better than connected mode. It can be configured to run in connected mode by setting the connectedmode property:
Example
For nodes that are PXE booting or are getting provisioned over InfiniBand, the mode setting in the node-installer script has to be changed accordingly.
Example
Once the network has been created all nodes must be assigned an InfiniBand interface on this network. The easiest method of doing this is to create the interface for one node device and then to clone that device several times.
For large clusters, a labor-saving way to do this is using the addinterface command (section 3.7.1) as follows:
When the head node is also equipped with an InfiniBand HCA, it is important that a corresponding interface is added and configured in the cluster management infrastructure.
Example
Assigning an IP address on the InfiniBand network to the head node:
As with any change to the network setup, the head node needs to be restarted to make the above change active.
3.6.5 Verifying Connectivity
After all nodes have been restarted, the easiest way to verify connectivity is to use the ping utility
Example
Pinging node015 while logged in to node014 through the InfiniBand interconnect:
If the ping utility reports that ping replies are being received, the InfiniBand is operational. The ping utility is not intended to benchmark high speed interconnects. For this reason it is usually a good idea to perform more elaborate testing to verify that bandwidth and latency are within the expected range.
The quickest way to stress-test the InfiniBand interconnect is to use the Intel MPI Benchmark (IMB), which is installed by default in /cm/shared/apps/imb/current. The setup.sh script in this directory can be used to create a template in a user’s home directory to start a run.
Example
Running the Intel MPI Benchmark using openmpi to evaluate performance of the InfiniBand interconnect between node001 and node002:
To run on nodes other than node001 and node002, the ../nodes file must be modified to contain different hostnames. To perform other benchmarks, the PingPong argument should be omitted.
3.7 Configuring BMC (IPMI/iLO/DRAC/CIMC/Redfish) Interfaces
BCM can initialize and configure the baseboard management controller (BMC) that may be present on devices. This ability can be set during the installation on the head node (figure 3.15 of the Installation Manual), or it can be set after installation as described in this section. The IPMI, iLO, DRAC, CIMC, or Redfish interface that is exposed by a BMC is treated in the cluster management infrastructure as a special type of network interface belonging to a device. In the most common setup a dedicated network (i.e. IP subnet) is created for BMC communication. The 10.148.0.0/16 network is used by default for BMC interfaces by BCM.
3.7.1 BMC Network Settings
The first step in setting up a BMC is to add the BMC network as a network object in the cluster management infrastructure. The procedure for adding a network is described in section 3.2.2. The following settings are recommended as defaults:
Once the network has been created, all nodes must be assigned a BMC interface, of type bmc, on this network. The easiest method of doing this is to create the interface for one node device and then to clone that device several times.
For larger clusters this can be laborious, and a simple bash loop can be used to do the job instead:
The preceding loop can conveniently be replaced with the addinterface command, run from within the device mode of cmsh:
The help text in cmsh gives more details on how to use addinterface.
Most administrators are likely to simply run it as an interactive session in cmsh, running the help addinterface command for reference, and then supplying the options for the nodes and interface settings in device mode. For example, as in the following session:
In order to be able to communicate with the BMC interfaces, the head node also needs an interface on the BMC network. Depending on how the BMC interfaces are physically connected to the head node, the head node has to be assigned an IP address on the BMC network one way or another. There are two possibilities for how the BMC interface is physically connected:
-
When the BMC interface is connected to the primary internal network, the head node should be assigned an alias interface configured with an IP address on the BMC network.
-
When the BMC interface is connected to a dedicated physical network, the head node must also be physically connected to this network. A physical interface must be added and configured with an IP address on the BMC network.
Example
Assigning an IP address on the BMC network to the head node using an alias interface:
As with any change to the network setup, the head node needs to be restarted to make the above change active.
BMC connectivity from the head node to the IP addresses of the configured interfaces on the regular nodes can be tested with Bash one-liner such as:
Example
In the preceding example the packet loss demonstrates there is a connection problem between the head node and the BMC subnet.
3.7.2 BMC Authentication
The node-installer described in Chapter 5 is responsible for the initialization and configuration of the BMC interface of a device. In addition to a number of network-related settings, the node-installer also configures BMC authentication credentials. By default BMC interfaces are configured with username bright and a random password that is generated during the installation of the head node. The password is stored by CMDaemon. It can be managed from cmsh from within the base object of partition mode, in the bmcsettings submode. This means that by default, each BMC in the cluster has that username and password set during node boot.
For example, the current values of the BMC username and password for the entire cluster can be obtained and changed as follows:
Example
In Base View, selecting the cluster item in the resources pane, and then using the Settings option, allows the BMC settings to be edited.
The BMC authentication credentials, and also some other BMC properties can be set cluster-wide, category, or per node. As usual, category settings override cluster-wide settings, and node settings override category settings. The relevant properties are:
3.7.2.1 Viewing The Effective BMC Settings (-s|--show)
Because BMC settings can be set cluster-wide, per category, and per node, it is not always obvious which values a particular node actually uses. The bmcsettings command therefore accepts a -s|--show option that prints the effective settings without entering the bmcsettings submode.
When --show is used, BCM resolves the settings along the inheritance chain. For a node this is the node first, then its category, then the base partition. For a category it is the category first, then the base partition. The first level that has the settings defined is displayed, and a comment line indicates where the displayed values come from. If no level has the settings defined, then < not set > is shown instead.
The same -s|--show option is available for the other settings submodes that hold a single settings object and follow the same inheritance, such as accesssettings, dpusettings, ztpsettings, snmpsettings, selinuxsettings, and proxysettings. Submodes that hold a list of objects, such as roles or interfaces, do not support it. Availability can also depend on the device type: snmpsettings, for example, applies to switches, rack sensors, and power distribution units, so running snmpsettings --show on a regular node displays the command usage instead of settings.
BMC configuration on a head node is done directly.
For regular nodes BCM stores the BMC configuration, and uses it:
-
to configure the BMC interface from the node-installer
-
to authenticate to the BMC interface after it has come up
BMC management operations, such as power cycling nodes and collecting hardware metrics, can then be performed after the node has been provisioned again.
If BMC authentication fails, then an explanation for why can often be found in the node-installer log at /var/log/node-installer.
The credentialsoverview command (section 3.7.3) within device mode is the recommended utility for seeing which BMC username and password each device ends up using, once the device → category → partition inheritance is resolved.
3.7.3 Auditing Cluster Credentials With The credentialsoverview Command
The credentialsoverview command within device mode lists the effective Access and BMC credentials per device.
It walks the device → category → partition inheritance chain, so that the cluster administrator can see which of the levels actually supplies the setting for the Access and BMC credentials.
Access settings are described in section 3.9.1.1 for Cumulus switches, but are also used cluster-wide. The BMC settings are described in section 3.7.2.
If used without arguments, then the command lists the output for every device on the cluster. The usual device-selection flags, such as a hostname list or range, -c|--category, -t|--type, -g|--group, -r|--rack, and so on, can be used to narrow the list to a specific subset.
The password columns never show plaintext. Instead they show a short SHA-256 fingerprint, salted with the running cmsh session’s PID and start time, so that:
-
within a single
cmshsession, identical underlying passwords render as identical hex blobs, which is the whole point: two devices with diverging passwords stand out immediately -
across
cmshsessions, the same password produces a different fingerprint, so that a hex blob copied from someone else’s scrollback cannot be used to recognise a password on a different login. -
Empty password fields render as:
-
<not set>for settings objects that exist and have no credential values supplied by a level -
-for settings objects that do not yet exist, or for objects that are redacted by CMDaemon, in cases when thecmshuser lacks theACCESS_SETTINGS_TOKENorBMC_USERNAME_PASSWORD_TOKENprofile token
-
Example
In the preceding example, node003 is the odd one out because its BMC password fingerprint differs from the other members of its category.
Example
In the preceding example, node004 has not had its BMC user or password set, even though the BMC object exists.
The --inverse flag flips the table so that each distinct (access_user, access_pass, bmc_user, bmc_pass) tuple is shown once, with the matching hostnames listed beside it. Rows are sorted ascending by count, so outliers land at the top of the output:
Example
Standard table-formatting flags also apply: -d|--delimiter sets a custom column separator ({} or {<digits>} is used for JSON output, just like for other cmsh list commands), and -v|--verbose enables multi-line wrapping, which is useful when a single tuple in --inverse mode covers a long list of hostnames.
3.7.4 Interfaces Settings
3.7.4.1 Interface Name
It is recommended that the network device name of a BMC interface start with ipmi, ilo, drac, cimc, or rf, according to whether the BMC is running with IPMI, iLO, DRAC, CIMC, or Redfish. Numbers are appended to the base name, resulting in, for example: ipmi0.
3.7.4.2 Obtaining The IP address
BMC interfaces can have their IP addresses configured statically, or obtained from a DHCP server.
Only a node with a static BMC IP address has BMC power management done by BCM. If the node has a DHCP-assigned BMC IP address, then it requires custom BMC power management (section 4.1.4) due to its dynamic nature.
3.7.4.3 Dell OpenManage And racadm Installation
The Dell OpenManage utilities are provided with BCM only for RHEL8-based distributions at the time of writing of this section (September 2023).
If Dell was chosen as the hardware vendor when the BCM ISO was created for installation, and chosen as the hardware manufacturer when the head node was configured in the BCM installer (section 3.3.10 of the Installation Manual), then the Dell OpenManage utilities are located under /opt/dell on the head node.
If Dell was chosen as the hardware manufacturer when nodes are configured in the BCM installer (section 3.3.11 of the Installation Manual), then the default software image that is used by the node has the Dell OpenManage utilities, located on the head node at /cm/images/default-image/opt/dell.
The Dell OpenManage utilities contain the racadm binary to carry out remote access control administration. The racadm tool can be used to issue power commands (Chapter 4). BCM runs commands similar to the following to issue the power commands:
The BMC username/password values can be obtained from cmsh as follows:
Sometimes the bright user does not have the right privilege to get the correct values. The racadm commands then fail.
The bright user privilege can be raised using the following command:
Here it is assumed that the BMC user has the username bright, a userID 4, and the privilege can be set to 511.
3.7.5 Identification With A BMC
3.7.6 Identification At A Lower Level, Directly With ipmitool
Sometimes it is useful to identify a node using BMC commands. This can be done by, for example, blinking a light via a BMC command on the node:
Example
The exact implementation may be vendor-dependent, and need not be an ipmitool command. Such commands can be scripted and run from CMDaemon.
The ipmitool command is provided by loading the ipmitool modules environment. The modules environment (section 2.2) is provided by the cm-ipmitool and the cm-freeipmi packages.
For testing without a BMC, the example script at /cm/local/examples/cmd/bmc_identify can be used if the environment variable $CMD_HOSTNAME is set. The logical structure of the script can be used as a basis for carrying out an identification task when a physical BMC is in place, by customizing the script and then placing the script in a directory for use.
To have such a custom BMC script run from CMDaemon, the BMCIdentifyScript advanced configuration directive (here) can be used.
The ipmitool command can also be used for troubleshooting during provisoning (here).
3.7.7 Identification At A Higher Level, With The identify Command Of Device Mode
In addition to using ipmitool directly, BCM provides the identify command in device mode as a convenient wrapper. It supports turning the identification LED on or off, as well as querying its current status:
Example
The standard node selection options (-n, -c, -g, -r) can be used to target specific nodes.
3.7.8 BMC Event Log
The bmceventlog command in device mode retrieves the BMC event log for one or more nodes using Redfish. This is useful for diagnosing hardware issues such as fan failures, power events, and sensor threshold violations.
Example
Options to bmceventlog include:
-
--tail <count>: Show only the last<count>events. The default is 100. -
--clear: Clear the BMC event log. -
-v, --verbose: Show additional details. -
--debug: Enable debug output.
3.7.9 BMC Reset
The bmcreset command in device mode performs a hardware reset of the BMC controller on one or more nodes. This can be useful when the BMC becomes unresponsive or needs to be restarted after a configuration change.
Example
Resetting the BMC temporarily disrupts out-of-band management access to the node. The BMC typically takes a few minutes to become available again after a reset. Power state and the running OS on the node are not affected.
3.7.10 BMC Port Queries
3.7.10.1 BMC Port Accessibility
The netcat utility can be used to detect if the default UDP port 623 for standard IPMI services on a network is open. For a service on IP address 10.184.154.15 the following session query can be carried out:
Example
The asf-rmcp part indicates the Alert Standard Format Remote Management And Control Protocol over UDP.
3.7.10.2 BMC Version
The IPMI version can often be discovered using the nmap port scanner with the ipmi-version LUA script:
Example
3.7.11 Leak Detection
For liquid-cooled systems some leak detection commands may be available:
-
the
leakdetectioncommand indevicemode enables or disables leak detection on nodes. Leak detection monitors coolant leak sensors using the BMC. -
the
leakinfocommand indevicemode displays detected leaks. -
The
leakdetectionoverviewcommand (section 3.3.2.3 of the NVIDIA Mission Control Manual) is a rack-centric approach to leak detection, available in the NVIDIA Mission Control edition of BCM. Basicrackmode is described in section 3.16 of the Administrator Manual.
Enabling leakdetection on a node001, and disabling leakdetection for a rack rack01 could be carried out with:
Example
Options to leakdetection include:
-
enable: Enable leak detection on the specified devices. -
disable: Disable leak detection on the specified devices. -
-m, --message <message>: Add an information message that is displayed in the device status.
The standard node selection options (-n, -c, -g, -r) can be used to target devices. Rack-level selection with -r is convenient for enabling or disabling leak detection across all nodes in a rack.
A device with leak detection disabled shows leak:disabled appended to its status line. This is not for devices that lack leak-detection hardware. It is for devices that have leak-detection hardware whose sensor is broken or is reporting a false positive: in either case the administrator can disable leak detection on that device to prevent an unwanted power-off until the sensor is replaced.
Example
A device with leak detection enabled, which is the default, shows no leak: suffix on its status line.
Typically, and ideally, running the leakinfo command shows nothing of interest:
Example
If there are issues on the devices, then the output may look similar to::
3.8 Configuring Switches And PDUs
3.8.1 Configuring With The Manufacturer’s Configuration Interface
Network switches and PDUs that are to be used as part of the cluster should be configured with the PDU/switch configuration interface described in the PDU/switch documentation supplied by the manufacturer. Typically the interface is accessed by connecting using a web browser or telnet to an IP address preset by the manufacturer.
The IP address settings of the PDU/switch must match the settings of the device as stored by the cluster manager.
-
In Base View, this is done using the navigation path
Devices > All Devices ><switchname> to select the switch. If the switch does not already exist, then it can be added using the+ Addbutton. The values in the associatedSettingswindow that comes up (figure 3.11) can then be filled in, and the IP address can be set and saved. -
In
cmshthis can be done indevicemode, with asetcommand:Example
3.8.1.1 Port Assignments For Switches
-
Using the
uplinksoption to configure uplink ports is described in section 3.9.3. -
The
showporttool for seeing what MAC address matches what port number on a switch is described in section 3.9.4. -
The
switchoverviewtool gives an overview of the MAC addresses detected on the ports based on SNMP queries, and is described in section 3.9.6. -
The
switchportscommand lists the switches and switch ports that have been assigned a node. -
The
switchportsoption assigns ports on a switch to a node:Example
The
switchportsoption used at node level is a legacy option, which can still be used in BCM version 10. However it may not work as expected when a node has multiple interfaces that may be connected to a switch.Since BCM version 10 it is therefore recommended to assign ports from within the
interfacessubmode for a node. This assigns ports clearly per interface, and supports bonding of the interfaces (section 3.5). Management of ports atinterfacelevel also makes it possible for CMDaemon Lite (section 2.6.7) to manage the network configuration of Cumulus switches (section 3.9).Example
Managing PDUs in Base View or cmsh is done in a similar way to the preceding method for switches. However, assigning PDUs and PDU ports to devices such as nodes is not part of this method, and is instead described in section 4.1.1.
3.8.1.2 APC PDUs
For the APC brand of PDUs, the powercontrol value for the PDU device should be set to apc.
For example, for a PDU with the name mypdu, its value can be set in cmsh with:
Example
and in Base View with the navigation path:
Devices > All Devices > Power Distribution Units > Power Control
If it is not set to apc, then the list of PDU ports is ignored by default.
3.8.2 Configuring SNMP
BCM can use SNMP to manage devices such as rack sensors, power distribution units (PDUs), and switches (including many InfiniBand switches). This requires that SNMP be enabled. If disablesnmp is set to no, the default, then SNMP is enabled. For example for a switch:
Example
3.8.2.1 Configuring SNMP Community Strings
In order to allow the cluster management software to communicate with a device that is managed using SNMP, SNMP must be enabled on it, and the SNMP community strings should be configured correctly.
By default, the SNMP community strings for switches and PDUs are set to public and private for read and write access respectively. If different SNMP community strings have been configured in the switch or PDU, the readstring and writestring properties of the corresponding switch device should be changed.
Example
Alternatively, these properties can also be set in Base View using the navigation path:
Devices > All Devices > Switch > ↗ > SNMP Settings > ↗
3.8.2.2 Configuring SNMP Settings
SNMP settings can be configured in cmsh via the snmpsettings submode, which is available under partition mode as well as under device mode. The partition mode values are inherited by default by devices using SNMP settings at node level.
The effective (inherited) values can be displayed without entering the submode by using the -s|--show option, for example snmpsettings -s (section 3.7.2.1).
The submode allows the version to be set to v1, v2c, or v3.
Setting the version to the value file is also an option, but is not meant as an option for end users. It is used in SNMP walk emulation for debugging non-standard switches.
The SNMPv3 settings that can be managed in BCM are:
Example
The set command can be used, sometimes with tab-completion, to set the SNMP switch parameters. For example, for the SNMPv3 parameters that are set to use cryptographic keys:
Example
3.8.2.3 SNMP Traps
BCM can assign an SNMP trap manager role to a node. The snmptrapd daemon is then configured and managed on the assigned node by CMDaemon.
Configuration options include enabling or disabling mailing of the messages, and setting the sender and recipients for the mail. By default an undefined value for Server means that the SNMP server is localhost.
Example
3.9 Configuring Cumulus Switches
A Cumulus switch is a switch that runs Cumulus Linux, which is a Debian-based distribution with a networking focus.
The following capabilities and features are available, or can be run, on a switch that can run Cumulus Linux:
-
ONIE (Open Network Install Environment, https://opencomputeproject.github.io/onie/): a bootloader, similar in concept to PXE booting. It allows the switch to boot up and install the Cumulus OS from an image on the network. Installing Cumulus with ONIE wipes out any existing image already installed on the switch.
-
ZTP (Zero Touch Provisioning): a protocol that is used with the
ztpclient. The protocol uses specially defined DHCP options. ZTP allows the switch to automatically carry out provisioning for other hardware devices on a network on top of an OS on the switch. The capability to carry this out becomes available automatically when the switch is powered on, and the interface on which provisioning is to be carried out automatically becomes active with an IP address (“day-0 provisioning”). -
NVUE (NVIDIA User Experience): a CLI that uses the
nvcommand set to manage the network configuration of the switch. The NVUE CLI is documented at https://docs.nvidia.com/networking-ethernet-software/cumulus-linux-55/System-Configuration/NVIDIA-User-Experience-NVUE/NVUE-CLI/. -
The NVUE REST API: if it is explicitly enabled, can run the same commands via HTTP as the NVUE CLI. The NVUE REST API is documented at https://docs.nvidia.com/networking-ethernet-software/cumulus-linux-55/System-Configuration/NVIDIA-User-Experience-NVUE/NVUE-API/
-
Public key SSH: if configured, the administrator can access the switch from the head node safely and securely with public key SSH, including passwordless SSH.
A Cumulus switch is added to the cluster manager as a regular switch object:
Example
Cumulus access settings (described later on, starting from here) and ZTP settings (described later on, starting from here) must also be configured for the switch to work correctly.
Committing the Cumulus switch object configuration automatically configures the DHCP and the DNS services. The DHCP server is configured by CMDaemon to use the ZTP custom provisioning script. The ZTP provisioning script is created on-demand, along with a directory, from a default template (here) when the switch boots. The creation can alternatively be forced right away by running the initialize command.
3.9.1 Cumulus Switches Access Configuration, Initialization And Network Device Discovery
3.9.1.1 Cumulus Switches Access Configuration
By default, Cumulus switches use certificate-based authentication for CMDaemon access, just like regular nodes. DGX SuperPODS are configured in that manner.
However, CMDaemon Lite (section 2.6.7) is recommended instead of CMDaemon for Cumulus switches on most other clusters. If CMDaemon Lite is to run on the switch, then the hasclientdaemon parameter must be enabled for it:
Example
The cluster administrator must configure a username/password pair for SSH public key authentication with CMDaemon Lite.
-
Since BCM version 11, Cumulus switch access via a username/password pair is configured in the
accesssettingssubmode. Updates can be done using ZTP or NV. -
In earlier versions of BCM SNMP settings were used to set the username/password pair.
Example
If all switches are Cumulus switches, then setting the username/password can be carried out at partition level with:
Example
The effective (inherited) values for a device, category, or partition can be displayed without entering the submode by using the -s|--show option, for example accesssettings -s (section 3.7.2.1).
Compared with a regular node (section 6.2), a Cumulus switch has these differences when setting a username and password:
-
The password change only takes effect on the switch after the switch reboots.
-
If the
startup.yamlfile used by NV does not set the password, andcm-lite-daemonis not installed, then during reboot either-
Update in ztpmust be set toyesto allow the password change using ZTP
or -
Update in NVmust be set toyes, to allow the password change using NV
-
The REST API port, with a default value of 8765, can also be modified from the accesssettings submode, to match the deployment specifications.
The effective Access (and BMC) credentials for any subset of devices, including the inheritance source (device, category, or partition), can be reviewed with the credentialsoverview command described in section 3.7.3.
Other parameters for CMDaemon Lite integration are described in the section starting here, Custom Services Option 1: Cumulus With CMDaemon Lite. Also covered in that section, here, are the ZTP settings. ZTP settings are managed via the ZTP mode of cmsh, and are needed for the switch to pick up its ZTP provisioning script.
3.9.1.2 The Cumulus Custom Discovery Script (Deprecated)
This is a legacy script that comes with BCM, and is at /cm/local/apps/cmd/scripts/cm-cumulus-switch.py.
Setting the script and running the initialize command for the Cumulus switch in device mode initializes access settings and carries out network discovery for the Cumulus switch, in versions of BCM prior to version 10.
Since BCM version 10, the script is only needed for the Cumulus Linux version 4 series. Since Cumulus Linux version 5, and since BCM version 10, the script is no longer required, due to the integration of Cumulus with BCM.
A Cumulus switch running version 4 of Cumulus Linux can be set up and initialized on BCM version 10 with:
Example
3.9.2 Custom Service Setups For Cumulus Linux
There are two custom service setups that are supported for cluster management on top of Cumulus Linux:
-
a setup that uses CMDaemon Lite (here, Custom Services Option 1: Cumulus With CMDaemon Lite)
-
a setup that uses YAML to configure the services (here, Custom Services Option 2: Cumulus With A YAML Preconfiguration).
These can actually be run together, if the services do not conflict with each other. For example, the nvued service can be installed via YAML, to provide the NVUE, independently of CMDaemon Lite. It is however useful to describe these custom service setups individually.
3.9.2.1 Custom Services Option 1: Cumulus With CMDaemon Lite
If the Cumulus switch is defined and configured with CMDaemon Lite, then this allows some Cumulus features to be managed via BCM, as well as some of the standard features of BCM to work on the switch. The following features can be managed:
-
monitoring (Chapter 10). For example, the latest data values (section 10.6.3) of the switch, including the bytes going through the many ports, can be seen with:
Example
-
system information can be viewed with the
sysinfocommand:Example
-
systemd services can be added for the device via roles, and listed in the
servicessubmode (section 3.15). Management of services is a standard part of CMDaemon Lite since NVIDIA Base Command Manager version 10.23.06. -
configuration via
cmsh: can be set up via either a YAML file, or manually, or automatically with some optional manual parts. The appropriate mode is set withnvconfigurationmodefor the Cumulus device:-
auto: BCM settings such as forhostnameortimezonefor a Cumulus switch network configuration are converted automatically to run asnvcommands. All thenvcommands carried out on the switch via BCM, whether from an automatic conversion or not, can be viewed withinnvconfigurationmode. Thenvcommands that have been automatically converted from BCM settings are assigned a type value ofauto, and can be viewed withinnvconfigurationmode:Example
The settings are applied to the switch when the
applycommand is run withinnvconfigurationmode. -
manual: Ifnvconfigurationmodeis set tomanualthen the commands of typeauto(as shown within the preceding example) are ignored. Directnvcommands can be entered by the administrator manually from within themanualNV Configuration mode.Direct
nvcommands can actually also be added withinautomode fornvconfiguration, and are in that case also of typemanual:Example
The changes are applied when the
applycommand is run withinnvconfigurationmode.Only commands of type
manualcan be removed fromnvconfigurationmode. The removal can be carried out from withinnvconfigurationmode with the help of themanualcommand and thenv delcommand:Example
The
manualcommand switchesnvconfigurationmodetomanual, and copies the stack ofautotype commands over to the stack inmanualmode. Thecommitcommand saves the configuration in the CMDaemon database. As usual, the configuration defined by themanualNV configuration mode is only applied to the switch after using theapplycommand.The stack in the
manualmode stack is then what is used on the switch instead of theautomode stack, as per the CMDaemon state. -
file: Ifnvconfigurationmodeis set tofile, then a YAML file is used by BCM to carry out the commands. A sample YAML file that uses the currently running configuration of the switch can be displayed by running
nv config show
on the switch.Example
The
applycommand is not used forfilemode, since the commands are carried out over ZTP.
-
-
the ZTP configuration can be managed from
ztpsettingsmode:Example
The effective (inherited) values can be displayed without entering the submode by using the
-s|--showoption, for exampleztpsettings -s(section 3.7.2.1).Notes about some of the
ztpsettings:-
By default,
authorizedkeyfilerootis not set, which means that userrootcannot access the switch with public key authentication. -
By default,
authorizedkeyfilecumulusis not set. The usercumulusis the API user with administrator privileges for the Cumulus switch. -
By default,
authorizedkeyfileadminis not set. The useradminis the API user with administrator privileges for the NVLink switch. -
Cumulus images for the switch, set by
image, are provisioned from the head node. Cumulus images can be picked up from https://enterprise-support.nvidia.com/s/downloads and can then be placed on the head node at/cm/local/apps/cmd/etc/htdocs/switch/images/. -
The
checkimageonbootsetting checks that the existing image on the switch matches the image that can be offered via ZTP. If it does not, then the switch updates its image, picking it up via ZTP. -
The file specified by
scripttemplateis used to generate a ZTP provisioning file on-demand when the switch boots. Runninginitializefrom the switch object level (atcumulus02level in the preceding example) generates the file without a reboot. -
The file specified by
PTM topology filedescribes the cabling topology.
-
-
The
switchoverviewcommand returns output such as: -
The
switchportscommand (here) is used to configure the port assignment between the nodes and the switch ports. Configuring the port assignment atinterfaceslevel is needed to allow CMDaemon Lite to manage Cumulus network configuration.Example
3.9.2.2 Custom Services Option 2: Cumulus With A YAML Preconfiguration
A YAML configuration can be used outside of cmsh. DGX SuperPODS use this option during the standard BCM installation. It means that CMDaemon Lite running on the switch (section 3.9.2.1) does not need to be used. Instead, two custom-generated YAML files are used.
The YAML files that are generated are:
-
startup.yaml: this contains a sequence of Cumulusnvcommands -
cm-startup.yaml: this contains the BCM DGX/switch definitions to be added by pythoncm
The cm-startup.yaml file is parsed, and the devices that are defined within it are configured with the PythonCM (Chapter 1 of the Developer Manual) script, cm-import-startup.
The devices are then powered on in the correct order.
The YAML file startup.yaml can be handled manually (using scp and the nv apply command), or by using ZTP, or by using Ansible.
3.9.2.3 Settings Applied Via ZTP
The configuration script cumulus-ztp.sh template, found under /cm/local/apps/cmd/etc/htdocs/switch/template, can be customized to suit the requirements.
The YAML file startup.yaml is placed under:
/cm/local/apps/cmd/etc/htdocs/switch/ <switch or host name>/
This allows it to be picked up automatically via ZTP, and the nv commands are applied it to the switch on boot.
CMDaemon Lite is not required, but can be installed separately.
3.9.2.4 Settings Applied Via Ansible
Alternatively, Ansible can be used to push the YAML configuration to each switch.
With an Ansible installation, ZTP is not required, but it can be used. CMDaemon Lite is not required for applying the settings via Ansible either, but can be installed separately.
3.9.3 Uplink Ports
Uplink ports are switch ports that are connected to other switches. CMDaemon must be told about any switch ports that are uplink ports, or the traffic passing through an uplink port will lead to mistakes in what CMDaemon knows about port and MAC correspondence. Uplink ports are thus ports that CMDaemon is told to ignore.
To inform CMDaemon about what ports are uplink ports, Base View or cmsh are used:
- In Base View, the switch is selected, and uplink port numbers can be added via the navigation path:
Devices > All Devices > Switch > Uplinks > + Add
(figure 3.11):
Figure 3.11: Notifying CMDaemon about uplinks with Base View
The state is saved with the Commit Switch button of figure 3.11.
-
In
cmsh, the switch is accessed from thedevicemode. The uplink port numbers can be appended one-by-one with theappendcommand, orsetin one go by using space-separated numbers.Example
3.9.4 The showport MAC Address to Port Matching Tool
The showport command can be used in troubleshooting network topology issues, as well as checking and setting up new nodes (section 5.4.2).
3.9.4.1 Basic Use Of showport
In the device mode of cmsh is the showport command, which works out which ports on which switch are associated with a specified MAC address.
Example
When running showport, CMDaemon on the head node queries all switches until a match is found.
If a switch is also specified using the “-s” option, then the query is carried out for that switch first. Thus the preceding example can also be specified as:
If there is no port number returned for the specified switch, then the scan continues on other switches.
3.9.4.2 Mapping All Port Connections In The Cluster With showport
A list indicating the port connections and switches for all connected devices that are up can be generated using this script:
Example
The script may take a while to finish its run. It gives an output like:
Example
Related utilities to showport are:
-
finddevicebyswitchport(section 3.9.7) which—as the name suggests—finds the devices for each switch port -
setmacviaswitchport(section 3.9.8), running in--dry-runmode, which shows the discovered MAC address for a switch
3.9.5 Disabling Port Detection
An administrator may wish to disable node identification based on port detection. For example, in the case of switches with buggy firmware, the administrator may feel more comfortable relying on MAC-based identification. Disabling port detection can be carried out by clearing the switchports setting of a node, a category, or a group. For example, in cmsh, for a node:
Example
Or, for example for the default category, with the help of the foreach command:
Example
3.9.6 The switchoverview Command
Also within device mode, the switchoverview command gives an overview of MAC addresses detected on the ports, and some related properties. The command works using SNMP queries. Output is similar to the following (some lines ellipsized):
3.9.7 The finddevicebyswitchport Command
The finddevicebyswitchport command, in device mode, is the converse of the showport command (section 3.9.4). Instead of finding the switch port for a known MAC address, it finds which device is connected to a specified switch port. The port is specified in the form:
<switch name>:<port number>
An optional breakout port can be specified with:
<switch name>:<port number>s <breakout port number>
and several ports can be queried in one command.
Example
When only one port is queried, just the matching hostname is shown. When several ports are queried, each line is prefixed with the <switch name>:<port number> that was looked up. As with showport, the lookup relies on the port-to-MAC mapping that CMDaemon has discovered for the switch. If no device is associated with a specified port, then no hostname is returned for that port.
3.9.8 The setmacviaswitchport Command
The setmacviaswitchport command, in device mode, sets the MAC address of a device based on the MAC address discovered on the switch port to which the device is connected. This is convenient when provisioning hardware whose MAC address is not yet known to CMDaemon, but whose switch port connection is known.
The --dry-run option finds the MAC addresses, but does not save the change. Device selection options such as -t (type), -n (nodes), and -c (category), can be used to act on a set of devices. The -f|--force option forces an overwrite of devices that already have a MAC set, and the --index option selects which MAC to use, in case the switch port has more than one MAC associated with it.
Example
The second column indicates whether the MAC was (or, for a dry run, would be) saved, while the last column gives the discovered MAC address, or the reason that no change was made. Running the command without the --dry-run option commits the discovered MAC addresses.
3.9.9 The checkfactorydefaultpassword Command
The checkfactorydefaultpassword command, in device mode, checks whether switches still have their factory default password set, by attempting to authenticate against them. With the --update option, it also changes the factory password to the target password that is defined in the accesssettings submode of the device. Switches can be selected by name, by a range of names, or with device selection options such as -t switch.
Example
Without the --update option the command only reports the status, and does not modify any passwords.
3.10 Additional device Mode Node Commands And Submodes
Besides the switch-oriented commands of the preceding section, device mode provides several commands and submodes for inspecting and configuring devices, including nodes.
3.10.1 The nodeoverview Command
The nodeoverview command displays a brief summary for a node. This includes its uptime, load averages, memory and workload manager (WLM) slot usage, per-interface network throughput, and per-mount disk usage. If no node is specified, then the current node is used.
Example
3.10.2 The additionalnodeinformation Command
The additionalnodeinformation command is run on a set of nodes, and displays administrator-registered information commands for those nodes. The set of registered commands can be listed with the --list option. The -a|--run-on-active-head-node option runs the command on the active head node instead of on the node itself. Nodes are selected with the usual selection options, such as -n, -c, or -r.
Example
Here info-1 and info-2 are the names of administrator-registered information commands. If no commands have been registered, then --list returns nothing.
Setting up the commands can be done with the cm-manipulate-advanced-config.py command (section C.80.0.1, Managing Key/Value Pairs With The cm-manipulate-advanced-config.py Utility) as follows:
Example
and then restarting cmd with systemctl restart cmd.
An example of a script for info-1.sh is:
Example
That script can then be run with:
Example
3.10.3 The minimalconfig Command
The minimalconfig command shows the minimal set of configuration objects that apply to a node. This includes the category, configuration overlays, head nodes, monitoring data producers, and other entities that make up a node configuration. It is useful when troubleshooting why a particular setting or monitoring item for a node may not work. If no node is specified, then the current node is used.
Example
3.10.4 The checkremotemount Command
The checkremotemount command checks the status of remote mounts on a set of nodes. The mount to check is given as a path by default. The --file option evaluates the path as a file instead of a directory, the -f|--force option forces an update of the cached mounts data, and the --clear option clears the mount cache data. Nodes are selected with the usual selection options.
Example
The columns show the node, the number of matching mounts found, and the status of the mount.
3.10.5 The proxysettings Submode
The proxysettings submode, within device mode, configures the HTTP, HTTPS, and FTP proxy servers that a node uses, along with the list of hosts that should bypass the proxy.
Example
3.10.6 The selinuxsettings Submode
The selinuxsettings submode, within device mode, configures the SELinux behavior for a node, such as the SELinux mode and policy, whether to initialize SELinux, whether to reboot after a context restore, and the context actions to apply for the various install scenarios.
Example
SELinux is typically carried out right after a clean installation (Chapter 12 of the Installation Manual).
3.10.7 The remotedaemon Command
The remotedaemon command, in device mode, installs or removes the CMDaemon package on a device that already has an operating system running, without going through a BCM software-image provisioning cycle. This is intended for devices that were brought up by something other than BCM and then registered with it. A DPU that has already been installed by DPF is the primary example. DPF installs the DPU’s operating system independently of BCM, and remotedaemon install then deploys CMDaemon onto the already-running DPU, so that it can be managed and monitored by BCM. This is the same idea as cm-lite-daemon for switches, where the device’s own operating system is left in place and only the BCM daemon is added to it.
The device must already be defined in BCM before remotedaemon is used. The command does not create the device object.
Example
Options to remotedaemon include:
-
install: Install the CMDaemon package on the specified devices. The-f|--forceoption reinstalls CMDaemon even if it is already present. -
remove: Remove the CMDaemon package from the specified devices. The--purge-repooption also removes the BCM package repository configuration from the device.
Prerequisites for remotedaemon install are:
-
The target device is already defined in BCM as a compute node.
-
The target is running Ubuntu, and is reachable over SSH from the active head node using the device access settings (username and password) configured for it.
-
The target can reach the active head node over HTTPS, to fetch packages and its node certificate.
3.11 Configuring The NetQ Network Management System
NetQ telemetry data values are produced by NetQ. A running NetQ server can be integrated with BCM by configuring its credentials and connectivity settings in the netqsettings submode from within the partition mode of BCM:
Example
The corresponding Base View navigation path for this is using:
Cluster > Settings > BMC Settings > NetQ > +
With Kubernetes, NetQ can also be configured with the NetQ operator (section 6.9 of the Containerization Manual).
Connecting to the NetQ server allows NetQ telemetry data values to be picked up by BCM. These values are then treated as measurables (section 10.2.1). NetQ measurables (sections G.1.13 and G.2.4) can be managed and displayed with BCM just like other measurables.
3.12 Configuring UFM
UFM, the NVIDIA Unified Fabric Manager, is a fabric manager, that handles routing on the fabric. An optional component, UFM Host Agent, allows performance to be monitored. A running UFM server can be integrated with BCM by configuring its credentials and connectivity settings in the ufmsettings submode from within the partition mode of BCM. This is very similar to how NetQ settings (section 3.11) are managed:
Example
The corresponding Base View navigation path for this is using:
Cluster > Settings > BMC Settings > UFM settings> +
3.13 Disk Layouts: Disked, Semi-Diskless, And Diskless Node Configuration
Configuring the disk layout for head and regular nodes is done as part of the initial setup (section 3.3.16 of the Installation Manual). For regular nodes, the disk layout can also be re-configured by BCM once the cluster is running. For a head node, however, the disk layout cannot be re-configured after installation by BCM, and head node disk layout reconfiguration must then therefore be treated as a regular Linux system administration task, typically involving backups and resizing partitions.
The remaining parts of this section on disk layouts therefore concern regular nodes, not head nodes.
3.13.1 Disk Layouts
A disk layout is specified using an XML schema (Appendix D.1). The disk layout typically specifies the devices to be used, its partitioning scheme, and mount points. Possible disk layouts include the following:
-
Default layout (Appendix D.3)
-
Hardware RAID setup (Appendix D.4)
-
Software RAID setup (Appendix D.5)
-
LVM setup (Appendix D.7)
-
Diskless setup (Appendix D.9)
-
Semi-diskless setup (Appendix D.10)
3.13.2 Disk Layout Assertions
Disk layouts can be set to assert
-
that particular hardware be used, using XML element tags such as
vendororrequiredSize(Appendix D.11) -
custom assertions using an XML
assertelement tag to run scripts placed in CDATA sections (Appendix D.12)
3.13.3 Changing Disk Layouts
A disk layout applied to a category of nodes is inherited by default by the nodes in that category. A disk layout that is then applied to an individual node within that category overrides the category setting. This is an example of the standard behavior for categories, as mentioned in section 2.1.3.
By default, the cluster is configured with a standard layout specified in section D.3. The layouts can be accessed from Base View or cmsh, and a template layout can be used. A diskless node template can also be used, to change a node from a disked to a diskless node, as illustrated by the example here.
3.13.4 Changing A Disk Layout Using Base View
To change a disk layout with Base View, the current disk layout is accessed by selecting a node category or a specific node from the resource tree in the navigation panel. For a node node001, the navigation path is:
Devices > All Devices > node001 > Disk Setup(a tabbed window)> Devices > 
and it brings up the window shown in figure 3.12:
Figure 3.12: Changing a disked node to a diskless node with Base View
However, in a default installation, the values for the devices in the disk layout are inherited from the category level, which can only be modified at category level. That means the default disk layout values are initially read-only values, with the values that were set up during installation (section 3.3.16 of the Installation Manual).
At node level, values can be written so that they override the inherited values. Writing values at node level can be done using the Select Disk Setup button in various ways:
-
The
Select Disk Setupbutton brings up an option to copy from the category.If copying over from the category is carried out, then the XML entries in the
Devices > screen (figure 3.13) can be edited at node level (are no longer read-only):
Figure 3.13: Editing disk layouts with Base View
-
The
Select Disk Setupbutton also presents aSelect from templatemenu option, which shows several possible ready-made configurations that can be loaded up from the CMDaemon database. A selected copy can also be edited to suit the situation.The XML schema for a node configured for diskless operation is shown in Appendix D.9. This can often be deployed as is, or it can be modified during deployment using Base View or
cmsh.3.13.4.1 Changing A Disk Layout From Disked To Diskless
One of the templates that can be used to switch from the existing disk layout to a diskless one is
slave-diskless.xml. This XML configuration template can be loaded using theSelect from templatebutton, and saved to the node or node category. -
The
Select Disk Setupbutton also presents aSelect Filemenu option, which can be used to upload a custom configuration via the browser.
3.13.5 Changing A Disk Layout Using cmsh
To edit an existing disk layout from within cmsh, the existing XML configuration is accessed by editing the disksetup property in device mode for a particular node, or by editing the disksetup property in category mode for a particular category. Editing is done using the set command, which opens up a text editor:
Example
After editing and saving the XML configuration, the change is then committed to CMDaemon with the commit command. It should be understood that a disk layout XML configuration is not stored in a file on the filesystem, but in the CMDaemon database. The XML configurations that exist on a default cluster at
/cm/images/default-image/cm/local/apps/cmd/etc/htdocs/disk-setup/
and
/cm/local/apps/cmd/etc/htdocs/disk-setup/
are merely default configurations.
If the disksetup setting for a device is deleted, using the clear command, then the category level disksetup property is used by the device. This is in accordance with the usual behavior for node values that override category values (section 2.1.5).
Instead of editing an existing disk layout, another XML configuration can also be assigned. A diskless configuration may be chosen and set as follows:
Example
In these preceding Base View and cmsh examples, after committing the change and rebooting the node, the node then functions entirely from its RAM, without using its own disk.
However, RAM is usually a scarce resource, so administrators often wish to optimize diskless nodes by freeing up the RAM on them from the OS that is using the RAM. Freeing up RAM can be accomplished by providing parts of the filesystem on the diskless node via NFS from the head node. That is, mounting the regular node with filesystems exported via NFS from the head node. The details of how to do this are a part of section 3.14, which covers the configuration of NFS exports and mounts in general.
3.14 Configuring NFS Volume Exports And Mounts
NFS allows NFS clients shared access to a filesystem on an NFS server. The accessed filesystem is called an NFS volume by remote machines. The NFS server exports the filesystem to selected hosts or networks, and the clients can then mount the exported volume locally.
An unformatted filesystem cannot be used. The drive must be partitioned beforehand with fdisk or similar partitioning tools, and its filesystem formatted with mkfs or similar before it can be exported.
In BCM, the head node is typically used to export an NFS volume to the regular nodes, and the regular nodes then mount the volume locally.
-
NFS can be made to work at higher speeds with remote direct memory access (RDMA), by bypassing the CPU. If there is RDMA hardware present, and if the
rdma-corepackage is installed, then the RDMA service works automatically in RHEL 8 and 9.The settings that determine client module loading are set in the file
/etc/rdma/modules/rdma.confso that the service auto-loads by default. -
An alternative to NFS over RDMA for very fast file systems is the massively parallel and free (GPLv2) Lustre filesystem, running over InfiniBand.
3.14.0.1 Automounting With NFS
If auto-mounting is used, then the configuration files for exporting should be set up on the NFS server, and the mount configurations set up on the software images. The service “autofs” or the equivalent can be set up using Base View via the “Services” option (section 3.15) on the head and regular nodes or node categories. With cmsh the procedure to configure auto-mounting on the head and regular nodes could be:
Example
Filesystems imported to a regular node via an auto-mount operation must explicitly be excluded in excludelistupdate by the administrator, as explained in section 5.6.1.2, here.
3.14.0.2 Dropping All Use Of NFS Version 3
At the time of writing, (August 2025), the default NFS protocol versions used in BCM are a mixture of version 3 and 4. This is because some aspects of NFS version 4 clients in BCM have not yet been extensively tested. Migrating the remaining version 3 parts over to version 4 is therefore still experimental. If, despite this, the cluster administrator would still like to migrate over to the use of only NFS version 4 clients, then it can be carried out as follows:
The following configuration files should be modified:
-
/etc/nfs.conf: On all nodes, changing the default value ofvers3=yby adding the line -
/etc/nfsmount.conf: On the head node(s), changing the lineNfsvers=3(the BCM default) to -
/cm/node-installer*/scripts/node-installer.conf: On the head node(s), adding the line -
/cm/node-installer*/scripts/initrd_linuxrc: On the head node(s), modifying thenolockentries:so that the
vers=4option is explicitly specified:
The changes can be deployed by rebuilding the ramdisk:
Example
and then rebooting the head and regular nodes.
The rest of this section describes the configuration of NFS for static mounts, using Base View or cmsh.
Sections 3.14.1 and 3.14.2 explain how exporting and mounting of filesystems is done in general by an administrator using Base View and cmsh, and considers some mounting behavior that the administrator should be aware of.
Section 3.14.3 discusses how filesystems in general on a diskless node can be replaced via mounts of NFS exports.
Section 3.14.4 discusses how OFED InfiniBand or iWarp drivers can be used to provide NFS over RDMA.
3.14.1 Exporting A Filesystem Using Base View And cmsh
3.14.1.1 Exporting A Filesystem Using Base View
basecm11:/modeldata” it can be exported using Base View using the head node navigation path:Devices > All Devices > Head Node > > Settings > Filesystem exports > This shows the list of exports (figure 3.14):
Figure 3.14: NFS exports from a head node viewed using Base View
Using the + Add button, a new entry (figure 3.15) can be configured with values as shown:
Figure 3.15: Setting up an NFS export using Base View
For this example, the value for “Name” is set arbitrarily to “Fluid Model Data”, the value for Path is set to /modeldata, and the value for Network is set from the selection menu to allowing access to internalnet (by default 10.141.0.0/16 in CIDR notation).
By having the Write option disabled, read-only access is kept.
Saving this preceding configuration means the NFS server now provides NFS access to this filesystem for internalnet.
The network can be set to other network values using CIDR notation. It can also be set to particular hosts such as just node001 and node002, by specifying a value of “node001 node002” instead. Other settings and options are also possible and are given in detail in the man pages for exports(5).
3.14.1.2 Exporting A Filesystem Using cmsh
The equivalent to the preceding Base View NFS export procedure can be done in cmsh by using the fsexports submode on the head node (some output elided):
Example
3.14.1.3 General Considerations On Exporting A Filesystem
Built-in exports: In versions of NVIDIA Base Command Manager prior to version 9.0, all filesystem exports could be removed from the fsexports submode, simply by using the remove command with the name of the export.
From version 9.0 onward however, the following filesystem exports:
-
/var/spool/burn -
/home -
/cm/shared
are treated as special built-ins.
Head node role and disableautomaticexports: Built-ins are exported automatically as part of the headnode role, also introduced in NVIDIA Base Command Manager 9.0, and cannot simply be removed.
To disable export of the built-in file systems, the disableautomaticexports command must be run in the headnode role for that node:
Example
Disabling exports that are not built-ins: Exports that are not built-ins can still simply be removed. However, also from NVIDIA Base Command Manager 9.0 onward they can also simply be disabled in the fsexports submode. For example there is an export created by the cluster administrator for /opt, it can be disabled as follows:
Example
The reason for automating the export for nodes via a headnode role is that NVIDIA Base Command Manager 9.0 onward has multidistro and multiarch capabilities (section 9.7), which would make manual management of exports harder for such nodes. The reason for the extra hurdle of disableautomaticexports for built-ins is that disabling these exports can result in an unbootable system.
3.14.2 Mounting A Filesystem Using Base View And cmsh
Continuing on with the Fluid Model Data export example from the preceding section, the administrator decides to mount the remote filesystem over the default category of nodes. Nodes can also mount the remote filesystem individually, but that is usually not a common requirement in a cluster. The administrator also decides not to re-use the exported name from the head node. That is, the remote mount name modeldata is not used locally, even though NFS allows this and many administrators prefer to do this. Instead, a local mount name of /modeldatagpu is used, perhaps because it avoids confusion about which filesystem is local to a person who is logged in, and perhaps to emphasize the volume is being mounted by nodes with GPUs.
3.14.2.1 Mounting A Filesystem Using Base View
In Base View the navigation path to manage the mount points of nodes in the category of default is:
Grouping > Categories[default] > Settings > Extended settings > Filesystem mounts >
A mount point can be added with the + Add button. Values for the remote mount point (basecm11:/modeldata), the filesystem type (nfs), and the local mount point (/modeldatagpu) can then be set for the category, while the remaining options stay at their default values (figure 3.16):
Figure 3.16: Setting up NFS mounts on a node category using Base View
Saving the configuration saves the values and creates the local mount point, so that the volume can then be accessed by nodes within that category.
3.14.2.2 Mounting A Filesystem Using cmsh
The equivalent to the preceding Base View NFS mount procedure can be done in cmsh by using the fsmounts submode, for example on the default category. The add method under the fsmounts submode sets the mountpoint path, in this case /modeldatagpu (some output elided):
Example
Values can be set for Mount options other than default. For example, the noac flag can be added as follows:
Mounting a CIFS might use:
A _netdev mount option to make systemd wait until the network is up before it is mounted can be added as follows:
3.14.2.3 General Considerations On Mounting A Filesystem
There may be a requirement to segregate the access of nodes. For example, in the case of the preceding, because some nodes have no associated GPUs.
Besides the “Allowed hosts” options of NFS exports mentioned earlier in section 3.14.1.1, BCM offers two more methods to fine tune node access to mount points:
-
Nodes can be placed in another category that does not have the mount point.
-
Nodes can have the mount point set, not by category, but per device within the
Nodesresource. For this, the administrator must ensure that nodes that should have access have the mount point explicitly set.
Other considerations on mounting are that:
-
When adding a mount point object:
-
The settings take effect right away by default on the nodes or node categories.
-
If
noautois set as a mount option, then the option only takes effect on explicitly mounting the filesystem. -
If “
AutomaticMountAll=0” is set as a CMDaemon AdvancedConfig directive (Appendix C.104, here), then CMDaemon changes for/etc/fstabare written to the file, but themount -acommand is not run by CMDaemon. However, the administrator should be aware that sincemount -ais run by the distribution during booting, a node reboot implements the mount change.
-
-
While a mount point object may have been removed, umount does not take place until reboot, to prevent mount changes outside of the cluster manager. If a umount needs to be to done without a reboot, then it should be done manually, for example, using the
pdshorpexeccommand (section 14.1.0.1), to allow the administrator to take appropriate action if umounting goes wrong. -
When manipulating mount points, the administrator should be aware which mount points are inherited by category, and which are set for the individual node.
-
In Base View, for a node, inheritance by category is indicated in the navigation path
Devices>Nodes[node name]>Edit>Settings>Filesystem mounts, under theINHERITEDcolumn, with the entry(Category). -
In
cmsh, the category a mount belongs to is displayed in brackets. This is displayed from within thefsmountssubmode of thedevicemode for a specified node:Example
To remove a mount point defined at category level for a node, it must be removed from within the category, and not from the specific node.
-
3.14.2.4 Mount Order Considerations
Care is sometimes needed in deciding the order in which mounts are carried out.
-
For example, if both
/usr/share/docand a replacement directory subtree/usr/share/doc/compat-gcc-34-3.4.6javaare to be used, then the stacking order should be that/usr/share/docis mounted first. This order ensures that the replacement directory subtree overlays the first mount. If, instead, the replacement directory were the first mount, then it would be overlaid, inaccessible, and inactive. -
There may also be dependencies between the subtrees to consider, some of which may prevent the start up of applications and services until they are resolved. In some cases, resolution may be quite involved.
The order in which such mounts are mounted can be modified with the up and down commands within the fsmounts submode of cmsh.
3.14.3 Mounting A Filesystem Subtree For A Diskless Node Over NFS
3.14.3.1 NFS Vs tmpfs For Diskless Nodes
For diskless nodes (Appendix D.9), the software image (section 2.1.2) is typically installed from a provisioning node by the node-installer during the provisioning stage, and held as a filesystem in RAM on the diskless node with the tmpfs filesystem type.
It can be worthwhile to replace subtrees under the diskless node filesystem held in RAM with subtrees provided over NFS. This can be particularly worthwhile for less frequently accessed parts of the diskless node filesystem. This is because, although providing the files over NFS is much slower than accessing it from RAM, it has the benefit of freeing up RAM for tasks and jobs that run on diskless nodes, thereby increasing the cluster capacity.
An alternative “semi-diskless” way to free up RAM is to use a local disk on the node itself for supplying the subtrees. This is outlined in Appendix D.10.
3.14.3.2 Moving A Filesystem Subtree Out Of tmpfs To NFS
To carry out subtree provisioning over NFS, the subtrees are exported and mounted using the methods outlined in the previous examples in sections 3.14.1 and 3.14.2. For the diskless case, the exported filesystem subtree is thus a particular path under /cm/images/ <image> on the provisioning node, and the subtree is mounted accordingly under / on the diskless node. By default, <image> is default-image on a newly-installed cluster.
While there are no restrictions placed on the paths that may be mounted in NVIDIA Base Command Manager 11, the administrator should be aware that mounting certain paths such as /bin is not possible.
When Base View or cmsh are used to manage the NFS export and mount of the subtree filesystem, then tmpfs on the diskless node is reduced in size due to the administrator explicitly excluding the subtree from tmpfs during provisioning.
An example might be to export /cm/images/default-image from the head node, and mount the directory available under it, usr/share/doc, at a mount point /usr/share/doc on the diskless node. In cmsh, such an export can be done by creating an FS export object corresponding to the software image object defaultimage with the following indicated properties (some prompt output elided):
Example
As the output to list shows, the NFS export should be kept read-only, which is the default. Appropriate parts of the export can then be mounted by a node or node category. The mount is defined by setting the mount point, the nfs filesystem property, and the export device. For example, for a node category (some output elided):
Other mount points can be also be added according to the judgment of the system administrator. Some consideration of mount order may be needed, as discussed here under the subheading “Mount Order Considerations”.
3.14.3.3 An Example Of Several NFS Subtree Mounts
The following mounts save about 440MB from tmpfs on a diskless node with Rocky Linux 8, as can be worked out from the following subtree sizes:
The filesystem mounts can then be created using the techniques in this section. After doing that, the result is then something like (some lines omitted):
Diskless nodes that have NFS subtree configuration carried out on them can be rebooted to start them up with the new configuration.
3.14.4 Configuring NFS Volume Exports And Mounts Over RDMA With OFED Drivers
If running NFS over RDMA, then at least NFS version 4.0 is recommended. NFS version 3 will also work with RDMA, but uses IPoIB encapsulation instead of native verbs. NFS version 4.1 uses the RDMA Connection Manager (librdmacm), instead of the InfiniBand Connection Manager (ib_cm) and is thereby also able to provide pNFS.
The administrator can set the version of NFS used by the cluster by setting the value of Nfsvers in the file /etc/nfsmount.conf on the head node(s).
3.14.4.1 Drivers To Use For NFS Over RDMA
The DOCA Mellanox OFED drivers (Chapter 10 of the Installation Manual) can support using the RDMA protocol (section 3.6) to provide NFS.
The distribution OFED drivers also support NFS over RDMA.
When using NFS over RDMA, ibnet, the IP network used for InfiniBand, should be set. Section 3.6.4 explains how that can be done.
3.14.4.2 Exporting With Base View And cmsh Using NFS Over RDMA
With the drivers installed, a volume export can be carried out using NFS over RDMA.
The procedure using Base View is much the same as done in section 3.14.1 (“Exporting A Filesystem Using Base View”), except for that the ibnet network should be selected instead of the default internalnet, and the “RDMA” option should be enabled.
The procedure using cmsh is much the same as done in section 3.14.1 (“Exporting A Filesystem Using cmsh”), except that the ibnet network (normally with a recommended value of 10.149.0.0/16) should be set, and the rdma option should be set.
Example
(based on the example in section 3.14.1)
3.14.4.3 Mounting With Base View And cmsh Using NFS Over RDMA
The mounting of the exported filesystems using NFS over RDMA can then be done.
The procedure using Base View is largely like that in section 3.14.2.1, (“Mounting A Filesystem Using Base View”), except that the Device entry must point to master.ib.cluster so that it resolves to the correct NFS server address for RDMA, and the checkbox for NFS over RDMA must be ticked.
The procedure using cmsh is similar to that in section 3.14.2.2, (“Mounting A Filesystem Using cmsh”), except that device must be mounted to the ibnet, and the rdma option must be set, as shown:
Example
(based on the example in section 3.14.2.2)
3.15 Managing And Configuring Services
3.15.1 Why Use The Cluster Manager For Services?
Linux administrators should be familiar with managing services from the command line using systemctl:
Example
where <service name> indicates a service such as mysqld, mariabd, nfs, postfix and so on.
Services can also be managed with BCM. That is, they can also be started and stopped with Base View and cmsh tools.
An additional convenience that comes with the cluster manager tools is that some CMDaemon parameters useful for managing services in a cluster are very easily configured, whether on the head node, a regular node, or for a node category. These parameters are:
-
monitored: checks periodically if a service is running. Information is displayed and logged the first time it starts or the first time it dies -
autostart: restarts a failed service that is beingmonitored.-
If
autostartis set toon, and a service is stopped using BCM, then no attempts are made to restart the service. Attempted autostarts become possible again only after BCM starts the service again. -
If
autostartis set toon, and if a service is removed using BCM, then the service is stopped before removal. -
If
autostartisoff, then a service that has not been stopped by CMDaemon still undergoes an attempt to restart it, if-
CMDaemon is restarted
-
its configuration files are updated by CMDaemon, for example in other modes, as in the example here.
-
-
-
runif: (only honored for nodes used as part of a high availability configuration (Chapter 15)) whether the service should run with a state of:-
active: run on the active node only -
passive: run on the passive only -
always: run both on the active and passive -
preferpassive: preferentially run on the passive if it is available. Valid only for head nodes. Invalid for failover groups (section 15.5.3.3).
BCM can be used to keep a service working across a failover event with an appropriate
runifsetting and appropriate failover scripts such as thePrefailover scriptand thePostfailover script(section 15.4.6.7). The details of how to do this will depend on the service. -
The details of a service configuration remain part of the configuration methods of the service software itself.
-
Thus BCM can run actions on typical services only at the generic service level to which all the unix services conform. This means that CMDaemon can run actions such as starting and stopping the service. If the restarting action is available in the script, then CMDaemon can also run that.
-
The operating system configuration of the service itself, including its persistence on reboot, remains under control of the operating system, and is not handled by CMDaemon. So, stopping a service within CMDaemon means that by default the service may start up on reboot. Running
systemctl disable <service name>.servicefrom the command line can be used to configure the service to no longer start up on reboot.
For convenience, BCM provides a systemctl command in cmsh to provide an overview of the status of units such as services (section 3.15.2.4, here).
3.15.2 Managing And Configuring Services—Examples
If, for example, the CUPS software is installed in an image with the help of cm-chroot-sw-img, and the nodes rebooted, then the CUPS service can be managed in several ways:
3.15.2.1 Managing The Service From The Regular Shell, Outside Of CMDaemon
Standard unix commands from the bash prompt work, as shown by this session:
3.15.2.2 Managing The Service From cmsh
Listing existing services managed by cmsh: Services that are managed by cmsh can be listed by the list command in services mode at device level. They mostly run on the head node. For example, on a standard BCM head node without workload managers or Kubernetes:
Example
These services are typically provided by BCM roles (section 2.1.5). For example, assigning the boot role to a node means that it runs the dhcpd service, which allows the netbooting of nodes from that node.
The services not managed by BCM are not listed in services mode, until they are configured to be managed by BCM. For example, cron is not listed in services mode unless it is added to services mode.
The overview command displays the list command output in a different way, along with the runif property.
Example
Adding and starting the service in cmsh: The following session illustrates adding the CUPS service from within device mode and the services submode. The device in this case is a regular node, node001, but a head node can also be chosen. Monitoring and auto-starting are also set in the session:
Other service options in cmsh:
Within the services submode of cmsh, the commands:
-
start -
stop -
restart -
update -
reload
can be used to manage the service.
These commands correspond to the modern systemctl options, as in the syntax:
systemctl start|stop|restart|... <service name>
For example, continuing with the preceding session, stopping the CUPS service can be done by running the stop option as follows:
Example
The service is then in a STOPPED state according to the status command.
Details on how a state is used when monitoring a service are given in the section Monitoring A Service With cmsh And Base View here.
Continuing from the preceding session, the CUPS service can also be added for a node category from category mode:
As before, after adding the service, the monitoring and autostart parameters can be set for the service. Also as before, the options to the service <service name> start|stop|restart|... command can be used to manage the service at the services submode level. The settings apply to the entire node category (some lines elided):
Example
Unlike at device level (here), the list command for the services submode at category level lists only the services that have been manually-configured by cmsh or Base View in that mode. So, services defined by roles are not included in the category-level list.
The status command lists all the services managed by BCM in a category, which includes the ones defined by roles:
Example
3.15.2.3 Removing A Service From CMDaemon Control Without Shutting It Down
Removing a service from BCM control while autostart is set to on stops the service on the nodes:
In the preceding cmsh session, cups starts up when the autostart parameter is committed, if cups is not already up.
The behavior of having the service stop on removal is implemented because it is usually what is wanted.
However, sometimes the administrator would like to remove the service from CMDaemon control without it shutting down. To do this, autostart must be set to off first.
3.15.2.4 Querying Service Information With systemctl
Services are the most common type of systemd unit. The systemctl command displays the status of systemd units on a device.
A service status overview can be carried out on devices using the BCM systemctl command in cmsh device mode. Running it presents information about services, mounts, slices, timers, and targets including their load state, active state, and sub-state:
Example
The systemctl command has options to run it per node, category, rack, and so on. Details on the options can be seen by running the help command (help systemctl).
3.15.2.5 Managing The Service From Base View
Using Base View, a service can be managed from an OSServiceConfig list window, accessible via the Services section of the Settings tab window. The OSServiceConfig list window is accessible for
-
Head nodes, for example using a navigation path of
Devices > All Devices > Head Node > Settings > Services -
regular nodes, for example for
node001using a navigation path ofDevices > All Devices > node001 > Settings > Services(figure 3.17):
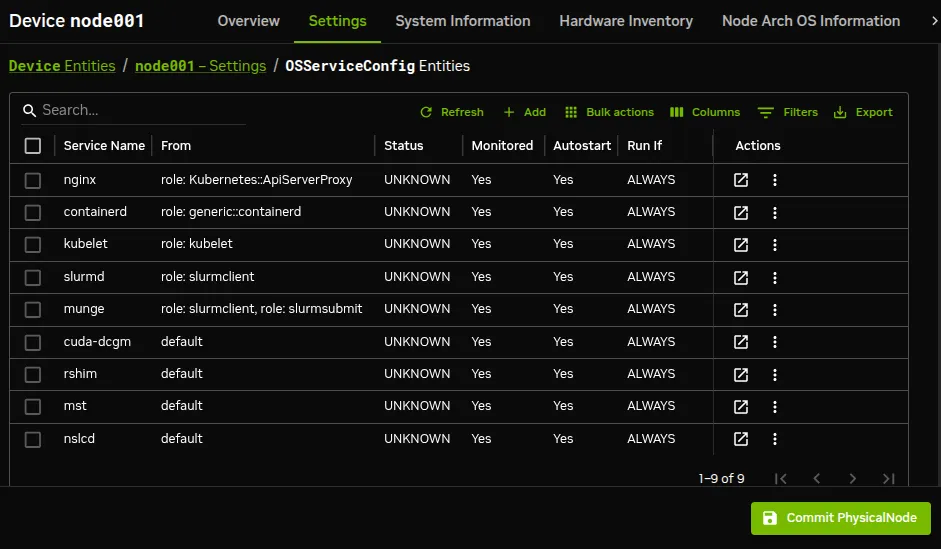
Figure 3.17: Operating system service configuration list window for nodes in Base View
- Node categories, for example using a navigation path of
Grouping > Categories > Settings > Services
A service can be added with the +Add button, and fields of the service can then be edited.
Figure 3.18 shows CUPS in the services window of Base View (figure 3.18).
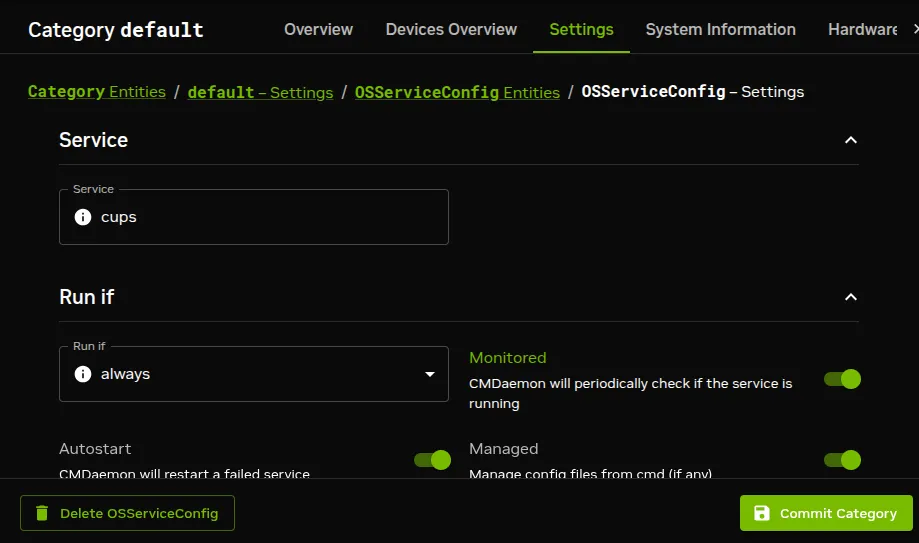
Figure 3.18: Setting up a service using Base View
The service command options start, stop, restart, and so on, are displayed as options when clicking on the ⋮ in the Actions column (figure 3.19):
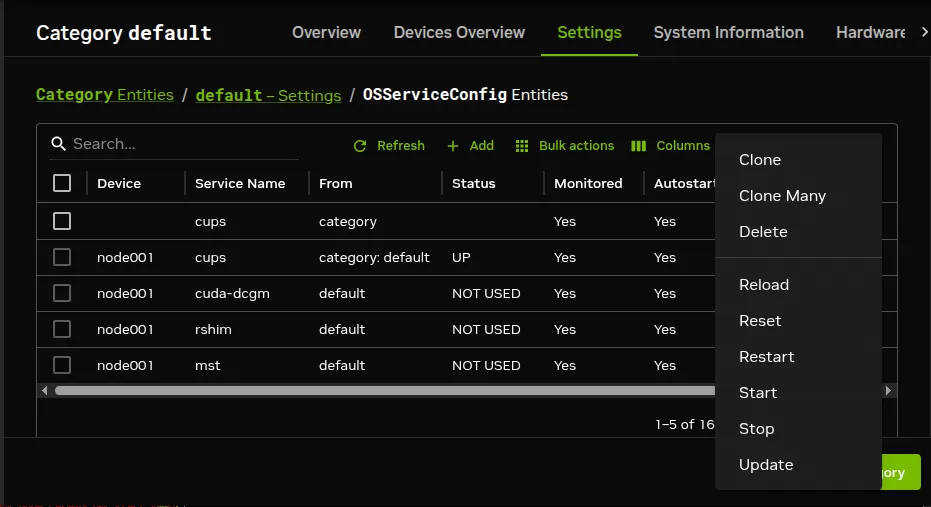
Figure 3.19: Operating system service options, seen after clicking on ⋮ in Actions column in Base View
3.15.2.6 Monitoring A Service With cmsh And Base View
The service is
-
in a
DOWNstate if it is not running, and -
in a
FAILINGstate if it is unable to run after 10 auto-starts in a row
Event messages are sent during these first 10 auto-starts. After the first 10 auto-starts, no more event messages are sent, but autostart attempts continue.
In case an autostart attempt has not yet restarted the service, the reset option may be used to attempt an immediate restart. The reset option is not a service option in the regular shell, but is used by CMDaemon (within cmsh and Base View) to clear a FAILING state of a service, reset the attempted auto-starts count to zero, and attempt a restart of the service.
The monitoring system sets the ManagedServicesOk health check (Appendix G.2.1) to a state of FAIL if any of the services it monitors is in the FAILING state. In cmsh, the statuses of the services are listed by running the latesthealthdata command (section 10.6.3) from device mode.
Standard init.d script behavior is that the script return a non-zero exit code if the service is down, and a zero exit code if the service is up. A non-zero exit code makes BCM decide that the service is down, and should be restarted.
However, some scripts return a non-zero exit code even if the service is up. These services therefore have BCM attempt to start them repetitively, even though they are actually running.
This behavior is normally best fixed by setting a zero exit code for when the service is up, and a non-zero exit code for when the service is down.
3.16 Managing And Configuring A Rack
3.16.1 Racks
A cluster may have local nodes grouped physically into racks. A rack is 42 units in height by default, and nodes normally take up one unit.
3.16.1.1 Rack List
Rack list in Base View: The Rack list pane can be opened up in Base View via the navigation path Datacenter Infrastructure > Racks (figure 3.20):
Figure 3.20: Rack list using Base View
Racks can then be added, removed, or edited from the pane.
Within the Rack list pane:
-
a new rack item can be added with the
+ Addbutton. This opens up a rack configuration window where details of the new configuration can be entered and saved (figure 3.21). -
an existing rack item can be edited with the navigation path
> Settings. This opens up theSettingstab from within which rack configuration details can be managed.
-
The
listcommand inrackmode incmshallows racks defined in the cluster manager to be listed: -
The
rackoverviewcommand displays information about the types of entities in a specified rack. It also lists some more detailed information about some of the entity types:Example
-
The
displaycommand inrackmode is useful for visualizing where devices are located in the rack, if the cluster administrator has recorded the device positionsExample
Other rack overview commands allow the electrical supply, liquid cooling, leak detection, and leak detection-related actions to be viewed at rack level (section 3.3 of the NVIDIA Mission Control Manual).
3.16.1.2 Rack Configuration Settings
Rack configuration settings in Base View: A Settings tab for editing a rack item selected from the Rack list pane is shown in figure 3.21.
Figure 3.21: Rack configuration settings using Base View
Among the rack configuration attributes are:
-
Name: A unique name for the rack item. Names such asrack001,rack002are a sensible choice. -
Room: A unique name for the room the rack is in. -
Position: The x- and y-coordinates of the rack in a room.These coordinates are meant to be a hint for the administrator about the positioning of the racks in the room, and as such are optional, and can be arbitrary numbers. The
Notesfield can be used as a supplement or as an alternative for hints. -
Height: by default this is the standard rack size of 42U. -
Inverted: Normally, a rack uses the number 1 to mark the top and 42 to mark the bottom position for the places that a device can be positioned in a rack. However, some manufacturers invert this and use 1 to mark the bottom instead. Enabling theInvertedsetting records the numbering layout accordingly for all racks, if the inverted rack is the first rack seen inRackview.
Rack configuration settings in cmsh: Tab-completion suggestions for the set command in rack mode display the racks available for configuration. Tab-completion suggestions can also display the configuration settings available for a specified rack, for example, rack2:
Example
The configuration settings for a particular rack match with the parameters of figure 3.21 and are discussed in the text that follows figure 3.21.
Setting the values can be done as in this example:
Example
3.16.2 Assigning Devices To A Rack
Devices such as nodes, switches, and chassis, can be assigned to racks.
By default, no such devices are assigned to a rack.
Devices can be assigned to a particular rack and to a particular position within the rack as follows:
3.16.2.1 Assigning Devices To A Rack Using Base View
Using Base View, a device such as a node node001 can be assigned to a rack using the navigation path (figure 3.22):
Devices > All Devices > node001 > Settings > Rack +
Figure 3.22: Rack assignment using Base View
3.16.2.2 Assigning Devices To A Rack Using cmsh
-
In
devicemode, nodes can be assigned to a position in a rack. For example:-
node001to position1 -
node002to position2 -
node003to position3
A looping instruction to do this in an existing rack
rack2is something similar to: -
-
The
addrackpositioncommand fills devices into a rack object more implicitly. By default the command fills devices into the first free slots on the rack.The first free
devicepositionvalue that it uses can be set with the--positionoption. Forcing a device into the the same position as another device is also possible, with the--forceoption.More options can be found using the
helptext for the command. -
The
rackpositionsubmode allows individual nodes to be managed directly:
A similar submode to rackposition is chassisposition (section 3.16.4).
3.16.2.3 The Convention Of The Top Of The Device Being Its Position
Since rack manufacturers usually number their racks from top to bottom, the position of a device in a rack (using the parameter Position in Base View, and the parameter deviceposition in cmsh) is always taken to be where the top of the device is located. This is the convention followed even for the less usual case where the rack numbering is from bottom to top.
A position on a rack is 1U of space. Most devices have a height that fits in that 1U, so that the top of the device is located at the same position as the bottom of the device, and no confusion is possible. The administrator should however be aware that for any device that is greater than 1U in height such as, for example, a blade enclosure chassis (section 3.16.3), the convention means that it is the position of the top of the device that is where the device is considered to be. The position of the bottom of the device is ignored.
3.16.3 Assigning Devices To A Chassis
3.16.3.1 A Chassis As A Physical Part Of A Cluster
In a cluster, several local nodes may be grouped together physically into a chassis. This is common for clusters using blade systems. Clusters made up of blade systems use less space, less hardware, and less electrical power than non-blade clusters with the same computing power. In blade systems, the blades are the nodes, and the chassis is the blade enclosure.
A blade enclosure chassis is typically 6 to 10U in size, and the node density for server blades is typically 2 blades per unit with 2014 technology.
3.16.3.2 Chassis Configuration And Node Assignment
Chassis in Base View: The Chassis pane can be added in Base View using the navigation path
Devices > All Devices > + Add > Chassis
This opens a Chassis pane where a new chassis object can be configured. Properties such as name, MAC address, rack location, can be set and saved (figure 3.23).
An existing chassis object, for example chassis01, can be edited by selecting it from the navigation path Devices > All Devices > chassis01
Figure 3.23: Base View chassis configuration
The options that can be set within the Chassis pane include the following:
-
Hostname: a name that can be assigned to the chassis operating system -
Mac: the MAC address of the chassis -
Model: the hardware model name -
Rack: the rack in which the chassis is placed -
Layout: how the nodes in a chassis are laid out visually. -
Network: which network the chassis is attached to. -
Access Settings: Opens up a pane to allow a user name and password to be set to access the chassis operating system, as well as the REST API port. -
Power control,Custom power script,Custom power script argument: power-related items for the chassis. -
BMC Settings: Baseboard Management Controller settings for the chassis. -
Userdefined1,Userdefined2: administrator-defined variables that can be used by CMDaemon.
Basic chassis configuration and node assignment with cmsh:
The chassis type in cmsh allows configuration related to a particular chassis. Tab-completion suggestions for a selected chassis with the set command show possible parameters that may be set:
Example
Whether the suggested parameters are actually supported depends on the chassis hardware. For example, if the chassis has no power control or network interface of its own, then the powercontrol value and mac address settings may be set, but they cannot function.
The positioning parameters of the chassis within an already-defined rack, rack2, can be set as follows with cmsh:
Example
The members of the chassis can be set as follows with cmsh:
Example
3.16.4 The chassisposition Submode
Section 3.16.2 described positioning attributes available in device mode, within the rackposition submode, for a device within a rack.
This section, describes positioning attributes available in device mode, within the chassisposition submode, for a device within a chassis.
Attributes include the chassis that the device belongs to, the slot, position, and width of the device within that chassis.
Example
3.16.5 Power Management Of Racks
Section 4.2 of this manual, describes the power operations and power status responses for devices in general, while section 4.9.4 of the NVIDIA Mission Control Manual goes into some more detail for particular rack operations.
3.17 Configuring GPU Settings
3.17.1 GPUs And GPU Units
GPUs (Graphics Processing Units) are processors that are heavily optimized for executing certain types of parallel processing tasks. GPUs were originally used for rendering graphics, and one GPU typically has hundreds of cores. When used for general processing, they are sometimes called General Processing GPUs, or GPGPUs. For convenience, the “GP” prefix for General Processing is not used in this manual.
A GPU is typically placed on a PCIe card. GPUs can be physically inside the node that uses them, or they can be physically external to the node that uses them. As far as the operating system on the node making use of the physically external GPUs is concerned, the GPUs are internal to the node.
If the GPUs are physically external to the node, then they are typically in a GPU unit. A GPU unit is a chassis that hosts only GPUs. It is typically able to provide GPU access to several nodes, usually via PCIe extender connections. This ability means that external GPUs typically require more configuration than internal GPUs. GPU units are not covered in this manual because they are not very popular due to their greater cost and slowness.
Configuring GPU settings for GPUs—that is, for devices internal to a node—is covered next.
3.17.2 Configuring GPU Settings
3.17.2.1 The gpusettings Submode In cmsh
In cmsh, GPUs can be configured for a specified node via device mode.
Going into the gpusettings submode for that node then allows a type of GPU to be set, from the amd or nvidia types, and a range to be specified for the GPU slots for that particular node:
Example
The range can be specified as
-
a single number, for a particular slot, for example:
3 -
a range, for a range of slots, for example:
0-2 -
all, for all GPU slots on that node, using:
allor
*
GPUs can also be configured for a specified category via category mode. For example, using the category default, then entering into the gpusettings submode allows a type (nvidia or amd) and a range to be set for the range of GPUs:
Example
As usual, GPU settings for a node override those for a category (section 2.1.3).
3.17.2.2 GPU Settings With NVIDIA GPUs
The installation of the NVIDIA GPU software driver packages is covered in section 9.1 of the Installation Manual. It should be noted that the cuda-dcgm package must be installed to access NVIDIA GPU metrics.
The present section is about configuring NVIDIA GPUs in BCM. The driver itself does not necessarily have to be in place for the configuration to be done, although the configuration only becomes active when the driver is installed.
After a GPU type has been set, the following NVIDIA GPU settings may be specified, if supported, from within the gpusettings submode:
-
clockspeeds: The pair of clock speeds (frequency in MHz) to be set for this parameter can be selected from the list of available speeds. The available speeds can be seen by running thestatuscommand. The values are specified in the form: <number for GPU processor>,<number for memory> -
clocksyncboostmode: GPU boosting. Exceed the maximum core and memory clock speeds if it is safe. Choices are:-
enabled -
disabled
-
-
computemode: Contexts can be computed with the following values for this mode:-
Default: Multiple contexts are allowed -
Exclusive thread: Only one context is allowed per device, usable from one thread at a time -
Exclusive process: Only one context is allowed per device, usable from multiple threads at a time. This mode option is valid for CUDA 4.0 and later. Earlier CUDA versions ran only in this mode. -
Prohibited: No contexts are allowed per device
-
-
eccmode: Sets the ECC bit error check, with:-
enabled -
disabled
When ECC is enabled:
-
-
GPU range: range values can be set as follows:-
all: The GPU settings apply to all GPUs on the node. -
<number>: The GPU settings apply to an individual GPU, for example:
1 -
<number range>: The GPU settings apply to a range of GPUs, for example:
1,3-5
-
-
powerlimit: The administrator-defined upper power limit for the GPU. Only valid ifpowermodeisSupported.-
min: The minimum upper power limit that the hardware supports. -
max: The maximum upper power limit that the hardware supports. -
<number>: An arbitrary upper power limit, specified as a number between
minandmax -
default: Upper power limit based on the default hardware value.
-
If no value is specified for a GPU setting, then the hardware default is used.
3.17.2.3 The updatedevicepowerconfig Command For Controlling Power Consumption
Above the gpusettings submode, within device mode, nodes can have their power consumption limited per specified GPU or CPU:
Without arguments, the updatedevicepowerconfig command shows the current status for GPUs:
Example
In the preceding example, the only node with a GPU is node001. The same result is therefore shown if the command is run as updatedevicepowerconfig -n node001.
The kind of processing unit that can have its power configuration examined and set can be either a GPU or CPU. A CPU status command can be specified by using the --kind option:
Example
The first and second GPUs on node001 can have their power limits set to the same value with a range syntax and the --power-limit option:
For the first GPU on node001, and for all CPUs on node002 the power limit, in watts, is set to specified values:
A dry-run option --dry-run shows the effect on both the GPUs without execution.
3.17.2.4 GPU Settings With AMD GPUs
GPU settings for AMD Radeon GPUs are accessed via cmsh in the same way as NVIDIA GPU settings. The AMD GPU setting parameters do differ from the NVIDIA ones.
The AMD GPUs supported are Radeon cards. A list of cards and operating systems compatible with the Linux driver used is at https://support.amd.com/en-us/kb-articles/Pages/Radeon-Software-for-Linux-Release-Notes.aspx
AMD GPU driver installation is described in section 7.4 of the Installation Manual.
The Radeon Instinct MI25 shows the following settings in Ubuntu 16_06 running a Linux 4.4.0-72-generic kernel:
Example
The possible values here are:
-
activitythreshold: Percent GPU usage at a clock level that is required before clock levels change. From 0 to 100. -
fanspeed: Maximum fan speed. From 0 to 255 -
gpuclocklevel: GPU clock level setting. From 0 to 7. -
gpurange: The slots used. -
hysteresisdown: Delay in milliseconds before a clock level decrease is carried out. -
hysteresisup: Delay in milliseconds before a clock level increase is carried out. -
info: A compact informative line about the GPU status. -
memoryclocklevel: Memory clock speed setting. From 0-3. Other cards can show other values. -
minimumgpuclock: Minimum clock frequency for GPU, in MHz. The kernel only allows certain values. Supported values can be seen using thestatuscommand. -
minimummemoryclock: Minimum clock frequency for the memory, in MHz. The kernel only allows certain values. Supported values can be seen using the status command. -
overdrivepercentage: Percent overclocking. From 0 to 20% -
powerplaymode: Decides how the performance level power setting should be implemented.-
high: keep performance high, regardless of GPU workload -
low: keep performance low, regardless of GPU workload -
auto: Switch clock rates according to GPU workload -
manual: Use the memory clock level and GPU clock values.
-
The status command displays supported clock frequencies (some values ellipsized):
Example
3.17.2.5 GPU Settings In Base View
In Base View, GPU settings can be accessed within the settings options for a category or a device. This brings up a GPU settings list.
GPU Settings list pane can be opened up in Base View for a regular node, for example node001, with the navigation path:Devices > All Devices > Nodes > Settings > GPU Settings GPU Settings list pane can be opened up in Base View for nodes in a category, for example gpunodes, with the navigation path:Grouping > Categories[gpunodes] > Settings > GPU Settings Within the GPU Settings list pane:
- a new GPU settings item can be added with the
+Addbutton, and then clicking on either theAMDor theNVIDIAitem in the popup. This opens anAMDGPUSettingspane or anNvidiaGPUSettingspane, where GPU configuration can be carried out and saved (figure 3.24).
Figure 3.24: GPU settings window for a node
- an existing GPU settings item can be edited with the ↗ option, which opens up the GPU Settings pane where GPU configuration can be managed.
3.17.2.6 GPU Configuration For HPC Workload Managers
Slurm GPU configuration via direct slurm.conf changes: To configure NVIDIA GPUs for Slurm, changes are made in slurm.conf when cm-wlm-setup configures GPUs for Slurm (section 7.3).
Changes made are kept in the AUTOGENERATED section and can be worked out by checking the difference between the slurm.conf.template file and the actual slurm.conf file. Changes made include defining the GresTypes gpu and mps, and setting GPU plugins that allow Slurm generic resources to work.
The configured gres options can be seen by running sbatch --gres=help:
Example
This means that a GPU can be requested in a job script with the Slurm gres option:
Similarly, MPS resources (https://slurm.schedmd.com/gres.html#MPS_Management) can be requested with:
If adding new parameters manually, care must be taken to avoid duplication of parameters already in the file, because slurmd is unlikely to work properly with duplicated parameters.
The Slurm client role can be configured at configuration overlay, category, or node level. If configuring the Slurm client role for GPU gres resources manually, then each GPU can be configured within the role:
Example
By default, Slurm just allows a single job to be executed per node. To change this behavior, it is necessary to allow oversubscription. For example, to allow 8 jobs per node:
Example
Slurm GPU configuration via auto-detection: Instead of carrying out Slurm configuration by modifying slurm.conf by hand, it may be configured via auto-detection. More details on this are to be found starting at here.
LSF: Within LSF cluster configuration, GPU devices can be autodetected by setting the gpuautoconfig parameter to yes. In cmsh this can be carried out with:
Example
The parameter can also be set during LSF configuration via cm-wlm-setup (figure 3.25):
Figure 3.25: GPU settings screen for LSF in cm-wlm-setup
GPU resource enforcement can be configured for LSF as follows:
Example
3.17.3 MIG Configuration
MIG configuration can be carried out for the cluster using the BCM MIG management as described in this section.
An alternative for MIG configuration is to not use the BCM MIG management tool (cmsh), and to instead use other MIG management tools, such as the DGX native nvidia-migmanager.service, or the GPU operator-provided nvidia-mig-manager. If non-BCM MIG management tools are used, then BCM leaves the MIG configuration alone. Using multiple MIG management tools simultaneously to configure MIG should not be done.
3.17.3.1 What Is MIG?
An Ampere NVIDIA GPU is a GPU based on the GA100 microarchitecture. It has compute capability 8.0, which means it can be configured into multiple logical GPU instances if it uses CUDA 11 and NVIDIA driver 450.80.02 or later.
This configuration of multiple logical GPU instances is called Multi-Instance GPU (MIG). The logical GPU instances are MIG devices, that are enabled by setting up the physical GPU to switch to MIG mode.
As a sanity check to see if MIG is supported: If the hardware and drivers are in place, then running the nvidia-smi command on the node with the physical GPU should display its MIG capability:
GPU utilization information changes on enabling MIG: Once enabled, the full physical GPU is no longer available as a device, and GPU utilization metrics become unavailable by default.
GPU profiling metrics (section G.1.7) for the physical GPU can however still be enabled. For example, it can be carried out with cmsh as follows, for a GPU on node001:
Example
Enabling physical GPU profiling after MIG enablement should be done with caution, because:
-
it may affect the performance
-
newer drivers may support MIG profiling, which may be confusing
3.17.3.2 Overview Of MIG Concepts And Terminology
The logical GPU instances are composed of slices of GPU resources. Slices are the smallest fraction possible of the resource that can be allocated in a logical GPU instance. Thus:
-
memory slice: this is the smallest fraction of the memory of the physical GPU that can be allocated to the GPU instance. For the Ampere architecture this is 1/8(th) of the total physical GPU memory.
-
SM slice: this is the smallest fraction of the streaming multiprocessors (SMs) on the GPU that can be allocated as a logical SM. An SM is composed of multiple cores (streaming processors). For the Ampere architecture an SM slice is 1/7(th) of the total physical GPU SMs.
-
GPU slice: this is the smallest fraction of the physical GPU that has a single GPU memory slice and a single GPU SM slice. A maximum of 7 GPU slices can be specified from the original physical GPU.
The preceding fractional slices can be combined in various mixes to compose a logical GPU instance:
-
GPU instance: a combination of GPU slices and GPU engines. GPU engines are hardware components that execute other work on the GPU, and can be encoders/decoders (NVENCs/NVDECs), shortcut connectors (CE (copy engine) for DMA), etc.
-
compute instance: a part of a GPU instance. It consists of a subset of the parent GPU instance’s SM slices and other GPU engines (DMAs, NVENCs …). The compute instances can share memory and GPU engines with other compute instances within their GPU instance.
Further details on the terminology and how slices can be allocated to GPU instances are given in the NVIDIA documentation at https://docs.nvidia.com/datacenter/tesla/mig-user-guide/#concepts.
A use case for creating several GPU instances from a full physical GPU is when allocation of the full physical GPU is wasteful.
For example, if a full physical GPU is allocated to a job, but the job only uses a fraction of the full set of GPU cores, then the allocation is wasteful, because no other job can then be processed on the remaining idle cores. Instead, if the physical GPU is split into several instances and the job allocated to an instance with a closer match in resources, then it means that other GPU instances are still available for processing other jobs.
When configuring GPU instances for the cluster, the administrator typically allocates all available slices to all the GPU instances that are being configured. Leaving a slice unallocated means that that slice cannot be available to jobs, and it means that the physical resources of that slice are lying idle. For example, if some of the 7 SM slices from the physical GPU are not used, then they are wasted as their processors are never available to jobs, and so that slice stays idle.
Cluster management of GPU instances is described in the following sections.
3.17.3.3 MIG Status Of Physical GPUs
The MIG status on a GPU can be viewed with the mig status command. For example, the following shows 8 physical GPUs on node001 that have not yet become MIG enabled:
Example
3.17.3.4 MIG enable And disable Options To Set Up Pending States For The Physical GPUs
If the enable or disable options are run, then by default all the physical GPUs are set to a pending state for enabled (yes) and disabled (no) respectively:
Example
Individual physical GPUs can also be set to a pending state of enabled or disabled, following the node list syntax (section 2.5.5.10):
3.17.3.5 Rebooting The MIG Instances To Activate/Deactivate Instances According To Pending State Settings
The pending states only become active after the node is rebooted for A100 GPUs:
Example
The effect of enable and disable persists after reboots, until the pending value changes once more.
For H100 GPUs and other more modern GPUs, the changes do not require a reboot.
3.17.3.6 The MIG Profiles
Listing MIG profiles: The full list of the existing available MIG profiles for each physical GPU is displayed with the mig profiles command for the node. If there are 7 physical GPUs at the node, then the listing might look something like:
Example
A list for physical GPU 1 can be displayed with:
Example
MIG profiles naming convention: The naming format for the profile takes the form
<number of GPU slices in the physical GPU>g.<memory for slice in GB>gb
The +me suffix implies media extensions being active. The number of GPU instances, the number of GPU slices used, and the memory used by the instance can thus be worked out from the name.
For example:
-
1g.5gbimplies that the size of the GPU slice used for the instances is 1. 4.7GiB of memory is used by each of the 7 GPU instances, -
2g.10gbimplies that the size of the GPU slice used for the instances is 2. 9.7GiB of memory is used by each of the 3 GPU instances.
Creating GPU instances, by setting the MIG profile for a GPU: The MIG profile is an attribute that can be set within the GPU settings for its physical GPU. This can be done after having set up a CMDaemon entity for a physical GPU 0 (section 3.17.2):
Example
-
A simple existing set of profiles with 7 GPU instances with 1 GPU slice each, and 5 GB of memory for each slice can be specified with:
Example
Setting the profiles, and carrying out the
commitconfigures the GPU instances, but does not yet apply them:Example
Applying the profile deploys the configuration, and shows the configuration:
Example
In the preceding, 1 GPU instance has been deployed, with 1 compute instance slice using 5GB. The instance with the
-represents the hosting GPU instance, while the subsequent row represents the compute instance. -
Setting a profile with
mig apply --profileis an alternative to setting it withingpusettings. However, only a profile set withingpusettingsis persistent. The profile set with the--profileoption is lost if its node reboots. Multiple profiles can be set using comma-separation (instead of using space-separation). Using multiple--profileoptions is also possible.Example
-
Multiple GPU instances can be specified, if the GPU allows it, using a <number>
*prefix syntax. So, to deploy 7 GPU instances, each hosting 1 compute instance with 5gb slices, the specification can be:Example
-
GPU slices can be implied by default by the profile, and subsets of these slices can be specified explicitly.
To deploy 1 GPU instance, with 7 GPU slices of compute instance resources, the specification can be:
Example
If a profile with a more than 1 GPU slice is chosen, then GPU slice subsets can be set up via the following syntax:
Example
-
GPU slices use a colon syntax to explicitly specify subsets of GPU slices.
The configuration specification
2g.10gbcan also be specified as2g.10gb:1, where that:1indicates the number of GPU slices for the compute instance, counting from zero. That means the compute instance has 2 GPU slices. The resulting configuration is exactly the same as2g.10g.If the specification
2g.10gb:0is used instead, then the compute instance ends up looking like:Example
Here the
1cindicates 1 GPU slice (here it is counting from 1).Adding another slice to a separate compute instance within the same GPU instance can be specified with:
Example
In the preceding
set migprofilescommand, the specification2g.10gb:0:0can alternatively be expanded out and written in the form:
2g.10gb:1c.2g.10gb:1c.2g.10gbfor more clarity, at the expense of more typing.
For a general profile that allows N GPU slices for an instance (with N ≤ 7), the mapping for the colon syntax takes the form:
In practice, there are hardware-based restrictions for what is permitted to be allocated. So for example on the NVIDIA A100-PCIE-40GB:
7g.40gb:3is allowed but7g.40gb:4is not.Details on supported profiles for hardware can be found in the NVIDIA MIG user guide documentation at https://docs.nvidia.com/datacenter/tesla/mig-user-guide/supported-mig-profiles.html, which covers, for example, the A30, A100, H100, and B200 profiles.
Increasing the number of GPU instances can also still be done using the earlier <number>
*prefix syntax together with the colon syntax, if the GPU allows it:Example
-
A heterogeneous set of existing profiles for GPU instances can also be defined for the GPU with MIG profiles.
For example, 2 instances with the MIG profile
1g.5gb, and 1 instance with the MIG profile2g.10gbcan be specified with: -
heterogeneous sets are useful when trying to use up all the slices available, to make the maximum resources available. So, while an administrator can carry out the preceding specification:
2*1g.5gb 2g.10gbthis is not a good allocation of resources since it only makes 4/7 of the GPU slices available, and 4/8 of the memory slices available. An administrator would more sensibly specify something like, for example:
5*1g.5gb,2g.10gbwhich uses up the full 7 GPU slices and 35GB (6/8 slices) of memory available from the physical GPU. This makes full use of the SM resources derived from the physical GPU, so that these SM resources are fully available to workloads.
-
Overallocating slices for MIG configuration is not possible. If there is an attempt to overallocate, then the slices that are allocated too late are simply not allocated. This can lead to unexpected results for the unwary cluster administrator. For example:
-
5*1g.5gb,2g.10gballocates the 5 slices of the 1g instance and the 2 slices of the 2g instance.But
-
6*1g.5gb,2g.10gballocates the 6 slices of the 1g instance and none of the 2g instance. -
7*1g.5gb,2g.10gballocates the 7 slices of the 1g instance and none of the 2g instance. -
70*1g.5gb,2g.10gballocates 7 slices of the 1g instance and none of the 2g instance.
-
3.18 Configuring Sampling From A Prometheus Exporter
CMDaemon can be configured to sample a Prometheus exporter, for example from the NVIDIA Unified Fabric Manager (UFM) platform. A CMDaemon front end such as cmsh can have a data producer, for example UFM, configured within the monitoring setup mode (section 10.5.4) to allow sampling of the Prometheus exporter:
Example
In the example, the URL needs to be set to the Prometheus export server endpoint. The value of NoPostAllowed only needs to be set to yes for some older Prometheus versions that do not work with HTTP POST. The data producer is set to run on only the active head node with the nodeexecutionfilter setting (here).
The preceding example configures CMDaemon to sample from a Prometheus exporter. The other way around, that is to have CMDaemon be the exporter of Prometheus data, can be achieved via the EnablePrometheusExporterService directive (here).
3.19 Configuring Custom Scripts
Some scripts are used for custom purposes. These are used as replacements for certain default scripts, for example, in the case of non-standard hardware where the default script does not do what is expected. The custom scripts that can be set, along with their associated arguments are:
-
custompowerscriptandcustompowerscriptargument(section 4.1.4) -
custompingscriptandcustompingscriptargument(section 3.19.2) -
customremoteconsolescriptandcustomremoteconsolescriptargument(section 3.19.3)
In addition to the preceding custom* scripts, system information scripts can be set that provide extra information to the sysinfo command in BCM (section 3.19.4).
The environment variables of CMDaemon (section 3.3.1 of the Developer Manual) can be used in the scripts. Successful scripts, as is the norm, return 0 on exit.
3.19.1 custompowerscript
The use of custom power scripts is described in section 4.1.4.
3.19.2 custompingscript
The following example script:
Example
can be defined and set for the cases where the default built-in ping script, cannot be used.
By default, the node device states are detected by the built-in ping script (section 5.5) using ICMP ping. This results in the statuses that can be seen on running the list command of cmsh in device mode. An example output, formatted for convenience, is:
Example
If some device is added to the cluster that blocks such pings, then the built-in ping can be replaced by the custom ping of the example, which relies on standard ICMP ping.
However, the replacement custom ping script need not actually use a variety of ping at all. It could be a script running web commands to query a chassis controller, asking if all its devices are up. The script simply has to provide an exit status compatible with expected ping behavior. Thus an exit status of 0 means all the devices are indeed up.
3.19.3 customremoteconsolescript
A custom remote console script can be used to run in the built-in remote console utility. This might be used, for example, to allow the administrator remote console access through a proprietary KVM switch client.
For example, a user may want to run a KVM console access script that is on the head node and with an absolute path on the head node of /root/kvmaccesshack. The script is to run on the console, and intended to be used for node node001, and takes the argument 1. This can then be set in cmsh as follows:
Example
In Base View, the corresponding navigation paths to access these script settings are:
Devices > Nodes > Edit > Settings > Custom remote console script
and
Devices > Nodes > Edit > Settings > Custom remote console script argument
while the remote console can be launched via the navigation path:
Devices > Nodes > Edit > Connect > Remote console
3.19.4 sysinfo Custom Scripts
3.19.4.1 Standard sysinfo
The sysinfo command in BCM is run from device mode in cmsh for a node. By default, sysinfo returns some basic hardware information for the node, from the OS, from a cache. Direct hardware queries can be carried out with other commands (section 14.11).
3.19.4.2 Overview Of Running Custom Scripts In sysinfo
A cluster administrator may however wish to extract some additional hardware-related information from the cluster. To do this, custom scripts associated with the sysinfo command can be created by the cluster administrator. These sysinfo custom scripts run when the sysinfo command is executed via cmsh, and they pick up the additional information.
Custom script types: The scripts can be of three types, with corresponding directory locations. as indicated by the following table:
Custom script process: When sysinfo runs for a particular node, the scripts that are called have the following characteristics, and are run as follows:
-
Any scripts of the local type are run on the node that
sysinfois executed on. The scripts must be placed by the cluster administrator on the node itself. The node could be a head node, director node, a regular node, or a cloud node. The output from the local scripts is picked up. -
Any scripts of the director type are run on the director node. The scripts must be placed by the cluster administrator on the director node itself. The output from the scripts is picked up.
-
Any scripts of the head type are run on the head node. The scripts themselves must be placed by the cluster administrator on the head node. The output from the scripts is picked up.
Custom script output format: The script outputs are JSON format key value pairs (JSON object literals).
The simplest standard JSON output form supported for sysinfo is:
The format if getting output for N key-value pairs is:
Nested sysinfo output: The key-value pairs can also be grouped, with the output presented in the following format for a group:
The key-value pairs can also be structured with multiple groups. In the following example there are two groups:
Example
The nested multilayer output format can be useful for grouped values. For example, dmidecode can output key-value pairs that specify starting and ending ranges, which can be grouped according to the various DMI types that are also available in the output.
Simple sysinfo custom script construction: For example, the following bash script can be run on the head node:
Example
If run directly, outside of CMDaemon, then this would display a JSON key-value output similar to the following:
Example
Custom script placement—overview for placing on a regular node: Placing this head script on a regular node can be done by copying the script into a local directory on the node image, and rebooting the regular node so that it picks up the image with the new local type script. After CMDaemon is updated with the new sysinfo information, then, whenever sysinfo is run, the script is automatically run by CMDaemon.
3.19.4.3 Examples Of Running Custom Scripts In sysinfo
The following example session makes the preceding concepts more explicit: the script is copied over from the head node to the default image of a regular node. It goes into the directory location for custom sysinfo scripts of the local type. Rebooting a node then installs the new script on the node:
Example
To update cmdaemon with the values from the new scripts for the node, the --update option to the sysinfo command can be run for the node. Running sysinfo for the node then displays the output of the scripts for the node. The sysinfo output value for Age shows how long it has been since CMDaemon was updated by the scripts for the node:
Example
In the preceding example, the grouping braces are not part of the actual output. They are just part of this explanation, and show that the first four lines after the Age line are from the local type script running on node001. The four lines after that are from the head type script running on head, even though its corresponding CMDaemon is running on node001.
3.19.4.4 Considerations Before Running Custom Scripts With sysinfo
Although BCM gives the administrator the freedom to construct all kinds of custom sysinfo scripts, some caution is urged before implementing the scripts. The following issues should at least be considered:
-
The scripts should be speedy. The scripts run asynchronously, but a script is expected to take less than 15 seconds to run.
-
The data output should be small. JSON objects allow, for example, that megabyte-sized text could be output by the sysinfo scripts. However, this is often unwise, given the nature of clusters. A cluster with a 1000 nodes and 1MB blobs would mean that 1GB of memory is being moved around.
3.20 Cluster Configuration Without Execution By CMDaemon
3.20.1 Cluster Configuration: The Bigger Picture
The configurations carried out in this chapter so far are based almost entirely on configuring nodes, via a CMDaemon front end (cmsh or Base View), using CMDaemon to execute the change. Indeed, much of this manual is about this too because it is the preferred technique. It is preferred:
-
because it is intended by design to be the easiest way to do common cluster tasks,
-
and also generally keeps administration overhead minimal in the long run since it is CMDaemon rather than the system administrator that then takes care of tracking the cluster state.
There are however other cluster configuration techniques besides execution by CMDaemon. To get some perspective on these, it should be noted that cluster configuration techniques are always fundamentally about modifying a cluster so that it functions in a different way. The techniques can then for convenience be separated out into modification techniques that rely on CMDaemon execution and techniques that do not, as follows:
-
Configuring nodes with execution by CMDaemon: As explained, this is the preferred technique. The remaining techniques listed here should therefore usually only be considered if the task cannot be done with Base View or
cmsh. -
Replacing the node image: The image on a node can be replaced by an entirely different one, so that the node can function in another way. This is covered in section 3.20.2. It can be claimed that since it is CMDaemon that selects the image, this technique should perhaps be classed as under item 1. However, since the execution of the change is really carried out by the changed image without CMDaemon running on the image, and because changing the entire image to implement a change of functionality is rather extreme, this technique can be given a special mention outside of CMDaemon execution.
-
Using a
FrozenFiledirective: Applied to a configuration file, this directive prevents CMDaemon from executing changes on that file for nodes. During updates, the frozen configuration may therefore need to be changed manually. The prevention of CMDaemon acting on that file prevents the standard cluster functionality that would run based on a fully CMDaemon-controlled cluster configuration. TheFrozenFiledirective is introduced in section 2.6.5, and covered in the configuration context in section 3.20.3. -
Using an
initializeorfinalizescript: This type of script is run during the initrd stage, much before CMDaemon on the regular node starts up. It is run if the functionality provided by the script is needed before CMDaemon starts up, or if the functionality that is needed cannot be made available later on when CMDaemon is started on the regular nodes. CMDaemon does not execute the functionality of the script itself, but the script is accessed and set on the initrd via a CMDaemon front end (Appendix E.2), and executed during the initrd stage. It is often convenient to carry out minor changes to configuration files inside a specific image in this way, as shown by the example in Appendix E.5. Theinitializeandfinalizescripts are introduced in section 3.20.4. -
A shared directory: Nodes can be configured to access and execute a particular software stored on a shared directory of the cluster. CMDaemon does not execute the functionality of the software itself, but is able to mount and share directories, as covered in section 3.14.
Finally, outside the stricter scope of cluster configuration adjustment, but nonetheless a broader way to modify how a cluster functions, and therefore mentioned here for more completeness, is:
-
Software management: the installation, maintenance, and removal of software packages. Standard post-installation software management based on repositories is covered in sections 9.2–9.6. Third-party software management from outside the repositories, for software that is part of BCM is covered in Chapter 7 of the Installation Manual.
Third-party software that is not part of BCM can be managed on the head node as on any other Linux system, and is often placed under
/optor other recommended locations. If required by the other nodes, then the software should typically be set up by the administrator so that it can be accessed via a shared filesystem.
3.20.2 Making Nodes Function Differently By Image
3.20.2.1 Making All Nodes Function Differently By Image
To change the name of the image used for an entire cluster, for example after cloning the image and modifying it (section 3.20.2.2), the following methods can be used:
-
in Base View, via
Cluster>Settings>Default software image -
or in
cmshfrom within thebaseobject ofpartitionmode
A system administrator more commonly sets the software image on a per-category or per-node basis (section 3.20.2.2).
3.20.2.2 Making Some Nodes Function Differently By Image
For minor changes, adjustments can often be made to node settings via initialize and finalize scripts so that nodes or node categories function differently (section 3.20.4).
For major changes on a category of nodes, it is usually more appropriate to have nodes function differently from each other by simply carrying out image changes per node category with CMDaemon. Carrying out image changes per node is also possible. As usual, node settings override category settings.
Modifying images via cloning primitives for a node or category: Setting a changed image for a category can be done as follows with cmsh:
-
The image on which the new one will be based is cloned. The cloning operation not only copies all the settings of the original (apart from the name), but also the data of the image:
Example
-
After cloning, the settings can be modified in the new object. For example, if the kernel needs to be changed to suit nodes with different hardware, kernel modules settings are changed (section 5.3.2) and committed. This creates a new image with a new ramdisk.
Other ways of modifying and committing the image for the nodes are also possible, as discussed in sections 9.2–9.6.
-
The modified image that is to be used by the differently functioning nodes is placed in a new category in order to have the nodes be able to choose the image. To create a new category easily, it can simply be cloned. The image that the category uses is then set:
-
-
For just one node, or a few nodes, the node can be set from
devicemode to the new category (which has the new image): -
If there are many nodes, for example node100 sequentially up to node200, they can be set to that category using a
foreachloop like this:Example
-
-
Rebooting restarts the nodes that are assigned to the new category with the new image.
Modifying images by adding files in the cm/conf directory, for a category, node, or MAC address: The preceding 5-step method is understandable. For just a few file changes it is perhaps overkill and not very elegant. BCM has a more structured and efficient way to make some nodes function differently by image if only a few file additions are to be carried out. The specification adds the files in the image via a target path that is specified in special configuration locations in the image. It can be configured per node, but also per category and MAC address.
-
For a category, the specification takes the form:
/cm/images/<image>/cm/conf/category/<category>/ <target>Thus, if some file on the node is to be placed so that on a running node it is at
/path/to/some.file, and this needs to be configured for an imagedefault-image, and a categorydefault, then it would be placed at this location on the head node:Example
The file on the target node would be placed in the absolute directory
/path/to/some.fileMultiple categories can be configured per image. Thus, for example, beside the
defaultcategory, an additionalgpucategory can exist:Example
Also, multiple files can be specified per category per image. Thus, beside the file
some.file, an additional filesome.other.filecould be placed:Example
-
For a node, the configuration form is:
/cm/images/<image>/cm/conf/node/<node name>/ <target>An example for a node called
node001could then be:Example
-
For a MAC address, the configuration form is:
/cm/images/<image>/cm/conf/node/<MAC address>/ <target>An example for a node with MAC address
00:aa:bb:cc:dd:eecould then be:Example
The copying of the specified files to the image is done just before the finalize stage of the node-installer (section 5.4.11) during node provisioning.
A common theme in BCM is that node-level configuration overrides category-level configuration. In keeping with this behavior, a file configuration at category level could be applied to the many nodes in a category. And, a file configuration copy at node level (for a node that is in the category) overrides the category level value for just that particular node.
3.20.3 Making All Nodes Function Differently From Normal Cluster Behavior With FrozenFile
Configuration changes carried out by Base View or cmsh often generate, restore, or modify configuration files (Appendix A).
However, sometimes an administrator may need to make a direct change (without using Base View or cmsh) to a configuration file to set up a special configuration that cannot otherwise be done.
The FrozenFile directive to CMDaemon (Appendix C.69, here) applied to such a configuration file stops CMDaemon from altering the file. The frozen configuration file is generally applicable to all nodes and is therefore a possible way of making all nodes function differently from their standard behavior.
Freezing files is however best avoided, if possible, in favor of a CMDaemon-based method of configuring nodes, for the sake of administrative maintainability.
3.20.4 Adding Functionality To Nodes Via An initialize Or finalize Script
CMDaemon can normally be used to allocate different images per node or node category as explained in section 3.20.2.2. However, some configuration files do not survive a reboot (Appendix A), sometimes hardware issues can prevent a consistent end configuration, and sometimes drivers need to be initialized before provisioning of an image can happen. In such cases, an initialize or finalize script (sections 5.4.5, 5.4.11, and Appendix E.5) can be used to initialize or configure nodes or node categories.
These scripts are also useful because they can be used to implement minor changes across nodes:
Example
Supposing that some nodes with a particular network interface have a problem auto-negotiating their network speed, and default to 100Mbps instead of the maximum speed of 1000Mbps. Such nodes can be set to ignore auto-negotiation and be forced to use the 1000Mbps speed by using the ETHTOOL_OPTS configuration parameter in their network interface configuration file: /etc/sysconfig/network-scripts/ifcfg-eth0 (or /etc/sysconfig/network/ifcfg-eth0 in SUSE).
The ETHTOOL_OPTS parameter takes the options to the “ethtool -s <device>” command as options. The value of <device> (for example eth0) is specified by the filename that is used by the configuration file itself (for example /etc/sysconfig/network-scripts/ifcfg-eth0). The ethtool package is installed by default with BCM. Running the command:
turns out after some testing to be enough to reliably get the network card up and running at 1000Mbps on the problem hardware.
However, since the network configuration file is overwritten by node-installer settings during reboot, a way to bring persistence to the file setting is needed. One way to ensure persistence is to append the configuration setting to the file with a finalize script, so that it gets tagged onto the end of the configuration setting that the node-installer places for the file, just before the network interfaces are taken down again in preparation for init.
The script may thus look something like this for a Red Hat system:
The method of enforcing an interface space just outlined is actually just for educational illustration, and is not a recommended method.
In practice, the recommended way to enforce an interface speed is to simply set it in the CMDaemon database. For example, for the boot interface of node001 it could be via the Base View navigation path:
Devices > Nodes[node001] > Edit > Settings > Interfaces[BOOTIF] > Edit > Speed
3.20.5 Examples Of Configuring Nodes With Or Without CMDaemon
A node or node category can often have its software configured in CMDaemon via Base View or cmsh:
Example
Configuring a software for nodes using Base View or cmsh: If the software under consideration is CUPS, then a node or node category can manage it from Base View or cmsh as outlined in section 3.15.2.
A counterexample to this is:
Example
Configuring a software for nodes without using Base View or cmsh, using an image: Software images can be created with and without CUPS configured, without using Base View or cmsh except to link nodes to their appropriate image via the associated category. Setting up nodes to load one of these two images via a node category is an alternative way of letting nodes run CUPS.
Whether node configuration for a particular functionality is done with CMDaemon, or directly with the software, depends on what an administrator prefers. In the preceding two examples, the first example, that is the one with Base View or cmsh setting the CUPS service, is likely to be preferred over the second example, where an entire separate image must be maintained. A new category must also be created in the second case.
Generally, sometimes configuring the node via BCM, and not having to manage images is better, sometimes configuring the software and making various images to be managed out of it is better, and sometimes only one of these techniques is possible anyway.
3.20.5.1 Configuring Nodes Using Base View Or cmsh: Category Settings
When configuring nodes using Base View or cmsh, configuring particular nodes from a node category to overrule the state of the rest of its category (as explained in section 2.1.3) is sensible for a small number of nodes. For larger numbers it may not be organizationally practical to do this, and another category can instead be created to handle nodes with the changes conveniently.
The CUPS service in the next two examples is carried out by implementing the changes via Base View or cmsh acting on CMDaemon.
Example
Setting a few nodes in a category: If only a few nodes in a category are to run CUPS, then it can be done by enabling CUPs just for those few nodes, thereby overriding (section 2.1.3) the category settings.
Example
Setting many nodes to a category: If there are many nodes that are to be set to run CUPS, then a separate, new category can be created (cloning it from the existing one is easiest) and those many nodes are moved into that category, while the image is kept unchanged. The CUPS service setting is then set at category level to the appropriate value for the new category.
In contrast to these two examples, the software image method used in section 3.20.2.2 to implement a functionality such as CUPS would load up CUPS as configured in an image, and would not handle it via CMDaemon (except to link nodes to their appropriate image via the associated category). So, in section 3.20.2.2, software images prepared by the administrator are set for a node category. Since, by design, images are only selected for a category, a node cannot override the image used by the category other than by creating a new category, and using it with the new image. The administrative overhead of this can be inconvenient.
Administrators would therefore normally prefer letting CMDaemon track software functionality across nodes as in the last two examples, rather than having to deal with tracking software images manually. Indeed, the roles assignment option (section 2.1.5) is just a special pre-configured functionality toggle that allows CMDaemon to set categories or regular nodes to provide certain functions, typically by enabling services.
3.21 Saving A Backup Of Configuration Files With versionconfigfiles
If versionconfigfiles is set to the value yes for a node or a category, then if configuration files changed for that node or category due to CMDaemon, then the old configuration files are saved.
Example
This is useful, for example, if an administrator would like to know what the configuration was just before it was changed.
If a configuration change takes place, then the old configuration files are automatically sent from the node where they changed, to the active head node. The configuration files:
-
are saved on the active head node under the directory
/var/spool/cmd/config_file_versions, under their node name. -
have a modification time that indicates the time of the change.
-
are given a suffix in the form of the local unix epoch time.
Example