

Conv2d#
Overview#
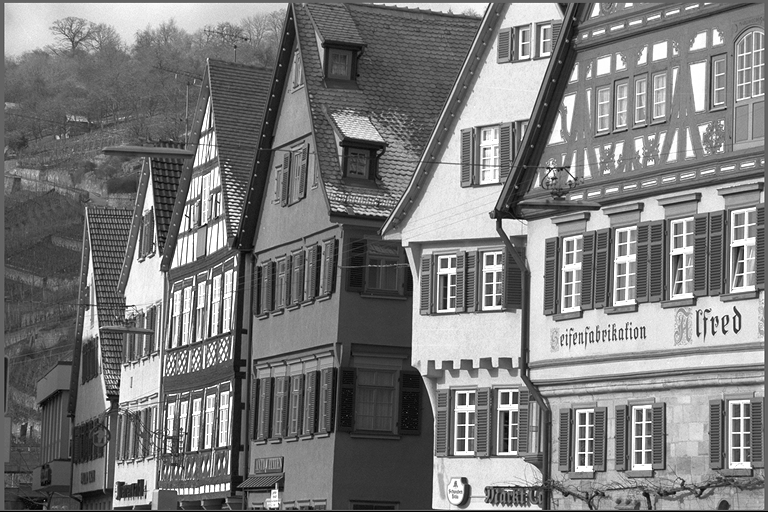
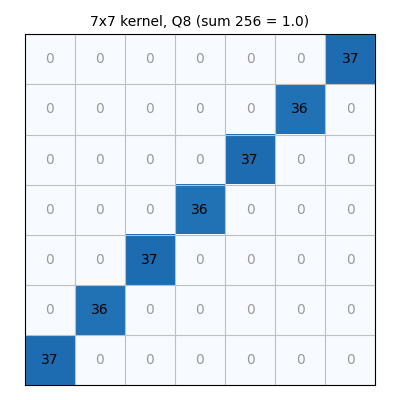
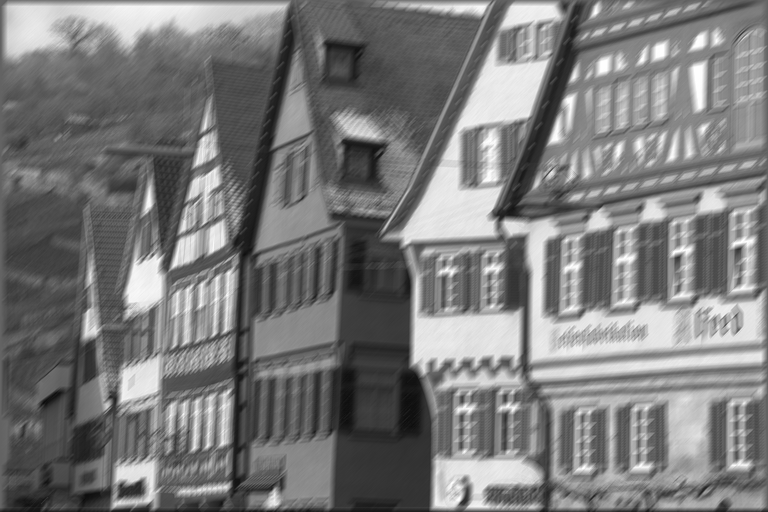
The Conv2d operator performs general 2D convolution operations with a user-defined filter kernel. It applies a custom kernel to an input image, so it can use kernel shapes that the dedicated filters do not offer, such as directional (motion) blur or other custom smoothing kernels. Kernel coefficients are unsigned fixed point (\(0 \le w < 1\), Q8 for 8-bit data and Q16 for 16-bit data): kernels that need negative weights, such as edge detection or sharpening, are not supported. The current implementation supports 3x3, 5x5, and 7x7 kernels.
Input Image |
Kernel |
Output Image |
|---|---|---|
|
|
|
Conv2d Parameters: 7×7 motion-blur kernel (seven equal Q8 weights on the anti-diagonal), replicate border.
Algorithm Description#
Conv2d is implemented as a convolution operation on the input image where the kernel has user-defined weights:
where \(n\) is the width and height of the kernel (3, 5, or 7), and \(kernel[i, j]\) represents the user-defined kernel coefficients.
Implementation Details#
Kernel Reformatting#
The Conv2d operator internally reformats the kernel coefficients into a format optimized for the hardware convolution instructions. This reformatting is automatically performed by the operator and is transparent to the user.
The reformatting process involves:
Aligning kernel width to a multiple of 4 (padding with zeros)
Creating two kernel variants with different row padding
Interleaving the kernel data for optimal memory access patterns
For uint8/int8 data types, the kernel is reformatted into structures suitable for the vfilt4x2x2 instruction.
For uint16/int16 data types, the kernel is reformatted into structures suitable for the vfilt4x2 instruction.
Refer to Conv2d primitive documentation for detailed information on how the reformatted kernel is used in the convolution computation.
Dataflow Configuration#
Refer to GaussianFilter operator documentation for more details. Conv2d operator uses the same dataflow configuration as GaussianFilter operator.
Buffer Allocation#
Refer to GaussianFilter operator documentation for more details. Conv2d operator uses the same buffer allocation as GaussianFilter operator.
Kernel Implementation#
Conv2d operator uses Conv2d primitive to perform convolution operations. Please refer to Conv2d primitive documentation for more details on the implementation, including:
Hardware instruction usage (vfilt4x2x2 for uint8/int8, vfilt4x2 for uint16/int16)
Detailed explanation of the convolution computation with reformatted kernels
Performance#
Execution Time is the average time required to execute the operator on a single VPU core.
Note that each PVA contains two VPU cores, which can operate in parallel to process two streams simultaneously, or reduce execution time by approximately half by splitting the workload between the two cores.
Total Power represents the average total power consumed by the module when the operator is executed concurrently on both VPU cores.
Idle power is approximately 7.6 W on Jetson AGX Orin and 11.8 W on Jetson AGX Thor when the PVA is not processing data.
For detailed information on interpreting the performance table below and understanding the benchmarking setup, see Performance Benchmark.
Image Size |
Data Type |
Kernel Size |
Execution Time |
Submit Latency |
Total Power |
|---|---|---|---|---|---|
1920x1080 |
U8 |
3x3 |
0.159ms |
0.004ms |
16.93W |
1920x1080 |
U8 |
5x5 |
0.164ms |
0.004ms |
17.526W |
1920x1080 |
U8 |
7x7 |
0.266ms |
0.004ms |
15.72W |
1920x1080 |
S8 |
3x3 |
0.159ms |
0.004ms |
17.228W |
1920x1080 |
S8 |
5x5 |
0.164ms |
0.004ms |
18.324W |
1920x1080 |
S8 |
7x7 |
0.266ms |
0.004ms |
16.518W |
1920x1080 |
U16 |
3x3 |
0.288ms |
0.004ms |
17.526W |
1920x1080 |
U16 |
5x5 |
0.386ms |
0.004ms |
17.321W |
1920x1080 |
U16 |
7x7 |
0.479ms |
0.006ms |
16.812W |
1920x1080 |
S16 |
3x3 |
0.288ms |
0.004ms |
17.925W |
1920x1080 |
S16 |
5x5 |
0.386ms |
0.004ms |
18.119W |
1920x1080 |
S16 |
7x7 |
0.479ms |
0.005ms |
17.211W |
Image Size |
Data Type |
Kernel Size |
Execution Time |
Submit Latency |
Total Power |
|---|---|---|---|---|---|
1920x1080 |
U8 |
3x3 |
0.124ms |
0.003ms |
20.454W |
1920x1080 |
U8 |
5x5 |
0.178ms |
0.002ms |
18.458W |
1920x1080 |
U8 |
7x7 |
0.297ms |
0.002ms |
16.453W |
1920x1080 |
S8 |
3x3 |
0.124ms |
0.002ms |
22.78W |
1920x1080 |
S8 |
5x5 |
0.177ms |
0.002ms |
18.853W |
1920x1080 |
S8 |
7x7 |
0.297ms |
0.002ms |
16.949W |
1920x1080 |
U16 |
3x3 |
0.217ms |
0.002ms |
20.938W |
1920x1080 |
U16 |
5x5 |
0.432ms |
0.002ms |
17.444W |
1920x1080 |
U16 |
7x7 |
0.537ms |
0.003ms |
16.645W |
1920x1080 |
S16 |
3x3 |
0.216ms |
0.003ms |
20.938W |
1920x1080 |
S16 |
5x5 |
0.432ms |
0.003ms |
17.444W |
1920x1080 |
S16 |
7x7 |
0.538ms |
0.003ms |
16.645W |
Compatibility#
Requires PVA SDK 2.6.0 and later.