

LidarHistogramConversion#
Overview#
The LidarHistogramConversion operator turns per-pixel LiDAR histogram data into optional range, Cartesian XYZ, and reflectance outputs. Each spatial location may carry one or more histograms; each histogram is a sequence of time-bin counts with optional opaque sensor headers.
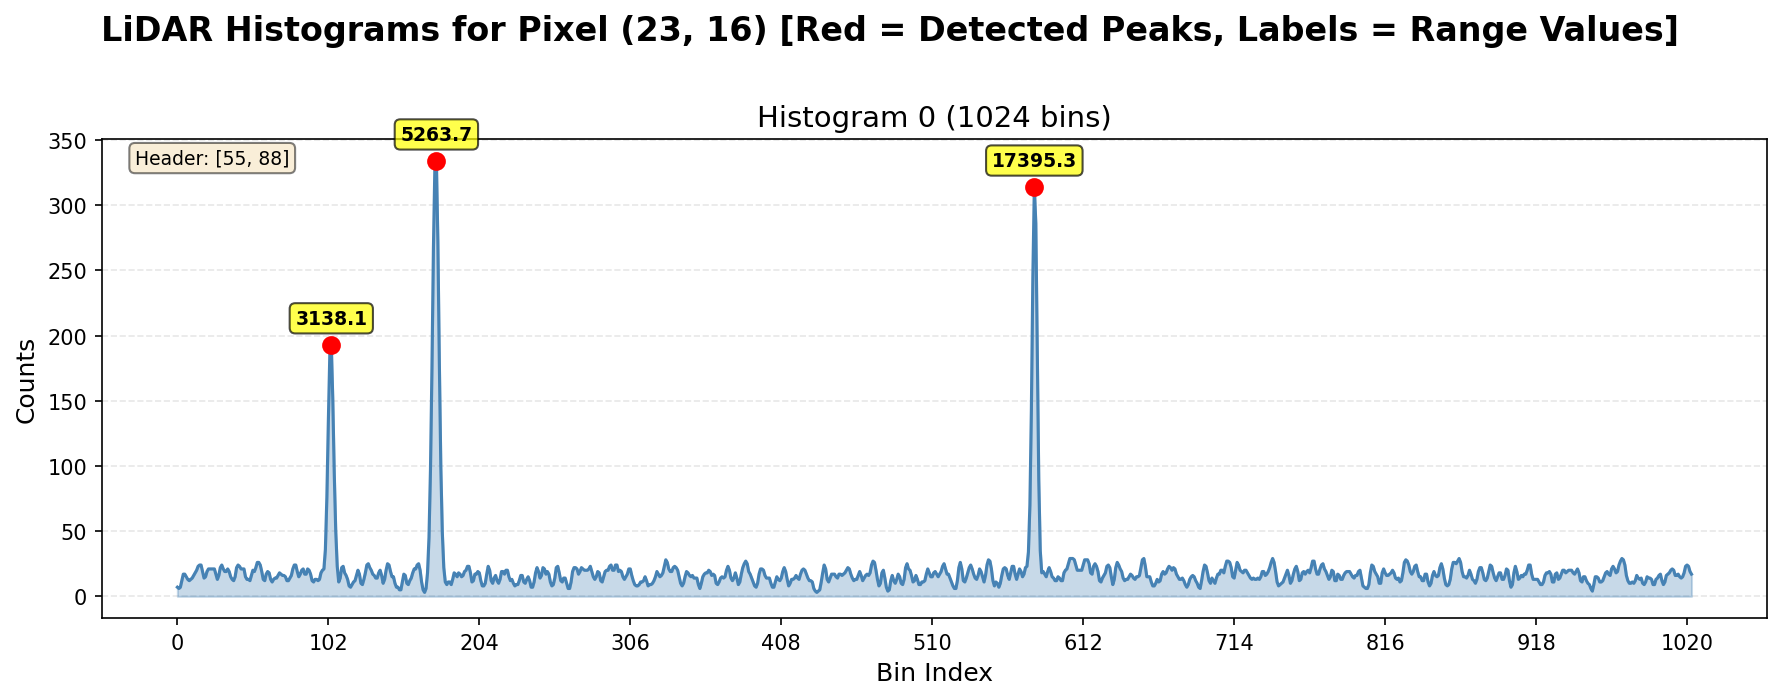
Figure 1: Example of a LiDAR histogram with detected peaks#
Processing follows unpack, per-histogram smoothing, peak detection, sub-bin time-of-flight refinement, and optional calibration steps to produce the requested outputs.
Algorithm Description#
Pixel layout#
A pixel is the full C-channel payload at one (H, W) index. Its logical layout is:
[pixelHeader] histogram_0 ... histogram_{N-1}
where N = numHistPerPixel. Each histogram has:
[histHeader] bin_0 ... bin_{K-1}
where K = numBinsPerHist. Pixel and histogram headers are treated as opaque sensor metadata at the API boundary; the
stages below use the bin counts only.
Two packing modes are supported:
NONE: histogram and header samples are logically 16-bit elements in the input tensor.
RAW12: pairs of 12-bit samples are packed as 24 bits (3 bytes) per pair. When this mode is used,
pixelHeaderSize,histHeaderSize, andnumBinsPerHistmust be even.
Unpacking (conceptual)#
Packed input is decoded into per-histogram bin arrays. Before smoothing, each histogram is extended at both ends with symmetric (reflective) padding so a fixed-width smoothing filter has well-defined boundary conditions.
Smoothing#
Each histogram is smoothed into a separate buffer with a fixed 7-tap Gaussian kernel (sigma = 1.0), applied in
integer arithmetic as [5, 55, 248, 408, 248, 55, 5] / 1024.
Peak detection#
Before scanning for peaks, a noise floor threshold is derived from the smoothed histogram to gate candidate evaluation. The threshold is:
where \(H_{\min}\) and \(H_{\max}\) are the minimum and maximum values of the smoothed histogram. The \(\tfrac{1}{8}\) margin is chosen as a conservative SNR gate: it sits comfortably above the noise floor (which clusters near \(H_{\min}\)) while remaining well below any genuine return, and is hard-coded into the algorithm. A bin must satisfy \(v > \theta\) before it is considered as a peak candidate.
Peaks are found with 3-bin non-maximum suppression on the smoothed histogram: a bin is a candidate maximum
if its value is strictly greater than both neighbors (a neighbor outside the histogram counts as 0). Plateaus (flat tops) are treated as a single peak whose
index is the mean of the plateau span, rounded down. The operator keeps the top numPeaksPerHist peaks by descending
value; ties favor the smaller bin index.
Range (time-of-flight to distance)#
For each accepted peak at integer bin index \(k\), sub-bin refinement uses parabolic interpolation on the three samples \(y_{k-1}, y_k, y_{k+1}\) (end samples are replicated when \(k\) is at the boundary):
with \(\delta\) clamped to \([-\tfrac{1}{2}, \tfrac{1}{2}]\) when the denominator is numerically well conditioned. The sub-bin index is \(\tilde{k} = k + \delta\) (clamped below at 0). Time-of-flight in nanoseconds is:
Let \(c\) denote the speed of light in meters per nanosecond. Range for peak \(p\) is:
where rangeBias is a per-pixel calibration value. If no peak is present in a slot (index -1), the corresponding
range is 0.
XYZ coordinates#
When XYZ output is requested, each peak range is multiplied by three per-pixel calibration coefficients \((c_x, c_y, c_z)\):
The host API requires xyzCalibration whenever XYZ is produced, and range bias must be provided if XYZ calibration
is used (XYZ is derived from calibrated range).
Reflectance#
Reflectance estimates signal strength as the sum of the three bins centered on each peak in the smoothed histogram (partial windows at the edges use only in-range bins). The output is:
when maxIntensity > 0, else 0. Values are not clamped to [0, 1]: intensities above maxIntensity yield
reflectance greater than 1. Missing peaks produce 0.
Implementation Details#
Histogram specification and runtime parameters#
PvaLidarHistogramSpec describes how to interpret the input C dimension: packingType, numHistPerPixel (1–8),
numBinsPerHist (3–2048), numPeaksPerHist (1–8), pixelHeaderSize (0–64), and histHeaderSize (0–16).
PvaLidarHistogramParams supplies offsetNs, binSizeNs, rangeScale, and maxIntensity. Full tensor
layout, dtype, and optionality rules for submit are documented in OpLidarHistogramConversion.h.
Dataflow configuration#
TensorDataFlow (TDF) brings histogram tiles from DRAM into a double-buffered VMEM input region sized for the worst-case pixel/histogram layout (utilizing one whole superbank). To support a wide variety of input tensor shapes, the DMA maps one full pixel (histogram tensor C dim) as the TDF width, tensor width as the TDF height, and tensor height as the TDF depth. Tile size is selected to pull in as many pixels in the tensor width dimension as possible, and for simplicity keeps a fixed tile “depth” of 1. More efficient use of VMEM may be possible if the input tensor shape is known apriori by pulling an exact multiple of pixels in the tensor width dimension and modifying the code to support a tile “depth” > 1.
SequenceDataFlow (SQDF) optionally streams per-pixel range bias and XYZ calibration from DRAM into VMEM before range/XYZ stages.
A single SQDF output path multiplexes optional range, XYZ, and reflectance DMAs. The three outputs occupy independent VMEM buffers – reflectance is staged in the histogram-header region, which is dead once unpacking has finished – so they carry no inter-output ordering constraint and are transferred in sequence on the shared handle.
Tile traversal follows the TensorDataFlow order depth → width → height, which corresponds to the histogram tensor’s H,
C, and W dimensions respectively. The resulting pattern is a “strip-mining” type of traversal, where the first
tile contains the first numHistPixPerTile pixels from row 0, the next tile contains numHistPixPerTile pixels from
row 1, etc., then the next numHistPixPerTile column of tiles is visited from row 0, etc.
VMEM buffer allocation (conceptual)#
The main kernel uses dedicated VMEM regions for: double-buffered packed histogram input; unpacked pixel and histogram headers; padded uint16 histogram working storage (including halo, pitch-aligned to vector width, and a space for one pixel of RAW12 decode scratch); the smoothed bins of the current histogram; the peak detector’s plateau-end candidate list; peak staging (index, value and the two neighboring bins); the emit pass’s integer gather scratch; float range staging; float XYZ staging; reflectance staging, aliased onto the now-dead histogram-header region; and optional per-tile range bias and XYZ calibration inputs.
Kernel workflow#
For each histogram tile:
Unpack pixel headers, histogram headers, and bins (NONE or RAW12 path); release the input tile early when done.
Optionally, start the DMA of range-bias and XYZ calibration tiles.
For every histogram: smooth, then detect peaks.
If any output is enabled: sync the calibration DMA when range bias was requested, then run one fused pass per pixel that gathers the peak scratch and computes range, XYZ and reflectance as enabled.
DMA the enabled outputs in sequence on the shared output handle: range, then XYZ, then reflectance.
Unpacking#
The VPU kernel separates pixel headers, histogram headers, and bin arrays into distinct VMEM regions. That
split keeps header metadata out of the convolution path and matches alignment needs for vector loads (including RAW12).
The header regions are write-only for the current pipeline: the histogram-header region is reused as the reflectance
output staging buffer once unpacking completes. Histogram bins are stored in a vector-width-aligned working
buffer:
each histogram includes a fixed halo of 3 bins, then numBinsPerHist samples, then 3 trailing bins for halo,
then the next histogram starts aligned to the next vector width.
NONE packing: headers and bins are simply copied with double-vector bulk moves from the acquired tile to the respective buffers.
RAW12 packing: the kernel requires 4-byte alignment of the tile base pointer and expects the per-pixel byte stride to be a multiple of 3 bytes (every pixel contains an integral number of RAW12 pairs). Decoding uses WX-style 24-bit vector loads to pick up a pair of 12-bit samples per lane directly from VMEM into a vshortx vector register. Each RAW12 pixel pair (A,B) is packed as A[4:11]B[4:11]B[0:3]A[0:3] from least to most significant bits. The vector code performs bitwise operations to extract the 12-bit samples, zero-extend to 16-bits, and store to the appropriate header and bin buffers while being careful to put the samples in the correct order. The offset into the input buffer is adjusted to maintain both the 4 and 3-byte alignment requirements when loading vectors of RAW12 samples.
Reflective halo fill: after bins are extracted to the histogram buffer, the three leading and three trailing halo bins are reflected using permutation patterns to initialize the boundary conditions for the smoothing kernel.
Smoothing#
Smoothing reads the uint16 bins and writes a separate output buffer. The 7 taps are applied with an agen-driven
sliding window: seven consecutive short vectors are multiplied by fixed coefficients, summed in the accumulator,
truncated by 10 bits (a floor divide by 1024) by the store AGEN, and narrowed back to uint16 for each output
vector. Writing out of place keeps each iteration’s loads independent of the previous
iteration’s stores, so the loop pipelines. Vector width and the precomputed pitch ensure the reflection-based halo
scheme remains valid (the kernel asserts the vector width exceeds the kernel radius).
The smoothing pass also collects the minimum and maximum of the smoothed bins at no additional cost by enabling the
VPU AGEN’s built-in min/max tracking feature (minmax_opt = 3 for unsigned tracking). When this mode is active,
the hardware updates running min and max accumulators in the store pipeline on every vector write; the values are readable
from the AGEN register after the loop completes. Because the smoothing result is written through this same output AGEN,
\(H_{\min}\) and \(H_{\max}\) are ready for the noise floor threshold calculation immediately after smoothing
returns, with no extra pass over the histogram data. The final store in the smoothing loop uses a per-lane predicated
store to restrict tracking to the valid bins only, avoiding contamination of \(H_{\min}\) from the padding lanes
written in the last partial vector when numBinsPerHist is not a multiple of the vector width.
Peak detection#
The noise floor threshold \(\theta\) is computed from \(H_{\min}\) and \(H_{\max}\) returned by the smoothing pass (see above) and folded into the per-bin candidate test below, so no separate gate is needed.
Peak detection runs in two passes. A branch-free dense pass tests every bin \(e\) with
\(S[e] > \max(S[e+1], S[e-1] - 1, \theta)\), 32 bins at a time on dvshortx vectors, so only the last bin of each
plateau passes; vcollate_idx_bits compacts the passing indices into a candidate list. A sparse pass then walks
each candidate back to the start of its plateau, keeps it only if the bin before the plateau is lower, and places the
peak at the plateau midpoint. The top N peaks are kept in registers with an insertion shuffle by descending value,
together with each peak’s two neighboring bins for the emit stage.
Because a neighbor outside the histogram counts as 0, the implementation writes a zero bin on both sides of the valid bins, and the last partial vector is peeled out of the dense loop and masked there.
Range, XYZ, and reflectance#
Sub-bin interpolation, bias, scaling, XYZ scaling, and the three-bin intensity sum for reflectance run as one fused pass per pixel: an integer gather of the peak scratch, then range, XYZ and reflectance evaluated in the vector unit. When the reflectance output is enabled it is staged in the histogram-header VMEM region, which is dead once unpacking has finished; range, XYZ and reflectance therefore occupy independent buffers and impose no ordering constraint on their DMAs.
Performance#
Execution Time is the average time required to execute the operator on a single VPU core.
Note that each PVA contains two VPU cores, which can operate in parallel to process two streams simultaneously, or reduce execution time by approximately half by splitting the workload between the two cores.
Total Power represents the average total power consumed by the module when the operator is executed concurrently on both VPU cores.
Idle power is approximately 7.6 W on Jetson AGX Orin and 11.8 W on Jetson AGX Thor when the PVA is not processing data.
For detailed information on interpreting the performance table below and understanding the benchmarking setup, see Performance Benchmark.
Packing |
Image Size |
Bins per Histogram |
Histograms per Pixel |
Peaks per Histogram |
Execution Time |
Submit Latency |
Total Power |
|---|---|---|---|---|---|---|---|
NONE |
192x56 |
2024 |
1 |
8 |
31.024ms |
0.009ms |
9.907W |
NONE |
192x128 |
32 |
3 |
3 |
39.627ms |
0.012ms |
9.499W |
RAW12 |
192x56 |
2024 |
1 |
8 |
35.702ms |
0.009ms |
9.807W |
RAW12 |
192x128 |
32 |
3 |
3 |
43.269ms |
0.012ms |
9.499W |
Packing |
Image Size |
Bins per Histogram |
Histograms per Pixel |
Peaks per Histogram |
Execution Time |
Submit Latency |
Total Power |
|---|---|---|---|---|---|---|---|
NONE |
192x56 |
2024 |
1 |
8 |
33.602ms |
0.005ms |
13.541W |
NONE |
192x128 |
32 |
3 |
3 |
44.236ms |
0.005ms |
12.742W |
RAW12 |
192x56 |
2024 |
1 |
8 |
40.226ms |
0.005ms |
13.339W |
RAW12 |
192x128 |
32 |
3 |
3 |
48.306ms |
0.005ms |
13.137W |