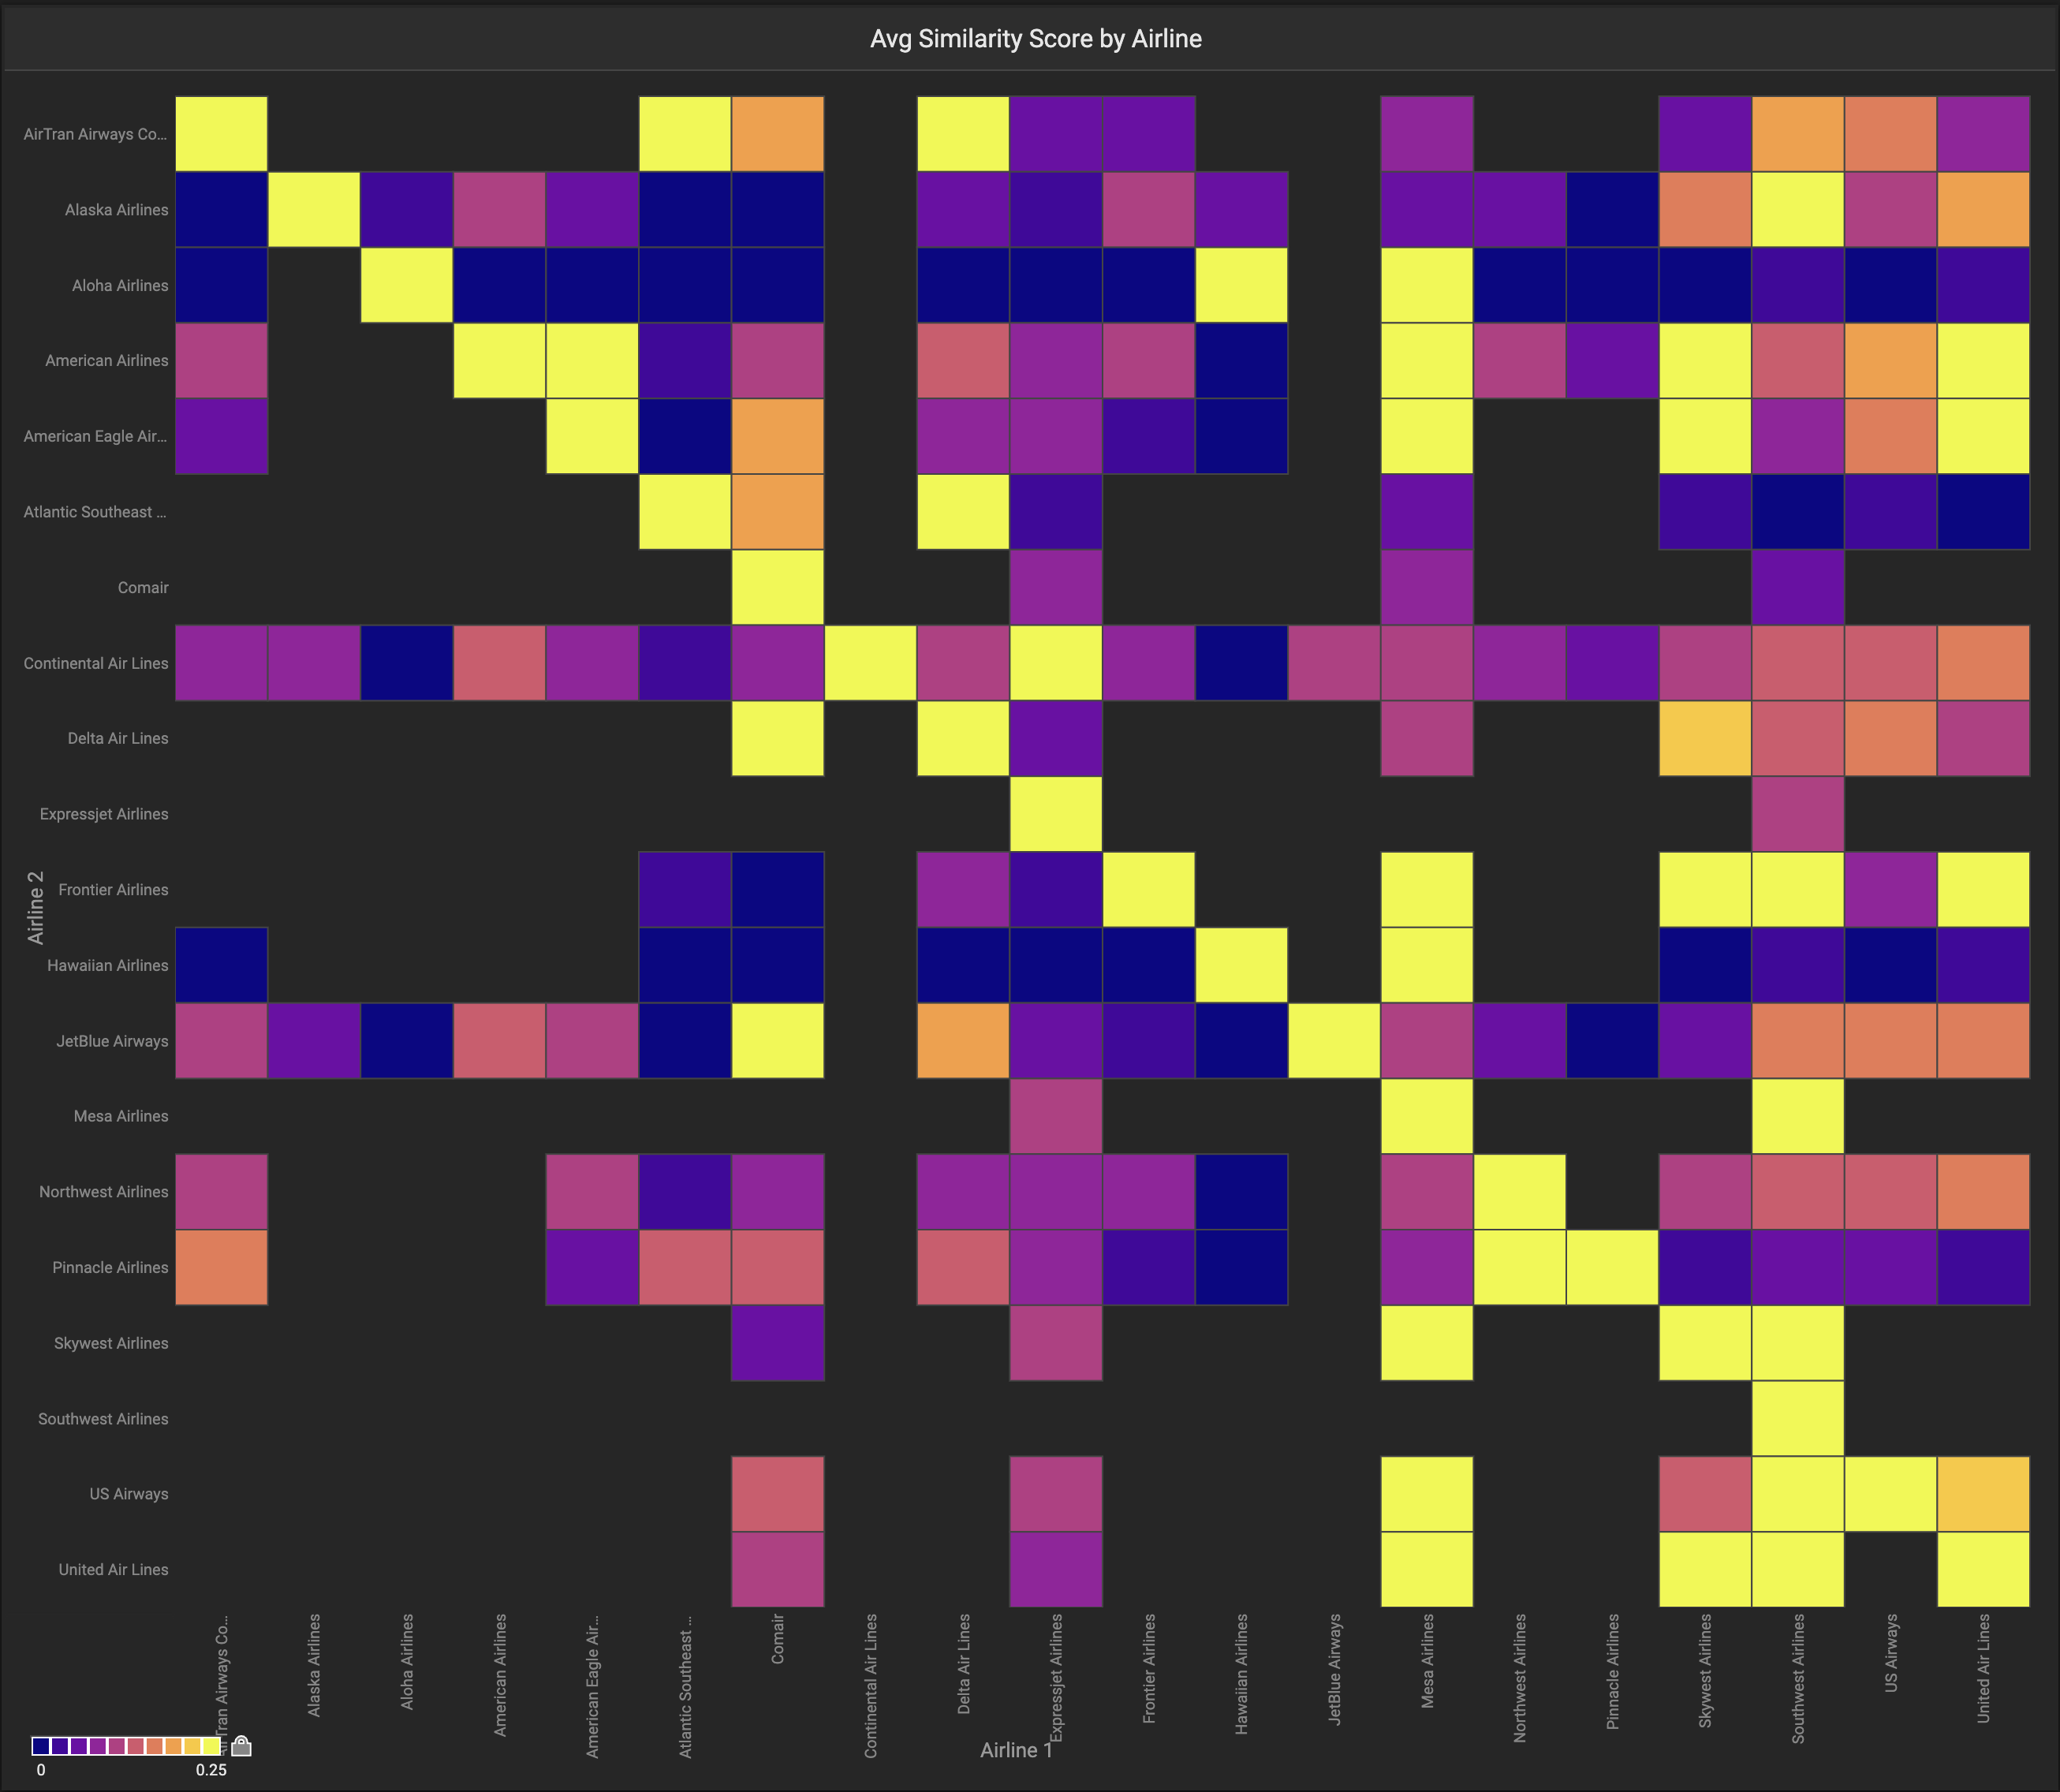
tf_feature_self_similarity
tf_feature_self_similarity
Given a query input of entity keys/IDs (for example, airplane tail numbers), a set of feature columns (for example, airports visited), and a metric column (for example number of times each airport was visited), scores each pair of entities based on their similarity. The score is computed as the cosine similarity of the feature column(s) between each entity pair, which can optionally be TF/IDF weighted.
select * from table(tf_feature_self_similarity(primary_features => cursor(selectprimary_key,pivot_features,metricfromtablegroup byprimary_key,pivot_features),use_tf_idf => <boolean>))
Input Arguments
| Parameter | Description | Data Type |
|---|---|---|
primary_key | Column containing keys/entity IDs that can be used to uniquely identify the entities for which the function computes co-similarity. Examples include countries, census block groups, user IDs of website visitors, and aircraft callsigns. | Column<TEXT ENCODING DICT | INT | BIGINT> |
pivot_features | One or more columns constituting a compound feature. For example, two columns of visit hour and census block group would compare entities specified by primary_key based on whether they visited the same census block group in the same hour. If a single census block group feature column is used, the primary_key entities would be compared only by the census block groups visited, regardless of time overlap. | Column<TEXT ENCODING DICT | INT | BIGINT> |
metric | Column denoting the values used as input for the cosine similarity metric computation. In many cases, this is COUNT(*) such that feature overlaps are weighted by the number of co-occurrences. | Column<INT | BIGINT | FLOAT | DOUBLE> |
use_tf_idf | Boolean constant denoting whether TF-IDF weighting should be used in the cosine similarity score computation. | BOOLEAN |
Output Columns
| Name | Description | Data Types |
|---|---|---|
class1 | ID of the first primary key in the pair-wise comparison. | Column<TEXT ENCODING DICT | INT | BIGINT> (type is the same of primary_key input column) |
class2 | ID of the second primary key in the pair-wise comparison. Because the computed similarity score for a pair of primary keys is order-invariant, results are output only for ordering such that class1 <= class2. For primary keys of type TextEncodingDict, the order is based on the internal integer IDs for each string value and not lexicographic ordering. | Column<TEXT ENCODING DICT | INT | BIGINT> (type is the same of primary_key input column) |
similarity_score | Computed cosine similarity score between each primary_key pair, with values falling between 0 (completely dissimilar) and 1 (completely similar). | Column<Float> |
Example
/* Compute similarity of airlines by the airports they fly from */select*fromtable(tf_feature_self_similarity(primary_features => cursor(selectcarrier_name,origin,count(*) as num_flightsfromflights_2008group bycarrier_name,origin),use_tf_idf => false))wheresimilarity_score <= 0.99order bysimilarity_score desclimit20;class1|class2|similarity_scoreExpressjet Airlines|Continental Air Lines|0.9564615Delta Air Lines|Atlantic Southeast Airlines|0.9436753Delta Air Lines|AirTran Airways Corporation|0.9379856Atlantic Southeast Airlines|AirTran Airways Corporation|0.9326661American Eagle Airlines|American Airlines|0.8906327Northwest Airlines|Pinnacle Airlines|0.8222722Skywest Airlines|United Air Lines|0.6857293Mesa Airlines|US Airways|0.6116939United Air Lines|Frontier Airlines|0.5921053Mesa Airlines|United Air Lines|0.5686765United Air Lines|American Eagle Airlines|0.5272493Skywest Airlines|Frontier Airlines|0.4684323Southwest Airlines|US Airways|0.4166781United Air Lines|American Airlines|0.397027Comair|JetBlue Airways|0.3631534Mesa Airlines|American Eagle Airlines|0.3379275Skywest Airlines|American Eagle Airlines|0.3331468Mesa Airlines|Skywest Airlines|0.3235496Comair|Delta Air Lines|0.3075919Southwest Airlines|Mesa Airlines|0.2901711/* Compute the similarity of US States by the TF-IDFweighted cosine similarity of the words tweeted in each state */select*fromtable(tf_feature_self_similarity(primary_features => cursor(selectstate_abbr,unnest(tweet_tokens),count(*)fromtweets_2022_06where country = 'US'group bystate_abbr,unnest(tweet_tokens)),use_tf_idf => TRUE))whereclass1 <> class2order bysimilarity_score desc;TX|GA|0.9928479IL|TN|0.9920474IL|NC|0.9920027TX|IL|0.9917723IN|OH|0.9916649TN|NC|0.9915619CA|TX|0.9910875IN|VA|0.9909871CA|IL|0.9909689IL|OH|0.9909481TX|NC|0.9908867IL|MO|0.9907863IN|MI|0.990751TN|OH|0.9907123IL|MD|0.9907106OH|NC|0.9905779VA|OH|0.990536IN|IL|0.9904549IN|MO|0.9903805TX|TN|0.9903381