

Tutorial
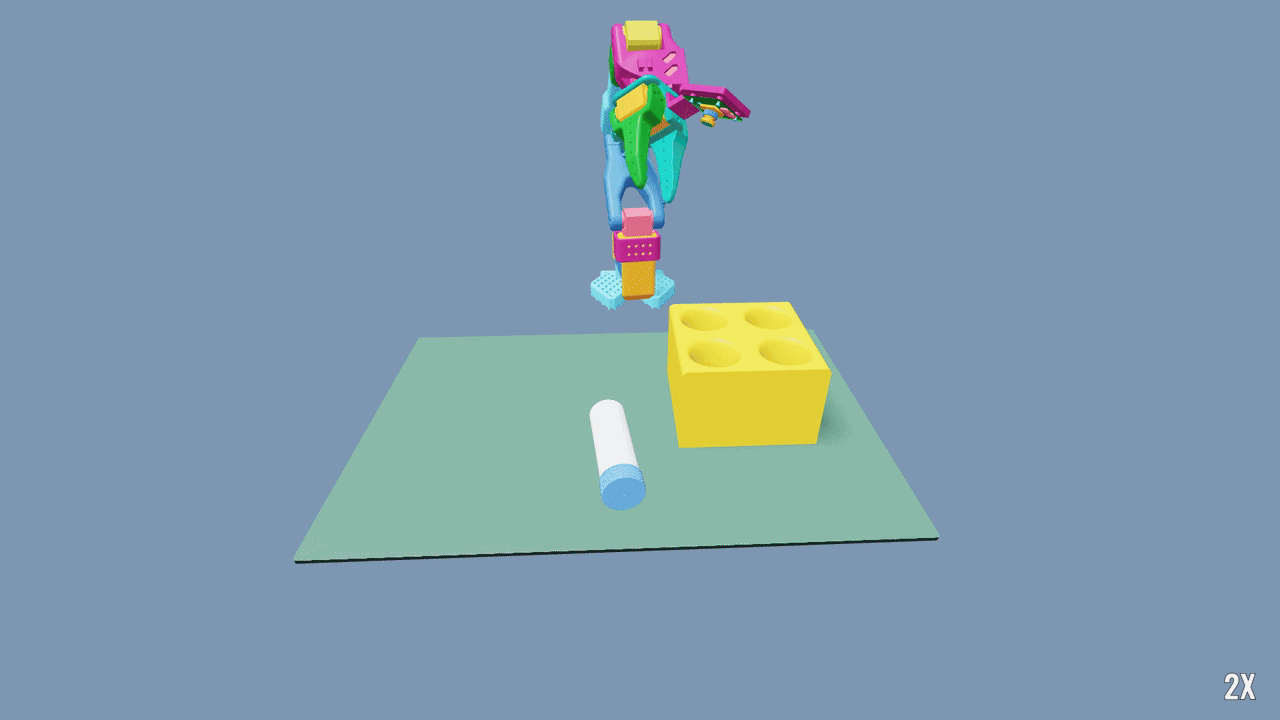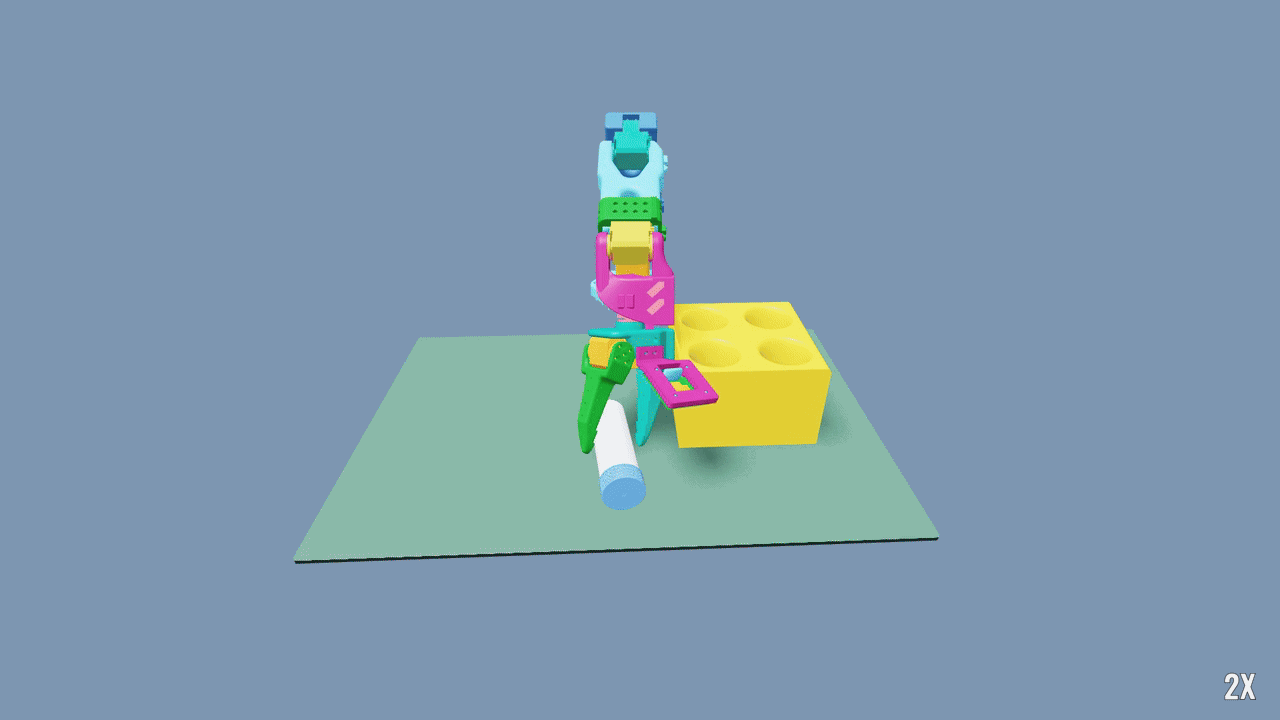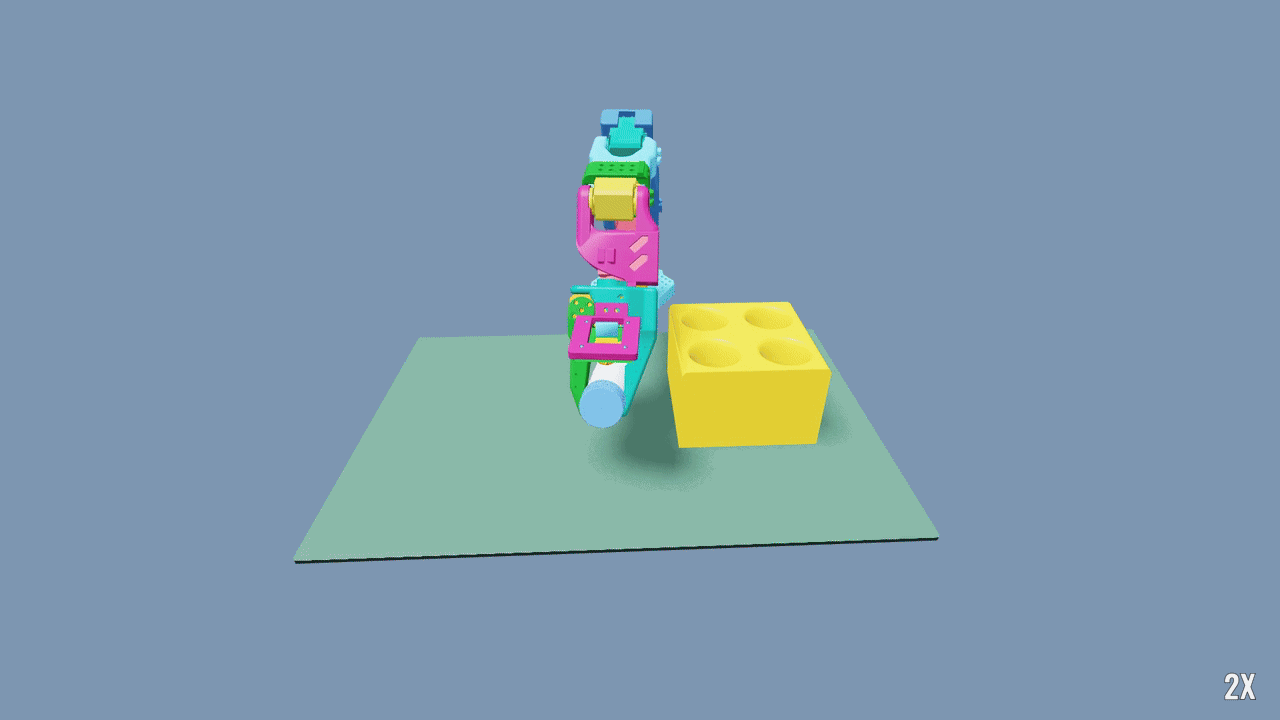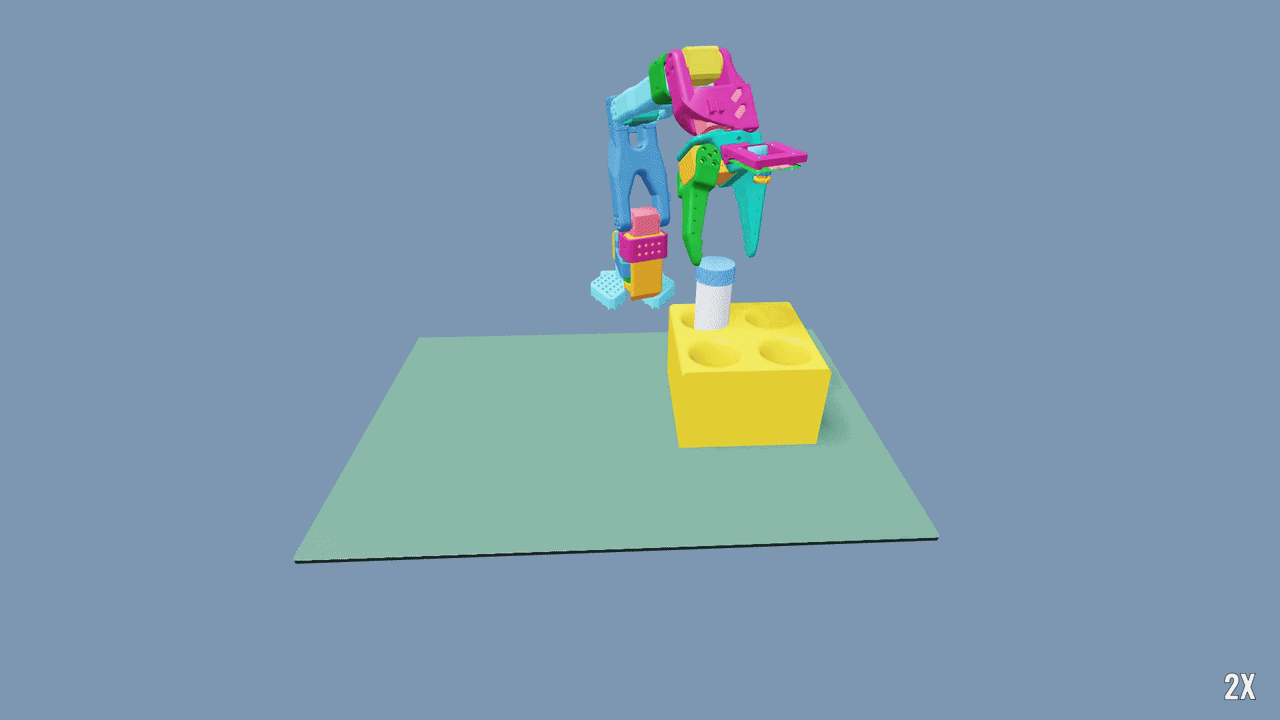
This tutorial ties in with the NVIDIA Sim-to-Real SO-101 learning course and its workshop repository, which present a broader end-to-end physical AI workflow with the SO-101, Isaac Lab, and NVIDIA Isaac GR00T.
This tutorial builds a complete robot-learning workflow around an SO-101 arm that picks up a vial and places it in a rack. Instead of assembling disconnected examples, you will work with a production-shaped downstream project: IsaacLabTutorial main branch. The project includes the robot and workshop assets, a manager-based reinforcement-learning environment, state and wrist-camera observations, RSL-RL agent configurations, tests, state-policy training, state-to-vision policy distillation, and an optional sim-to-real profile for running the camera policy on a physical SO-101.
By the end, you will know how a downstream Isaac Lab task is packaged, discovered, validated, trained, and evaluated. You will also know where to change the robot, scene, MDP, and learning configuration for your own task.
Navigate the tutorial
Contents
- 1. Set up — Install the project and verify task discovery.
- 2. Tour the project — Find the assets, task terms, configurations, and tests.
- 3. Understand the task — Connect the scene, actions, observations, resets, rewards, and physics.
- 4. Validate — Run tests, a zero-agent smoke test, and a benchmark.
- 5. Train and evaluate — Train a state teacher, distill a wrist-camera policy, and measure success.
- 6. Make it yours — Adapt the task without tangling reusable and robot-specific code.
1. Set up the project
You need Python 3.12, uv, Git with Git LFS, and an NVIDIA GPU on Linux or Windows. The tutorial uses Newton with the MJWarp solver, so it does not require the Isaac Sim application. Review the system requirements before starting.
Every command on this page is a single line, so it runs unchanged in bash, PowerShell, and Command Prompt.
Clone the tutorial’s main branch and create its environment:
The project pins Isaac Lab’s release/3.0.0 branch through pyproject.toml, so it does not require a sibling
Isaac Lab checkout. uv sync creates the environment and installs the tutorial, Isaac Lab, and their runtime
dependencies.
This repository is also a complete example of the downstream project produced by the Isaac Lab template generator . Use the generator when starting your own project, then follow the same package layout and task-discovery pattern shown here.
Confirm that the shared CLI discovers the downstream package:
The second command should include isaaclab_tutorial. Task discovery works because the project publishes an
isaaclab.tasks entry point:
pyproject.toml
Importing that package registers two Gymnasium task IDs:
Adding presets=sim2real to either task enables the randomization used for robot transfer (see
Train for the real robot).
Run all remaining commands from the IsaacLabTutorial directory. Train the state task first: it is the
baseline and supplies the teacher checkpoint used by the camera task.
2. Tour the project
The project keeps reusable task logic separate from SO-101-specific configuration:
This boundary is intentional. A new robot gets a sibling of config/so101 and reuses the vial-placement
MDP. A different manipulation problem gets a sibling of tasks/place_vial and owns its task terms.
The registration connects a task ID to the generic manager-based environment, the task configuration, and its default RSL-RL agent:
src/isaaclab_tutorial/tasks/place_vial/config/so101/init.py
This is why the normal isaaclab train, play, and benchmark commands work without project-local
launcher scripts.
3. Understand the task
The environment is assembled declaratively with ~isaaclab.envs.ManagerBasedRLEnvCfg. The main
configuration connects one scene configuration and one configuration for each MDP manager:
src/isaaclab_tutorial/tasks/place_vial/config/so101/env_cfg.py
The 120 Hz simulation and decimation of four give the policy a 30 Hz control rate. replicate_physics=True
allows the same scene to scale across thousands of environments. Values wrapped in preset(...) change only when
the named preset is selected on the command line.
Scene and control
SO101SceneCfg contains a fixed-base SO-101, a free 20 g vial, the four-hole rack, the desk, contact sensors on
both jaws and the vial, and lights. The robot configuration, identified actuator dynamics, and limits come from
Isaac Lab’s SO101_CFG.
The six-dimensional policy action uses Isaac Lab’s relative joint-position action: at every physics step, each joint target is the measured joint position plus the scaled action. The task never attaches the vial to the gripper and never writes its pose after reset. Grasping, transport, insertion, and release must therefore succeed through simulated contact.
MDP at a glance
The task reuses Isaac Lab’s core MDP terms and terms from the lift task (body_state_b, out_of_bound,
abnormal_robot_state), and adds only the terms specific to vial placement.
Physical progress and resets
Long-horizon manipulation is difficult to learn from the initial tabletop pose alone. The project therefore replays physics-validated reset poses across eight phases:
Training samples these phases as a reset curriculum. Each phase remains part of the same task: observations,
actions, rewards, and termination criteria do not change. Progress flags advance only when physical evidence is
present, for example bilateral jaw contact while the vial is held off the desk. Interactive play returns to
phase-zero starts so the final policy must complete the entire task. Read mdp/terminations.py for the physical
success predicate and reset/curriculum.py for the reset distribution.
State and camera policies
SO101VialEnvCfg is the fully observed baseline. SO101VialCameraEnvCfg in camera_env_cfg.py subclasses
it, adds the wrist camera, and replaces the actor observations. It also exposes the state actor’s observations as a
teacher_state group, which the state teacher reads during distillation; the deployed student consumes only wrist
RGB and proprioception.
4. Validate before training
Start with fast checks. They catch broken assets, registration, geometry, rewards, reset data, and configuration contracts before a long GPU run:
Next, construct and step a small vectorized environment with zero actions:
If this fails, fix task discovery, asset loading, or simulation stability before tuning RL. When it passes, measure the environment separately from the learning algorithm:
Reduce --num_envs if the batch does not fit your GPU. For the camera task, add the Newton renderer preset and
start with a smaller batch:
5. Train and evaluate
Train the state teacher with RSL-RL. The task’s default agent configuration is an 800-iteration run:
Checkpoints and TensorBoard events are written below logs/rsl_rl/so101_vial_state/<run>; the final checkpoint is
model_799.pt. While training runs, inspect the learning curves in another terminal:
Look for rising Metrics/success_rate, not reward alone. A larger return can come from shaping without a
corresponding increase in successful placements.
Play the state teacher
Play the trained teacher from the canonical home phase:
The rollout should start from the canonical home phase, pick up the horizontal vial, turn it upright, move it over
a hole, insert it, and open the jaw so gravity seats it in the rack. Playback already uses the policy’s
deterministic actions. Do not add --deterministic: it also enables Warp’s deterministic kernel mode, which this
scene’s collision and solver kernels exceed.
Distill the wrist-camera policy
The consolidated tutorial uses IsaacTutorial-Place-Vial-SO101-Camera for distillation.
If you followed an earlier version of this page, replace
IsaacTutorial-Place-Vial-SO101-Camera-Distillation with that task ID in training and playback commands.
Pass the finished teacher to the camera task. Add the renderer preset because the student observes wrist RGB:
The camera task’s default agent is RSL-RL’s DAgger-style distillation runner: the student acts, the frozen teacher
labels every visited state, and the labels are clipped to the executed [-1, 1] action range. Outputs are written
below logs/rsl_rl/so101_vial_camera_distillation/<run>.
Play the distilled student with the same task ID used for training:
Measure the policies
A visually convincing rollout is not an evaluation. Run the tracked phase-zero start set headlessly with the project’s external callback:
Use the same 1,024-start contract for the distilled policy:
The callback runs each tracked start once and prints one SO101_EVAL_RESULT JSON record. Preserve that record,
the checkpoint, seed, task ID, and resolved configuration when comparing experiments.
Maintain the reset dataset
The checked-in reset dataset is ready for training. Generate or inspect a separate candidate without overwriting it:
Train for the real robot
presets=sim2real adds the randomization used for robot transfer: contact, joint-dynamics, gain, and encoder
variation in both tasks, plus appearance and camera variation in the camera task. Because the physics randomization
is shared, the teacher and student train under the same physics. Fine-tune the state teacher with the preset, then
distill under the same preset:
The repository’s docs/SIM2REAL.md covers the physical setup, robot calibration, policy export, and deployment.
6. Make it yours
Change one boundary at a time and rerun the tests, zero-agent smoke test, and benchmark before training:
Keep these invariants as the task evolves:
- Task IDs resolve through the package entry point; do not copy Isaac Lab’s launcher scripts.
- Policy action order and scale match the robot command contract.
- Physical quantities and quaternions use Isaac Lab’s current conventions; Isaac Lab 3 uses XYZW quaternion order.
- Resets create valid physical states, and post-reset task code does not teleport the manipulated object.
- Success requires a released, mechanically seated vial rather than proximity to the rack.
- Tests cover observable task contracts, while a benchmark checks that changes did not move expensive work into the per-environment step loop.
From here, use Task Design Workflows for the manager/direct architecture, Reinforcement Learning for framework details, and Hydra Configuration System for command-line overrides.