

Reinforcement Learning
Isaac Lab provides a common workflow for training and evaluating policies with several reinforcement learning (RL) libraries. This page helps you choose a library, run your first experiment, and understand the options you are most likely to use.
If you are starting a new robotics project and do not need a feature unique to another library, start with RSL-RL.
Quick start
From the Isaac Lab repository, train a Cartpole policy with RSL-RL:
Training runs headless by default and writes checkpoints and TensorBoard logs
under logs/rsl_rl/.
To evaluate the latest compatible checkpoint in the interactive visualizer:
The train and play commands work across the supported RL libraries.
Try pretrained Cartpole, G1, and ANYmal-D controllers in the interactive demo gallery without installing Isaac Lab. These compact browser scenes illustrate policy control; use native playback for full task evaluation.
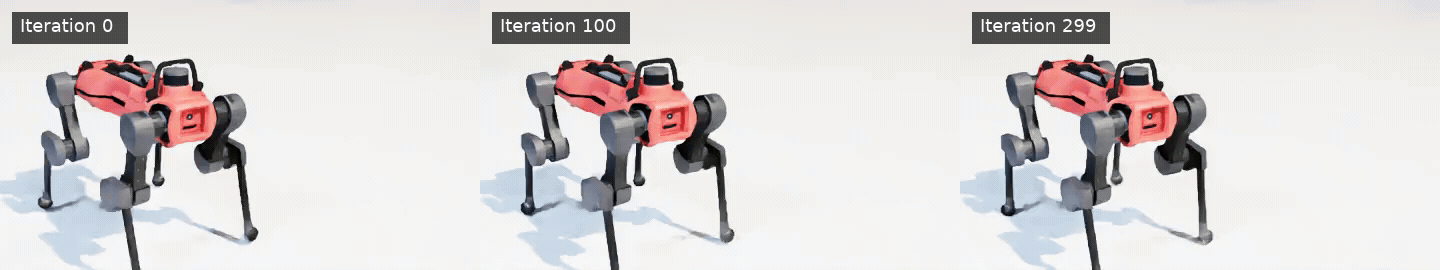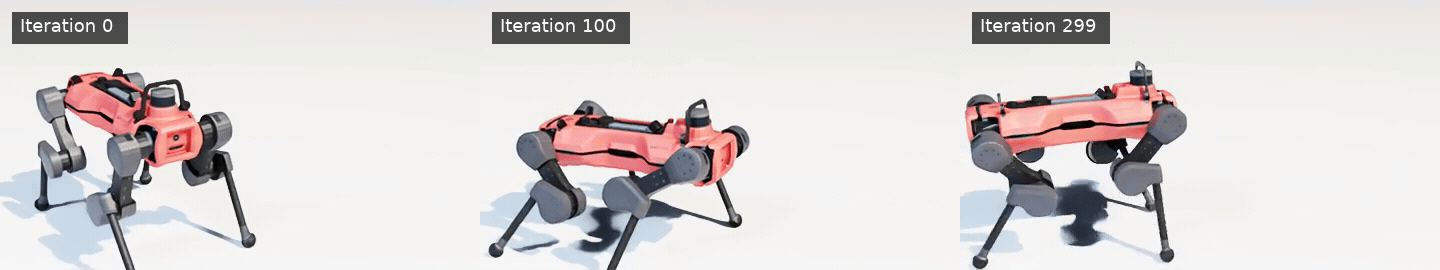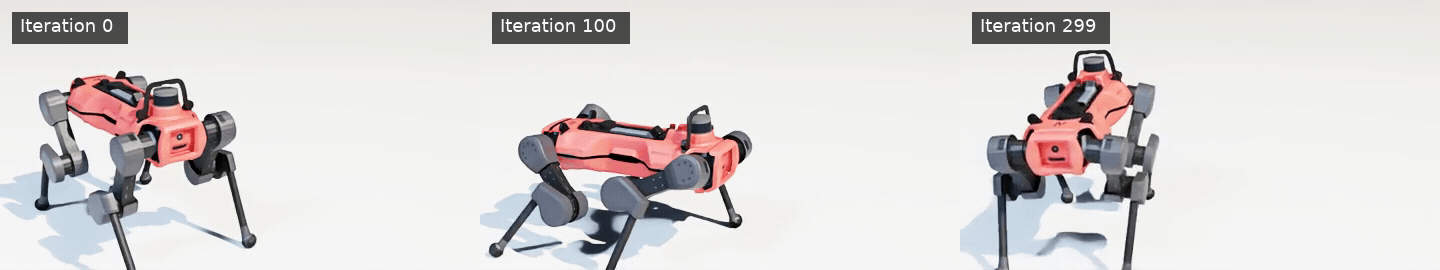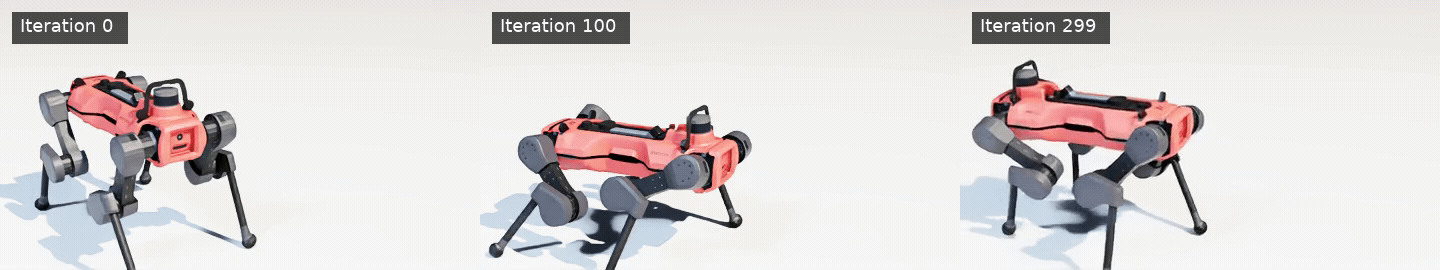
Choose an RL library
All supported libraries use the same Isaac Lab environments, but they differ in algorithms, configuration style, and intended workflow. Choose based on the features your experiment needs, not on a single throughput result.
Install optional dependencies by selecting the corresponding uv extra when running a command:
Typical training workflow
Before committing to a long run, verify the environment and the complete training path with small smoke tests.
First, check that the task resets and steps without an RL library:
Then run a few training iterations on a limited number of environments:
If both commands succeed, remove the smoke-test overrides and use the task’s tuned defaults.
Monitor training
Start TensorBoard in a second terminal:
Focus on trends across multiple iterations:
- Mean reward should generally improve, although its absolute value is task-specific.
- Mean episode length depends on the task. Longer episodes are useful for a balance task but not necessarily for a goal-completion task.
- Throughput helps identify systems bottlenecks after changes to the number of environments, sensors, or rendering.
- Losses, entropy, KL divergence, and action standard deviation help reveal unstable updates or stalled exploration. Exact metric names vary by library.
Evaluate a policy
Use play with one of the following checkpoint selectors:
For example, play the best local checkpoint and record a short video:
play applies the environment config’s play_mode() method: it caps the
scene at 50 environments and disables observation noise or corruption,
depending on the workflow. Override that method on a task config to customize
playback.
Pretrained checkpoints
Published pretrained checkpoints are available only for supported core tasks, and availability may vary by RL library and backend combination. Other registered tasks, including contributed tasks, are not covered by the published checkpoint set.
Pass --checkpoint pretrained to load the published policy matching the
resolved task configuration. The selector does not guarantee that an artifact
exists for every registered task: if the matching artifact has not been
published, the command reports that it is unavailable and exits. In that case,
train the task locally and use latest or an explicit checkpoint path.
Maintainers can generate the preferred core-task checkpoint matrix with
scripts/tools/train_and_publish_checkpoints.py. Use --list --all --core
to list the tasks and backend combinations targeted for publication by the
current source tree. This matrix is not a live check of the remote asset store;
a listed combination becomes usable with --checkpoint pretrained only
after its checkpoint has been uploaded.
Resume training
Resume from the latest compatible checkpoint:
When loading an explicit checkpoint, use the same task, agent, ML framework, and observation/action presets used during training. A checkpoint stores policy state; it cannot make incompatible observations or actions compatible.
Configure an experiment
Each task registers one or more agent configurations for the libraries it
supports. Start from the closest maintained configuration under
source/isaaclab_tasks/isaaclab_tasks/<task-family>/.../agents/ instead of
creating one from scratch.
Discover tasks and agents
List registered tasks, then inspect the task-specific help. The list includes an RL Libraries column, since each task supports only the libraries it registers a config for:
Use --agent to select an alternate registered configuration. For example:
Agent configuration formats are library-specific:
- RSL-RL uses Python configuration classes derived from
RslRlBaseRunnerCfg. - RL-Games, skrl, and Stable-Baselines3 use library-specific dictionaries or YAML files.
- RLinf uses a dedicated VLA post-training configuration.
When a task offers multiple observation or action presets, choose an agent whose network matches the selected preset.
If you omit --rl_library, train and play load the task’s
registered default_agent. Most core tasks default to RSL-RL; the
multi-agent Pendulum task defaults to skrl.
Override configuration with Hydra
Hydra allows you to override environment and agent configurations after the regular command-line options:
See /source/features/hydra for quoting rules, list values, and multirun sweeps.
Select backends and presets
Tasks can expose named selectors for physics, rendering, observations, actions, and other domains. Append selectors without leading dashes:
Not every task supports every backend. See /source/concepts/backends_and_presets for the presets declared by a task.
Use the same physics, renderer, domain, and observation/action presets for training and playback. Changing an observation or action preset can change the policy architecture and cause checkpoint shape errors. This is a feature and reflects that the selected configuration defines the policy contract.
Scale training
Isaac Lab collects experience from many environments in parallel.
--num_envs controls the number of simulation instances. Increasing it can
improve sample collection until simulation cost, optimizer structure, or GPU
memory becomes the bottleneck. Use --num_envs to scale up or down as needed,
but recognize that more environments do not always make training faster.
Isaac Lab also supports distributed training for RSL-RL, RL-Games, and skrl. See /source/features/multi_gpu for details on scaling training across multiple GPUs.
Specialized workflows
The standard training workflow is sufficient for most tasks. The following workflows are useful when transferring an existing policy, training multiple agents, using JAX, or post-training a vision-language-action model.
RSL-RL distillation
Distillation transfers behavior from a trained teacher policy to a student policy. The student learns to reproduce the teacher’s actions, often using a different observation set or a smaller network. This is useful when the teacher uses information that will not be available at deployment time. For example, you can train a state-based policy and distill it to a vision-based policy.
First, train the teacher:
Then select the registered distillation agent and load the teacher checkpoint:
The task and distillation configuration determine which observations are available to the teacher and student. Make sure the checkpoint was produced by a compatible teacher configuration.
skrl multi-agent training
Multi-agent reinforcement learning trains multiple agents that act in the same environment. skrl supports two common approaches:
-
MAPPO uses information from all agents while training the value function, but allows each agent to act from its own observations at runtime. This centralized-training, decentralized-execution approach can help agents learn coordinated behavior.
-
IPPO trains each agent independently. It is simpler and provides a useful baseline, but it does not explicitly use information from the other agents during optimization.
For example, train the Shadow Hand handover task with MAPPO:
Use --algorithm IPPO to run the corresponding independent-policy workflow.
The selected task must expose a multi-agent interface supported by the
algorithm.
skrl training with JAX
skrl can also train policies with JAX instead of PyTorch. This is useful when integrating with a JAX-based learning stack or experimenting with JAX compilation and execution:
The skrl-jax extra installs JAX with CUDA 13 support and the skrl JAX
dependencies. Use it instead of the skrl extra for this workflow.
JAX preallocates GPU memory by default, so ensure that the simulation and learner can share the available memory. See the skrl installation guide and the JAX installation guide for more information.
RLinf VLA post-training
Vision-language-action (VLA) models map visual observations and language instructions to robot actions. RLinf uses reinforcement learning to adapt a pretrained VLA model to a task, improving its behavior using task rewards rather than demonstrations alone.
Provide an RLinf experiment configuration and the base model to post-train:
VLA post-training typically requires substantially more GPU memory than training a small policy from scratch. See RL Post-Training for VLA Models for installation, distributed execution, configuration, and evaluation.
Programmatic use
Downstream applications and automated scripts can invoke the same training
dispatcher used by the command line. Constructing a request directly avoids creating an
argparse.Namespace and provides a stable interface for launching training
from Python:
Use ~isaaclab_rl.entrypoints.PlaybackRequest with
~isaaclab_rl.entrypoints.play for playback. Place options understood by
the selected RL library in backend_args. Place Hydra overrides and preset
selectors in hydra_args.
Troubleshooting
Out of memory
Reduce --num_envs first. This usually provides the largest memory reduction
without changing the task itself. For camera-based tasks, also consider
reducing the image resolution, number of captured views, rollout length, or
policy size.
Disable the interactive visualizer during performance runs. Remember that collision geometry, contacts, and deformable bodies consume simulation memory independently of the policy and rollout buffers.
When using JAX, account for its default GPU-memory preallocation in addition to the memory required by the simulation.
NaNs in observations or the policy
NaNs often originate in an unstable simulation or invalid reset state and then propagate through the observations, rewards, and learner. Reproduce the failure without training when possible, and locate the first value that becomes non-finite.
Check:
- reset joint positions, velocities, and object poses;
- actuator gains, limits, and action scaling;
- contact geometry, masses, inertias, and unexpectedly large impulses;
- the physics time step, substeps, and solver iterations; and
- reward or observation terms containing unsafe division, normalization, or square roots.
Fix the invalid state or calculation rather than masking the problem by clamping every policy input. Then repeat the training smoke test.
Training is stable but does not learn
Verify the environment contract before tuning hyperparameters:
- actions control the intended joints;
- observations change as the environment changes;
- rewards increase when the agent makes progress; and
- terminations and resets occur under the expected conditions.
Compare the configuration with the closest maintained task, then change one factor at a time. For each experiment, record the task, RL library, physics backend, domain presets, seed, number of environments, agent configuration, and Hydra overrides. Without this information, apparently small configuration differences can be mistaken for algorithmic regressions.
Checkpoint does not load
Verify that the playback or resumed-training command uses the same RL library, task, agent configuration, ML framework, and observation and action presets as the original run. Tensor-shape errors usually indicate that one of these settings changed.
Prefer the latest or best checkpoint selectors when available. Manifest
discovery filters incompatible runs before attempting to load their
checkpoints.
Next steps
-
Training with an RL Agent explains how an Isaac Lab environment is wrapped for an RL library.
-
Configuring an RL Agent walks through registering and selecting agent configurations.
-
/source/features/hydra covers command-line overrides and sweeps.
-
/source/features/multi_gpu covers multi-GPU and multi-node training.
-
/source/how-to/reproducibility covers reproducible experiments.
-
/source/how-to/capture_sensor_frames covers image-observation diagnostics.
This page is the source of truth for the isaaclab-training-rl-agents and
isaaclab-debugging-rl-training agent skills
(skills/user/train-rl-agents/,
skills/user/debug-rl-training/). When you change this
page, update those skills so their guidance stays in sync. See
/source/developer-tools/agent_skills.