

3D Multi Camera Detection and Tracking (Sparse4D)
The Real Time Video Intelligence CV Microservice leverages NVIDIA DeepStream SDK to generate metadata for each stream that downstream microservices can use to generate spatial metrics and alerts.
The microservice features metropolis-perception-app, a DeepStream pipeline that builds on the built-in deepstream-test5 app in the DeepStream SDK.
This perception app provides a complete application that takes streaming video inputs, decodes the incoming streams, performs inference & tracking, and sends the metadata to other microservices using the defined Protobuf schema.
The application features a modular architecture that integrates preprocessing plugins and a custom video template plugin (Sparse4D) specifically designed for multi-object detection and tracking in three-dimensional space.
At its core, Sparse4D performs Birds-Eye-View (BEV) 3D object detection and temporal tracking across multiple synchronized camera sensors within defined BEV groups. Refer to the Sparse4D model page for more details on the model architecture and training process.
The pipeline ingests multicamera video streams, processes them through calibrated projection matrices for spatial alignment, and utilizes a feedback mechanism with temporal instance banking to maintain object identity across frames. Detection results include 3D position, orientation, velocity, and instance IDs, enabling sophisticated multi-camera fusion capabilities.
For detailed information on all components, APIs, and customization options, refer to the Object Detection and Tracking.
The diagram below shows the perception pipeline used in the microservice:
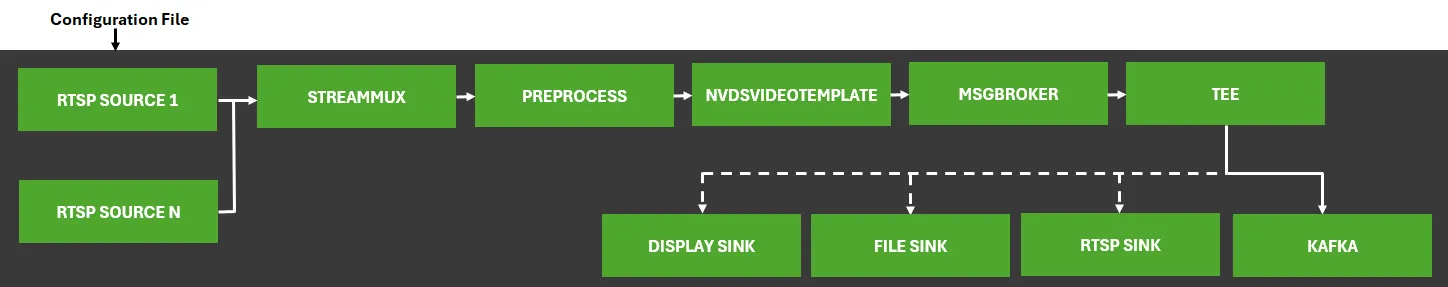
Configurations
The Perception microservice requires several configuration files that control various aspects of the 3D multi-camera detection and tracking system. These files allow users to customize the system’s behavior according to their specific requirements.
Dataset-specific Model Paths
For the Warehouse Operations Docker Compose profile, set DATASET_TYPE to synthetic or real in $VSS_APPS_DIR/industry-profiles/warehouse-operations/overrides.env before running the Blueprint Configurator. It selects the matching ResNet50 model, anchor, engine path, and labels and updates models-download.json and deepstream/configs/config.yaml. The generated paths are:
Here, <N> is the configured camera count (num_sensors), not the model batch size. Startup may reuse a compatible higher-camera-count engine for the same ONNX basename. Downloaded ONNX filenames have an _r50 suffix in the model package; the download manifest renames them to the suffix-free runtime filenames above. Anchor filenames retain _r50. The standalone detection/tracking helper has separate defaults that remain on v2.2; it does not use this dataset-based selection.
Docker Compose Volume Mounts
For docker compose deployment, the perception-3d service in deploy/docker/industry-profiles/warehouse-operations/warehouse-3d-app/warehouse-3d-app.yml mounts host paths into the container as follows:
The host directory $VSS_DATA_DIR/models/ is bind-mounted at /opt/storage/; there are no individual ONNX or anchor mounts. At startup, ds-start.sh uses models-download.json to acquire the selected artifacts into /opt/storage/sparse4d/. ONNX, anchor, and TensorRT engine files persist on the host under $VSS_DATA_DIR/models/sparse4d/. DeepStream pipeline configs (ds-main-config.txt, ds-mtmc-preprocess-config.txt, and related files) live on the host under $VSS_APPS_DIR/industry-profiles/warehouse-operations/warehouse-3d-app/deepstream/configs/ and appear in the container under metropolis_perception_app/configs/. The Sparse4D inference file config.yaml and calibration file are supplied at /opt/data/ds-configurator/.
Inference Configuration File
The main configuration file for Sparse4D, config.yaml, handles properties related to model inference and controls the core functionality of the 3D detection and tracking system. On the host, edit this file at $VSS_APPS_DIR/industry-profiles/warehouse-operations/warehouse-3d-app/deepstream/configs/config.yaml; docker compose mounts it to /opt/data/ds-configurator/config.yaml for the DeepStream Configurator. The configuration parameters organize into the following categories:
Inference Properties
Calibration Properties
Preprocessing Properties
These are network-input dimensions, not the source-video resolution: source frames such as 1920 x 1080 RGB images are preprocessed to 960 x 540 (width x height). The model image tensor is (1, N, 3, 540, 960), where N is the number of synchronized cameras in one BEV group. Keep the model batch_size at 1; DeepStream’s stream batch size and num_sensors represent N.
Augmentation Configuration:
Instance Bank Properties
Decoder Properties
The raw model outputs contain 900 queries. In the TAO tracking decoder, top-300 selection uses each query’s maximum sigmoid classification score across the seven classes. Quality estimation then weights the selected scores by sigmoid centerness and re-sorts them. Confidence thresholds can reduce the returned count below 300. The 600-entry temporal cache is selected separately, using confidence history and decay; it is not the candidate pool for this final top-300 selection. Do not use num_temp_instances as the output-buffer size for raw TensorRT outputs.
Debugging Properties
DeepStream Configuration File
The DeepStream main configuration file (ds-main-config.txt) builds on the DeepStream test5 application configuration and provides essential settings for the overall pipeline. This file controls various aspects of the application, including source configuration, stream multiplexing, message broker settings, and visualization parameters.
Key Configuration Sections
For a complete understanding of all configuration options, refer to the DeepStream SDK Documentation.
Preprocess Plugin Configuration File
The gst-nvdspreprocess plugin performs all preprocessing operations such as resizing, scaling, cropping, format conversion, and normalization on incoming video frames before feeding them to the neural network. These preprocessing operations prepare the input data according to the specific requirements of the Sparse4D model. You can configure all these preprocessing operations via the preprocess configuration file ds-mtmc-preprocess-config.txt.
For detailed information about the preprocessing configuration parameters and options, refer to the DeepStream Preprocessing Plugin Documentation.
Custom Video Template Plugin Configuration File
The ds-mtmc-videotemplate_custom_lib_config.txt file contains the configuration parameters for the custom video template plugin. This file configures the custom video template plugin for the Perception microservice.
The configuration specifies which GPU to use for processing and the path to the custom Sparse4D library that implements the 3D detection and tracking functionality.
Kafka Configuration File
The ds-kafka-config.txt file contains the Kafka configuration parameters for the Perception microservice. This file configures the Kafka producer and consumer settings for the Perception microservice.
The partition key setting ensures that messages from the same sensor go to the same Kafka partition, maintaining message ordering per camera stream.
Calibration File
The calibration.json file defines camera calibration parameters essential for 3D spatial understanding. This file contains intrinsic and extrinsic camera parameters for each camera in the system. On the host, it is located under $VSS_APPS_DIR/industry-profiles/warehouse-operations/warehouse-3d-app/calibration/sample-data/<SAMPLE_VIDEO_DATASET>/ and mounted into the container at /opt/data/ds-configurator/calibration.json. For detailed information about camera calibration parameters and setup, refer to the Calibration.
Labels File
The labels-synthetic.txt and labels-real.txt files contain the class labels that the model can detect along with class-wise confidence thresholds for filtering detections. Docker Compose mounts the file selected by DATASET_TYPE from $VSS_APPS_DIR/industry-profiles/warehouse-operations/warehouse-3d-app/deepstream/label/ into /opt/nvidia/deepstream/deepstream/sources/sparse4d/label/, retaining its filename. Each entry corresponds to a model class and its confidence threshold; users can tune the thresholds for their scene. The Helm chart also selects one of these two source files, but exposes it through a ConfigMap as /opt/nvidia/deepstream/deepstream/sources/sparse4d/labels.txt.
The file format uses a semicolon-separated list where each entry follows the pattern ClassName:ConfidenceThreshold:
For the released v2.3 and v3.0 models, retain all seven entries in this order (class IDs 0 through 6), even when a class is absent from your scene or evaluation set. Threshold values are examples and can be tuned without removing or reordering entries. Fine-tuned models must use their own training class count and order; changing the labels file alone does not change the model’s classifier.
Anchor File
The anchor file initializes the Sparse4D instance bank. Use /opt/storage/sparse4d/_ov_kmeans900_v2.3_r50.npy with the v2.3 ResNet50 model or /opt/storage/sparse4d/_ov_kmeans900_v3.0_r50.npy with the v3.0 ResNet50 model, as selected by DATASET_TYPE. The matching anchor is downloaded alongside the ONNX model; do not mix anchors across releases or backbones.
Runtime Configuration Adjustments
This section covers common configuration changes that users may need to make when adapting the Sparse4D pipeline for their specific deployment scenarios.
Modifying the Number of Input Streams
When updating the number of input streams/cameras, you must update the batch size settings in multiple configuration files to ensure consistency. This step is critical for the proper operation of the Sparse4D pipeline.
The related DeepStream configuration files can be found on the host at $VSS_APPS_DIR/industry-profiles/warehouse-operations/warehouse-3d-app/deepstream/configs/ (mounted into the container at /opt/nvidia/deepstream/deepstream/sources/apps/sample_apps/metropolis_perception_app/configs/).
Updating the Inference Configuration
Modify the config.yaml file to update the number of sensors:
Update DeepStream Configuration
Modify the ds-main-config.txt file to update source and batch size settings:
Updating Preprocess Configuration
Modify the ds-mtmc-preprocess-config.txt file to update the network input shape:
Integrating a Sparse4D Model Checkpoint
The Sparse4D plugin supports model swapping, allowing you to use different Sparse4D models based on your specific use case.
For adaptation to real-world datasets with 2D labels or detector pseudo-labels, follow the 2D-to-3D geometric distillation workflow. The LTT correction model and 2D teacher are used during training; deploy the adapted Sparse4D model using the compatibility checks below. Real camera calibration is still required for the multi-camera 3D pipeline.
Model Compatibility Requirements
Use the Input and Raw ONNX/TensorRT outputs sections of the matching NGC model card (ResNet50, ResNet101) as the tensor-interface reference. For v2.3 ResNet50/ResNet101 and v3.0 ResNet50, verify the following before starting the pipeline:
- Version and backbone: use the ONNX model, experiment specification, and anchor from the same release/backbone. A cached engine must correspond to that model and the target TensorRT/GPU environment; rebuild it when changing the model or engine build settings.
- Image inputs and camera profile:
imgis(1, N, 3, 540, 960),projection_matis(1, N, 4, 4), andimage_whis(1, N, 2). Use the sameNacross all three inputs, consistent with preprocessing and stream configuration. The selected engine optimization profile must support thatN; a dynamic ONNX dimension does not guarantee every camera count is supported by an existing engine. - Temporal inputs and dtypes:
input_cached_featureis(1, 600, 256),input_cached_anchoris(1, 600, 11),prev_existsis(1,), andinterval_maskis(1, 1, 1). The released ONNX inputs are float32 except for Booleaninterval_mask.prev_existsis float32, not Boolean. Query the engine’s actual I/O dtypes before allocating buffers; FP16 execution does not imply FP16 bindings. - Raw outputs: verify all 12 binding names against the model card. Classification outputs have shape
(1, 900, 7), prediction/anchor outputs(1, 900, 11), quality outputs(1, 900, 2), and the feature output(1, 900, 256). The final detection dictionary keys, such asboxes_3d, are post-processing results, not engine bindings. - Labels and anchors: the seven labels must follow the trained class order, and the anchor array must have shape
(900, 11). Matching dimensions alone do not prove that an anchor or label order belongs to the selected model; retain the release/version association. - Post-processing: keep
num_anchor = 900,num_temp_instances = 600,embed_dims = 256, andnum_output = 300consistent with the released configuration. Use compatible Sparse4D box decoding and temporal-cache logic. In particular, the 900-query cache outputs require instance-bank selection before reuse as 600-entry inputs.
These checks can be automated in a deployment preflight: enumerate engine tensor names, dtypes, shapes, and optimization profiles with the TensorRT API, then compare them with the configuration, labels, anchor, and versioned model metadata. Resolve dynamic shapes for the intended camera count before checking buffer sizes. A class dimension only verifies the number of classes, not their semantic order. Stop deployment on a mismatch and report the offending field; do not rely on automatic correction or assume the existing plugin performs every check above.
Updating Sparse4D Configuration
- Place your custom ONNX and anchor in
$VSS_DATA_DIR/models/sparse4d/on the host. The existing/opt/storage/directory mount exposes both files without individual model mounts. Place your custom labels in the host label directory and replace the dataset-label mount with the custom-label mount shown below. This is a custom-model configuration, not the default release setup:
- Place your new ONNX model (for example,
your_new_model.onnx) and anchor file (for example,your_new_anchors.npy) in$VSS_DATA_DIR/models/sparse4d/on the host. SetDS_MODEL_DOWNLOAD: neverin theperception-3dservice’s environment when supplying these files locally, so startup does not download the stock release manifest. - Place your new labels file (for example,
your_new_labels.txt) in$VSS_APPS_DIR/industry-profiles/warehouse-operations/warehouse-3d-app/deepstream/label/on the host.
- Update
config.yamlon the host at$VSS_APPS_DIR/industry-profiles/warehouse-operations/warehouse-3d-app/deepstream/configs/config.yaml:
Apply these custom paths after Blueprint Configurator generation and before starting or restarting perception-3d; rerunning the configurator restores the dataset-selected paths unless its corresponding model-path rules are also customized. Startup derives the engine filename from the ONNX basename and num_sensors (b4 above assumes four cameras). The Perception microservice builds the TensorRT engine for the new model, and engine files persist under $VSS_DATA_DIR/models/sparse4d/ on the host. Use a distinct ONNX basename for a new model to avoid accidentally reusing an older engine.
Your labels file must list all classes in the same order your model was trained on. This example is for the seven-class v2.3/v3.0 releases; use the matching class list for a custom fine-tuned model.
Since model training and inference depend on the initialized anchor .npy file, use the anchor file from the TAO finetuning process when you finetune on a new scene or set of classes.
- If the resolution is changed for the new model, set the
NETWORK_WIDTHandNETWORK_HEIGHTenvironment variables to match the new model’s input resolution.
The sparse4d_setup.sh script automatically handles updating the required configuration parameters in config.yaml and ds-mtmc-preprocess-config.txt (under metropolis_perception_app/configs/ in the container) based on these values.