

RT-DETR (2D warehouse detection)
TAO RT-DETR fine-tuning and deployment guidance for 2D warehouse object detection.
This page combines the RT-DETR Warehouse 2D Model overview, sample output, model-card reference, runtime performance, evaluation KPI, and TAO workflow for dataset preparation, training, evaluation, inference, export, optional FP16 optimization, and Perception microservice integration.
TAO RT-DETR is an advanced 2D Single-Camera Real-Time Detection Transformer tailored for warehouse environments and industrial automation settings. It generates precise 2D bounding boxes for a diverse set of objects including people, humanoid robots, autonomous vehicles, and warehouse equipment. The RT-DETR Warehouse 2D Model v1.0.2 is part of NVIDIA’s RT-DETR family and is pretrained on warehouse scene datasets for precise 2D object detection in industrial environments. This release uses a lighter-weight ResNet-50 backbone to reduce model size and inference cost while retaining competitive accuracy.
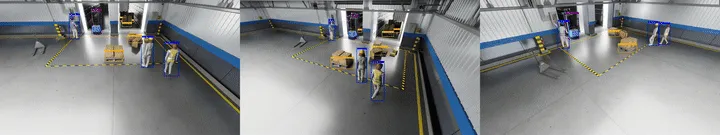
Release Information
The RT-DETR Warehouse 2D Model v1.0.2 release is scheduled for NGC on June 2, 2026.
The model was trained and evaluated on seven warehouse-centric classes: Person, Fourier GR1_T2 Humanoid, Agility Digit Humanoid, Nova Carter, Transporter, Forklift, and Pallet.
Key NGC artifacts include:
- rtdetr_warehouse_v1.0.2.onnx and FP16 ONNX for ResNet-50 deployment.
Model Card
The TAO RT-DETR model card on NGC describes architecture, datasets, and accuracy methodology.
Inference using Perception Microservice
Detailed information can be found in the Warehouse 2D single-camera detection and tracking page.
Real-Time Inference Throughput & Latency
The following VSS 3.3 / DeepStream 9.1 target results were collected on September 16, 2026, for the RT-DETR v1.0.2 ResNet-50 deployable model at 640×640 input resolution. These are compute-only stream capacity estimates from TensorRT measurements at each device’s peak-throughput batch size.
Compute throughput in images per second is batch_size * 1000 / compute_latency_ms. Stream capacity is floor(compute_throughput / target_fps), using inference rates of 30 or 15 FPS per stream. Decode, tracking, preprocessing, postprocessing, and pipeline contention are excluded; deployed pipeline capacity can be lower.
Benchmark Software Stack
The dGPU results use strongly typed TensorRT engines; the embedded results are labeled FP16. Software versions differ by platform:
KPI
The key performance indicators are Average Precision (AP) per-class evaluated on the Warehouse Synthetic Test dataset. AP quantifies a detector’s ability to trade off precision and recall for a single object category by computing the normalized area under its precision-recall curve.
The model supports 7 object categories: Person, Agility Digit (humanoid robot), Fourier GR1_T2 (humanoid robot), Nova Carter, Transporter, Forklift, and Pallet.
Evaluation Settings
The reported metrics use the following evaluation configuration:
- AP Variant: COCO AP@0.50
- IoU Thresholds: 0.50
- Max Detections: 100 detections per image
- Matching Policy: Greedy matching based on IoU with ground truth boxes, highest confidence predictions matched first
The Warehouse Synthetic Test evaluation uses the MTMC Tracking 2025 subset from the NVIDIA PhysicalAI-SmartSpaces dataset. This is a comprehensive, annotated dataset for multi-camera tracking and 2D/3D object detection, synthetically generated with NVIDIA Omniverse. The dataset consists of time-synchronized video from indoor warehouse scenes with annotations for 2D & 3D bounding boxes and multi-camera tracking IDs. The Warehouse Synthetic Test dataset used for evaluation is the Warehouse_019 scene from the test split.
Please refer to the Model Card for more details on benchmark datasets and evaluation methodology.
Model versions
The VSS 3.2.0 model card identifies RT-DETR 2D Warehouse Perception Model v1.0 as the warehouse detector family and lists deployable updates through v1.0.2:
Use backbone: efficientvit_l2 for the v1.0/v1.0.1 EfficientViT-L2 path, or backbone: resnet50 for the v1.0.2 lightweight path.
Hardware & Software Requirements
Please refer to the Requirements section of the TAO Toolkit Quick Start Guide for more details.
The VSS 3.3 performance snapshot targets DeepStream 9.1. The measured TensorRT, CUDA, and GPU driver versions are listed in Benchmark Software Stack. TAO fine-tuning requires TAO 6.25.10 or later.
Dataset Requirements
The RT-DETR model can be fine-tuned on your own dataset for warehouse object detection tasks. The model is pre-trained on large-scale warehouse datasets including synthetic and real-world data.
For fine-tuning on your custom dataset, the data requirements are as follows:
Minimum Requirements:
-
Image Format
- RGB images in standard formats (JPEG, PNG)
- Recommended resolution: 640x640 or higher
-
Number of Training Images
- Minimum: 1,000 annotated images per class
- Recommended: 5,000+ images for robust performance
-
Annotations
- Ground Truth 2D bounding boxes in COCO format or compatible format
- Class labels for all objects
-
Data Split
- Training set: 70-80% of total data
- Validation set: 10-15% of total data
- Test set: 10-15% of total data
The model supports 7 object categories: Person, Agility Digit (humanoid robot), Fourier GR1_T2 (humanoid robot), Nova Carter, Transporter, Forklift, and Pallet.
Fine-tuning using NVIDIA TAO Toolkit
RT-DETR can be fine-tuned via the TAO containers and the TAO CLI Notebook.
The documentation provided below accompanies the cells in the TAO fine-tuning notebook and offers guidance on how to execute them. TAO RT-DETR supports the following tasks via the Jupyter notebook:
- dataset
convert - model
train - model
evaluate - model
inference - model
export
An experiment specification file (also known as a configuration file) is used for fine-tuning the model. It consists of several main components:
datasetmodeltrainevaluateinferenceexport
For more information on experiment spec file, please refer to the Train Adapt Optimize (TAO) Toolkit User Guide - RT-DETR.
Backbone Configuration
Use ResNet-50 for v1.0.2:
The following is a ResNet-50 example spec file for training an RT-DETR model on warehouse datasets.
Notice that the example fine-tunes, evaluates, and exports at 640x640 resolution for optimized inference.
Dataset Preparation
The RT-DETR model supports two data input formats for training. You can prepare your dataset in either format depending on your data source.
Option 1: COCO Format
The standard format for RT-DETR training is the COCO (Common Objects in Context) format. This format uses JSON annotation files with the following structure:
For detailed information on the COCO format specification, please refer to the TAO Toolkit Data Annotation Format - Object Detection COCO Format documentation.
The directory structure for COCO format should be:
Option 2: H5 Files Format
For synthetic data generation pipelines or large-scale datasets, RT-DETR also supports data stored in HDF5 (H5) format. In this format, RGB images are stored within H5 files organized by camera.
The directory structure for H5 format is as follows:
Each H5 file contains an rgb group with RGB image frames (e.g., rgb_00000.jpg, rgb_00001.jpg, …).
The ground truth annotations use the same COCO JSON format as Option 1, but the file_name field in the images array uses a special H5 URI format:
For example:
Launch Model Fine-tuning
Below are the important configurations that need to be updated to launch training:
Once the configurations are modified, launch training by running the following command:
The pretrained RT-DETR warehouse checkpoints and deployable ONNX artifacts are available in the NGC Catalog. Select the NGC version that matches the backbone and input resolution summarized above.
Evaluate the fine-tuned model
The fine-tuned model’s accuracy can be evaluated using the Average Precision (AP) metrics.
Below are the important configurations that need to be updated to launch evaluation:
Once the configurations are modified, launch evaluation by running the following command:
Run Inference on the fine-tuned model
The fine-tuned model’s output can be inspected by running inference and visualizing the 2D bounding boxes. Below are the important configurations that need to be updated to launch inference:
Once the configurations are modified, launch inference by running the following command:
Export the fine-tuned model
Below are the important configurations that need to be updated to launch export:
Once the configurations are modified, launch export by running the following command:
By default, the exported model is in ONNX format, FP32 precision. To further optimize the model for deployment, you can convert the model to FP16 precision using the NVIDIA Model Optimizer
Step 1: Install NVIDIA Model Optimizer and set up your environment by following the official instructions here: https://nvidia.github.io/Model-Optimizer/getting_started/_installation_for_Linux.html
Step 2: Convert the model to FP16 precision using the following command:
Using the fine-tuned model in the Perception Microservice
Once the model is fine-tuned and exported to ONNX format, it can be used in the Perception Microservice. Refer to the Integrating a New RT-DETR Model section for more details.