

3D Vision AI Profile
Overview
Introduction
The VSS Warehouse Blueprint’s 3D Vision AI Profile is a comprehensive guide to building a 3D intelligent video analytics system. It provides a detailed overview of the system architecture, data flow, and key components.
Deployment Architecture
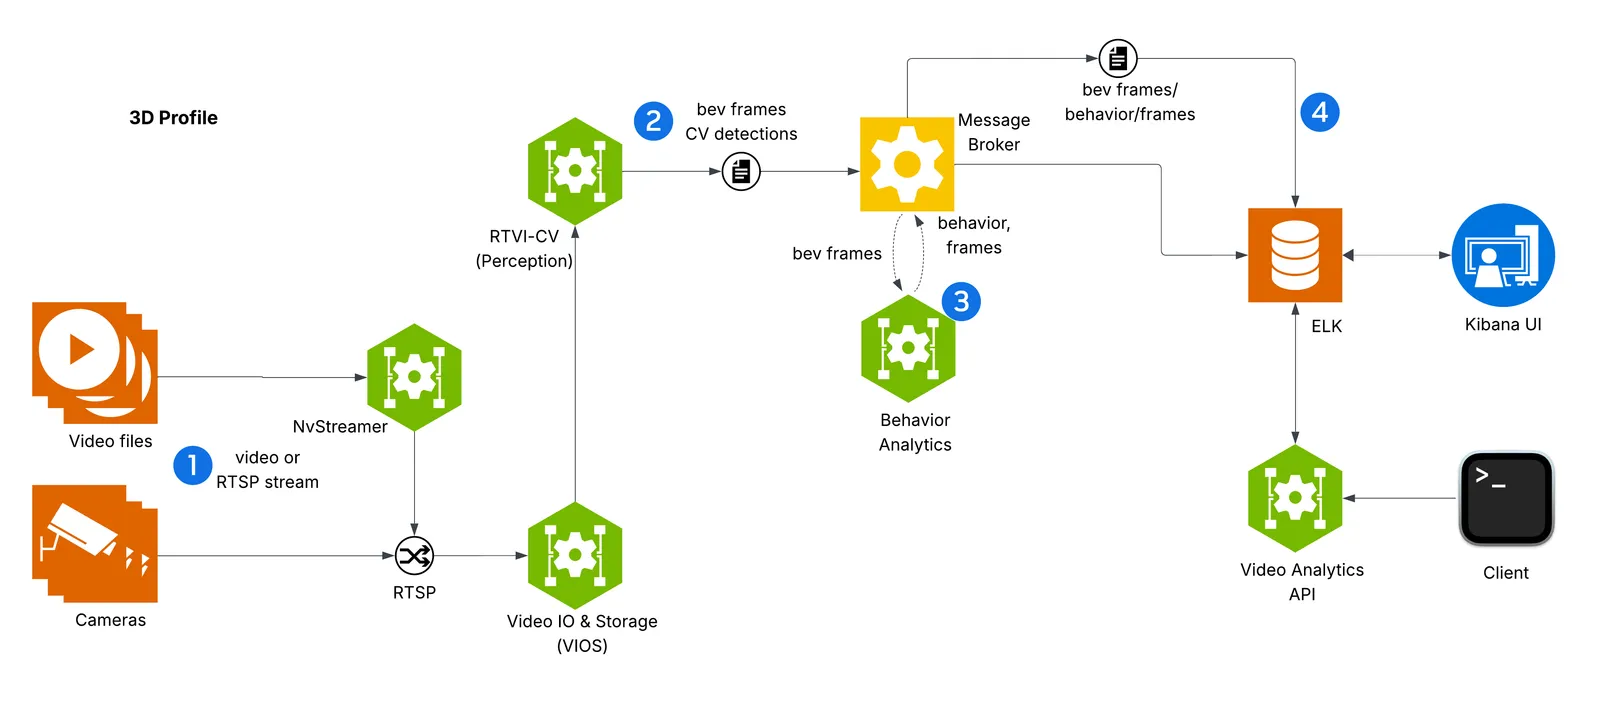
Components and Interactions
The diagram depicts VSS Warehouse 3D Blueprint, emphasizing 3D multi-camera detection, tracking, and behavior analytics for safety events and metrics. Below is a breakdown of the components and their interactions.
-
Input Source
- Videos: Raw video data stored in a filesystem, serving as input for processing.
- NvStreamer (NVStreamer): A microservice that streams videos via RTSP (Real-Time Streaming Protocol) to the VIOS (Video IO & Storage). NvStreamer can be swapped with real-world cameras.
-
Video IO & Storage (VIOS) (VIOS Microservices)
- VIOS ingests video streams from NvStreamer via RTSP.
- It records the streams and forwards them (via RTSP) to the DeepStream microservice for further processing.
-
DeepStream (3D Multi Camera Detection and Tracking (Sparse4D))
- DeepStream processes RTSP streams for 3D multi-camera detection and tracking, utilizing the Sparse4D model (Sparse4D (3D multi-camera)) to generate BEV (Bird’s Eye View) outputs.
- It sends frame data, including detected and tracked object IDs, in Protobuf format to the message broker via the
mdx-bevtopic.
-
Message Broker (Kafka or Redis)
- The message broker serves as the central hub for data distribution, using Protobuf for all data exchanges.
- Kafka (Kafka): High-throughput message broker optimized for datacenter deployments with robust persistence and scalability.
- Redis Streams: Lightweight message broker ideal for edge deployments with minimal memory footprint and low-latency requirements.
- It also functions as a control bus, managing notifications (in JSON, via
mdx-notification) for calibration updates, such as new ROI or tripwire definitions.
-
Behavior Analytics (Behavior Analytics)
- This microservice consumes
mdx-bevdata (Protobuf) from the message broker. - It processes the data to generate behavior analytics, safety insights, and metrics.
- The resulting data, in Protobuf format, is sent back to the message broker for indexing into Elasticsearch.
- This microservice consumes
-
Storage
- ELK (Elasticsearch, Logstash, Kibana) (ELK): Logstash retrieves BEV outputs and safety violation frames from the message broker, converts Protobuf to JSON, stores the data in Elasticsearch, and supports querying and visualization.
-
Visualization
-
External Interfaces
- API Gateway and MCP (API Gateway / MCP): Enables external systems to interact with the events data through API calls.
Key Technologies
- Microservices: Components like NvStreamer, VIOS, DeepStream, and Behavior Analytics are modular microservices.
- RTSP: Facilitates real-time video streaming.
- Protobuf: Ensures efficient, compact data exchange.
- Message Broker: Manages data distribution and control messaging.
- ELK Stack: Supports storage, logging, and visualization.
- JSON: Used for notifications and calibration data.
Setup and Configuration
Testing and Validation
Kibana UI
In the new Kibana UI (versions 8.0 and later), “Index Patterns” have been renamed to “Data Views”.
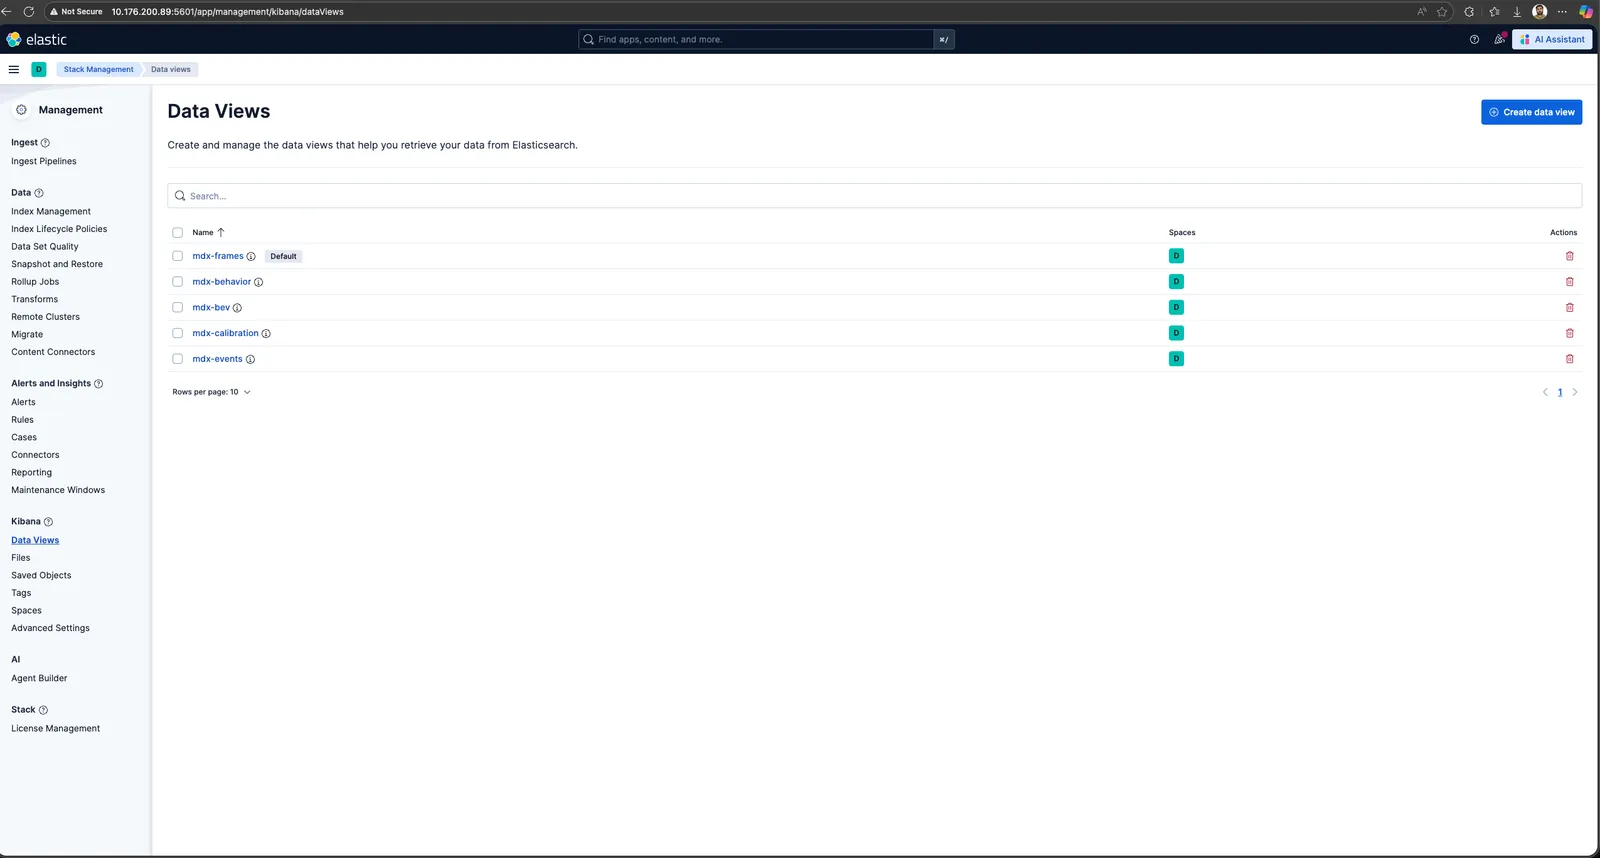
Check for BEV, Frames and Behavior Data Views in Kibana:
- Launch Chrome browser
- In the address bar enter
http://<IP_address>:7777/kibana
In the user interface, navigate to the Management -> Stack Management section and select Data Views under Kibana. If the data views are not visible, create a new data view (via “Create data view” button on the top right corner) for mdx-bev, mdx-frames and mdx-behavior.
Browse the Kibana UI, discover the data views and visualize the data.
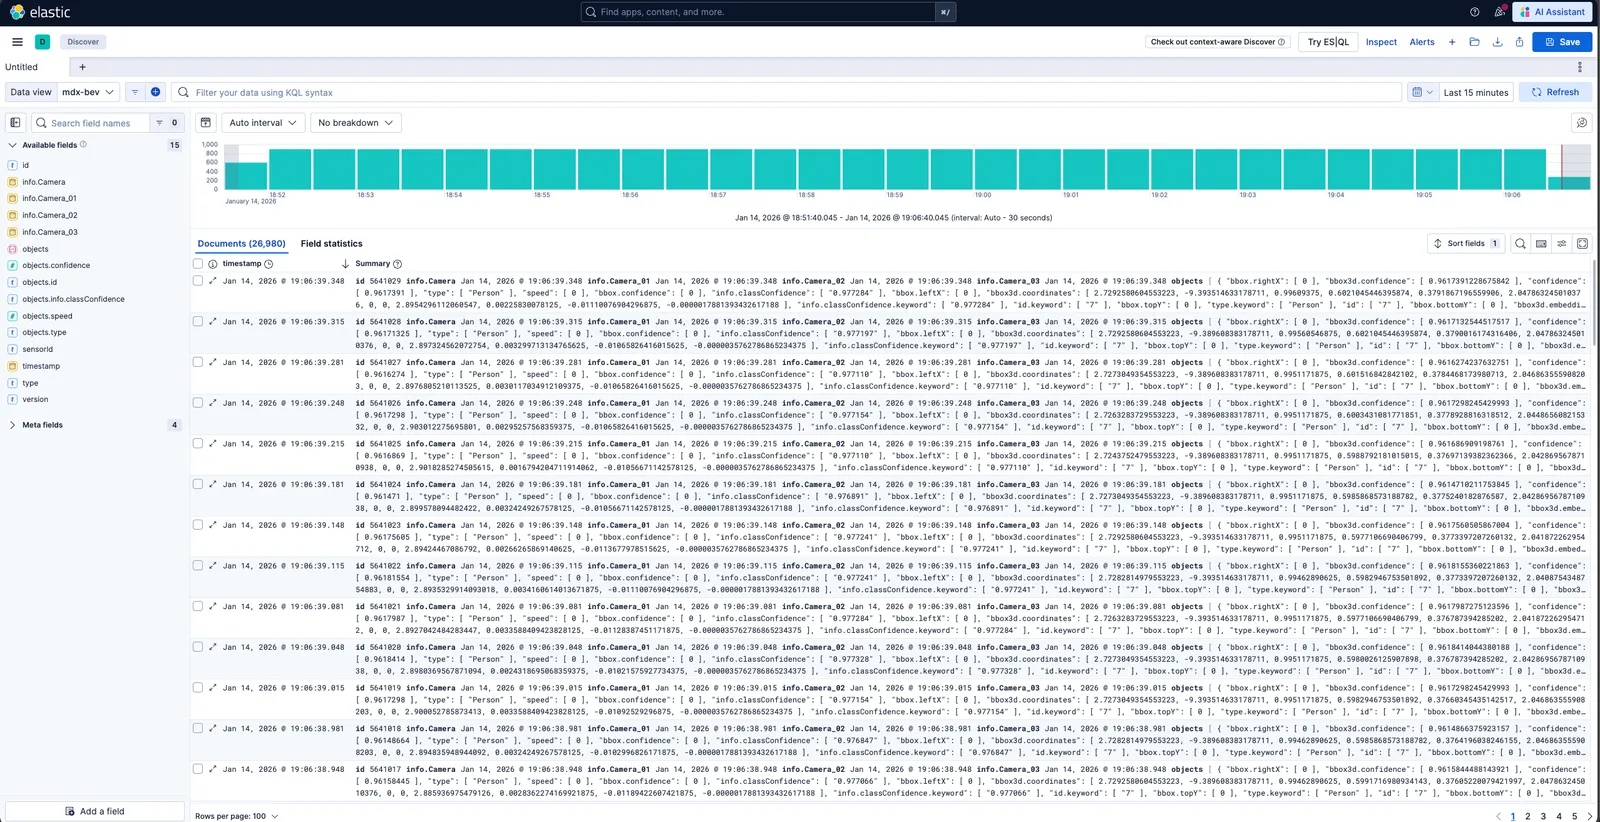
- BEV frames are created by combining frames from individual cameras.
- For better accuracy, the timestamps of the frames across the cameras should be synchronized. These timestamps can be found under the
infoattribute of the frame; see the example below.
VIOS UI
At this point the web-based application is only available for Chrome browser running on Linux, Windows or macOS, details can be found in VST docs.
- Launch Chrome browser.
- In the address bar enter
http://<IP_address>:30888/vst/.
Configure
Select the sensors and streaming protocol, then click Start Video Wall.
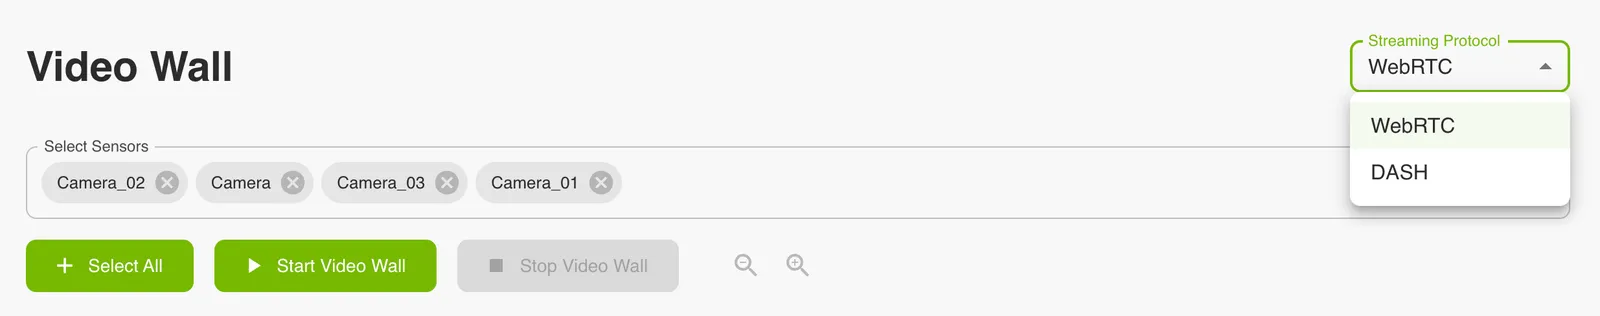
View VIOS Video Wall
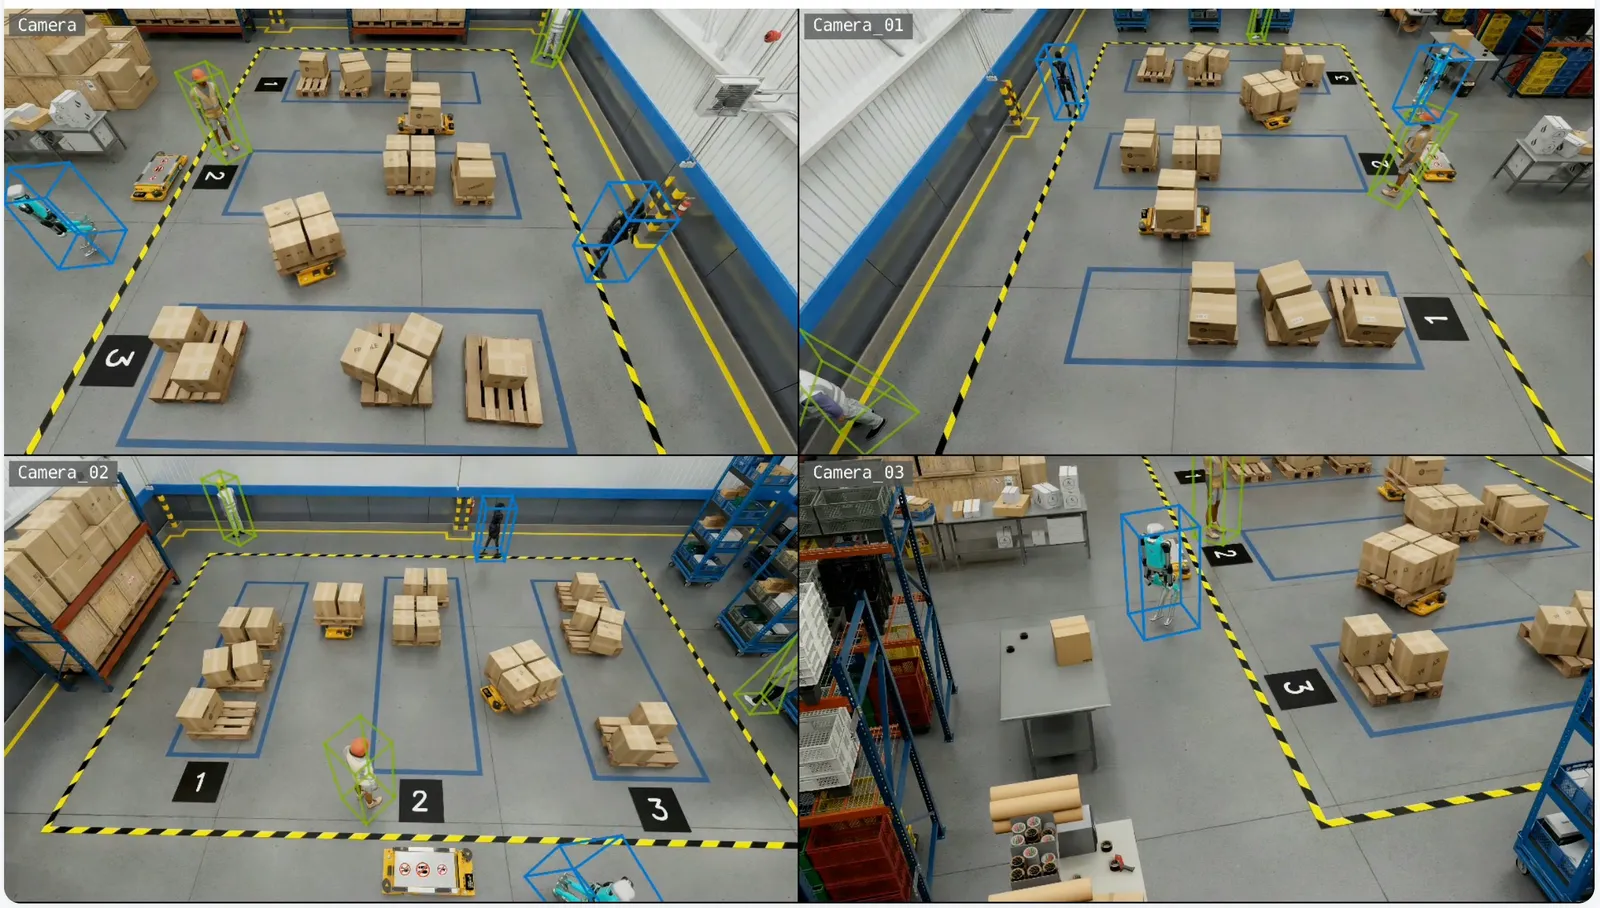
Enable Overlay settings (refer to Playback Overlay on Video Wall) to view 3D object detection and tracking results.
Events and Incidents
Events
The VSS Warehouse 3D Blueprint processes calibrated multi-camera feeds, detects and tracks objects in 3D world coordinates, and generates events based on configurable logic.
One type of event is supported:
- ROI Events: Triggered when objects enter or exit a predefined region of interest (ROI).
For more details, see Event Detection. All event data is stored in Elasticsearch, and can be queried and visualized in Kibana and the VIOS UI.
Incidents
The 3D profile generates restricted-area, confined-area, and proximity incidents and publishes them to mdx-incidents. Per-frame violations are also written to enhanced frames; see Enhanced Frame Data. These Behavior Analytics incidents do not undergo VLM verification in the 3D profile.
Use Cases
ROI events provide the foundation for occupancy monitoring and safe-zone enforcement across calibrated multi-camera 3D scenes—continuously tracking whether designated zones remain clear and maintaining accurate enter/exit occupancy counts for spatial analytics and capacity management.
Latency Measurements
The latency may vary based on the hardware, the number of objects in a scene, the number of ROIs and tripwires, and the machine’s load.
Customization
The Blueprint supports several levels of customization:
- Data Level: Add, remove, or replace cameras while maintaining the existing workflow.
- Model Level: Fine-tune perception models to better suit your use cases.
- Application Level: Build new microservices or applications using the provided APIs and components.
- Microservice Level: Modify existing microservices from source code to extend functionality.
Adding New Cameras or Custom Datasets
Recorded videos and live RTSP streams must be encoded without B-frames and have a resolution of 1920 x 1080.
To check for and remove B-frames, see the FAQ guidance.
For custom video inputs, provide time-synchronized MP4 videos encoded without B-frames that are at least 60 seconds long and all videos should have the same duration.
The tracklet-based AMC method relies heavily on moving people in the input videos. Ensure that the videos contain a sufficient number of clearly visible moving people.
Step 1: Prepare video sources
Choose one of the following options to provide video sources for the 3D profile:
-
Using recorded videos
Use this option to run the VSS with local video files instead of live camera feeds. Place your videos in the
videosdirectory under the path configured byVSS_DATA_DIRin$VSS_APPS_DIR/industry-profiles/warehouse-operations/overrides.env. -
Using live RTSP streams
Use this option when you want to use live RTSP endpoints. Define each camera in
$VSS_APPS_DIR/industry-profiles/warehouse-operations/camera_configs/camera_info.jsonso the VSS Configurator can read the camera list and generate the required configuration. The following steps apply when using live RTSP streams.(i) Create a Sensor Info File (
camera_info.json):The
camera_namevalue should be unique for each camera, andrtsp_urlshould point to the camera stream. Thegroup_idfield defines camera groups with overlapping fields of view, which is required for multi-camera 3D tracking and BEV fusion. Theregionfield identifies the camera location or area and is required for 3D profile camera configuration.Required fields:
camera_name,rtsp_url,group_id,region
Each rtsp_url in camera_info.json must be reachable from the machine where you deploy VSS. VIOS connects to those URLs directly. Before you deploy, test every URL from the deployment machine (for example, with VLC or ffplay).
You do not have to assign group_id by hand. The spatialai_data_utils (SDU) camera grouping tools derive the camera-to-BEV-group partition directly from your camera calibration. Run create_camera_clusters.py to partition cameras into non-overlapping BEV groups; cameras placed in the same cluster share a group_id (the generated group name, such as bev-sensor-1). These tools also populate the matching per-sensor group and region blocks (origin, dimensions, place level) in calibration.json that must be filled in before deployment (see the note under Step 3). For installation and the full command reference, see Camera Grouping Utilities.
(ii) Configure VSS Configurator environment variables: Set the following in $VSS_APPS_DIR/industry-profiles/warehouse-operations/overrides.env, which is loaded after warehouse .env and takes precedence:
Step 2: Configure number of streams
Configuring Number of Streams
Number of streams to be processed can be configured in two ways:
-
Static Configuration: Set the
NUM_STREAMSenvironment variable in warehouseoverrides.envto specify the desired number of streams for video dataset or RTSP streams.The configured number of streams should be less than or equal to the maximum streams supported by your hardware profile and deployment mode. VSS Configurator can be used to automatically cap the stream count using the formula:
final_stream_count = min(NUM_STREAMS, max_streams_supported). WhenSENSOR_INFO_SOURCE=nvstreamer, the sameNUM_STREAMSvalue is the expected camera count the Sensor Configuration Manager waits for before VST registration. For more details, refer to the How to Count Files Dynamically (Prerequisites) section and NVStreamer Settings in VSS Configurator Documentation. -
Dynamic Configuration: Use the VSS Configurator’s prerequisite operations to automatically count the number of video files in the recorded videos directory and use that count for configuration updates.
Dynamic Configuration cannot be used for live RTSP streams.
Example: Automatically determine stream count from video files in the dataset directory:
How it works: If your dataset directory has 6 video files and the GPU supports a maximum of 4 streams, the configurator computes: final_stream_count = min(6, 4) = 4. For more details, refer to the How to Count Files Dynamically (Prerequisites) section in VSS Configurator Documentation.
When using a custom recorded-video dataset, NUM_STREAMS depends on the number of video files available in that dataset. Make sure NUM_STREAMS is less than or equal to the number of videos you want to process.
To use a custom dataset:
-
For a custom synthetic dataset, use a dataset name that ends in
-synthetic(for example,my-warehouse-synthetic). Custom real datasets do not have a suffix requirement. -
Set
SAMPLE_VIDEO_DATASETin$VSS_APPS_DIR/industry-profiles/warehouse-operations/overrides.envto the name of your dataset. -
Set
DATASET_TYPEin$VSS_APPS_DIR/industry-profiles/warehouse-operations/overrides.envtosyntheticfor a synthetic dataset orrealfor a real dataset. This selects the corresponding Sparse4D model, engine, anchor, and labels. -
Place the video files in
$VSS_DATA_DIR/videos/$SAMPLE_VIDEO_DATASET/. -
Add the image metadata and floor map files under
$VSS_APPS_DIR/industry-profiles/warehouse-operations/warehouse-3d-app/calibration/sample-data/${SAMPLE_VIDEO_DATASET}. If you already have a calibration, addcalibration.jsonto the same directory. Otherwise, generate it in Step 3. You can refer to sample datasets provided in the repository for the expected file structure and sample contents.
Refer to Sparse4D Real-Time Performance for more details on the max streams supported for a particular GPU. If GPU is not found in list, then increase the streams gradually to find the optimal number of streams that can be used
Step 3: Deploy and generate new calibration
Before deploying the stack and generating a calibration, create the projects directory:
Projects will be saved in ${VSS_APPS_DIR}/services/auto-calibration/projects.
Change the ownership of the Auto Calibration data and projects directories to UID 1000 and GID 1000:
Configure industry-profiles/warehouse-operations/overrides.env using the Auto-Calibration tab under Deployment Selection, then follow Deploy the Blueprint to start the Auto-Calibration profile. Use it to generate a new calibration against live RTSP streams served by nvstreamer, using the warehouse dataset and VST stack. For steps to generate calibration, see Auto Calibration workflow steps. After generating and storing the calibration, bring the Docker Compose stack down and update the calibration file at $VSS_APPS_DIR/industry-profiles/warehouse-operations/warehouse-3d-app/calibration/sample-data/${SAMPLE_VIDEO_DATASET}/calibration.json.
- Maintain a single
calibration.jsonfile per deployment. - Each sensor name in
calibration.jsonmust match the correspondingcamera_nameincamera_info.jsonor the name of the corresponding video placed in${VSS_DATA_DIR}/videos. - For 3D profile use cases, the ROIs and Tripwires must be drawn on the floor plan/layout map.
- Add new camera information following the schema defined in Calibration Schema.
- The
imageMetadatafile needs to be generated manually. - Manually add any other attributes that are missing from the generated calibration file but are required for your use case.
- Auto Calibration requires time-synchronized videos as input. For RTSP cameras, record videos from the RTSP source (e.g. using ffmpeg or similar tools), manually trim the videos to time-synchronize them if needed, then provide them to Auto Calibration.
Step 4: Camera Clustering
Use create_camera_clusters.py to partition cameras into non-overlapping groups for separate 3D model instances. Use --n_clusters 1 for a single group. For command examples and available options, see Camera Clustering.
Step 5: Redeploy the stack to apply the new calibration
Before redeploying, replace the Auto-Calibration settings in industry-profiles/warehouse-operations/overrides.env with the settings from the 3D tab under Deployment Selection. Then follow Deploy the Blueprint to start the 3D profile with the new calibration.
Before updating the warehouse overrides.env file or running docker compose up, check whether containers from a previous Docker Compose deployment are still present:
No containers belonging to the previous deployment should be present before starting a new deployment. Stale containers from a previous deployment can cause silent errors. For example, already-running containers can create the false impression that a new deployment has started successfully.
Camera Grouping Utilities
The 3D Blueprint uses multi-camera BEV (Bird’s Eye View) perception systems that require cameras to be organized into groups. Each camera group defines a set of cameras with overlapping fields of view that work together for 3D detection and tracking.
The spatialai_data_utils library provides the following functionality:
- Calculate BEV origin and dimensions for each camera group.
- Partition cameras into clusters using spatial clustering algorithms for distributed 3D model deployment.
- Filter and select specific cameras for processing.
- Generate FOV polygons from camera intrinsic/extrinsic matrices.
- Visualize camera coverage and group assignments.
To install the library:
The camera grouping tools are shipped with the full spatialai-data-utils package in the VSS repository. The examples below run the scripts from the package’s tools/camera_grouping directory.
BEV Group Origin Calculation
Use calculate_origin.py to calculate BEV origin and dimensions for camera groups, filter cameras, and generate FOV visualizations.
The algorithm works as follows:
- FOV Calculation: By default, the tool uses frustum-based FOV generation. It projects camera view frustums onto the ground plane using camera intrinsic (focal length, principal point) and extrinsic (rotation, translation) matrices. The frustum is intersected with a configurable height range to create a polygon representing the camera’s ground coverage.
- Group Bounds: For each camera group, the tool computes the union of all camera FOV polygons and calculates the bounding box with optional dilation.
- Origin Calculation: The BEV origin is computed as the centroid of the union FOV polygon, and dimensions are derived from the bounding box of the union, providing the coordinate reference for multi-camera tracking.
Origin calculation is required when setting up a new multi-camera deployment or when camera configurations change. This functionality is already integrated into the VSS Configurator, so manual execution is typically not necessary. However, if you need to run it as a standalone script for debugging, custom workflows, or batch processing, the example commands below demonstrate the available options.
Navigate to the spatialai-data-utils camera grouping tools
Use --help to list all available arguments.
Key options:
--output,-o: Output calibration file path (default: input_with_origins.json).--overwrite: Overwrite the input calibration file (mutually exclusive with--output).--map_file: Path to map image for visualization (uses black background if not provided).--sensor-names: Filter to process only specified sensor names (comma-separated).--n-sensor-groups: Number of sensor groups to create when group field is missing (default: 1).--dilation: Dilation distance in meters for group bounds calculation (default: 1.0).--height-range: Height range (min, max) in meters for ground plane intersection (default: 1.0 3.0).--max-camera-distance: Maximum distance in meters to constrain frustum polygons (default: 30.0).--scene-bounds: Scene bounds (min_x, min_y, max_x, max_y) in meters to clip frustum polygons.--prefer-existing-fov: Use existing FOV from calibration file, fall back to frustum if not available.--visualize: Generate visualization of groups.--vis_separate_images: Generate separate visualization images per group instead of combined.
Camera Clustering
For 3D model inference and deployment, cameras need to be partitioned into non-overlapping groups where each group is handled by a separate 3D model instance. Use create_camera_clusters.py to partition cameras into spatially compact clusters based on FOV coverage and spatial proximity. This tool assigns ALL cameras to exactly N clusters, ensuring efficient distribution of camera workloads across multiple model instances.
The clustering algorithm may not always produce optimal results depending on camera layout and configuration. Always use visualization (enabled by default) to verify the clustering results and manually adjust using reassign_camera_groups.py if needed.
By default, the tool auto-tunes clustering parameters (start camera index, overlap threshold, distance threshold) using a grid search to find optimal settings. Use --disable_param_tuning to skip auto-tuning and use the provided parameters directly.
Running Camera Clustering
Navigate to the spatialai-data-utils camera grouping tools
Use --help to list all available arguments.
Key options:
--max_camera_per_group: Maximum cameras per cluster (required). Has higher priority than--n_clusters.--n_clusters: Override auto-calculated number of clusters.--mode: Clustering mode - “balanced” or “densify” (default: densify).--output: Output path for the clustered calibration file.--overwrite: Overwrite the input calibration file.--output_suffix: Suffix for output files (default: “clustered”).--start_camera_index: Starting camera index for seeding (default: 0).--min_overlap_threshold: Minimum required FOV overlap (default: 0.2).--max_distance_threshold: Maximum allowed centroid distance in meters (default: 8.0).--max_cascade_depth: Maximum recursion depth for densify-mode cascade reassignment (default: 3).--prefer_existing_fov: Use existing FOV polygons in calibration instead of calculating from frustum.--height_range: Height range (min, max) in meters for ground plane intersection (default: 1.0 3.0).--image_size: Image dimensions (width, height) in pixels for frustum calculation (default: 1920 1080).--max_camera_distance: Maximum distance in meters for frustum calculation (default: 30.0).--dilation: Buffer distance in meters for cluster bounding boxes (default: 8.0).--disable_param_tuning: Disable auto-tuning of clustering parameters.--tuning_overlap_grid: Custom overlap thresholds (0-1) to search when auto-tuning.--tuning_distance_grid: Custom centroid distance thresholds (meters) to search when auto-tuning.--tuning_start_index_grid: Seed camera indices to try when auto-tuning.--tuning_workers: Number of parallel workers for auto-tuning (0=auto, 1=disable parallelism).--vis_no_camera_id_labels: Disable drawing camera IDs on the visualization.--vis_separate_images: Generate separate visualization images per cluster instead of combined.
Clustering Modes
densify(default): Prioritizes creating full, densely-packed clusters. Uses cascade reassignment to handle unassigned cameras by recursively attempting to place them in nearby clusters.balanced: Enforces strict thresholds for overlap and distance. Splits oversized clusters to maintain balance across all groups.
Cluster Count Calculation
The number of clusters is determined by the following logic:
- If
--n_clustersis not provided, it is auto-calculated asceil(total_cameras / max_camera_per_group). - If
--n_clustersis explicitly set but would violate the--max_camera_per_groupconstraint (i.e., requires more clusters than specified), the tool overrides--n_clusterswith the minimum required value and logs a warning. - If
--n_clusters=1is set buttotal_cameras > max_camera_per_group, an error is raised.
This ensures --max_camera_per_group always takes priority to guarantee each cluster stays within the specified camera limit.
Finding Optimal Clustering Parameters
Use find_suggested_cluster_params.py to search for optimal clustering parameters. This tool performs a grid search over overlap thresholds, distance thresholds, and seed camera indices to find settings that produce compact, capacity-respecting clusters:
Key options:
--max_camera_per_group: Maximum cameras per cluster (required).--mode: Clustering mode to evaluate - “balanced” or “densify” (default: densify).--prefer_existing_fov: Use existing FOV polygons instead of calculating from frustum.--max_camera_distance: Maximum distance in meters for frustum calculation (default: 30.0).--height_range: Height range (min, max) in meters for ground plane intersection (default: 1.0 3.0).--image_size: Image dimensions (width, height) in pixels for frustum calculation (default: 1920 1080).--max_cascade_depth: Maximum recursion depth for densify-mode cascade (default: 3).--overlap_grid: List of overlap thresholds (0-1) to search.--distance_grid: List of centroid distance thresholds (meters) to search.--start_index_grid: Seed camera indices to try.--start_index_seed: Random seed for auto-generated start camera indices.--top_k: Number of top candidates to display (default: 5).--workers: Number of parallel workers for the sweep (0=auto, 1=disable parallelism).--verbose: Enable verbose logging.
The output ranks candidates by score (lower is better), showing unassigned camera count, overflow, and scatter metrics for each parameter combination.
Camera Group Reassigning
Use reassign_camera_groups.py to manually reassign cameras to different existing BEV groups. Common use cases include:
- Fixing suboptimal clustering: Move cameras that were incorrectly assigned by the automatic clustering algorithm.
- Balancing cluster sizes: Redistribute cameras between groups to achieve more even workload distribution.
- Iterative refinement: Fine-tune cluster assignments after reviewing visualization results.
Navigate to the spatialai-data-utils camera grouping tools
Key options:
--move: Mappings ofcamera_id:group_name(space separated) to reassign (required).--output: Output path for updated calibration (default:<input>_reassigned.json).--overwrite: Overwrite the input calibration file in-place.--output_suffix: Suffix for output files (default: “reassigned”).--strict: Fail if a camera or target group is missing; otherwise skip with warning.--prefer_existing_fov: Use existing FOV from calibration, fall back to frustum if not available.--map_file: Path to map image for visualization (auto-detectsTop.pngif omitted).--dilation: Dilation distance in meters when recomputing group bounds (default: 1.0).--height_range: Height range (min, max) in meters for ground plane intersection (default: 1.0 3.0).--image_size: Image dimensions (width, height) in pixels for frustum calculation (default: 1920 1080).--max_camera_distance: Maximum distance in meters for frustum calculation (default: 30.0).--vis_no_camera_id_labels: Disable drawing camera IDs on the visualization.
Model Customization
Perception Model Fine-tuning
The Blueprint uses Sparse4D as its primary perception model. To customize:
- Fine-tune Sparse4D using TAO (Sparse4D model page)
- Configure DeepStream to use your custom model (model configuration guide)
Application Customization
The Blueprint uses a modular microservices architecture with the following communication channels:
- Message Broker (Kafka or Redis)
- Elasticsearch database
- REST APIs
Users can build their own microservices by consuming data from the above channels.
For complete API documentation, see API Reference Page.
Available Service Ports
The following ports are used during deployment, and users can leverage them for any potential integration:
Analytics Microservices Customization (Advanced)
For detailed information about customizing specific analytics microservices, refer to:
Hardware Config Customization
The 3D Warehouse Blueprint requires several configuration files to be properly tuned based on your GPU hardware and deployment requirements. When changing hardware (e.g., switching from H100 to L4 GPU) or adjusting the number of video streams, multiple configuration files must be updated to ensure optimal performance and prevent GPU overload.
Configuration Files Requiring Hardware-Based Updates
The following table lists the configuration files that typically require updates when hardware changes:
Certain GPUs require additional optimizations. For example, IGX-THOR and DGX-SPARK get:
- Extended
batched-push-timeout(67000ms) for DeepStream configs enable_overlay_skip_frameenabled in VST configs for better performance
There are two approaches to customize these configuration files:
Approach 1: Manual Configuration
Manually update all required configuration files before deploying the blueprint. This is time consuming, error prone and often not suitable for production deployments.
Approach 2: Automatic Config Management using VSS Configurator
The VSS Configurator provides a declarative approach to automatically update all required configuration files based on your hardware profile and deployment mode. This is the recommended approach for production deployments and simplifies the configuration management process.
For how the configurator updates configurations in this blueprint, see VSS Configurator for the Warehouse Blueprint. The guide describes configuration inputs, affected files, stream ceilings, and hardware-specific overrides.
To enable the VSS Configurator, in VSS Configurator’s environment variables you must set:
The VSS Configurator is enabled by default (ENABLE_PROFILE_CONFIGURATOR=true).
When enabled, it runs before the Blueprint Deployment starts and adjusts configuration files based on the hardware profile and deployment mode as defined in the HARDWARE_PROFILE and MODE environment variables.
The VSS Configurator provides a comprehensive set of features for automated profile configuration management:
Execution Order: Environment Variable Validation → Prerequisite Operations → Variable Computations → Configuration File Updates
For detailed information on how to create custom hardware profiles and advanced configuration options, refer to the Profile Configuration Manager section in VSS Configurator Documentation.