Skip to navigation

Creating a Manager-Based RL Environment

View as Markdown

Having learnt how to create a base environment in Creating a Manager-Based Base Environment, we will now look at how to create a manager-based task environment for reinforcement learning.

The base environment is designed as an sense-act environment where the agent can send commands to the environment and receive observations from the environment. This minimal interface is sufficient for many applications such as traditional motion planning and controls. However, many applications require a task-specification which often serves as the learning objective for the agent. For instance, in a navigation task, the agent may be required to reach a goal location. To this end, we use the envs.ManagerBasedRLEnv class which extends the base environment to include a task specification.

Similar to other components in Isaac Lab, instead of directly modifying the base class envs.ManagerBasedRLEnv, we encourage users to simply implement a configuration envs.ManagerBasedRLEnvCfg for their task environment. This practice allows us to separate the task specification from the environment implementation, making it easier to reuse components of the same environment for different tasks.

In this tutorial, we will configure the cartpole environment using the envs.ManagerBasedRLEnvCfg to create a manager-based task for balancing the pole upright. We will learn how to specify the task using reward terms, termination criteria, curriculum and commands.

The Code

For this tutorial, we use the cartpole environment defined in isaaclab_tasks.core.cartpole module.

# Copyright (c) 2022-2026, The Isaac Lab Project Developers (https://github.com/isaac-sim/IsaacLab/blob/main/CONTRIBUTORS.md).
# All rights reserved.
#
# SPDX-License-Identifier: BSD-3-Clause
"""Configuration for the manager-based cartpole environment."""
import math
import isaaclab.sim as sim_utils
from isaaclab.assets import ArticulationCfg, AssetBaseCfg
from isaaclab.envs import ManagerBasedRLEnvCfg
from isaaclab.managers import EventTermCfg as EventTerm
from isaaclab.managers import ObservationGroupCfg as ObsGroup
from isaaclab.managers import ObservationTermCfg as ObsTerm
from isaaclab.managers import RewardTermCfg as RewTerm
from isaaclab.managers import SceneEntityCfg
from isaaclab.managers import TerminationTermCfg as DoneTerm
from isaaclab.scene import InteractiveSceneCfg
from isaaclab.utils import configclass, replace
from isaaclab.visualizers import VisualizerCfg
from isaaclab_assets.robots.cartpole import CARTPOLE_CFG
from . import mdp
from .cartpole_common import LIGHT_ORIENTATION, CartpolePhysicsCfg
##
# Scene definition
##
@configclass
class CartpoleSceneCfg(InteractiveSceneCfg):
"""Configuration for a cart-pole scene."""
# ground plane
ground = AssetBaseCfg(
prim_path="/World/ground",
spawn=sim_utils.GroundPlaneCfg(size=(100.0, 100.0)),
)
# cartpole
robot: ArticulationCfg = replace(CARTPOLE_CFG, prim_path="{ENV_REGEX_NS}/Robot")
# lights
distant_light = AssetBaseCfg(
prim_path="/World/DistantLight",
init_state=AssetBaseCfg.InitialStateCfg(rot=LIGHT_ORIENTATION),
spawn=sim_utils.DistantLightCfg(color=(1.0, 1.0, 1.0), intensity=2000.0),
)
##
# MDP settings
##
@configclass
class ActionsCfg:
"""Action specifications for the MDP."""
joint_effort = mdp.JointEffortActionCfg(asset_name="robot", joint_names=["slider_to_cart"], scale=100.0)
@configclass
class ObservationsCfg:
"""Observation specifications for the MDP."""
@configclass
class PolicyCfg(ObsGroup):
"""Observations for policy group."""
# observation terms (order preserved)
joint_pos_rel = ObsTerm(func=mdp.joint_pos_rel)
joint_vel_rel = ObsTerm(func=mdp.joint_vel_rel)
def __post_init__(self):
self.enable_corruption = False
self.concatenate_terms = True
# observation groups
policy: PolicyCfg = PolicyCfg()
@configclass
class EventCfg:
"""Configuration for events."""
# reset
reset_cart_position = EventTerm(
func=mdp.reset_joints_by_offset,
mode="reset",
params={
"asset_cfg": SceneEntityCfg("robot", joint_names=["slider_to_cart"]),
"position_range": (-1.0, 1.0),
"velocity_range": (-0.5, 0.5),
},
)
reset_pole_position = EventTerm(
func=mdp.reset_joints_by_offset,
mode="reset",
params={
"asset_cfg": SceneEntityCfg("robot", joint_names=["cart_to_pole"]),
"position_range": (-0.25 * math.pi, 0.25 * math.pi),
"velocity_range": (-0.25 * math.pi, 0.25 * math.pi),
},
)
@configclass
class RewardsCfg:
"""Reward terms for the MDP."""
# (1) Constant running reward
alive = RewTerm(func=mdp.is_alive, weight=1.0)
# (2) Failure penalty
terminating = RewTerm(func=mdp.is_terminated, weight=-2.0)
# (3) Primary task: keep pole upright
pole_pos = RewTerm(
func=mdp.joint_pos_target_l2,
weight=-1.0,
params={"asset_cfg": SceneEntityCfg("robot", joint_names=["cart_to_pole"]), "target": 0.0},
)
# (4) Shaping tasks: lower cart velocity
cart_vel = RewTerm(
func=mdp.joint_vel_l1,
weight=-0.01,
params={"asset_cfg": SceneEntityCfg("robot", joint_names=["slider_to_cart"])},
)
# (5) Shaping tasks: lower pole angular velocity
pole_vel = RewTerm(
func=mdp.joint_vel_l1,
weight=-0.005,
params={"asset_cfg": SceneEntityCfg("robot", joint_names=["cart_to_pole"])},
)
# (6) Success rate tracking (zero-weight, metric only)
success_rate = RewTerm(func=mdp.survival_success_rate, weight=0.0)
@configclass
class TerminationsCfg:
"""Termination terms for the MDP."""
# (1) Time out
time_out = DoneTerm(func=mdp.time_out, time_out=True)
# (2) Cart out of bounds
cart_out_of_bounds = DoneTerm(
func=mdp.joint_pos_out_of_manual_limit,
params={"asset_cfg": SceneEntityCfg("robot", joint_names=["slider_to_cart"]), "bounds": (-3.0, 3.0)},
)
##
# Environment configuration
##
@configclass
class CartpoleEnvCfg(ManagerBasedRLEnvCfg):
"""Configuration for the cartpole environment."""
# Scene settings
scene: CartpoleSceneCfg = CartpoleSceneCfg(num_envs=4096, env_spacing=4.0, clone_in_fabric=True)
# Basic settings
observations: ObservationsCfg = ObservationsCfg()
actions: ActionsCfg = ActionsCfg()
# MDP settings
rewards: RewardsCfg = RewardsCfg()
terminations: TerminationsCfg = TerminationsCfg()
events: EventCfg = EventCfg()
def __post_init__(self):
"""Post initialization."""
# general settings
self.decimation = 2
self.episode_length_s = 5
# simulation settings
self.sim.dt = 1 / 120
self.sim.render_interval = self.decimation
self.sim.physics = CartpolePhysicsCfg()
# visualizer settings
self.sim.default_visualizer_cfg = VisualizerCfg(eye=(8.0, 0.0, 5.0))

The script for running the environment run_cartpole_rl_env.py is present in the isaaclab/scripts/tutorials/03_envs directory. The script is similar to the cartpole_base_env.py script in the previous tutorial, except that it uses the envs.ManagerBasedRLEnv instead of the envs.ManagerBasedEnv.

# Copyright (c) 2022-2026, The Isaac Lab Project Developers (https://github.com/isaac-sim/IsaacLab/blob/main/CONTRIBUTORS.md).
# All rights reserved.
#
# SPDX-License-Identifier: BSD-3-Clause
"""
This script demonstrates how to run the RL environment for the cartpole balancing task.
~~~bash
uv run python scripts/tutorials/03_envs/run_cartpole_rl_env.py --num_envs 32
~~~
Trailing `key=value` arguments (e.g. `physics=isaacsim_physx`) are forwarded as Hydra-style
overrides to the task configuration; see `~isaaclab_tasks.utils.parse_env_cfg`.
"""
"""Parse the command-line arguments first."""
import argparse
from isaaclab.app import add_launcher_args, launch_simulation
from isaaclab.utils import instantiate
# add argparse arguments
parser = argparse.ArgumentParser(description="Tutorial on running the cartpole RL environment.")
parser.add_argument("--num_envs", type=int, default=16, help="Number of environments to spawn.")
# append simulation launcher cli args
add_launcher_args(parser)
# tutorials should open Kit visualizer by default
parser.set_defaults(visualizer=["kit"])
# parse the arguments, forwarding unrecognized ones as Hydra-style task config overrides
args_cli, hydra_overrides = parser.parse_known_args()
"""Rest everything follows."""
import torch
from isaaclab_tasks.utils import parse_env_cfg
def main():
"""Main function."""
# create environment configuration
env_cfg = parse_env_cfg(
"Isaac-Cartpole", device=args_cli.device, num_envs=args_cli.num_envs, overrides=hydra_overrides
)
# Launch the simulator runtime that the configuration needs
with launch_simulation(env_cfg, args_cli):
# setup RL environment
env = instantiate(env_cfg)
# simulate physics
count = 0
while env.sim.is_running():
with torch.inference_mode():
# reset
if count % 300 == 0:
count = 0
env.reset()
print("-" * 80)
print("[INFO]: Resetting environment...")
# sample random actions
joint_efforts = torch.randn_like(env.action_manager.action)
# step the environment
obs, rew, terminated, truncated, info = env.step(joint_efforts)
# print current orientation of pole
print("[Env 0]: Pole joint: ", obs["policy"][0][1].item())
# update counter
count += 1
# close the environment
env.close()
if __name__ == "__main__":
# run the main function
main()

The Code Explained

We already went through parts of the above in the Creating a Manager-Based Base Environment tutorial to learn about how to specify the scene, observations, actions and events. Thus, in this tutorial, we will focus only on the RL components of the environment.

In Isaac Lab, we provide various implementations of different terms in the envs.mdp module. We will use some of these terms in this tutorial, but users are free to define their own terms as well. These are usually placed in their task-specific sub-package (for instance, in isaaclab_tasks.core.cartpole.mdp).

Defining rewards

The managers.RewardManager is used to compute the reward terms for the agent. Similar to the other managers, its terms are configured using the managers.RewardTermCfg class. The managers.RewardTermCfg class specifies the function or callable class that computes the reward as well as the weighting associated with it. It also takes in dictionary of arguments, "params" that are passed to the reward function when it is called.

For the cartpole task, we will use the following reward terms:

  • Alive Reward: Encourage the agent to stay alive for as long as possible.
  • Terminating Reward: Similarly penalize the agent for terminating.
  • Pole Angle Reward: Encourage the agent to keep the pole at the desired upright position.
  • Cart Velocity Reward: Encourage the agent to keep the cart velocity as small as possible.
  • Pole Velocity Reward: Encourage the agent to keep the pole velocity as small as possible.
@configclass
class RewardsCfg:
"""Reward terms for the MDP."""
# (1) Constant running reward
alive = RewTerm(func=mdp.is_alive, weight=1.0)
# (2) Failure penalty
terminating = RewTerm(func=mdp.is_terminated, weight=-2.0)
# (3) Primary task: keep pole upright
pole_pos = RewTerm(
func=mdp.joint_pos_target_l2,
weight=-1.0,
params={"asset_cfg": SceneEntityCfg("robot", joint_names=["cart_to_pole"]), "target": 0.0},
)
# (4) Shaping tasks: lower cart velocity
cart_vel = RewTerm(
func=mdp.joint_vel_l1,
weight=-0.01,
params={"asset_cfg": SceneEntityCfg("robot", joint_names=["slider_to_cart"])},
)
# (5) Shaping tasks: lower pole angular velocity
pole_vel = RewTerm(
func=mdp.joint_vel_l1,
weight=-0.005,
params={"asset_cfg": SceneEntityCfg("robot", joint_names=["cart_to_pole"])},
)
# (6) Success rate tracking (zero-weight, metric only)
success_rate = RewTerm(func=mdp.survival_success_rate, weight=0.0)

Defining termination criteria

Most learning tasks happen over a finite number of steps that we call an episode. For instance, in the cartpole task, we want the agent to balance the pole for as long as possible. However, if the agent reaches an unstable or unsafe state, we want to terminate the episode. On the other hand, if the agent is able to balance the pole for a long time, we want to terminate the episode and start a new one so that the agent can learn to balance the pole from a different starting configuration.

The managers.TerminationsCfg configures what constitutes for an episode to terminate. In this example, we want the task to terminate when either of the following conditions is met:

  • Episode Length The episode length is greater than the defined max_episode_length
  • Cart out of bounds The cart goes outside of the bounds [-3, 3]

The flag managers.TerminationsCfg.time_out specifies whether the term is a time-out (truncation) term or terminated term. These are used to indicate the two types of terminations as described in Gymnasium’s documentation.

@configclass
class TerminationsCfg:
"""Termination terms for the MDP."""
# (1) Time out
time_out = DoneTerm(func=mdp.time_out, time_out=True)
# (2) Cart out of bounds
cart_out_of_bounds = DoneTerm(
func=mdp.joint_pos_out_of_manual_limit,
params={"asset_cfg": SceneEntityCfg("robot", joint_names=["slider_to_cart"]), "bounds": (-3.0, 3.0)},
)

Defining commands

For various goal-conditioned tasks, it is useful to specify the goals or commands for the agent. These are handled through the managers.CommandManager. The command manager handles resampling and updating the commands at each step. It can also be used to provide the commands as an observation to the agent.

For this simple task, we do not use any commands. Hence, we leave this attribute as its default value, which is None. You can see an example of how to define a command manager in the other locomotion or manipulation tasks.

Defining curriculum

Often times when training a learning agent, it helps to start with a simple task and gradually increase the tasks’s difficulty as the agent training progresses. This is the idea behind curriculum learning. In Isaac Lab, we provide a managers.CurriculumManager class that can be used to define a curriculum for your environment.

In this tutorial we don’t implement a curriculum for simplicity, but you can see an example of a curriculum definition in the other locomotion or manipulation tasks.

Tying it all together

With all the above components defined, we can now create the ManagerBasedRLEnvCfg configuration for the cartpole environment. This is similar to the ManagerBasedEnvCfg defined in Creating a Manager-Based Base Environment, only with the added RL components explained in the above sections.

@configclass
class CartpoleEnvCfg(ManagerBasedRLEnvCfg):
"""Configuration for the cartpole environment."""
# Scene settings
scene: CartpoleSceneCfg = CartpoleSceneCfg(num_envs=4096, env_spacing=4.0, clone_in_fabric=True)
# Basic settings
observations: ObservationsCfg = ObservationsCfg()
actions: ActionsCfg = ActionsCfg()
# MDP settings
rewards: RewardsCfg = RewardsCfg()
terminations: TerminationsCfg = TerminationsCfg()
events: EventCfg = EventCfg()
def __post_init__(self):
"""Post initialization."""
# general settings
self.decimation = 2
self.episode_length_s = 5
# simulation settings
self.sim.dt = 1 / 120
self.sim.render_interval = self.decimation
self.sim.physics = CartpolePhysicsCfg()
# visualizer settings
self.sim.default_visualizer_cfg = VisualizerCfg(eye=(8.0, 0.0, 5.0))

Running the simulation loop

Coming back to the run_cartpole_rl_env.py script, the simulation loop is similar to the previous tutorial. The only difference is that the configuration’s class_type creates an instance of envs.ManagerBasedRLEnv instead of the envs.ManagerBasedEnv. Consequently, now the envs.ManagerBasedRLEnv.step method returns additional signals such as the reward and termination status. The information dictionary also maintains logging of quantities such as the reward contribution from individual terms, the termination status of each term, the episode length etc.

def main():
"""Main function."""
# create environment configuration
env_cfg = parse_env_cfg(
"Isaac-Cartpole", device=args_cli.device, num_envs=args_cli.num_envs, overrides=hydra_overrides
)
# Launch the simulator runtime that the configuration needs
with launch_simulation(env_cfg, args_cli):
# setup RL environment
env = instantiate(env_cfg)
# simulate physics
count = 0
while env.sim.is_running():
with torch.inference_mode():
# reset
if count % 300 == 0:
count = 0
env.reset()
print("-" * 80)
print("[INFO]: Resetting environment...")
# sample random actions
joint_efforts = torch.randn_like(env.action_manager.action)
# step the environment
obs, rew, terminated, truncated, info = env.step(joint_efforts)
# print current orientation of pole
print("[Env 0]: Pole joint: ", obs["policy"][0][1].item())
# update counter
count += 1
# close the environment
env.close()

The Code Execution

Similar to the previous tutorial, we can run the environment by executing the run_cartpole_rl_env.py script.

python scripts/tutorials/03_envs/run_cartpole_rl_env.py --num_envs 32 --viz kit

This should open a similar simulation as in the previous tutorial. However, this time, the environment returns more signals that specify the reward and termination status. Additionally, the individual environments reset themselves when they terminate based on the termination criteria specified in the configuration.
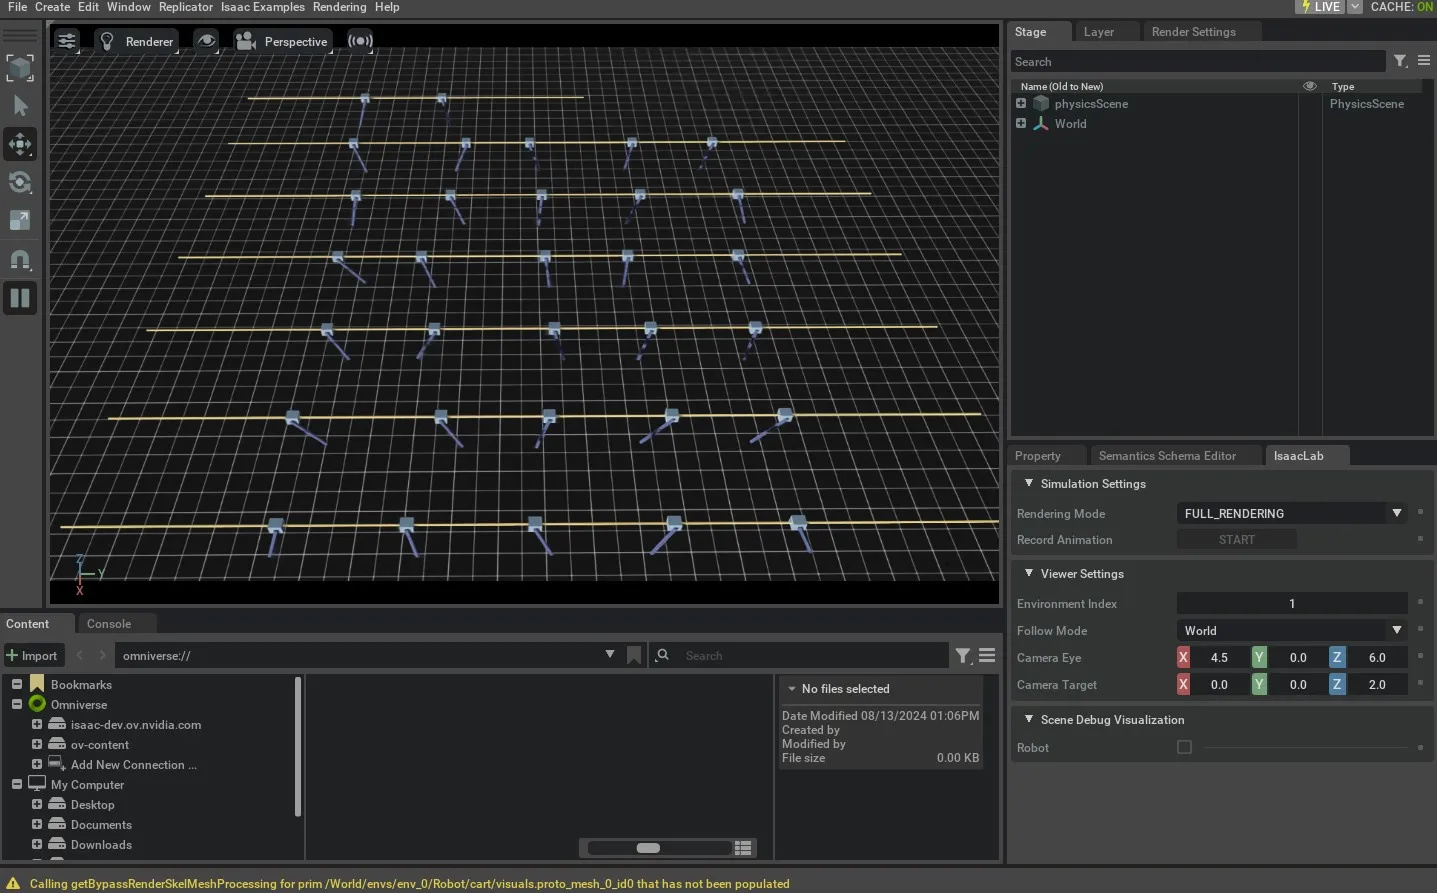
result of run_cartpole_rl_env.py

To stop the simulation, you can either close the window, or press Ctrl+C in the terminal where you started the simulation.

In this tutorial, we learnt how to create a task environment for reinforcement learning. We do this by extending the base environment to include the rewards, terminations, commands and curriculum terms. We also learnt how to use the envs.ManagerBasedRLEnv class to run the environment and receive various signals from it.

While it is possible to manually create an instance of envs.ManagerBasedRLEnv class for a desired task, this is not scalable as it requires specialized scripts for each task. Thus, we exploit the gymnasium.make function to create the environment with the gym interface. We will learn how to do this in the next tutorial.